docext
An on-premises, OCR-free unstructured data extraction, markdown conversion and benchmarking toolkit. (https://idp-leaderboard.org/)
- 2.1k
- Python
- Apache-2.0
- 8 mo ago
An on-premises, OCR-free unstructured data extraction, markdown conversion and benchmarking toolkit. (https://idp-leaderboard.org/)
Turn any PDF or image document into structured data for your AI. A powerful, lightweight OCR toolkit that bridges the gap between images/PDFs and LLMs. Supports 100+ languages.
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.
Convert documents to structured data effortlessly. Unstructured is open-source ETL solution for transforming complex documents into clean, structured formats for language models. Visit our website to learn more about our enterprise grade Platform product for production grade workflows, partitioning, enrichments, chunking and embedding.
[EMNLP 2025 Demo] PDF scientific paper translation with preserved formats - 基于 AI 完整保留排版的 PDF 文档全文双语翻译,支持 Google/DeepL/Ollama/OpenAI 等服务,提供 CLI/GUI/MCP/Docker/Zotero
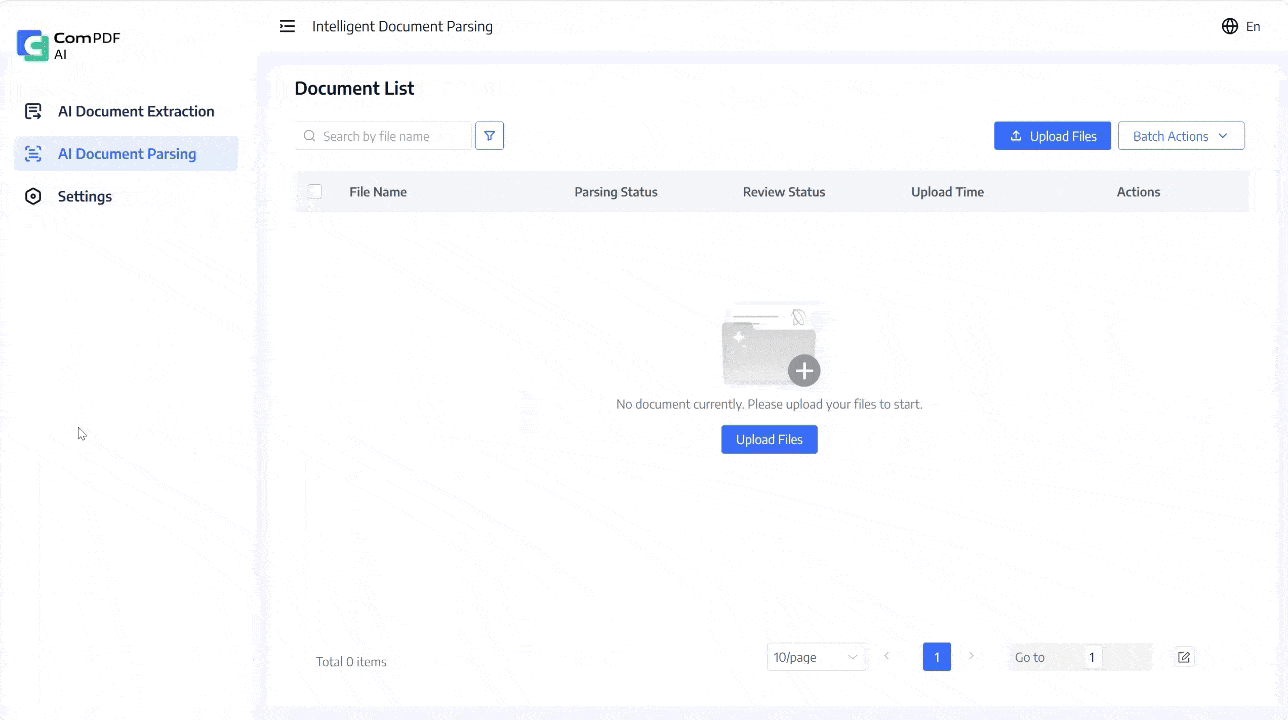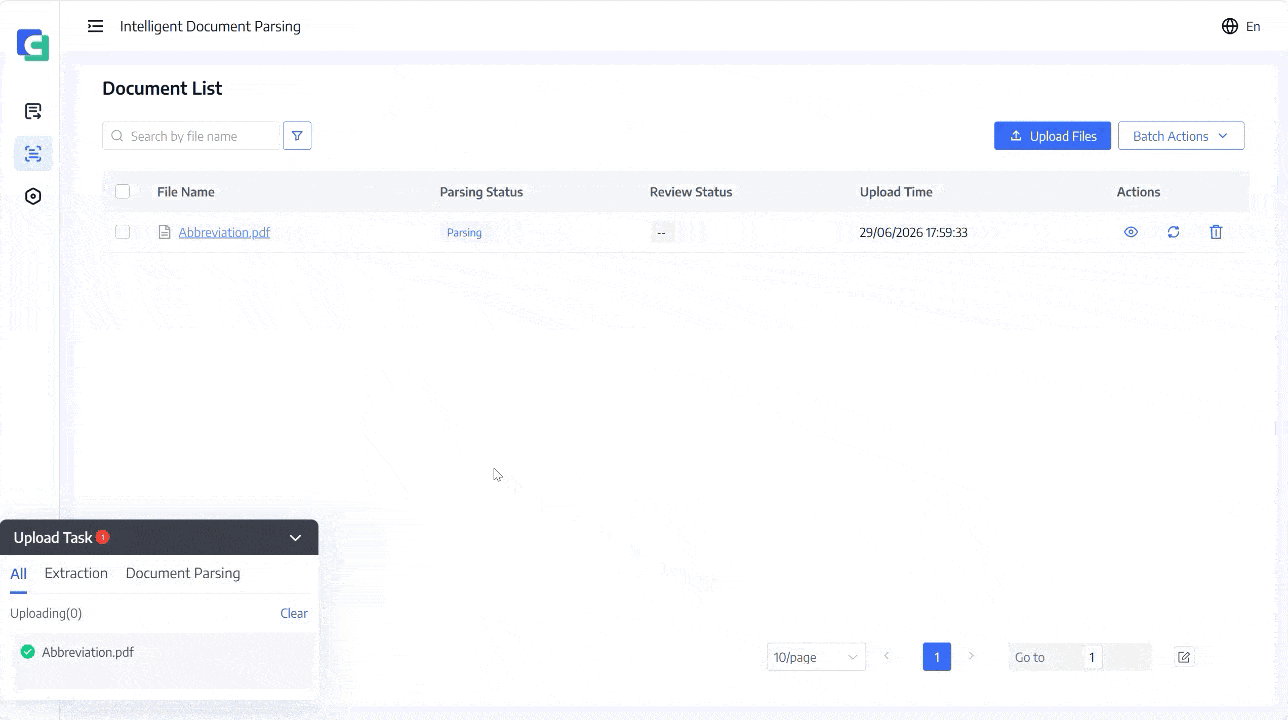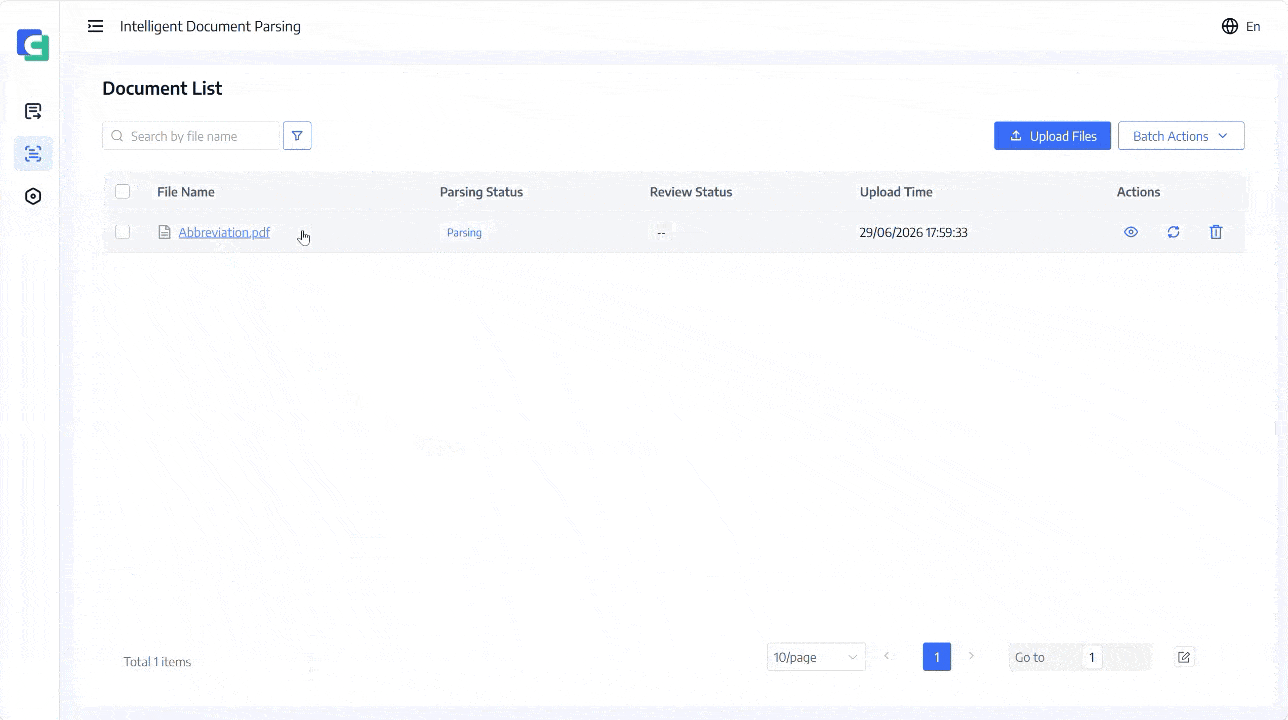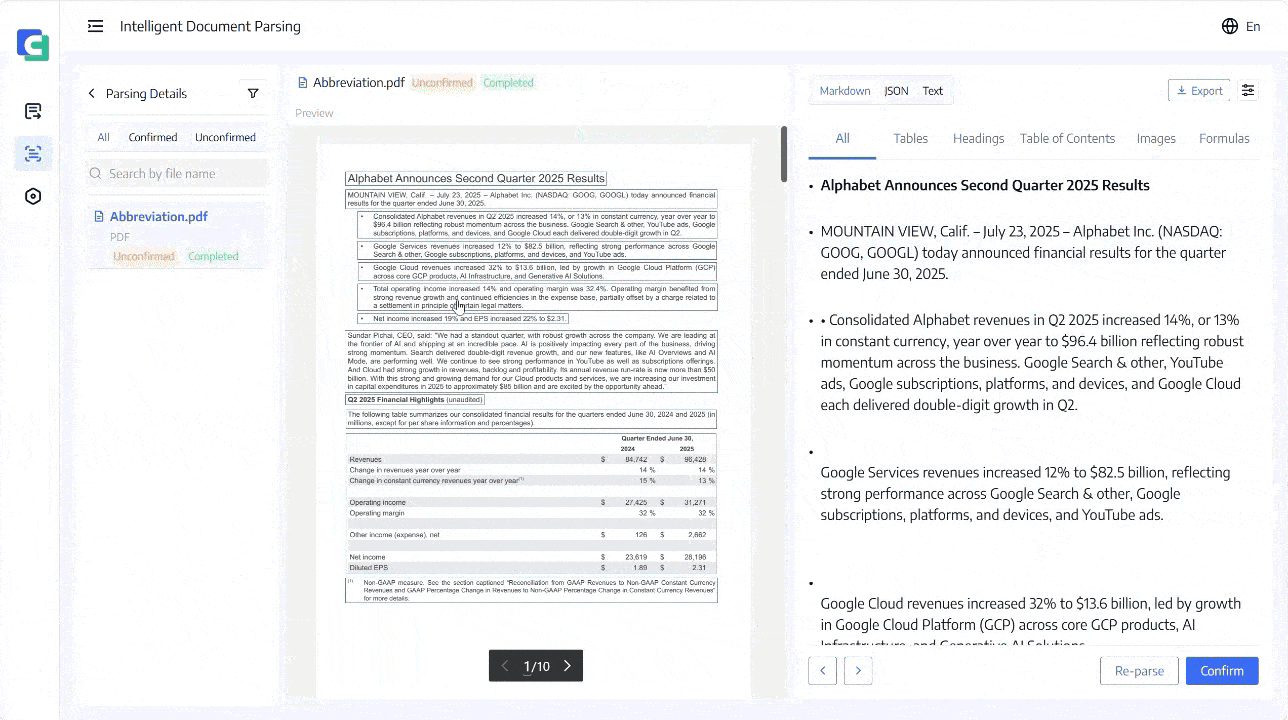
Part of the KDAN ecosystem, DocSlight offers document parsing, OCR, and data extraction that turn PDFs, scans, images, and Office files into structured outputs for RAG pipelines, AI agents, and enterprise document automation.
Your Personal Librarian Agent. Ask anything on your computer, organize files, remember important info and files.
本文原文由知名 Hacker Eric S. Raymond 所撰寫,教你如何正確的提出技術問題並獲得你滿意的答案。
| Name | Stars | License | Language | Last change | In common | Compare |
|---|---|---|---|---|---|---|
| ComPDFKit/docslight | 139 | LGPL-3.0 | Vue | 5 wk ago | ||
| NanoNets/docext | 2.1k | Apache-2.0 | Python | 8 mo ago | document-information-extraction, extraction, ocr | Compare |
| docling-project/docling | 71k | MIT | Python | 17 h ago | document-parser, document-parsing, pdf-to-json | Compare |
| PaddlePaddle/PaddleOCR | 93k | Apache-2.0 | Python | 2 mo ago | document-parsing, ocr, pdf-parser | Compare |
| TeamNewPipe/NewPipe | 41k | GPL-3.0 | Java | 3 d ago | Same need | Compare |
| huggingface/transformers | 169k | Apache-2.0 | Python | 59 min ago | Same need | Compare |
| Unstructured-IO/unstructured | 16k | Apache-2.0 | HTML | 3 d ago | document-parser, document-parsing, ocr | Compare |
| PDFMathTranslate/PDFMathTranslate | 39k | AGPL-3.0 | Python | 3 h ago | Same need | Compare |
| hiyouga/LlamaFactory | 76k | Apache-2.0 | Python | 1 d ago | Same need | Compare |
| ComPDF-derek/docslight | 52 | LGPL-3.0 | Vue | 4 mo ago | document-information-extraction, document-parser, document-parsing | Compare |
| Marker-Inc-Korea/AutoRAG | 6.1k | Apache-2.0 | TypeScript | 2 d ago | document-parser | Compare |
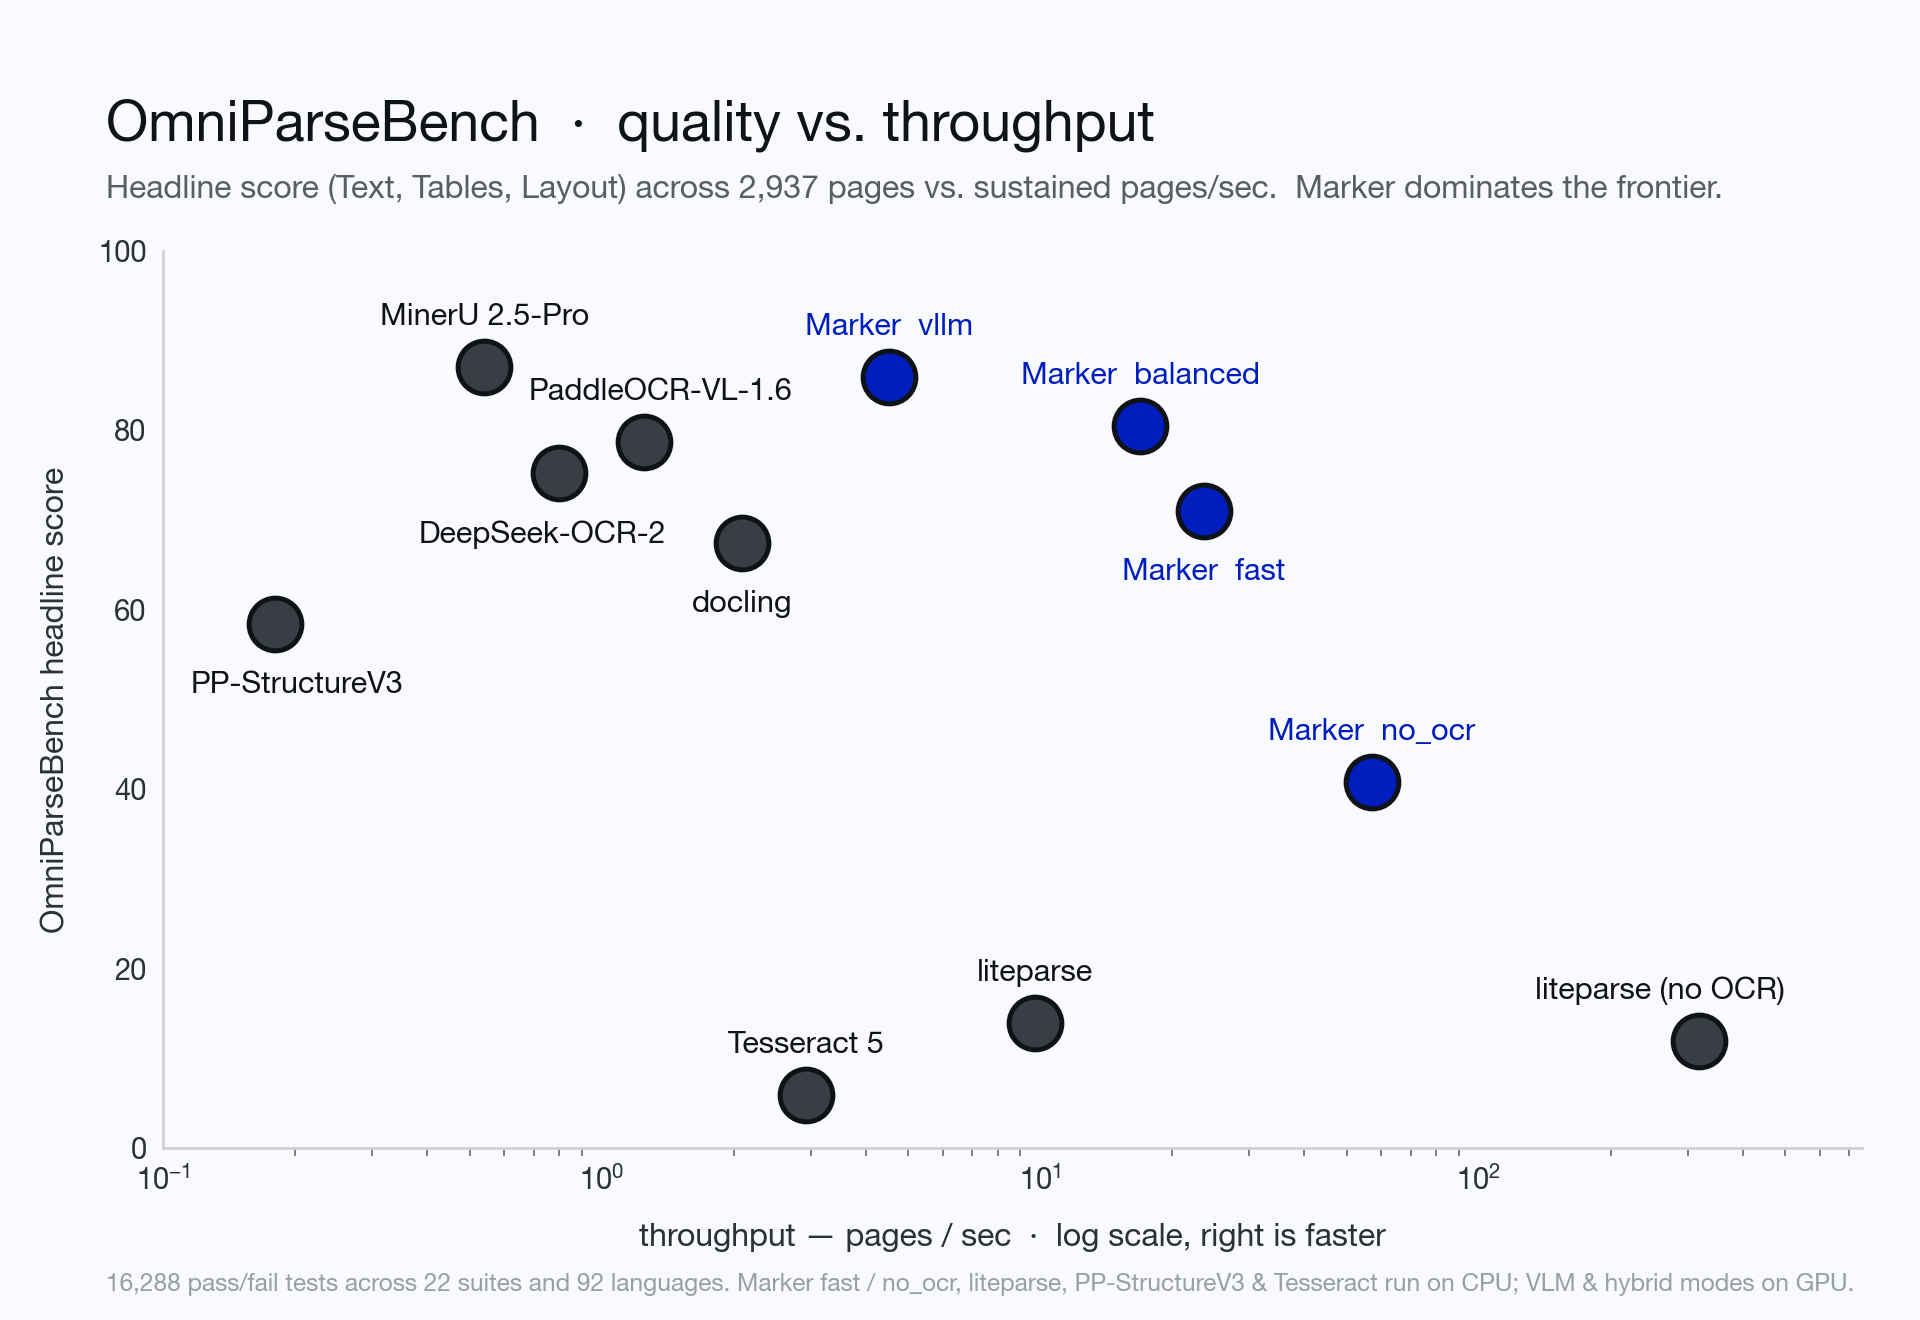
| datalab-to/marker | 41k | Apache-2.0 | Python | 2 d ago | document-parsing, ocr, pdf-parser | Compare |
| ryanhanwu/How-To-Ask-Questions-The-Smart-Way | 36k | MIT | JavaScript | 23 mo ago | Same need | Compare |