PaddleOCR
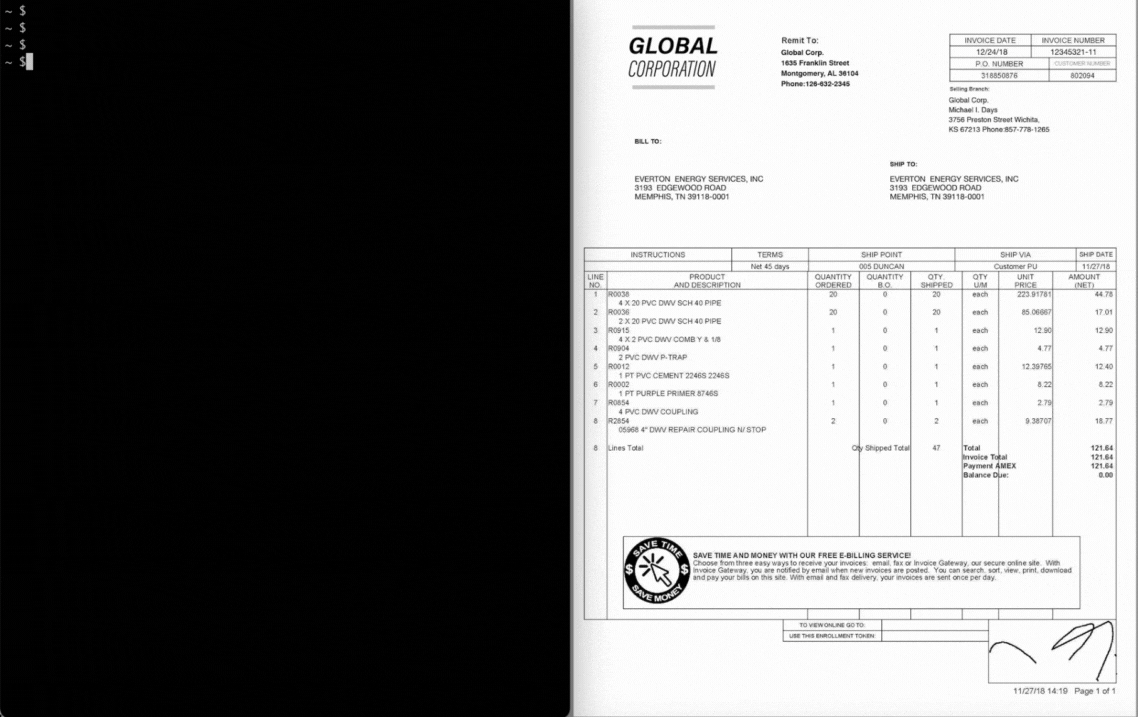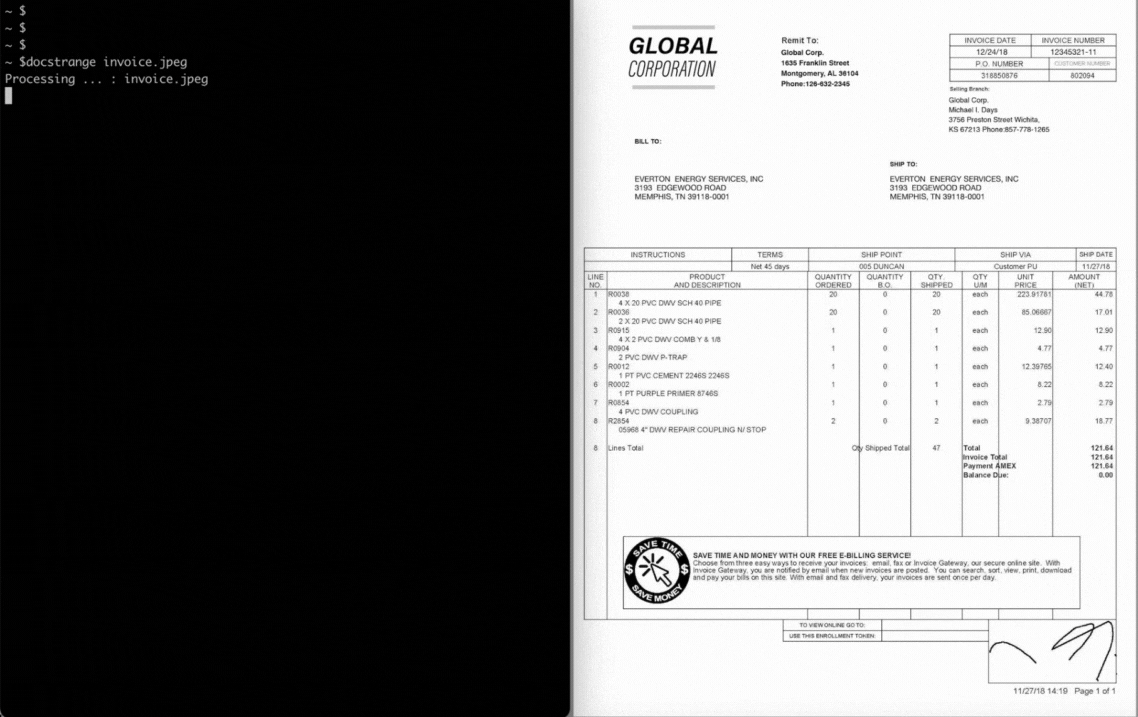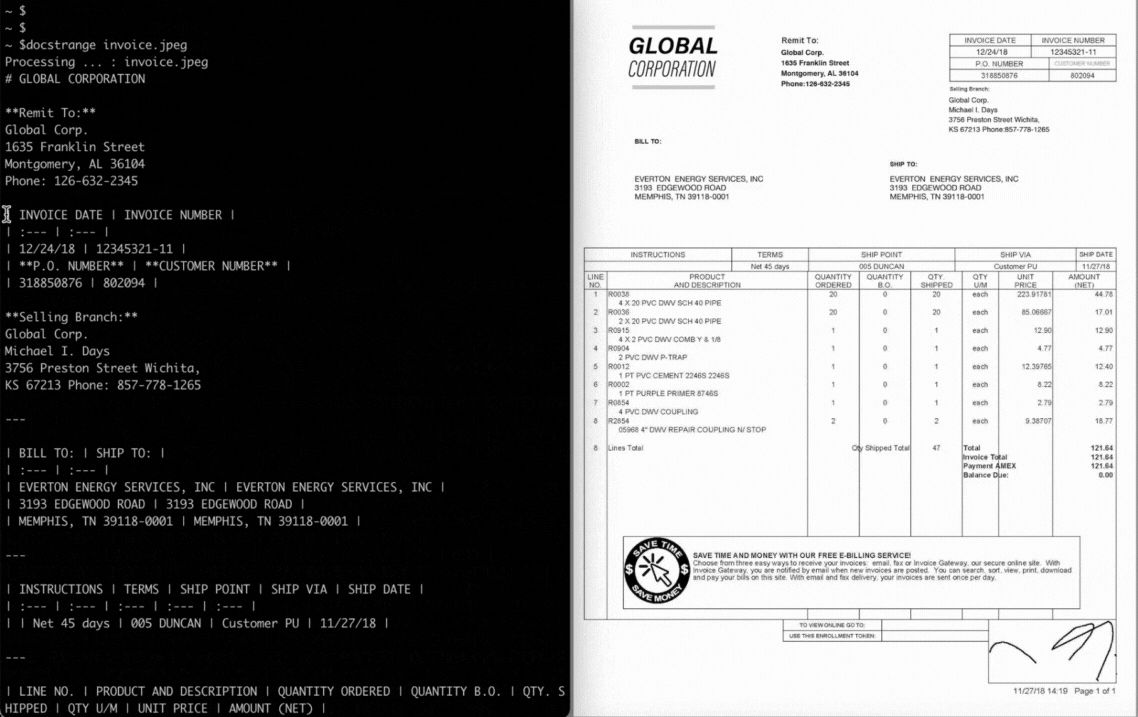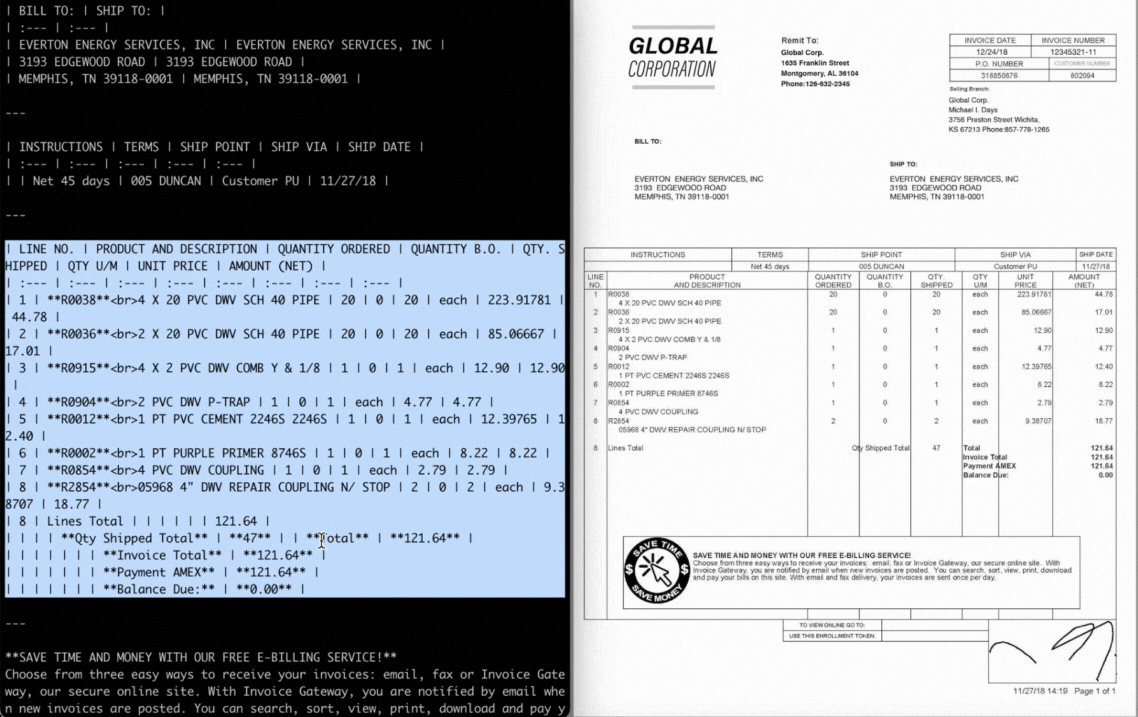
Turn any PDF or image document into structured data for your AI. A powerful, lightweight OCR toolkit that bridges the gap between images/PDFs and LLMs. Supports 100+ languages.
- 93k
- Python
- Apache-2.0
- 2 mo ago
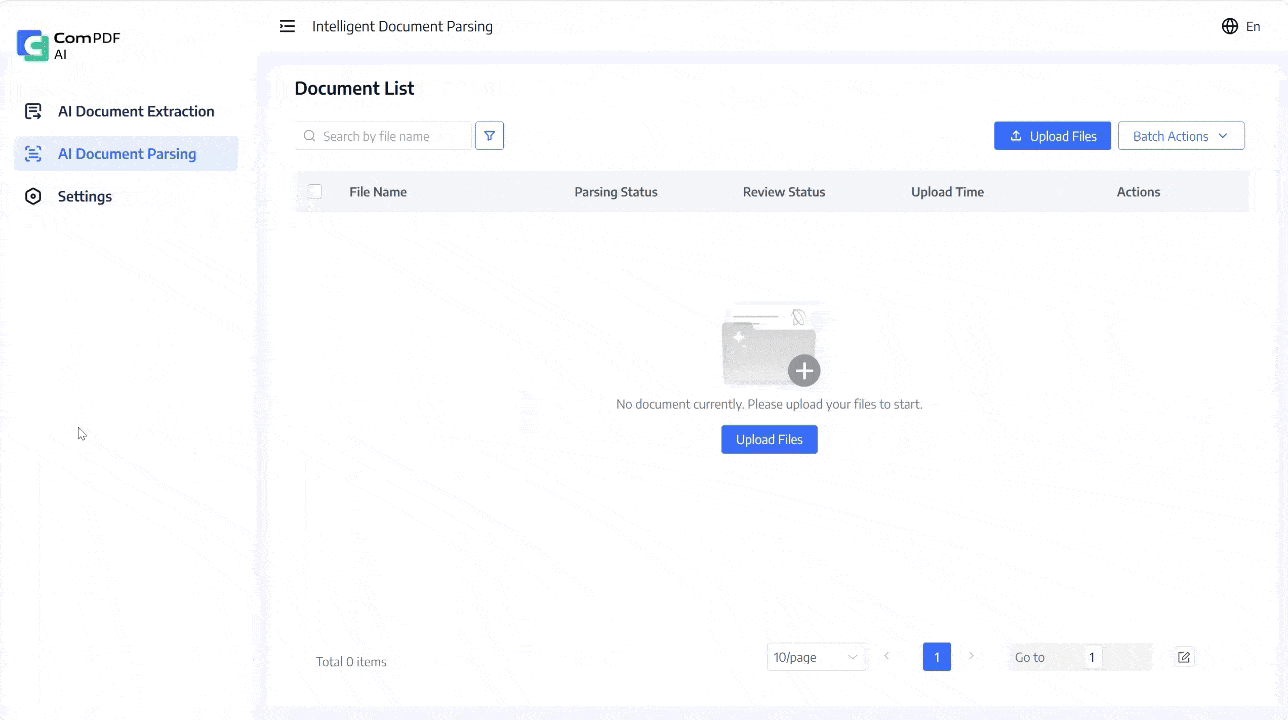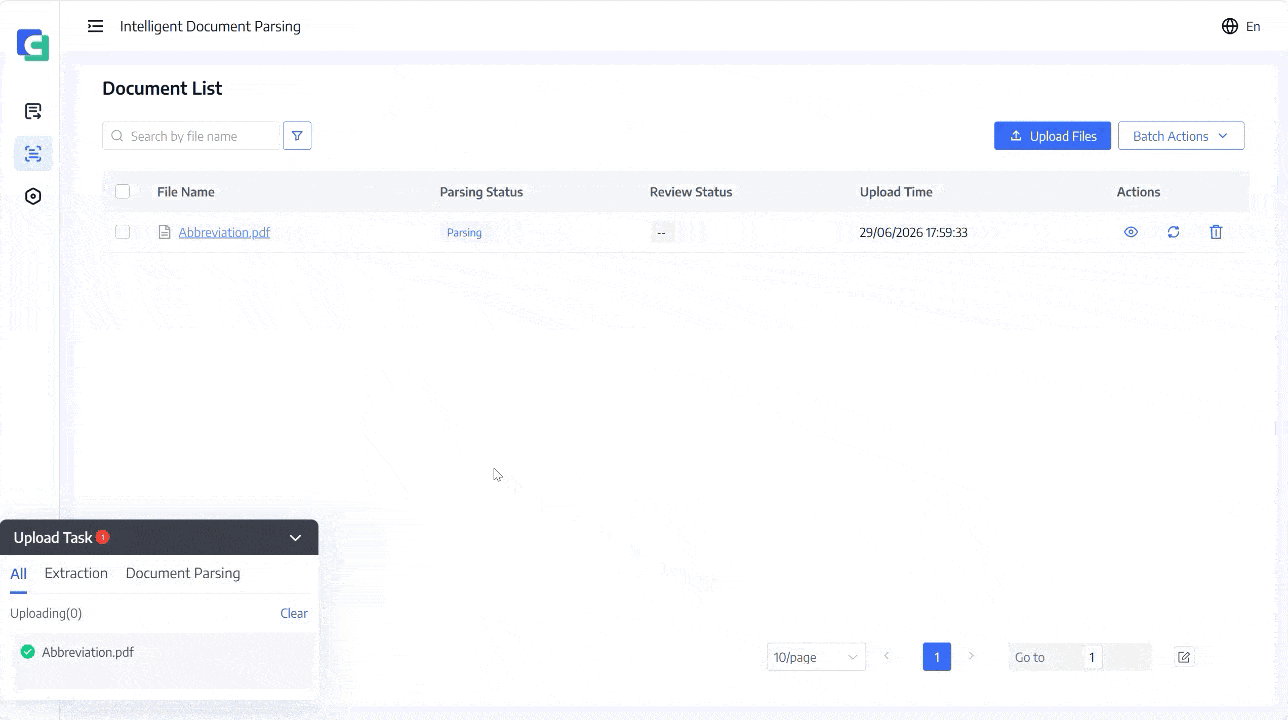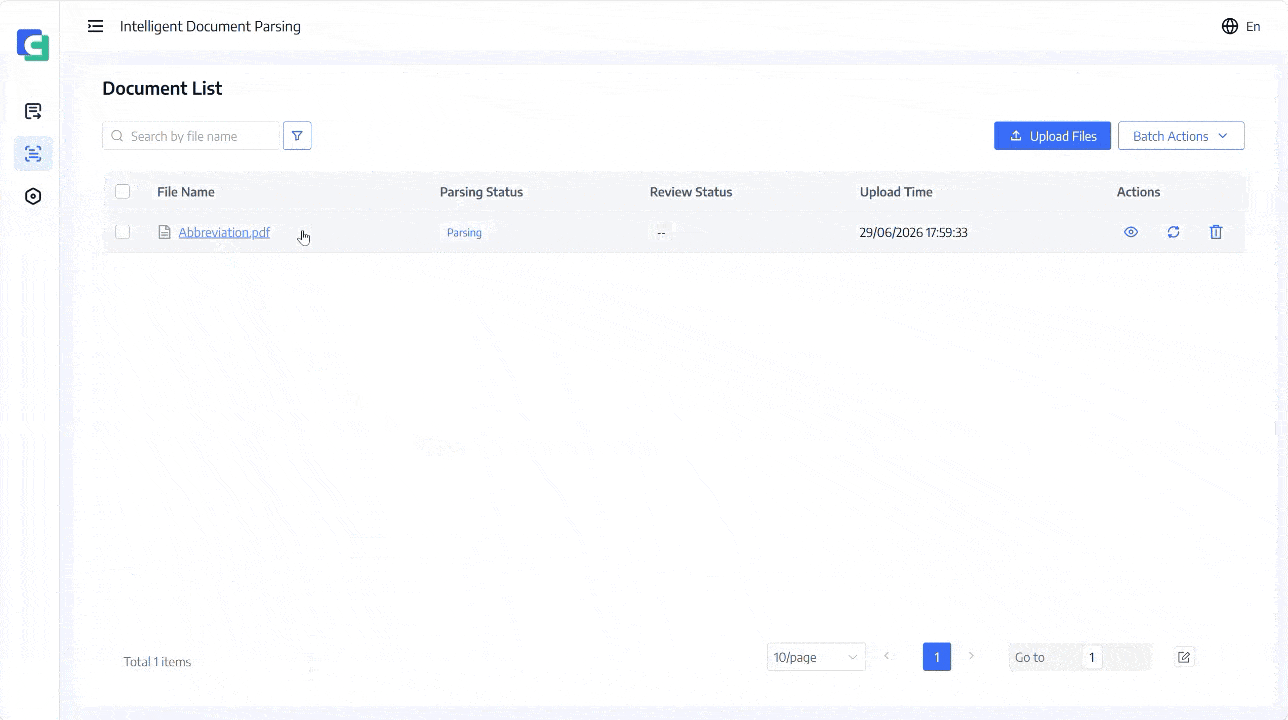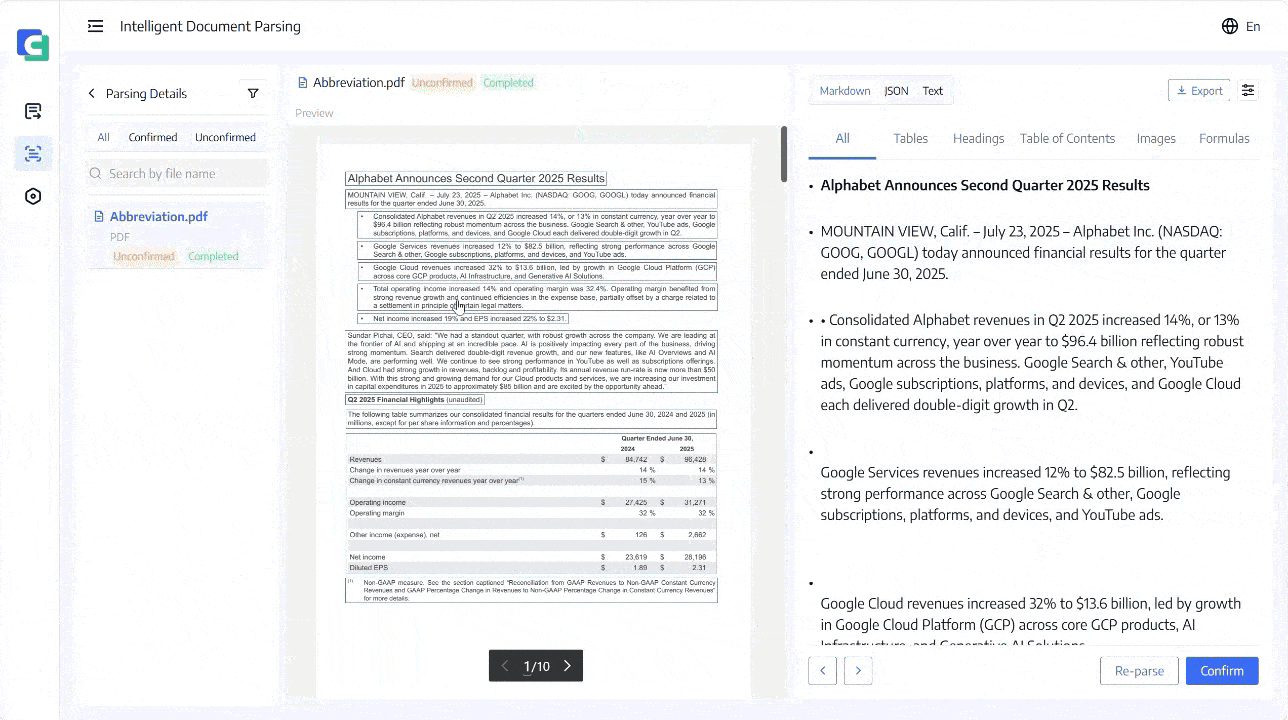
Turn any PDF or image document into structured data for your AI. A powerful, lightweight OCR toolkit that bridges the gap between images/PDFs and LLMs. Supports 100+ languages.
PDF Parser for AI-ready data. Automate PDF accessibility. Open-source.
Convert documents to structured data effortlessly. Unstructured is open-source ETL solution for transforming complex documents into clean, structured formats for language models. Visit our website to learn more about our enterprise grade Platform product for production grade workflows, partitioning, enrichments, chunking and embedding.
OCR model that handles complex tables, forms, handwriting with full layout.
docTR (Document Text Recognition) - a seamless, high-performing & accessible library for OCR-related tasks powered by Deep Learning. Ongoing development and maintenance by t2k.
The official CLI for Agentic Document Extraction (ADE) by LandingAI — parse documents and extract schema-shaped data from your terminal
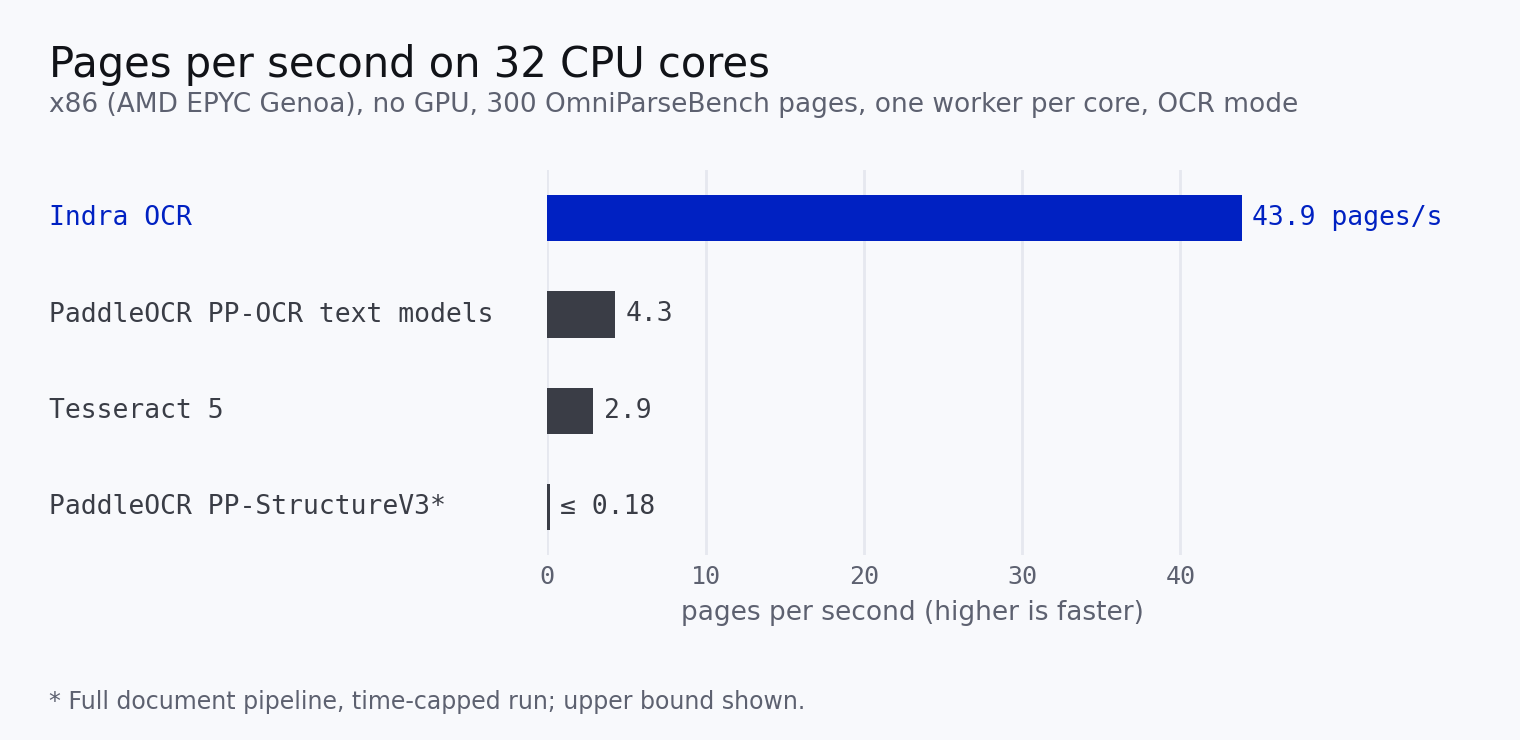
1M param OCR model - runs on CPU, 15x faster than tesseract, close to 1B+ param models in accuracy
ExtractThinker is a Document Intelligence library for LLMs, offering ORM-style interaction for flexible and powerful document workflows.
Extract and convert data from any document, images, pdfs, word doc, ppt or URL into multiple formats (Markdown, JSON, CSV, HTML) with intelligent structured data extraction and advanced OCR.
OpenOCR: An Open-Source Toolkit for General-OCR Research and Applications, integrates a unified training and evaluation benchmark, commercial-grade OCR and Document Parsing systems, and faithful reproductions of the core implementations from a wide range of academic papers.
Agentic RAG for local and self-hosted document search: hybrid retrieval, reranking and multimodal RAG on embedded LanceDB, with Docling parsing and an MCP server
Hybrid RAG system combining vector search, knowledge graph (LightRAG), and cross-encoder reranking — with Docling document parsing, visual intelligence (image/table captioning), agentic streaming chat, and inline citations. Powered by Gemini or local Ollama models.
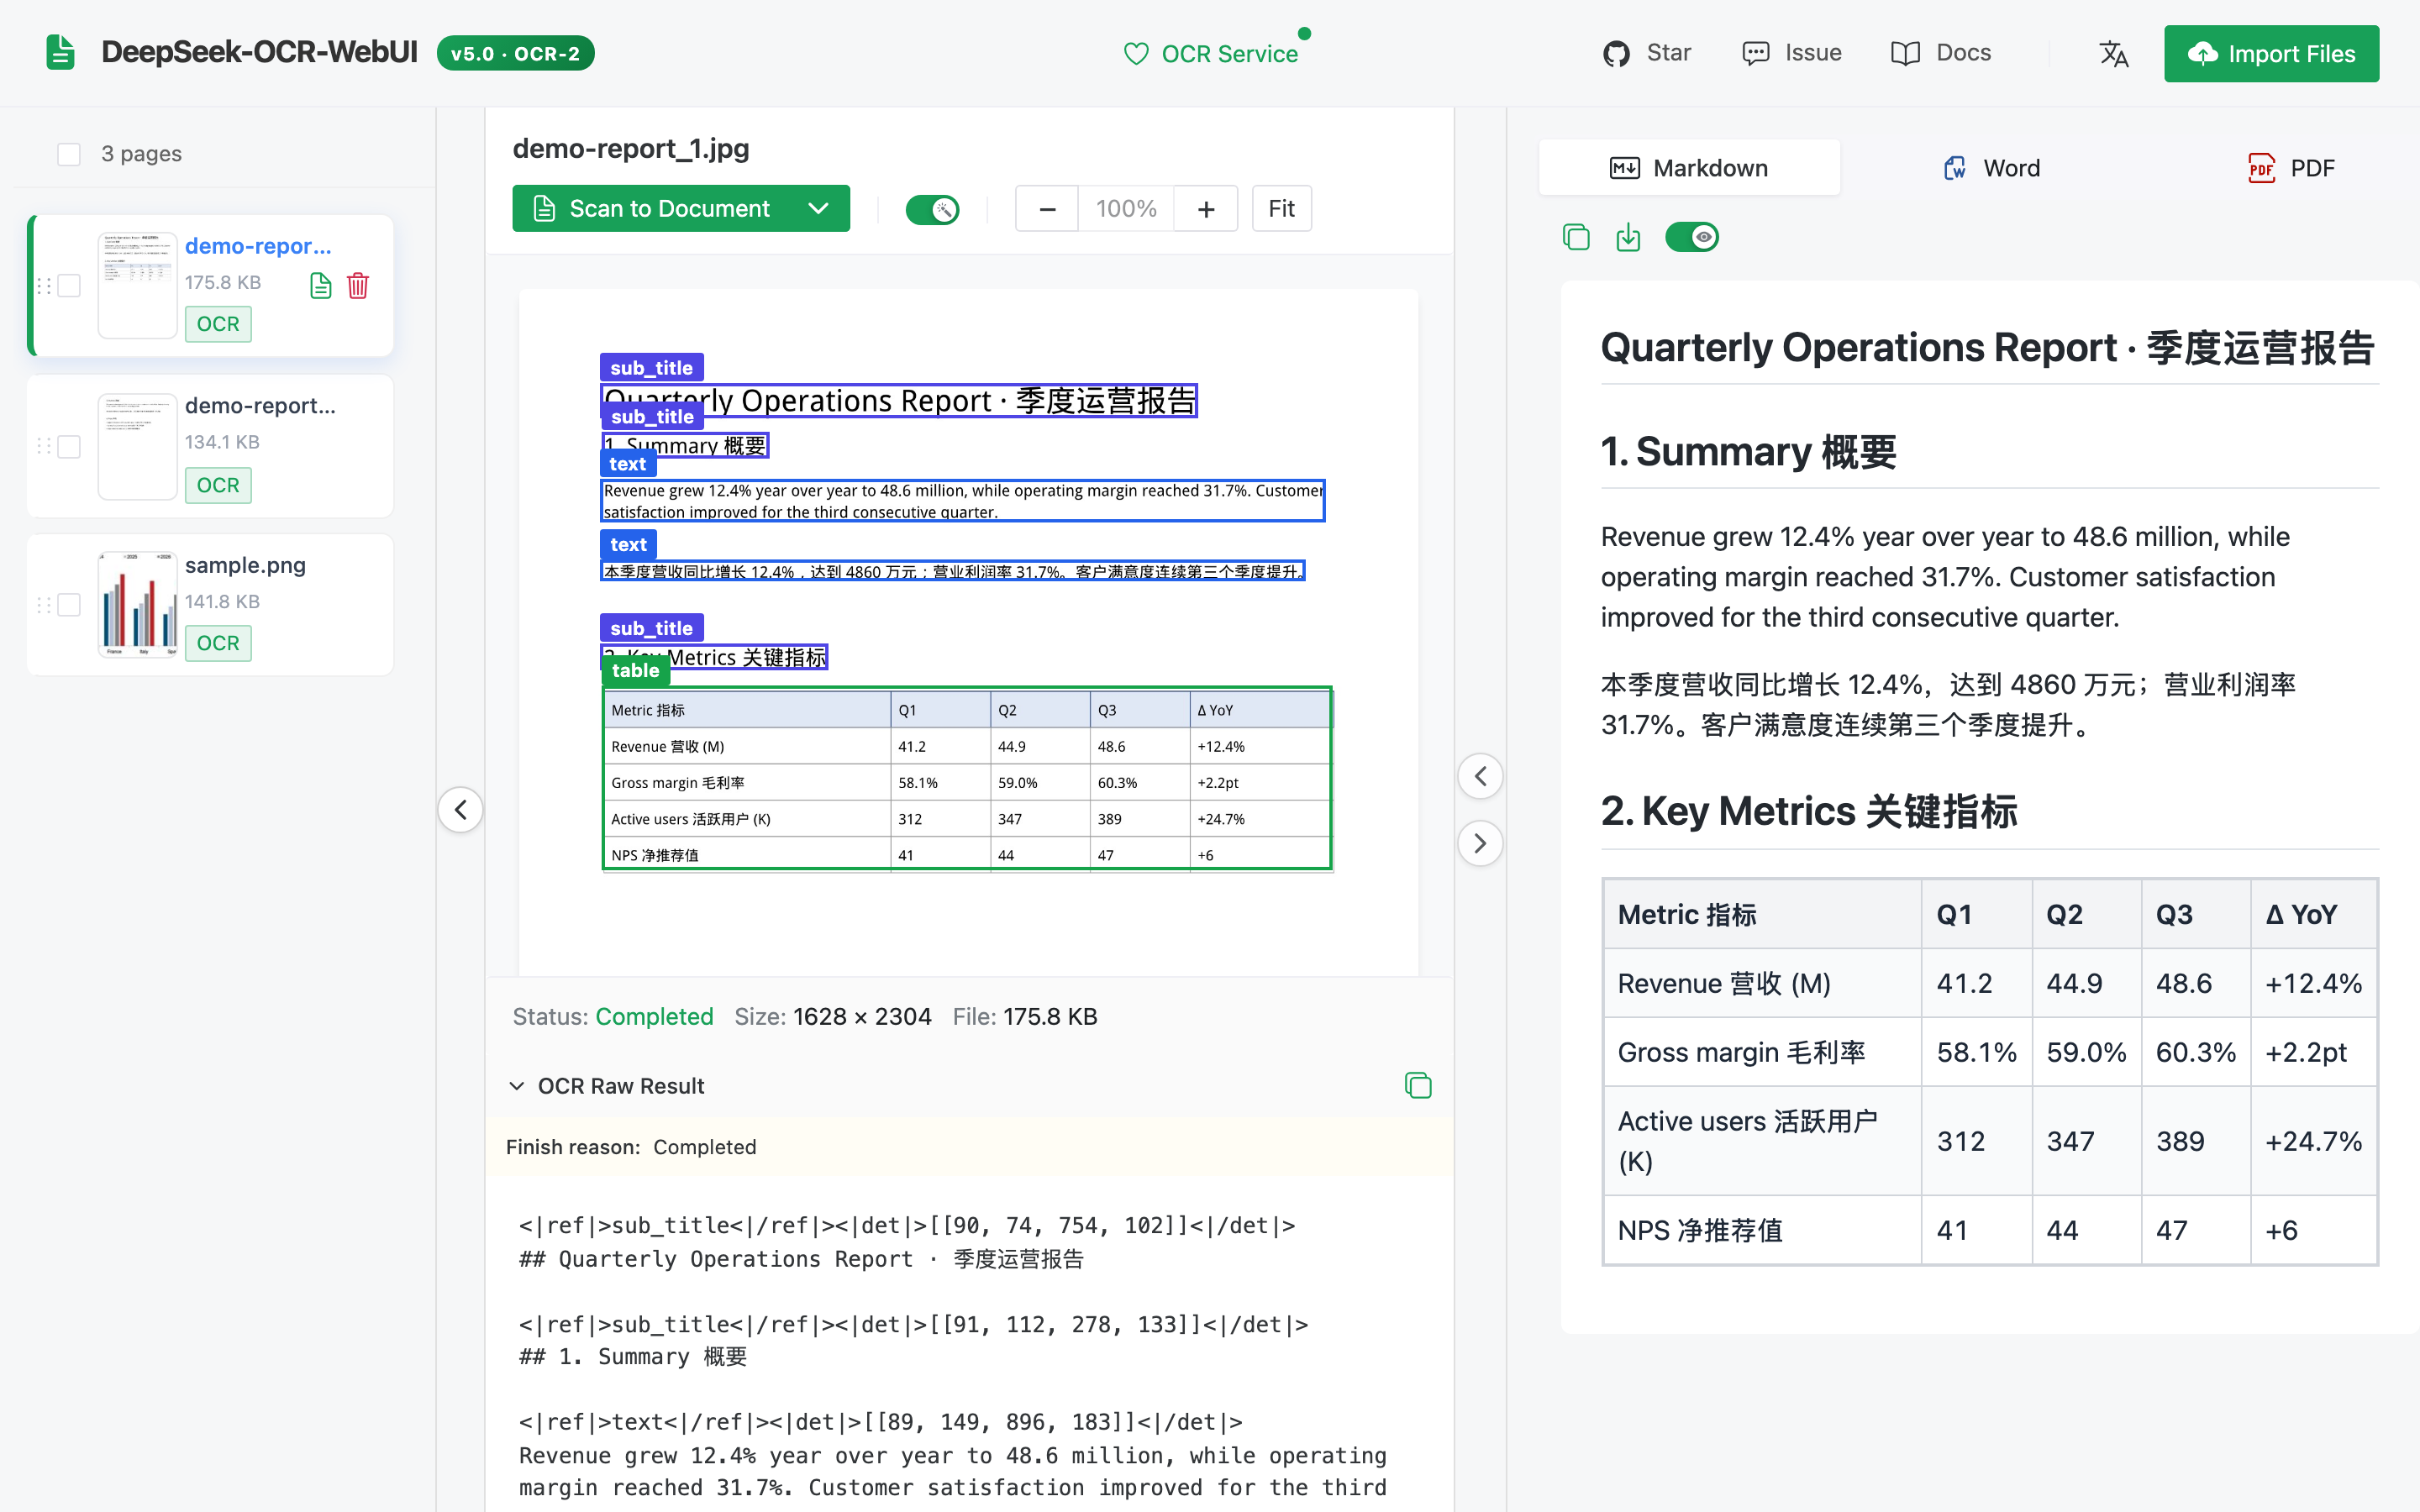
Self-hosted DeepSeek-OCR-2 WebUI & API — vLLM / transformers on NVIDIA, Apple Silicon & CPU, per-page quality checks, PDF streaming, MCP
With DocSlight, precisely parse and extract data from any document, including PDFs, scans, images, and Office files. It is an open-source AI project from ComPDF (KDAN ecosystem).
Local-first web & document ingestion engine in Rust — HTTP/browser capture, layout-aware PDF/Office/OCR parsing, persistent sync, verifiable data graphs, and evidence-grounded AI context.
Self-hosted RAG search engine — 34 formats, BM25+hybrid search, multi-LLM (Gemini/OpenAI/Claude/Ollama), FastAPI + Docker, production-ready in 3 min
Get your documents ready for gen AI, in pure Go. A Go alternative to anydoc & Docling — 纯 Go 实现的文档解析库:PDF/Word/PPT/Excel/HTML/Markdown/EML/图片等 12 种格式统一解析为 Docling 协议(Markdown/JSON/content_list),表格还原·多栏阅读顺序·图表数据回填,OCR 收敛为一个大模型接口,单二进制零依赖,快 34~153 倍。联犀物联网平台知识库同款引擎。
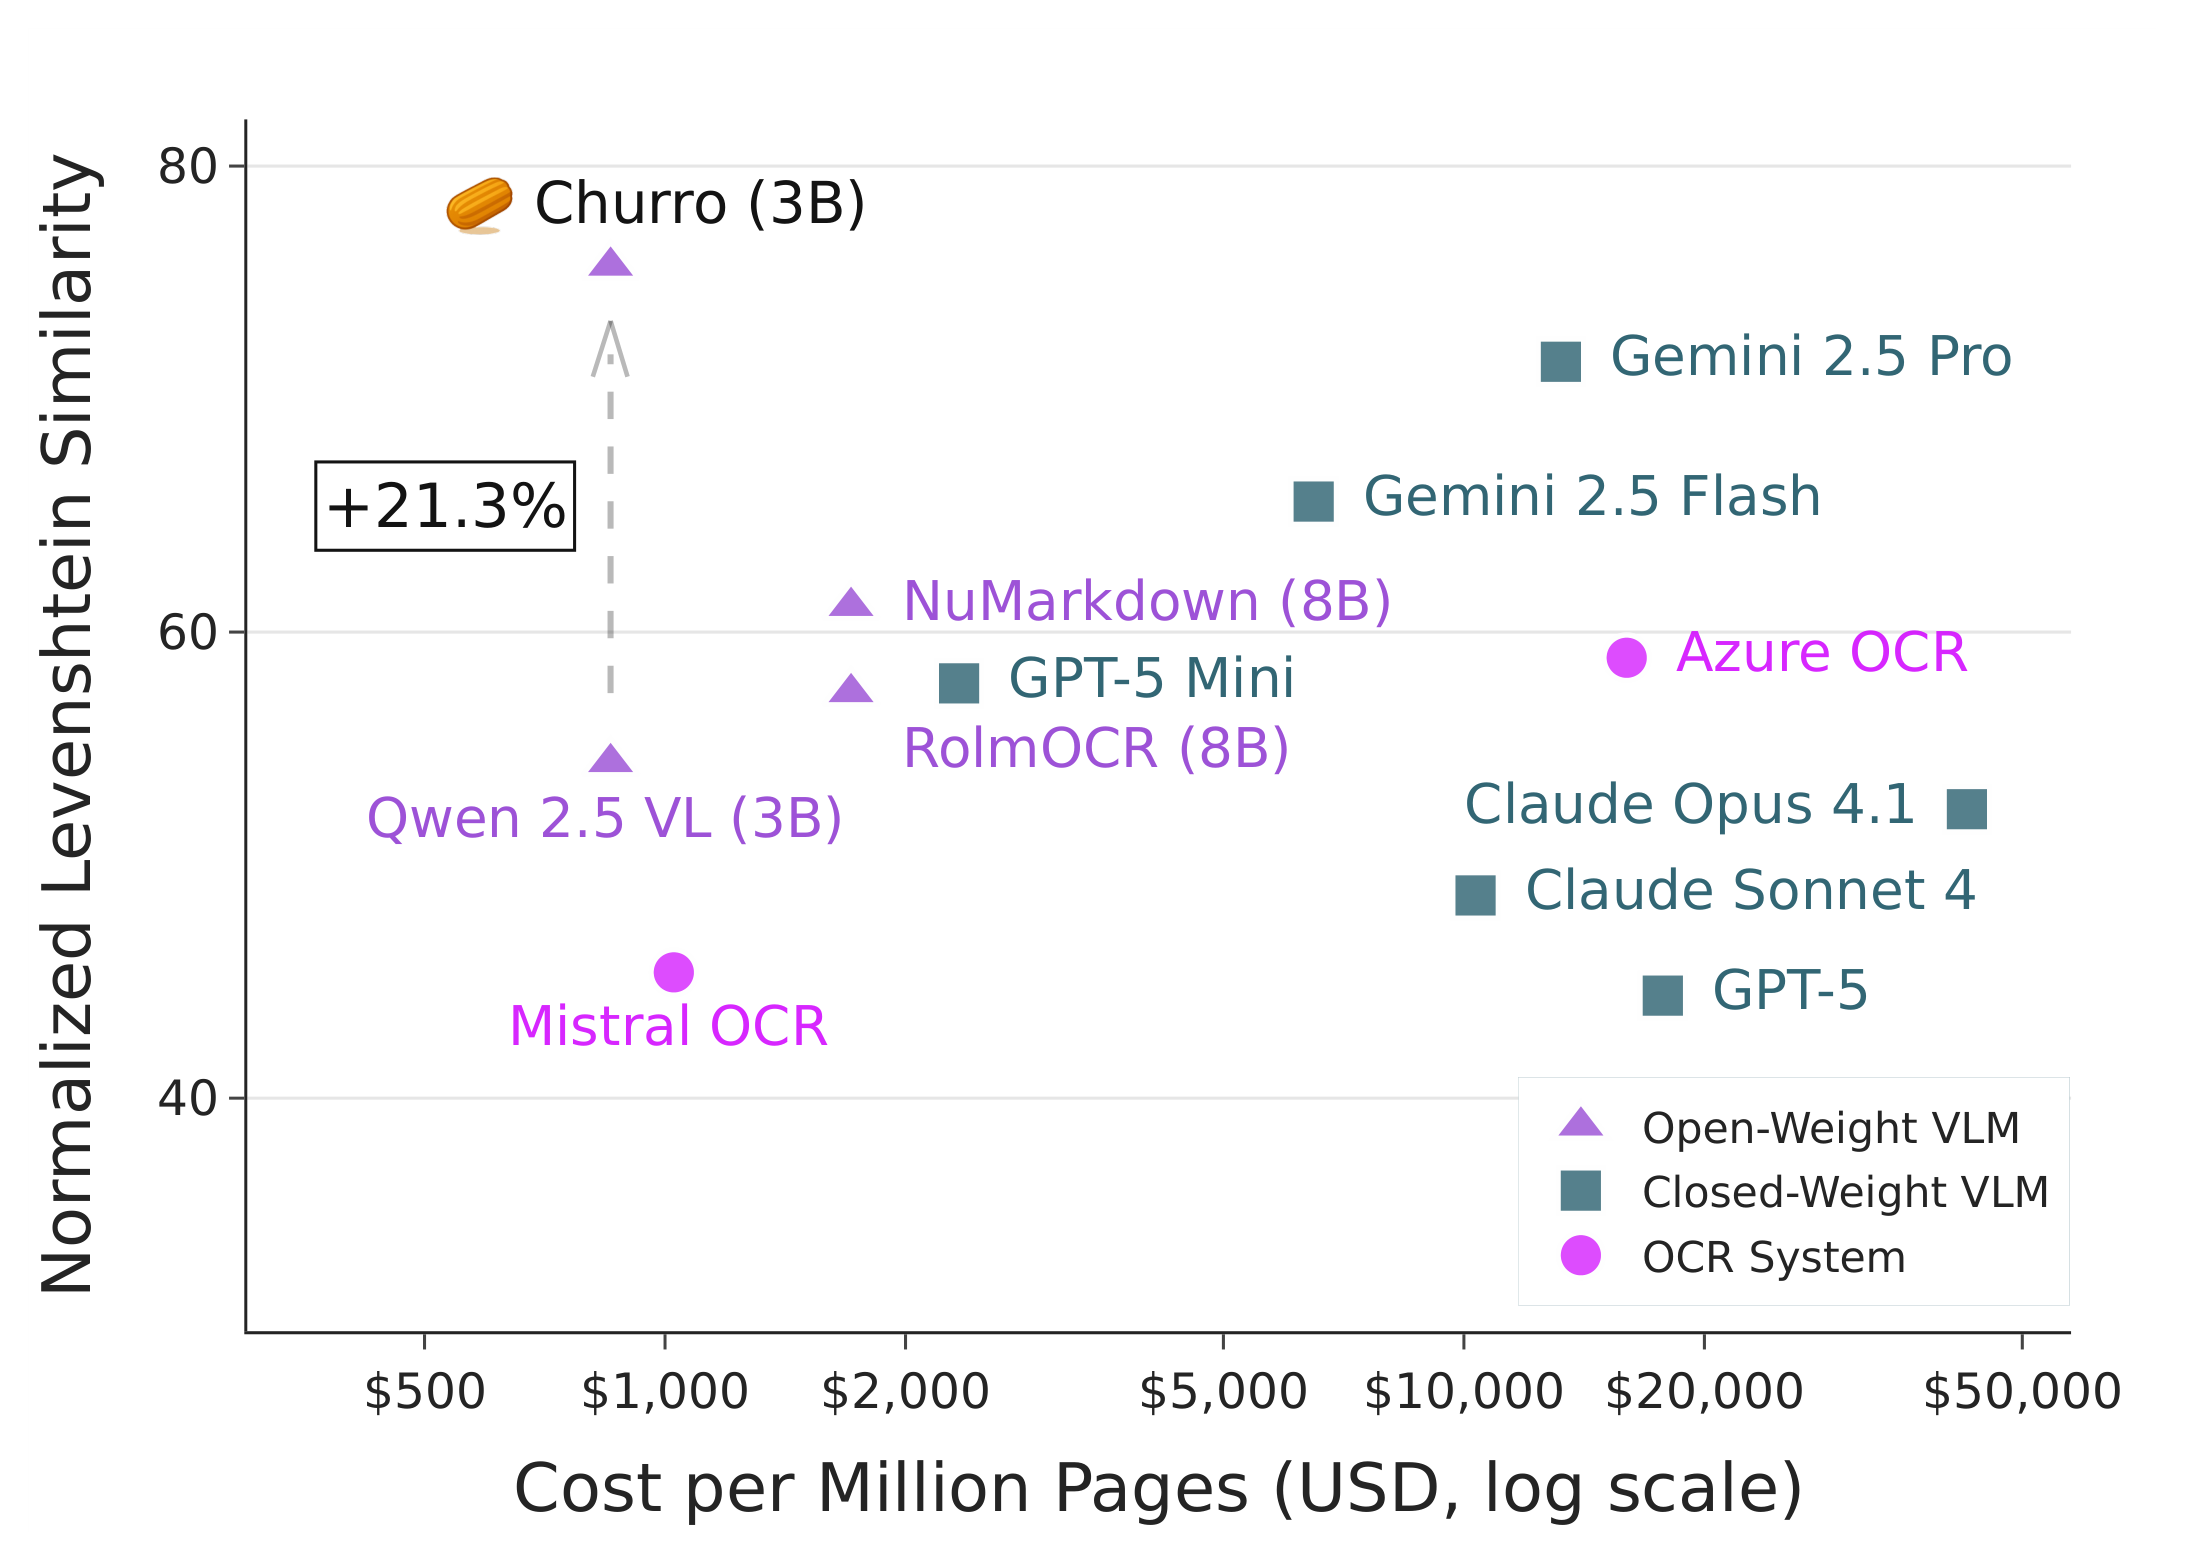
CHURRO is an OCR toolkit for historical document transcription, built to make handwritten and printed sources readable at high accuracy and lower cost.
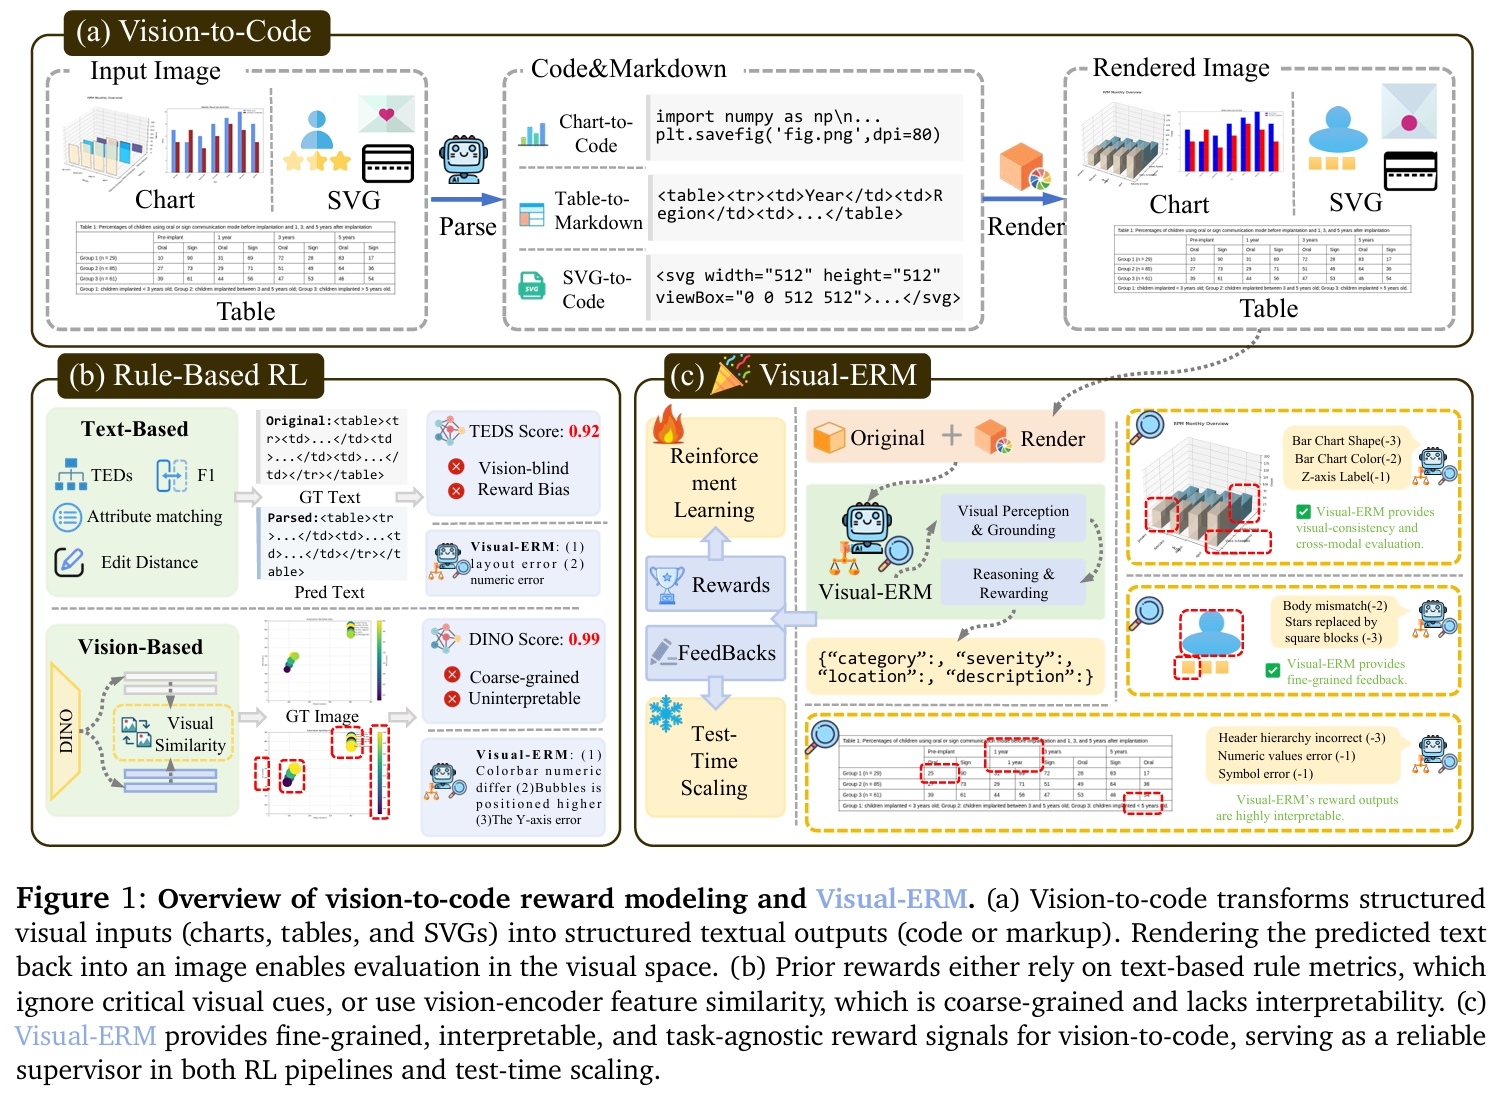
[NeurIPS 2026] Official Implementation of "Visual-ERM: Reward Modeling for Visual Equivalence"
Part of the KDAN ecosystem, DocSlight offers document parsing, OCR, and data extraction that turn PDFs, scans, images, and Office files into structured outputs for RAG pipelines, AI agents, and enterprise document automation.
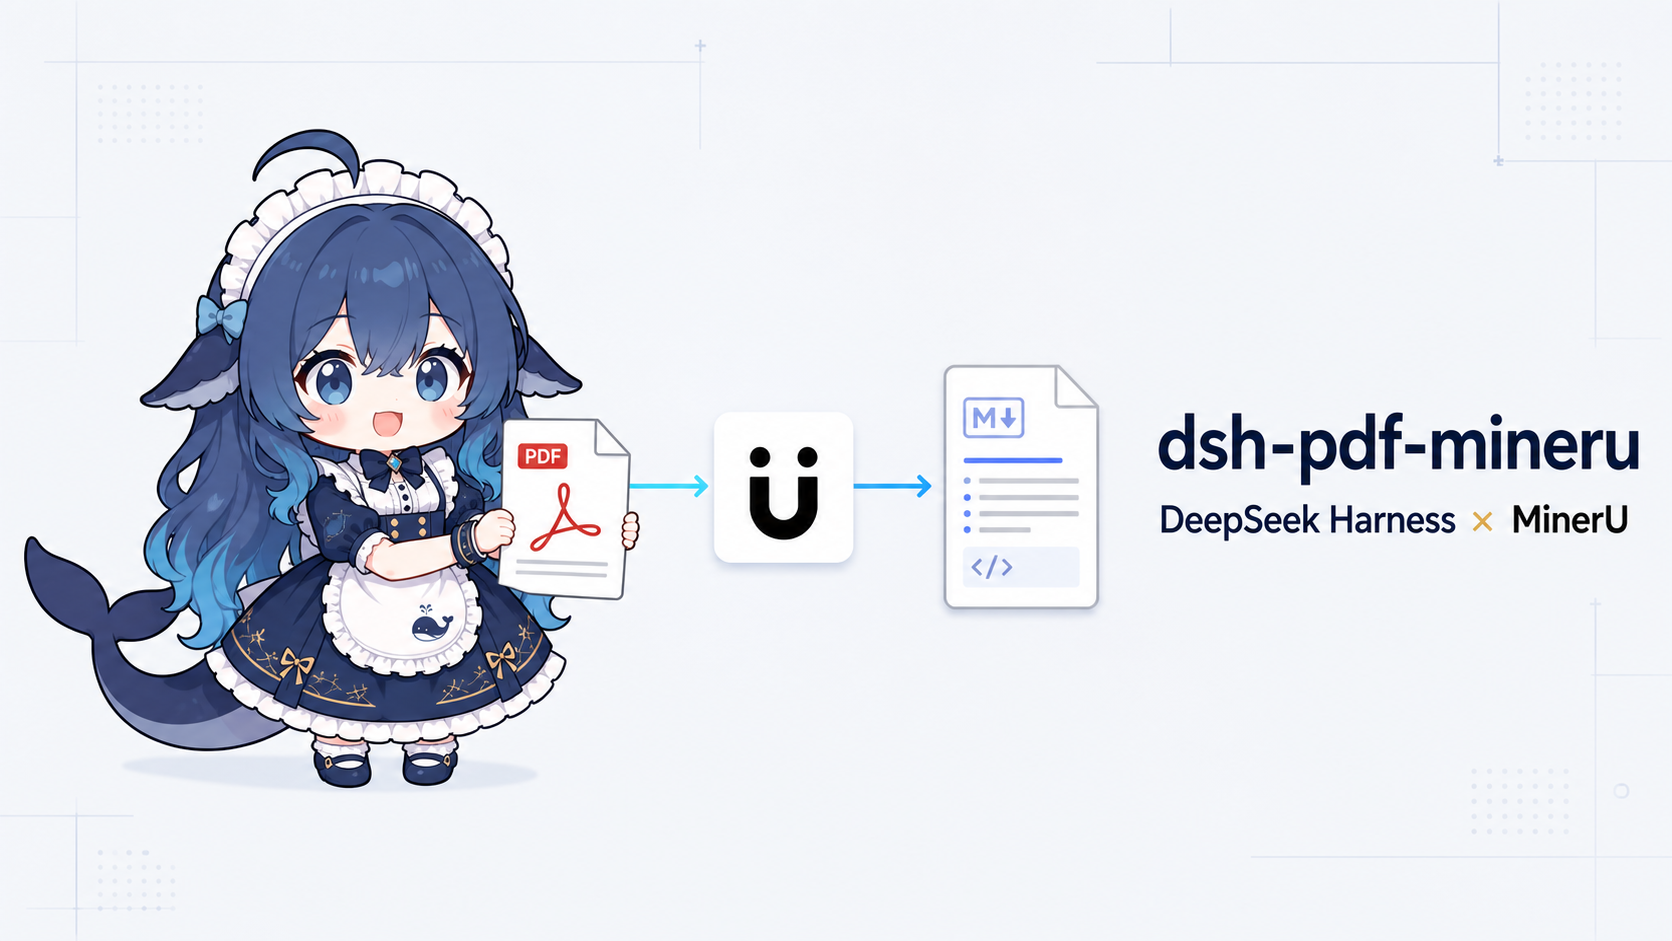
Convert PDF, Office, HWP/HWPX, OpenDocument, RTF, EPUB, HTML, email and images into clean, LLM-ready Markdown.
Next-Gen High-Precision Doc Parsing Solution
Runs in the browser on Hugging Face
Privacy-first document intelligence engine — parse PDFs, DOCX, PPTX, XLSX & CSV into AI-ready chunks for RAG pipelines. Includes HITL review, 3-layer memory chat, and a production FastAPI server.
Document intelligence APIs for enterprise documents
Runs in the browser on Hugging Face
NaviDC-OCR: This Tiny 1.2B Model Beats Paid OCR APIs (100% Local) - Lightweight 1.2B open-source vision parser for local document & whiteboard OCR.
Side-by-side OCR, MiniCPM-OCR 1.0 vs Unlimited-OCR-2
Runs in the browser on Hugging Face
ParseCrate: self-hosted document processing API powered by Docling and docling-serve. Converts PDF, DOCX, PPTX, HTML, and more to Markdown/JSON. Sync/async conversion, RAG chunking, optional web UI, offline mode with cached models, and persistent model caching. Docker deployment on CPU (amd64/arm64) or NVIDIA GPU (CUDA, amd64).
C# SDK for the LlamaParse API -- document parsing, extraction, RAG pipelines, and file management
Python scripts to parse and structure invoice data from PDFs using OpenAI, Anthropic and Invofox APIs
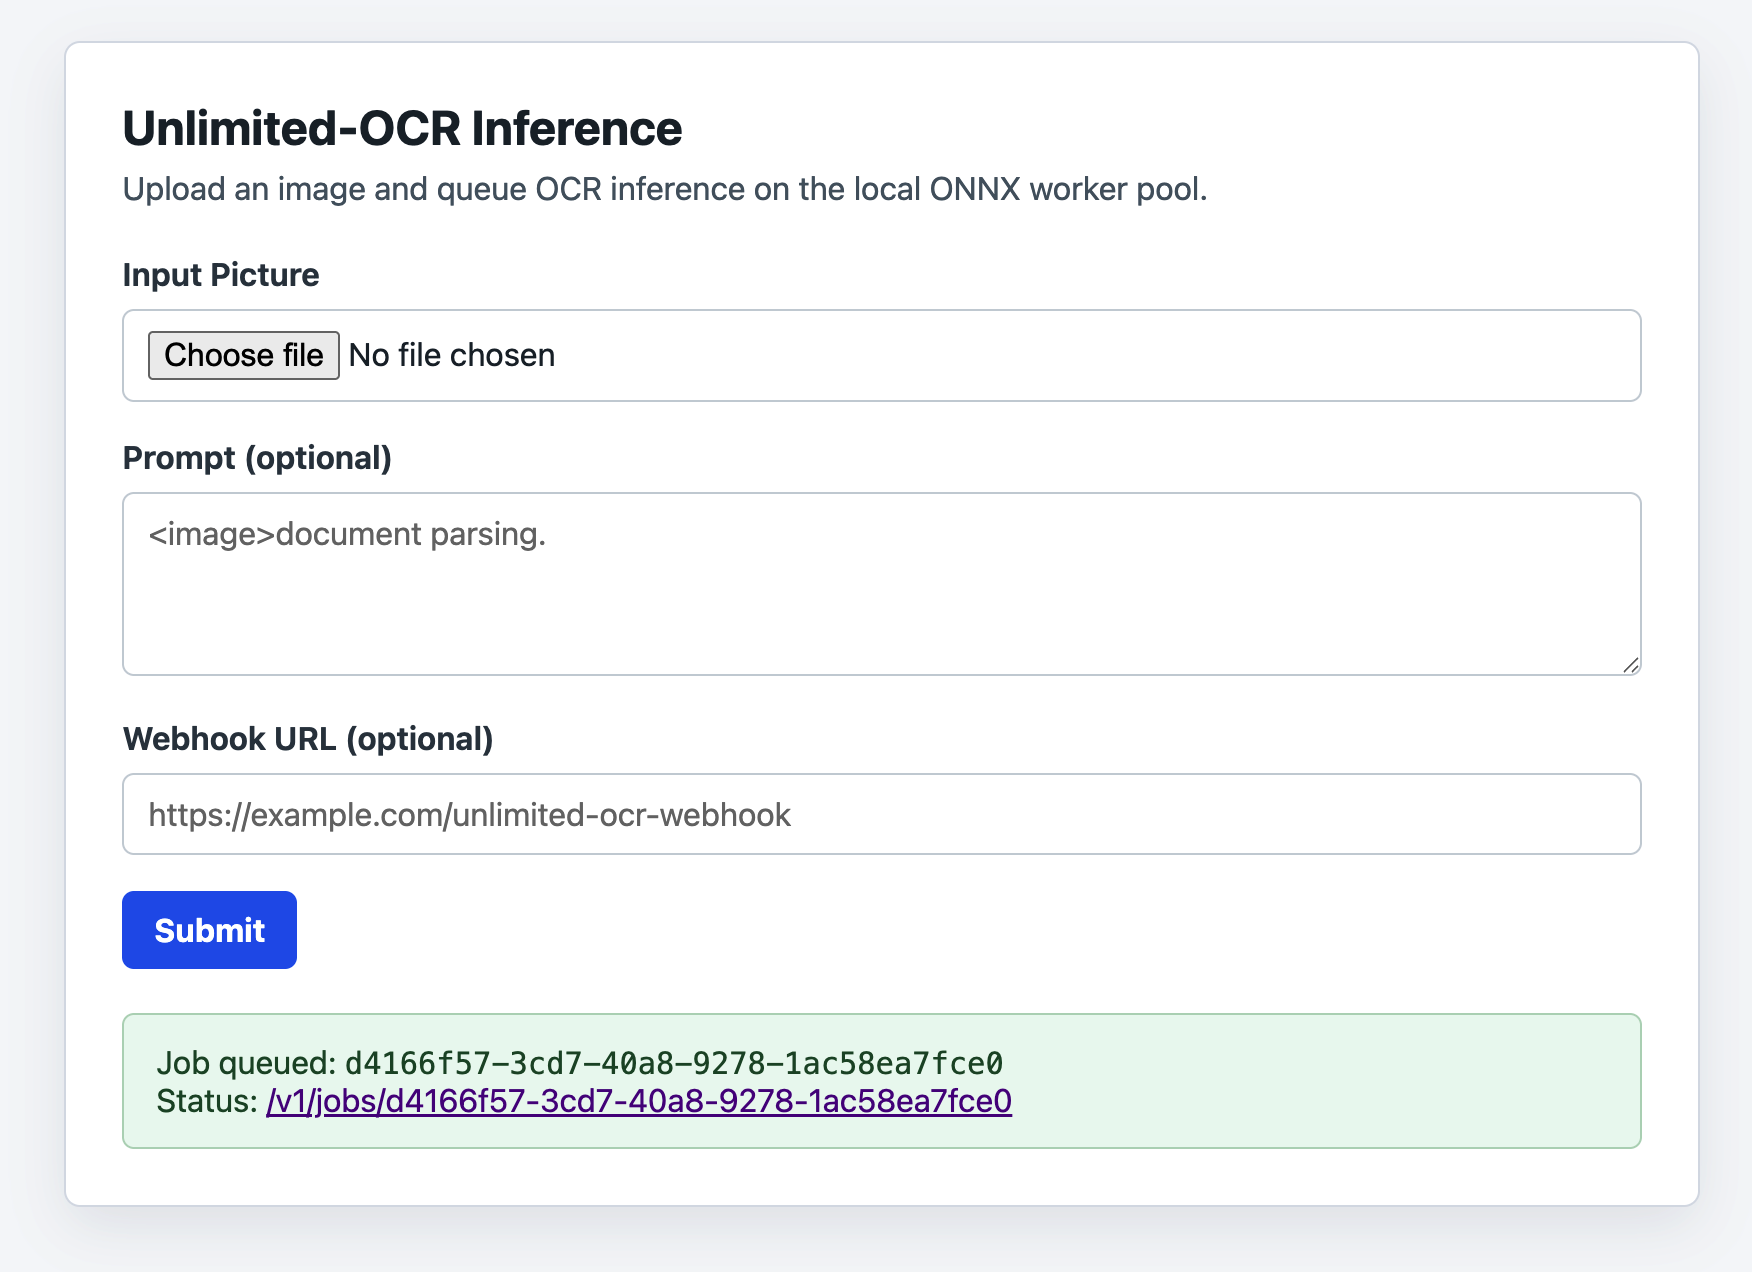
Free, open-source Google Colab notebook that converts PDF & image files (JPG, PNG, BMP, TIFF, WEBP) into clean Markdown using Baidu's Unlimited-OCR (MIT license, 93%+ OmniDocBench). No API key, no cost — runs on free Colab GPU. PDF to Markdown, OCR, document parsing, image to text converter.
Compare OCR engines on images & PDFs, in your browser
Runs in the browser on Hugging Face
Unlimited-horizon parsing studio for baidu/Unlimited-OCR-2
Runs in the browser on Hugging Face
PDF to Markdown in reading order, in your browser
Runs in the browser on Hugging Face