LLMs-from-scratch
Implement a ChatGPT-like LLM in PyTorch from scratch, step by step
- 109k
- Jupyter Notebook
- 11 d ago
Code for Comprehensive Attention Convolutional Neural Networks for Explainable Medical Image Segmentation.
Repo HiLab-git/CA-Net, read from GitHub 1 min ago. HiLab-git has not joined Take My Repo.
HiLab-git/CA-Net is a public repo on GitHub by HiLab-git. Code for Comprehensive Attention Convolutional Neural Networks for Explainable Medical Image Segmentation. It declares no license on GitHub. Public does not mean open source: without a license, nobody is granted the right to reuse it. It is written mainly in Python, has 176 stars and last changed on 2021-01-20. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-20.
This repository provides the code for "CA-Net: Comprehensive attention Convolutional Neural Networks for Explainable Medical Image Segmentation". Our work now is available on Arxiv. Our work is accepted by TMI.
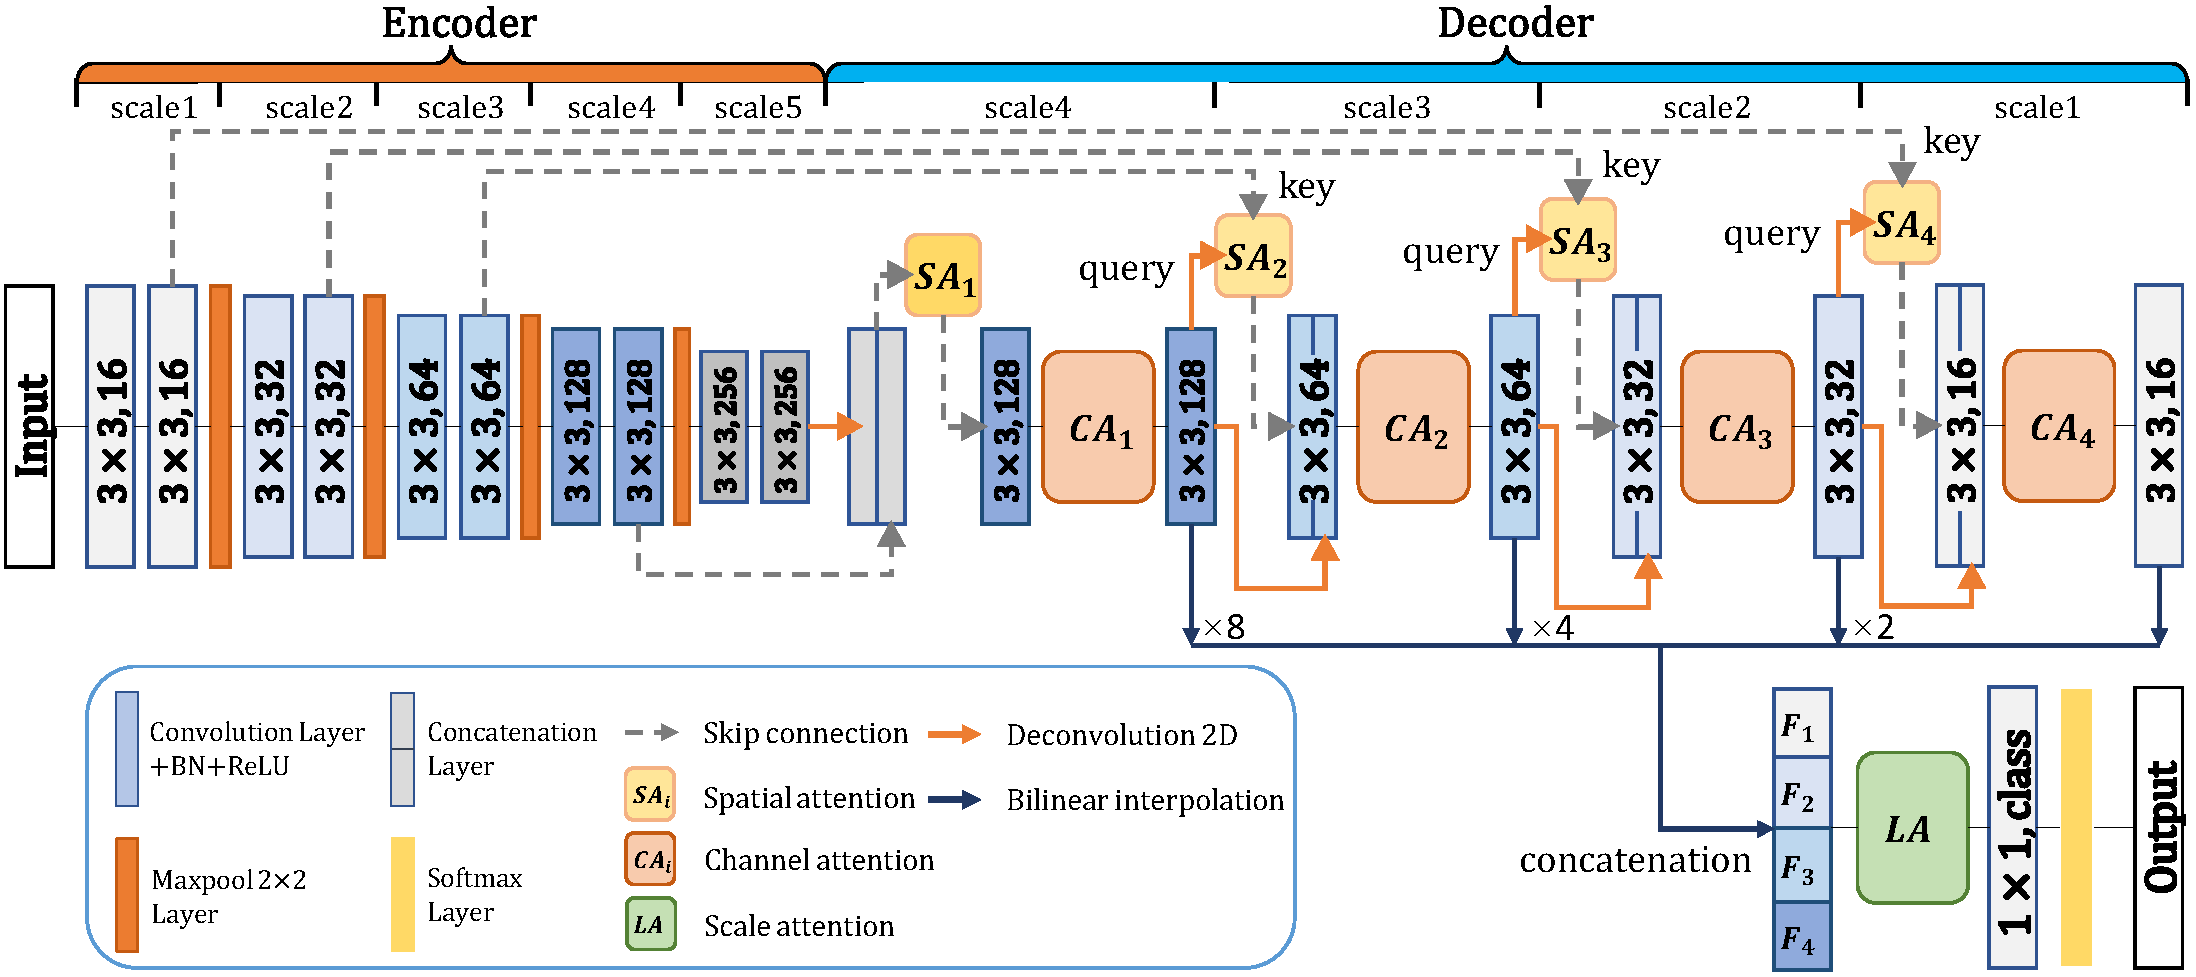
 Fig. 1. Structure of CA-Net.
 Fig. 2. Skin lesion segmentation.

Fig. 3. Placenta and fetal brain segmentation.
Some important required packages include:
Follow official guidance to install Pytorch.
python isic_preprocess.py
python create_folder.py
python main.py --data ISIC2018 --val_folder folder1 --id Comp_Atten_Unet
python validation.py --data ISIC2018 --val_folder folder0 --id Comp_Atten_Unet
Our experimental results are shown in the table:

python show_fused_heatmap.py
Visualzation of spatial attention weight map:

Visualzation of scale attention weight map:

If you find our work is helpful for your research, please consider to cite:
@article{gu2020net,
  title={CA-Net: Comprehensive Attention Convolutional Neural Networks for Explainable Medical Image Segmentation},
  author={Gu, Ran and Wang, Guotai and Song, Tao and Huang, Rui and Aertsen, Michael and Deprest, Jan and Ourselin, S{\'e}bastien and Vercauteren, Tom and Zhang, Shaoting},
  journal={IEEE Transactions on Medical Imaging},
  year={2020},
  publisher={IEEE}
}
Part of the code is revised from Attention-Gate-Networks.
HiLab-git/CA-Net is a public repo on GitHub by HiLab-git. Code for Comprehensive Attention Convolutional Neural Networks for Explainable Medical Image Segmentation.
It declares no license on GitHub. Public does not mean open source: without a license, nobody is granted the right to reuse it.
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
Its last change on GitHub was on 2021-01-20. Take My Repo does not judge from that whether it is maintained.
Nobody has reviewed it on Take My Repo yet, which says nothing about its quality.
Implement a ChatGPT-like LLM in PyTorch from scratch, step by step
Implementation of Vision Transformer, a simple way to achieve SOTA in vision classification with only a single transformer encoder, in Pytorch
RWKV (pronounced RwaKuv) is an RNN with great LLM performance, which can also be directly trained like a GPT transformer (parallelizable). We are at RWKV-7 "Goose". So it's combining the best of RNN and transformer - great performance, linear time, constant space (no kv-cache), fast training, infinite ctx_len, and free sentence embedding.
all kinds of text classification models and more with deep learning
A concise but complete full-attention transformer with a set of promising experimental features from various papers
Semi Supervised Learning for Medical Image Segmentation, a collection of literature reviews and code implementations.
Scribbles or Points-based weakly-supervised learning for medical image segmentation, a strong baseline, and tutorial for research and application.
[MedIA2022]WORD: A large scale dataset, benchmark and clinical applicable study for abdominal organ segmentation from CT image
matlab and python wrap of crf and dense crf, both 2d and 3d are supported