
G2VLM
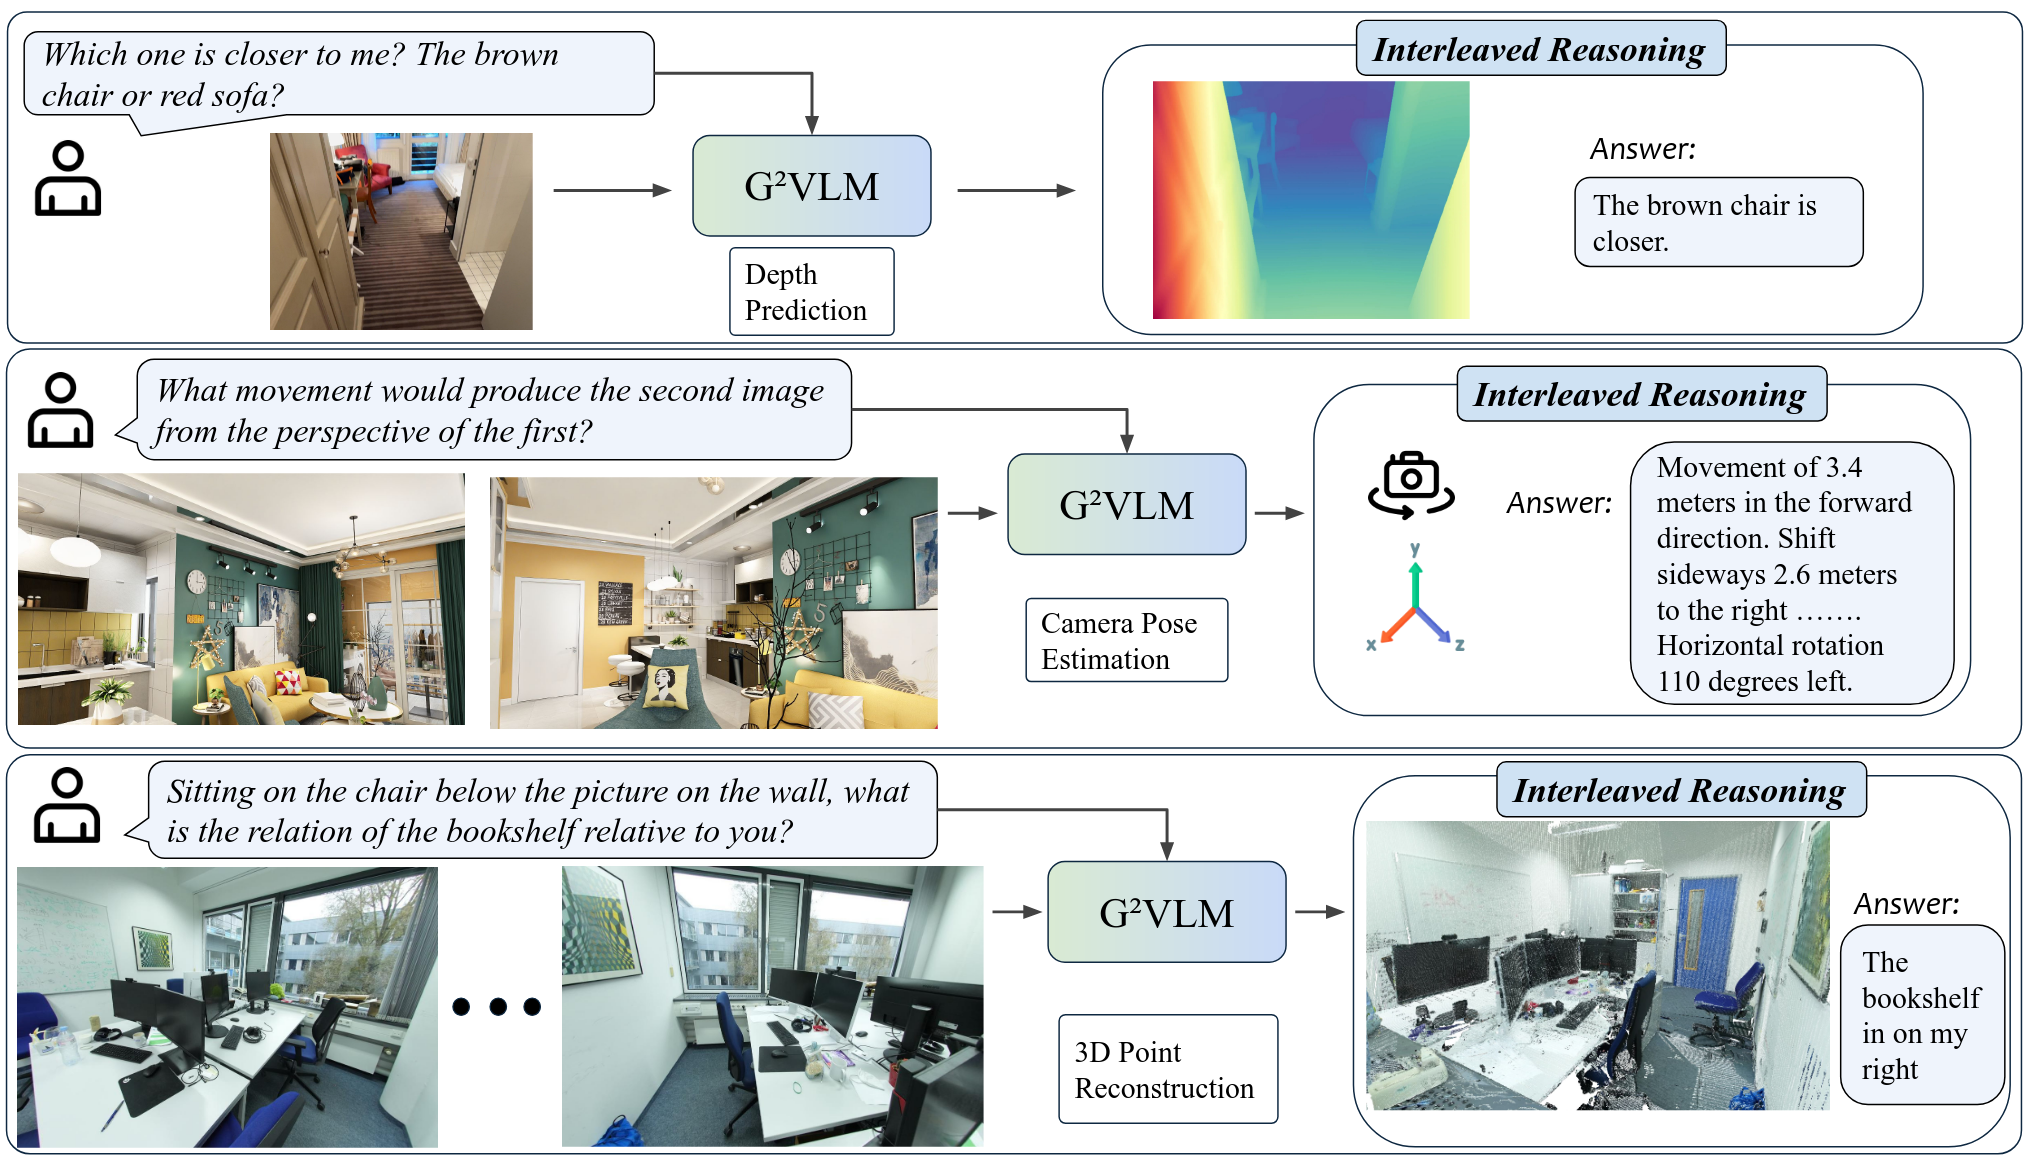
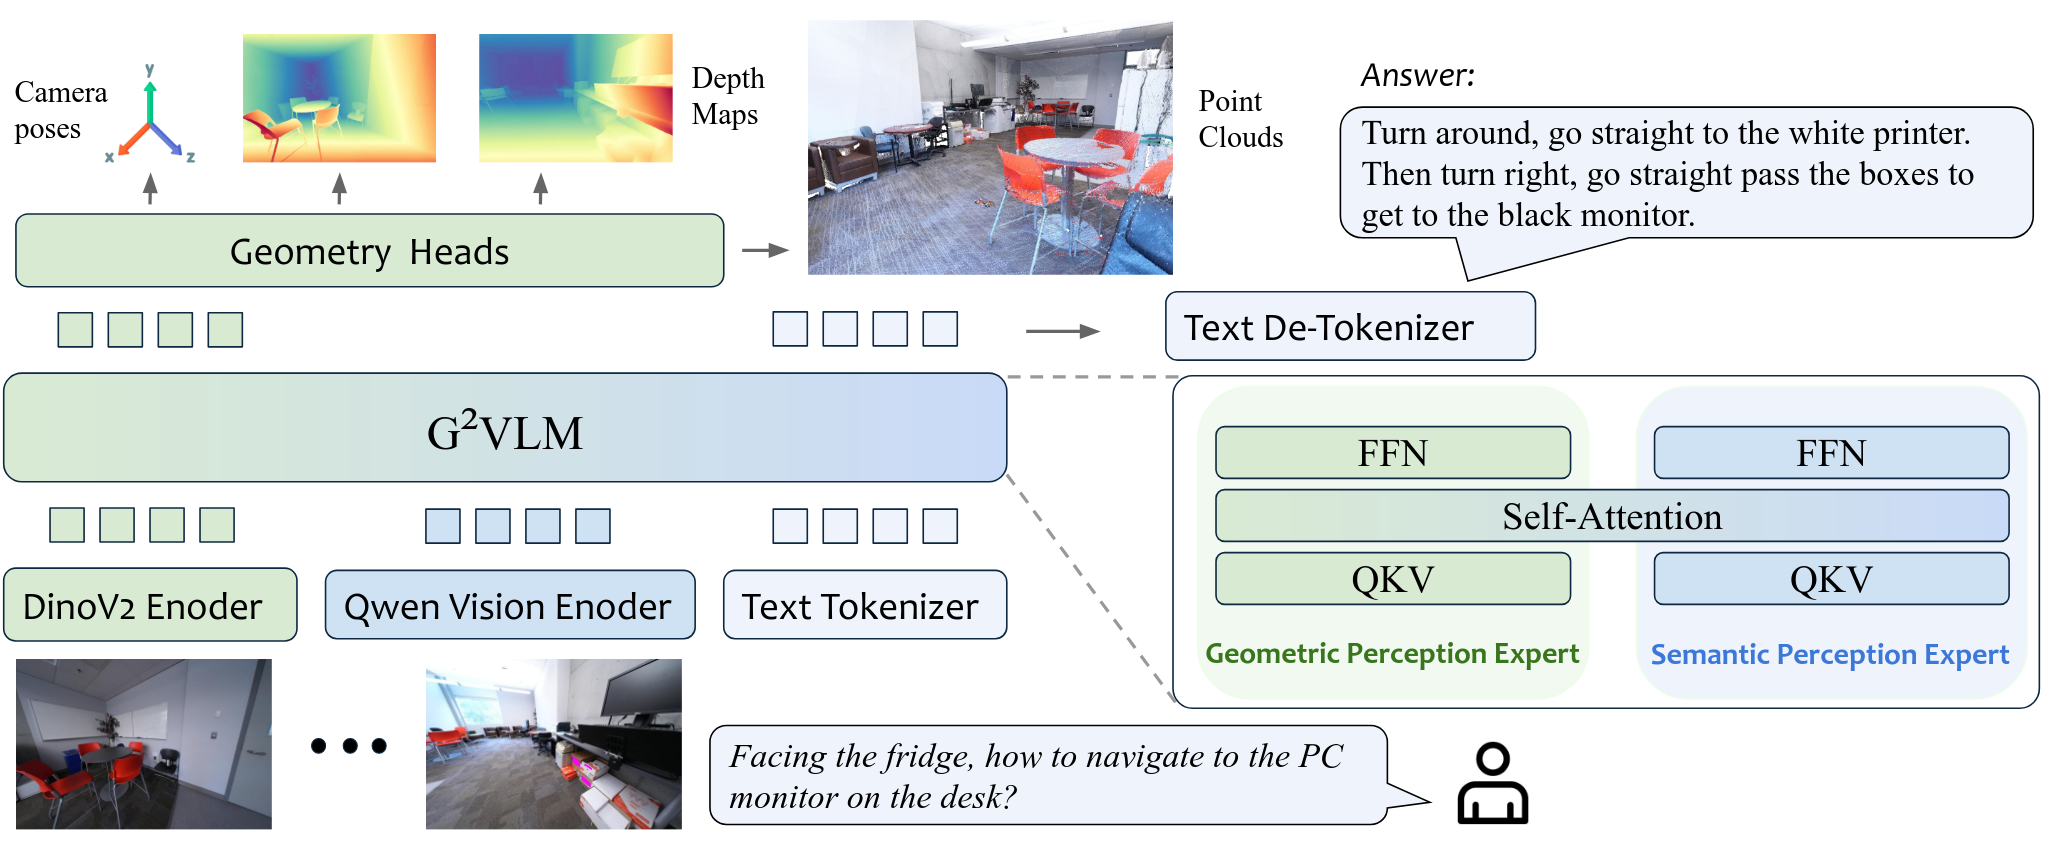
[CVPR 2026] G2VLM: Geometry Grounded Vision Language Model with Unified 3D Reconstruction and Spatial Reasoning
- 364
- Apache-2.0
- 7 mo ago
Repo InternRobotics/G2VLM, read from GitHub 7 h ago. InternRobotics has not joined Take My Repo.
In short
InternRobotics/G2VLM is a public repo on GitHub by InternRobotics. [CVPR 2026] G2VLM: Geometry Grounded Vision Language Model with Unified 3D Reconstruction and Spatial Reasoning. It declares the Apache-2.0 license on GitHub. It is written mainly in Python, has 364 stars and last changed on 2026-04-18. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-21.
AI models this project points to
G2VLM: Geometry Grounded Vision Language Model with Unified 3D Reconstruction and Spatial Reasoning
Wenbo Hu1,2*, Jingli Lin1,3*, Yilin Long1,4*, Yunlong Ran1,5, Lihan Jiang1,6, Yifan Wang1,3, Chenming Zhu1,7, Runsen Xu1,8, Tai Wang1†, Jiangmiao Pang1†
1Shanghai AI Lab, 2UCLA, 3SJTU, 4FDU, 5ZJU, 6USTC, 7HKU, 8CUHK
*Equal Contribution †Corresponding Author
📑 Paper | 📖 arXiv | 🌐 Homepage | 🤗 Model
🏠 About
📢 News
- [2026-04-18] 📝 We release our training code in the train folder. Please refer to our training instructions below.
- [2026-02-20] 🔥 Our work is accepted by CVPR 2026!
- [2026-01-14] We release the evaluation code for 3D reconstruction. Please refer to the eval readme here.
- [Coming!] 📝 We will release the checkpoint of G2VLM-SR, a strong spatial reasoning model. Stay tuned!
- [2025-11-27] 🔥 We release the example training data preprocessing code in the data folder.
- [2025-11-27] 🔥 We release the inference code and the checkpoint of G2VLM.
- [2025-11-27] 🔥 We release the paper of G2VLM.
Model
🚀 Quick Start
1️⃣ Set up environment
git clone https://github.com/InternRobotics/G2VLM
cd G2VLM
conda create -n g2vlm python=3.10 -y
conda activate g2vlm

pip install torch==2.5.1 torchvision==0.20.1 torchaudio==2.5.1 --index-url https://download.pytorch.org/whl/cu121
pip install -r requirements.txt
Optional: For training
pip install https://github.com/Dao-AILab/flash-attention/releases/download/v2.7.4.post1/flash_attn-2.7.4.post1+cu12torch2.5cxx11abiFALSE-cp310-cp310-linux_x86_64.whl
2️⃣ Download pretrained checkpoint
from huggingface_hub import snapshot_download

save_dir = "models/G2VLM-2B-MoT"
repo_id = "InternRobotics/G2VLM-2B-MoT"
cache_dir = save_dir + "/cache"

snapshot_download(cache_dir=cache_dir,
  local_dir=save_dir,
  repo_id=repo_id,
  local_dir_use_symlinks=False,
  resume_download=True,
  allow_patterns=["*.json", "*.safetensors", "*.bin", "*.py", "*.md", "*.txt"],
)
3️⃣ Run Inference from Command Line
Try our example inference script. Here is the script for 3D recontruction.
# Run with default example images
python inference_recon.py

# Run on your own data (image folder)
python inference_recon.py --image_folder <path/to/your/images_dir>
Here is the script for spatial reasoning task. We encourage to try spatial reasoning with G2VLM-SR which will be released soon!
# Run with default example images and default question
python inference_chat.py

# Run on your own data (image folder) and question
python inference_chat.py --image_path <path/to/your/images> --question "user question"
Optional Arguments:
--model_path: Path to a custom model checkpoint file.--image_folder: Path to the input image directory. (Default:examples/dl3dv)--image_path: Path to the image, if you want to specify the image. (Default:examples/25_0.jpg)--question: Input question. (Default:If the table (red point) is positioned at 2.6 meters, estimate the depth of the clothes (blue point).)--save_path: Path to save the output.plypoint cloud. (Default:examples/result.ply)
🔥 Training
We provide pre-train and joint-train scripts in scripts folder
# For pre-train of visual geometry expert only
bash scripts/pretrain.sh

# For joint-train of semantic perception expert and optionally (freeze or train) visual geometry expert
bash scripts/joint_train.sh
For finetuning or joint training, please edit the config file here data/configs/joint_train.yaml. The actual data config is in this file data/dataset_info.py where you can edit the path to your dataset.
🔗 Citation
If you find our work and this codebase helpful, please consider starring this repo 🌟 and cite:
@article{hu2025g2vlmgeometrygroundedvision,
      title={G$^2$VLM: Geometry Grounded Vision Language Model with Unified 3D Reconstruction and Spatial Reasoning},
      author={Wenbo Hu and Jingli Lin and Yilin Long and Yunlong Ran and Lihan Jiang and Yifan Wang and Chenming Zhu and Runsen Xu and Tai Wang and Jiangmiao Pang},
      year={2025},
      journal={arXiv preprint arXiv:2511.21688},
      url={https://arxiv.org/abs/2511.21688},
}
📄 License
G2VLM is licensed under the Apache 2.0.
👏 Acknowledgements
Questions
What is G2VLM?
InternRobotics/G2VLM is a public repo on GitHub by InternRobotics. [CVPR 2026] G2VLM: Geometry Grounded Vision Language Model with Unified 3D Reconstruction and Spatial Reasoning.
Is G2VLM open source?
It declares the Apache-2.0 license on GitHub.
Does G2VLM run on macOS, Windows or Linux?
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
How do I install G2VLM?
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
Is G2VLM still maintained?
Its last change on GitHub was on 2026-04-18. Take My Repo does not judge from that whether it is maintained.
What do people who ran G2VLM say?
Nobody has reviewed it on Take My Repo yet, which says nothing about its quality.