MemOS
Self-evolving memory OS for LLM & AI Agents: ultra-persistent memory, hybrid-retrieval, and cross-task skill reuse, with 35.24% token savings and DeepSeek Harness support.
- 12k
- TypeScript
- Apache-2.0
- 3 h ago
PHASE-Tree: Modeling Character-State Evolution in Long-Horizon Role-Playing Dialogue
Repo MemTensor/PHASE-Tree, read from GitHub 1 min ago. MemTensor has not joined Take My Repo.
MemTensor/PHASE-Tree is a public repo on GitHub by MemTensor. PHASE-Tree: Modeling Character-State Evolution in Long-Horizon Role-Playing Dialogue. It declares the MIT license on GitHub. It is written mainly in Python, has 7 stars and last changed on 2026-08-15. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-20.
English | 中文
A psychology-grounded, multi-timescale character-state representation that lets role-playing models speak from the character's current narrative state, not a frozen profile.

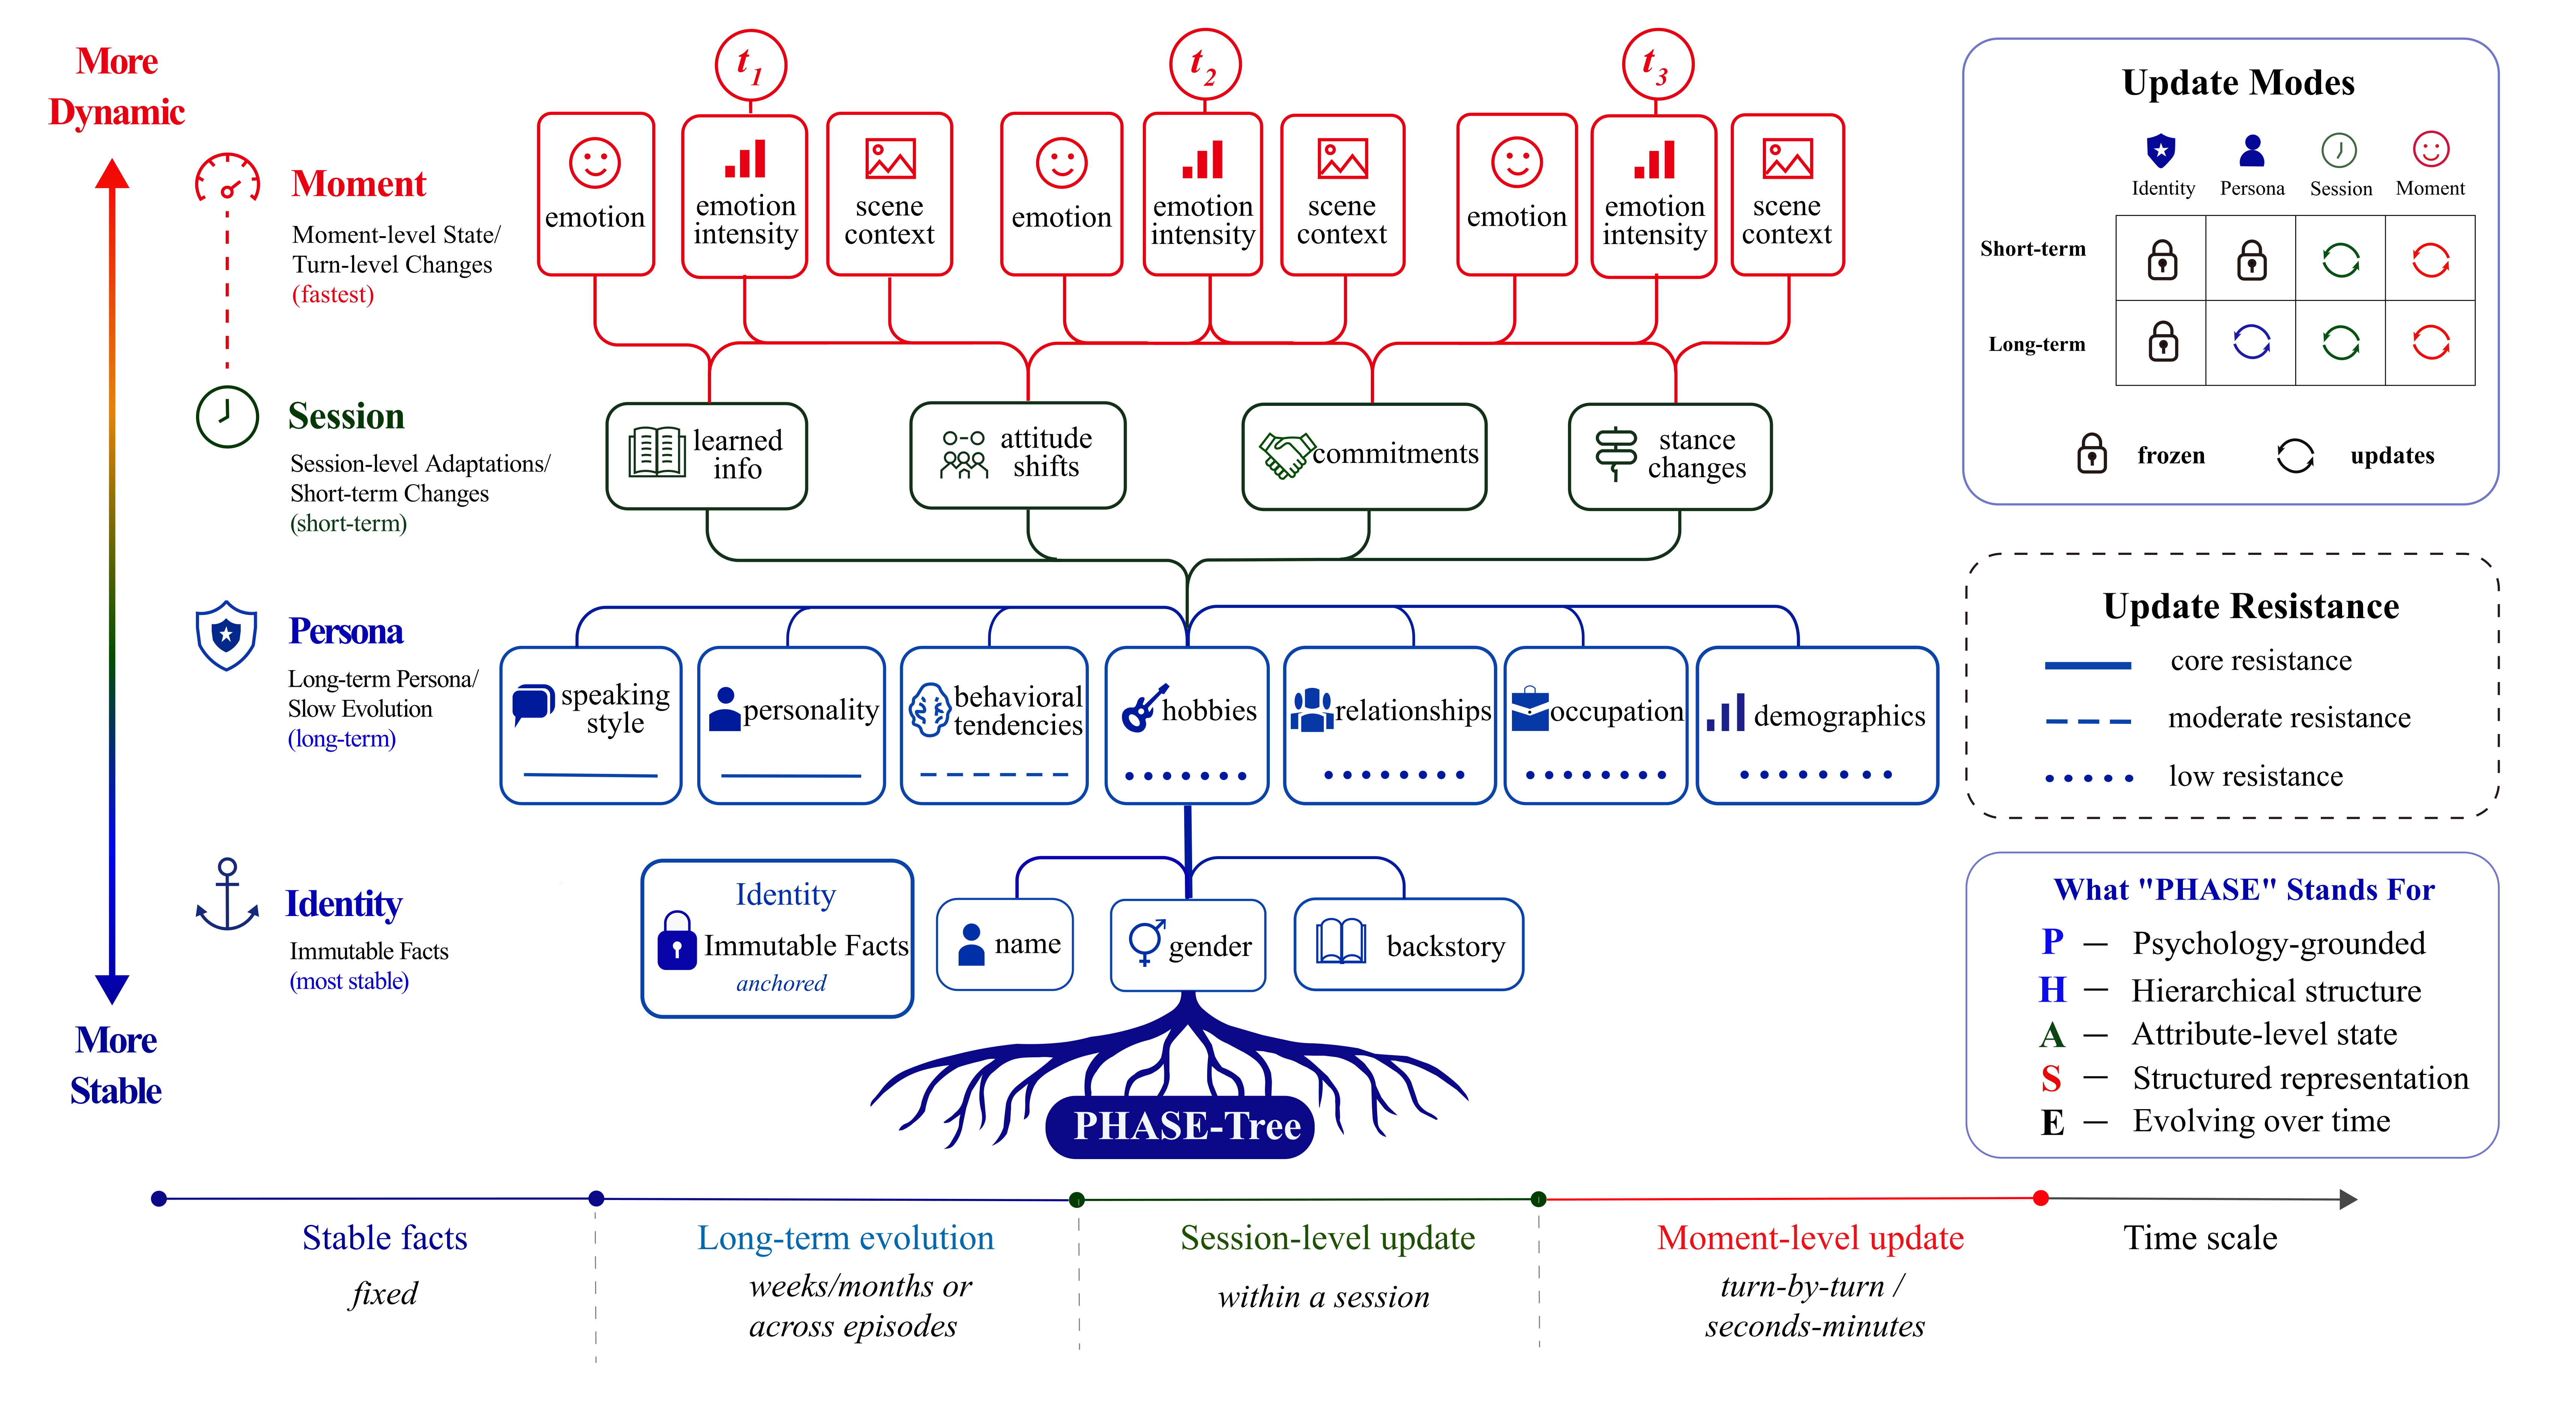
Figure 1. PHASE-Tree decomposes a character into an immutable identity root and three mutable strata at distinct time-scales — long-term persona, session-level session, and turn-level moment — each editable at the field level under resistance, evidence, and cooldown gates.
Long-horizon role-playing demands that characters remain recognizable as they evolve with the narrative. Yet existing work falls short on two fronts: representations are typically static profiles that cannot be updated locally without destabilizing unchanged traits, and benchmarks mainly test persona preservation and memory recall rather than whether a model speaks from a character's currently evolved state — a failure mode we call stale-state failure. We address both. PHASE-Tree is a multi-timescale character-state tree with an immutable identity root and mutable
persona,session, andmomentlayers, making each mutable field an addressable target for localized within- and cross-episode updates. It conditions generation through explicit textual provision or implicit parametric adaptation. To measure evolved-state generation, we introduce LongEvoRoleBench, which pairs four long-dialogue corpora for cross-episode evolution with four short-dialogue corpora as within-scene state-tracking checks, under a unified next-utterance protocol. On the long-dialogue core, textual PHASE-Tree ranks first in 11 of 12 dataset–metric cells against internal variants and all 12 cells against external textual baselines, improving character-level, semantic, and embedding scores by 19.7%, 12.4%, and 15.1% respectively. In a blinded 200-response study, human ratings correlate with the GPT-4.1 judge (Pearson r = 0.65); on descriptive n = 10 PT and NR prompt subsets, the Overall difference is +0.20. The long-dialogue Sem advantage persists across LLM judges and generation backbones.
PHASE-Tree (Psychology-grounded Hierarchical Attribute-Structured Evolving Tree) is a three-part contribution:
persona / session / moment). Each schema field is an independently addressable update target, supporting intra-episode tracking and cross-episode evolution under resistance–evidence–cooldown gates.
Figure 2. Two conditioning paradigms for the same flattened PHASE-Tree. Explicit Textual Provision (top, blue): profile lives in the prompt — full state inspectability. Implicit Parametric Adaptation (bottom, red): profile is absorbed into hypernetwork-generated LoRA weights — dialogue-only prompt, zero profile-token overhead.
On LongEvoRoleBench with Qwen2.5-7B-Instruct as the backbone. Throughout the README we write Ours (textual) and Ours (parametric) to disambiguate the two conditioning paradigms — both refer to PHASE-Tree, distinguished by which baseline block they sit in (paper Table 1 = internal ablation, Table 2 = external comparison with two Ours columns side by side).
| Setting | Result |
|---|---|
| 🏅 Internal ablation (textual) | PHASE-Tree achieves the best score in 21 of 24 dataset–metric cells overall, and leads 11 of 12 on the long-dialogue core. |
| 📈 External baselines (long-dialogue macro, textual block) | Ours (textual) ranks first in all 12 long-dialogue cells, improving over the strongest textual-provision baseline for each metric by +0.49 Char (+19.7%) vs PAG, +0.41 Sem (+12.4%) vs RAG, and +0.04 Emb (+15.1%) vs RAG. |
| 💸 Short-dialogue token efficiency | Ours (textual) uses 471 prompt tokens — 24–55% smaller than RP, RAG, PAG, and CFG — while attaining the highest Sem among them. |
| 🧩 Parametric adaptation | Ours (parametric) leads Sem on both short- and long-dialogue panels (3.748 / 3.434) and ties for first on long-dialogue Emb (0.283) at zero profile-token overhead. |
| 🔬 Effect sizes | Rankings are interpreted through paired Cohen's d rather than p alone (per-cell samples reach ~1.6 × 10⁴). Long-dialogue macro d: PT vs. NR Sem 0.25 / Emb 0.26; PT vs. ST Sem 0.40 / Emb 0.30; Ours vs. MT-LoRA Char 0.72 / Sem 0.29 / Emb 0.19 (borderline). |
| Block | Method | Char ↑ | Sem ↑ | Emb ↑ |
|---|---|---|---|---|
| — | Base (no profile) | 2.326 | 3.323 | 0.268 |
| Textual Provision | RAG | 2.405 | 3.289 | 0.273 |
| Textual Provision | PAG | 2.510 | 2.889 | 0.255 |
| Textual Provision | CFG | 2.389 | 2.429 | 0.225 |
| Textual Provision | Ours (textual) | 3.004 | 3.697 | 0.314 |
| Parametric Adaptation | MT-LoRA | 2.269 | 3.428 | 0.283 |
| Parametric Adaptation | Activation Steering | 2.381 | 2.350 | 0.249 |
| Parametric Adaptation | OPPU | 2.376 | 3.141 | 0.283 |
| Parametric Adaptation | P2P | 2.396 | 3.410 | 0.276 |
| Parametric Adaptation | Ours (parametric) | 2.306 | 3.434 | 0.283 |
Bold cells mark the best method within each paradigm block. See § Reproducing the Paper for the full per-dataset tables.

Figure 3. Prompt-token cost (leftmost panel, shorter bar = cheaper) paired with Char / Sem / Emb scores. On short dialogues, Ours (textual) is the cheapest profile-augmented method and still leads on Sem; on long dialogues the prompt grows to accommodate accumulated evolution history but yields the best Sem and Emb of any method in our comparison. All parametric-adaptation methods collapse to context-only cost.
PHASE-Tree/
├── preprocessing/         # Per-corpus profile extraction + dialogue conversion
├── src/
│   ├── tree_pipeline/     # Build raw → static → dynamic → PHASE-Tree profiles
│   ├── hyper_llm_modulator/  # Hyper-LoRA modulator (encoder, mixer, output heads)
│   ├── scripts/           # Hypernetwork training entry-points & launchers
│   └── configs/           # Training YAMLs
├── tasks/                 # Per-split metadata YAMLs (consumed by the SFT trainer)
├── evaluation/            # predict_* + judge.py + report.py + visualize.py
├── figures/               # Paper figures
├── .env                   # Placeholder template — fill in your API keys locally
├── requirements.txt       # Core Python dependencies
├── requirements-flash-attn.txt   # Optional FlashAttention-2 (recommended)
└── LICENSE                # MIT
⚠️ Three large directories are not tracked in this repository and must be fetched from Hugging Face on first use:
LongEvoRoleBench/,phase_tree_models/, and (optionally)results/.
| Type | Repo | Hugging Face | Default local path | Approx. size |
|---|---|---|---|---|
| Dataset | IAAR-Shanghai/LongEvoRoleBench |
🤗 link | LongEvoRoleBench/ |
≈ 9 GB |
| Model | IAAR-Shanghai/phase_tree_models |
🤗 link | phase_tree_models/ |
≈ 1.8 GB |
| Results | Mathematics-Yang/phase_tree_results |
🤗 link | results/ |
≈ 6.5 GB |
One-shot download (run from the repo root):
hf download IAAR-Shanghai/LongEvoRoleBench    --repo-type=dataset --local-dir LongEvoRoleBench
hf download IAAR-Shanghai/phase_tree_models                       --local-dir phase_tree_models
# Optional — only if you want to skip re-running predictions/judging:
hf download Mathematics-Yang/phase_tree_results --repo-type=dataset --local-dir results
You also need the two base models on disk (default expected under models/):
hf download Qwen/Qwen2.5-7B-Instruct  --local-dir models/Qwen2.5-7B-Instruct
hf download Qwen/Qwen3-Embedding-4B   --local-dir models/Qwen3-Embedding-4B
Tested on Python 3.10 + CUDA 12.x (Linux) with a single A100 / H100 for the textual-provision route and a single A100 80 GB for hypernetwork SFT.
git clone https://github.com/MemTensor/PHASE-Tree.git
cd PHASE-Tree

python -m venv .venv && source .venv/bin/activate

# 1) Core stack (torch, transformers, peft, vllm, openai, ...)
pip install -r requirements.txt

# 2) (Optional, recommended) FlashAttention-2 kernels
#    MUST come AFTER requirements.txt and use --no-build-isolation
pip install -r requirements-flash-attn.txt --no-build-isolation
If FlashAttention cannot build on your machine, the codebase falls back to attn_implementation="sdpa" automatically — you lose some throughput but training and inference still work.
PyTorch / CUDA mismatch? Use the official selector to install a wheel that matches your local driver before
requirements.txt.
All API-dependent steps (profile extraction, persona evolution, LLM-as-Judge scoring, embedding similarity) read credentials from a .env at the repo root via python-dotenv. The shipped .env is a placeholder template:
# Option A — fill placeholders in place (do NOT commit your real keys)
$EDITOR .env

# Option B — keep .env as the public template, override locally (recommended)
cp .env .env.local
$EDITOR .env.local         # `.env.local` is git-ignored
The three model groups can point to the same OpenAI-compatible endpoint, or to different ones (e.g. a local vLLM server for embeddings):
| Variable group | Used by |
|---|---|
LLM_* |
preprocessing/*.py, src/tree_pipeline/*.py (profile extraction + persona evolution) |
JUDGE_* |
evaluation/judge.py (LLM-as-Judge Char + Sem scoring) |
EMBED_* |
evaluation/judge.py (response-vs-reference cosine similarity) |
A minimum end-to-end smoke test on one short-dialogue dataset, both routes:
# 0) Fetch data + checkpoint (once)
hf download IAAR-Shanghai/LongEvoRoleBench   --repo-type=dataset --local-dir LongEvoRoleBench
hf download IAAR-Shanghai/phase_tree_models                       --local-dir phase_tree_models

# 1) Textual provision: predict + judge + report on RAIDEN (both splits)
bash evaluation/run_prompt_eval.sh RAIDEN

# 2) Parametric adaptation (hypernetwork → LoRA): predict + judge + report on RAIDEN
bash evaluation/run_phase_tree_eval.sh RAIDEN

# 3) External baseline for context (e.g. RAG)
bash evaluation/run_comparison_eval.sh RAIDEN rag
Each launcher reads LongEvoRoleBench/processed/<DATASET>/<METHOD>/{random_test,ood_test}.json, writes predictions to results/<DATASET>/<paradigm>/main/<METHOD>/<SPLIT>/predictions.jsonl, then chains judge.py → report.py → visualize.py.
PHASE-Tree is a 4-stage pipeline. Each stage is independently runnable; we ship the outputs of stages 1 and 2 (in LongEvoRoleBench/) and the outputs of stage 3 (in phase_tree_models/) so you can start from any point.
preprocessing/ contains one profile extractor + one dialogue converter per source corpus. Outputs land under LongEvoRoleBench/processed/<Dataset>/intermediate/.
# Friends (long-dialogue example): seed initial profiles from Season 1
python preprocessing/extract_profiles_friends.py

# Convert Season 1–10 transcripts into next-utterance samples + temporal split
python preprocessing/preprocess_dialogues_friends.py
Short-dialogue corpora (RAIDEN, CharacterEval, SimsConv, ChatHaruhi) use a personality-clustering split; long-dialogue corpora (Friends, HPD, StarTrek_TNG, TheOffice) use a chronological train / OOD-temporal split.
Six ablation-chain profile variants are produced under LongEvoRoleBench/processed/<Dataset>/:
| Variant | Description | Paper tag |
|---|---|---|
m1_context_only |
No profile — pure dialogue context. | Base |
m2_raw_profile |
Raw extracted profile text. | RP |
m3_naive_rewrite |
LLM-rewritten profile, no structure. | NR |
m4_static_tree |
Flattened PHASE-Tree, identity + persona only. | ST |
m5_dynamic_tree |
Persona-only evolution across episodes (long-dialogue only). | DT |
m6_phase_tree |
Full PHASE-Tree: identity + evolved persona + session + moment. | PT (Ours) |
The long-dialogue evolution orchestrator (pipeline_evolve_full) runs Stage A (evidence accumulation) → Stage B (resistance-gated update) → Stage C (deterministic post-update patches):
# Full run (LLM evolve + all patches)
python -m src.tree_pipeline.pipeline_evolve_full --dataset Friends

# Patches only (skip the slow / expensive LLM evolve step)
python -m src.tree_pipeline.pipeline_evolve_full --dataset Friends --skip_evolve

# Forward args to the inner evolve step (parallelism, single-episode test, ...)
python -m src.tree_pipeline.pipeline_evolve_full --dataset Friends --workers 8 --test_episode S05E10
Individual stages (evolve_persona, decay_stale_romantic, repair_inter_main_reciprocity, align_inverse_pair, forward_fill_continuity, ...) live under src/tree_pipeline/ and are independently runnable; see the docstring at the top of pipeline_evolve_full.py for the canonical order.
The hyper-LoRA modulator is a profile-to-adapter hypernetwork wrapped around Qwen2.5-7B-Instruct. The shipped launcher does a warm-start SFT on all 8 PHASE-Tree training sets:
# Warm-start from the released pretrained hypermod (default INIT_CKPT)
bash src/scripts/train_phase_tree_qwen_7b.sh

# Train from scratch (no warm-start)
INIT_CKPT="" bash src/scripts/train_phase_tree_qwen_7b.sh

# Override hyperparameters
LR=1e-5 EPOCHS=20000 WARMUP=0.1 bash src/scripts/train_phase_tree_qwen_7b.sh
The default config is src/configs/phase_tree_hyper_lora.yaml (lr 5e-6, warmup 0.05, 40 000 steps, hierarchical batch sampler, sqrt-size mixture). Checkpoints land in phase_tree_models/sft/<run>/{hypermod.pt, args.yaml, adapter_config.json} and are loadable by the same checkpoint reader used at inference time.
| Paradigm | Script | What it does |
|---|---|---|
| Textual Provision — Ours (textual) | evaluation/predict_prompt.py |
Serializes the PHASE-Tree into the prompt; vLLM or HF backend. |
| Parametric Adaptation — Ours (parametric) | evaluation/predict_phase_tree.py |
Generates per-character LoRA via the PHASE-Tree SFT hypermod; profile not in prompt. |
| Parametric Adaptation — P2P (baseline) | evaluation/predict_hypernet.py |
Same architecture, but with the raw-profile P2P hypermod. |
| External baselines: RAG / PAG / CFG / Steering / MT-LoRA / OPPU | evaluation/predict_{rag,cfg,steering,mt_lora,oppu}.py (PAG is dispatched through predict_rag.py with --profile_data) |
Reference baselines, three under each paradigm. |
The recommended path is the per-paradigm launcher, which auto-detects short vs long dialogue, distributes tasks across GPUs, and chains predict → judge → report → visualize:
# Textual Provision — ablation chain (m1 + m2 + m3 + m4 + m6 for short; + m5 for long)
bash evaluation/run_prompt_eval.sh <DATASET>

# Parametric Adaptation — PHASE-Tree SFT hypermod, all methods, both splits, multi-GPU
bash evaluation/run_phase_tree_eval.sh                       # all 8 datasets
bash evaluation/run_phase_tree_eval.sh Friends long-term     # single dataset, explicit mode

# Parametric Adaptation — P2P pretrained baseline
bash evaluation/run_hypernet_p2p_eval.sh <DATASET>

# External baselines
bash evaluation/run_comparison_eval.sh <DATASET> rag         # also: pag, cfg, steering, mt_lora, oppu
Once predictions.jsonl exists, evaluation/judge.py writes two scoring files (full resume support):
| File | Range | What it measures |
|---|---|---|
judge_scores.jsonl |
1 – 5 | character_score (profile consistency) + semantic_score (contextual coherence). GPT-4.1 LLM-as-Judge with the rubric in evaluation/persona_rubric.md. |
embedding_scores.jsonl |
[-1,1] | Cosine similarity of text-embedding-3-small embeddings of prediction vs reference. |
Aggregation + figures:
python evaluation/report.py    --results_dir results/RAIDEN/prompt/main --baseline m2_raw_profile --per_character
python evaluation/visualize.py --results_dir results/RAIDEN/prompt/main --format pdf
python evaluation/autoreport.py                                          # cross-dataset roll-up
A reference-side ablation (re-judge with m2_raw_profile persona reference instead of the full PHASE-Tree) is in evaluation/run_ablation.sh.
Eight role-playing corpora standardized into a common next-utterance generation format with paired random and OOD test regimes:
| Dataset | Lang | Pipeline | # Main characters | OOD axis |
|---|---|---|---|---|
| CharacterEval | ZH | short-term | 77 | unseen-character cluster |
| ChatHaruhi | EN+ZH | short-term | 31 | unseen-character cluster |
| RAIDEN | ZH | short-term | 30 | unseen-character cluster |
| SimsConv | EN | short-term | 68 | unseen-character cluster |
| Friends | EN | long-term | 6 | later-season temporal holdout |
| HPD (Harry Potter Dialogue) | EN | long-term | 6 | later-book temporal holdout |
| StarTrek_TNG | EN | long-term | 6 | later-season temporal holdout |
| TheOffice | EN | long-term | 6 | later-season temporal holdout |
Each tasks/<name>/metadata.yaml registers a split with the hypernetwork SFT trainer; the same JSONs are consumed directly by the prediction scripts. Generation and scoring both condition on the same time-t character state, so Character Score measures the current state rather than a frozen profile.
To regenerate every number in the paper:
# 0) Make sure data + the recommended SFT checkpoint are on disk
hf download IAAR-Shanghai/LongEvoRoleBench   --repo-type=dataset --local-dir LongEvoRoleBench
hf download IAAR-Shanghai/phase_tree_models                       --local-dir phase_tree_models

# 1) All textual-provision ablations across the 8 corpora
for D in RAIDEN CharacterEval HPD SimsConv ChatHaruhi Friends StarTrek_TNG TheOffice; do
    bash evaluation/run_prompt_eval.sh "$D"
done

# 2) All parametric-adaptation ablations
bash evaluation/run_phase_tree_eval.sh        # PHASE-Tree SFT hypermod — Ours (parametric)
bash evaluation/run_hypernet_p2p_eval.sh      # P2P baseline

# 3) External baselines (RAG, PAG, CFG, Steering, MT-LoRA, OPPU)
for D in RAIDEN CharacterEval HPD SimsConv ChatHaruhi Friends StarTrek_TNG TheOffice; do
    for M in rag pag cfg steering mt_lora oppu; do
        bash evaluation/run_comparison_eval.sh "$D" "$M"
    done
done

# 4) Roll everything up into the paper-style summary tables
bash evaluation/run_autoreport.sh
Token-pareto figures (Fig. 3 in the paper) are produced by evaluation/make_token_figures.py once summary.json files exist under each results/<DATASET>/<paradigm>/main/.
If you only want to inspect the numbers we report, download the precomputed results bundle instead:
hf download Mathematics-Yang/phase_tree_results --repo-type=dataset --local-dir results
bash evaluation/run_autoreport.sh
Appendix-level robustness checks. Each value is the macro-average over the 4 short (RAIDEN, CharacterEval, SimsConv, ChatHaruhi) or 4 long (Friends, The Office, Harry Potter, Star Trek) corpora × {random, OOD}, under the explicit textual-provision comparison — Base / RAG / PAG / CFG / Ours (PHASE-Tree). Bold = best in row.
Same protocol, swapping the generation backbone (GPT-4.1 judge, fixed 25% subsample). PHASE-Tree's gains are not tied to a single model — it wins every long-dialogue cell from 0.6B to 32B.
Character Score (Char ↑)
| Backbone | Split | Base | RAG | PAG | CFG | Ours |
|---|---|---|---|---|---|---|
| Qwen2.5-7B (primary) | Short | 2.183 | 2.533 | 3.038 | 3.096 | 3.044 |
| Qwen2.5-7B (primary) | Long | 2.327 | 2.400 | 2.505 | 2.400 | 2.999 |
| Qwen3-0.6B | Short | 1.642 | 1.681 | 1.970 | 2.038 | 1.850 |
| Qwen3-0.6B | Long | 1.904 | 1.831 | 1.906 | 1.711 | 2.029 |
| Gemma-4-E4B-it | Short | 1.949 | 2.315 | 3.049 | 3.130 | 3.142 |
| Gemma-4-E4B-it | Long | 2.038 | 2.142 | 2.495 | 2.698 | 3.019 |
| Qwen3-32B | Short | 3.197 | 3.356 | 3.815 | 3.797 | 3.986 |
| Qwen3-32B | Long | 2.930 | 2.976 | 3.208 | 3.101 | 3.685 |
Semantic Score (Sem ↑)
| Backbone | Split | Base | RAG | PAG | CFG | Ours |
|---|---|---|---|---|---|---|
| Qwen2.5-7B (primary) | Short | 3.571 | 3.656 | 3.580 | 3.273 | 3.785 |
| Qwen2.5-7B (primary) | Long | 3.327 | 3.285 | 2.883 | 2.444 | 3.707 |
| Qwen3-0.6B | Short | 2.625 | 2.561 | 2.596 | 2.254 | 2.744 |
| Qwen3-0.6B | Long | 2.861 | 2.511 | 2.481 | 1.917 | 2.924 |
| Gemma-4-E4B-it | Short | 3.402 | 3.525 | 3.416 | 3.075 | 3.619 |
| Gemma-4-E4B-it | Long | 3.256 | 3.270 | 2.911 | 2.774 | 3.715 |
| Qwen3-32B | Short | 3.983 | 4.004 | 3.910 | 3.622 | 4.120 |
| Qwen3-32B | Long | 3.632 | 3.594 | 3.412 | 3.045 | 4.056 |
Re-scoring the same Qwen2.5-7B-Instruct predictions with three LLM-as-Judge backends configured via .env (JUDGE_*). Absolute scales differ across judges (GLM-5.2 and DeepSeek-V4-Flash are stricter than GPT-4.1), but the ranking is stable — Ours leads every long-dialogue cell regardless of judge.
Character Score (Char ↑)
| Judge | Split | Base | RAG | PAG | CFG | Ours |
|---|---|---|---|---|---|---|
| GPT-4.1 (default) | Short | 2.143 | 2.527 | 2.989 | 3.075 | 3.028 |
| GPT-4.1 (default) | Long | 2.326 | 2.405 | 2.510 | 2.389 | 3.004 |
| GLM-5.2 | Short | 2.347 | 2.656 | 3.165 | 3.208 | 3.150 |
| GLM-5.2 | Long | 2.607 | 2.665 | 2.709 | 2.524 | 3.040 |
| DeepSeek-V4-Flash | Short | 2.675 | 2.893 | 3.040 | 2.819 | 3.210 |
| DeepSeek-V4-Flash | Long | 2.911 | 2.924 | 2.645 | 2.278 | 3.391 |
Semantic Score (Sem ↑)
| Judge | Split | Base | RAG | PAG | CFG | Ours |
|---|---|---|---|---|---|---|
| GPT-4.1 (default) | Short | 3.539 | 3.659 | 3.588 | 3.245 | 3.792 |
| GPT-4.1 (default) | Long | 3.323 | 3.289 | 2.889 | 2.429 | 3.697 |
| GLM-5.2 | Short | 2.824 | 2.913 | 2.853 | 2.583 | 3.025 |
| GLM-5.2 | Long | 2.502 | 2.466 | 2.187 | 1.882 | 2.751 |
| DeepSeek-V4-Flash | Short | 2.707 | 2.813 | 2.712 | 2.387 | 2.895 |
| DeepSeek-V4-Flash | Long | 2.611 | 2.583 | 2.238 | 1.892 | 2.917 |
@misc{tang2026phasetree,
  title         = {PHASE-Tree: Modeling Character-State Evolution in Long-Horizon Role-Playing Dialogue},
  author        = {Bo Tang and Jianan Yang and Junyi Zhu and Yiquan Wu and Rui Zhao and Zhengyu Yang and Yang Zhang and Feiyu Xiong and Zhiyu Li and Jiajun Shen},
  year          = {2026},
  eprint        = {2608.06975},
  archivePrefix = {arXiv},
  primaryClass  = {cs.CL},
  url           = {https://arxiv.org/abs/2608.06975},
}
GitHub's Cite this repository button reads CITATION.cff, which resolves to the same entry.
The hyper-LoRA modulator architecture builds on the P2P codebase [Tan et al., 2025]. The eight evaluation corpora are derived from prior public releases — RAIDEN, CharacterEval, SimsConv, ChatHaruhi, HPD, the ConvoKit Friends Corpus, and public episode transcripts for The Office and Star Trek: TNG — and we thank the original authors and maintainers for making these resources available. The generation backbone (Qwen2.5-7B-Instruct) and embedding encoder (Qwen3-Embedding-4B) are from the Qwen team.
MemTensor/PHASE-Tree is a public repo on GitHub by MemTensor. PHASE-Tree: Modeling Character-State Evolution in Long-Horizon Role-Playing Dialogue.
It declares the MIT license on GitHub.
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
Its last change on GitHub was on 2026-08-15. Take My Repo does not judge from that whether it is maintained.
Nobody has reviewed it on Take My Repo yet, which says nothing about its quality.
Self-evolving memory OS for LLM & AI Agents: ultra-persistent memory, hybrid-retrieval, and cross-task skill reuse, with 35.24% token savings and DeepSeek Harness support.
🍙 A personal AI agent & local memory hub for all AI agents, gives every AI one shared, fully controlled memory and persistent context — all AI remember the same you. Now supports Claude Code, Codex, OpenClaw and Hermes Agent etc.
Official MemOS Cloud plugin for OpenClaw. Enables long-term memory for agents by recalling context before execution and saving conversations after each run.
SkillsVote: Lifecycle Governance of Agent Skills from Collection, Recommendation to Evolution
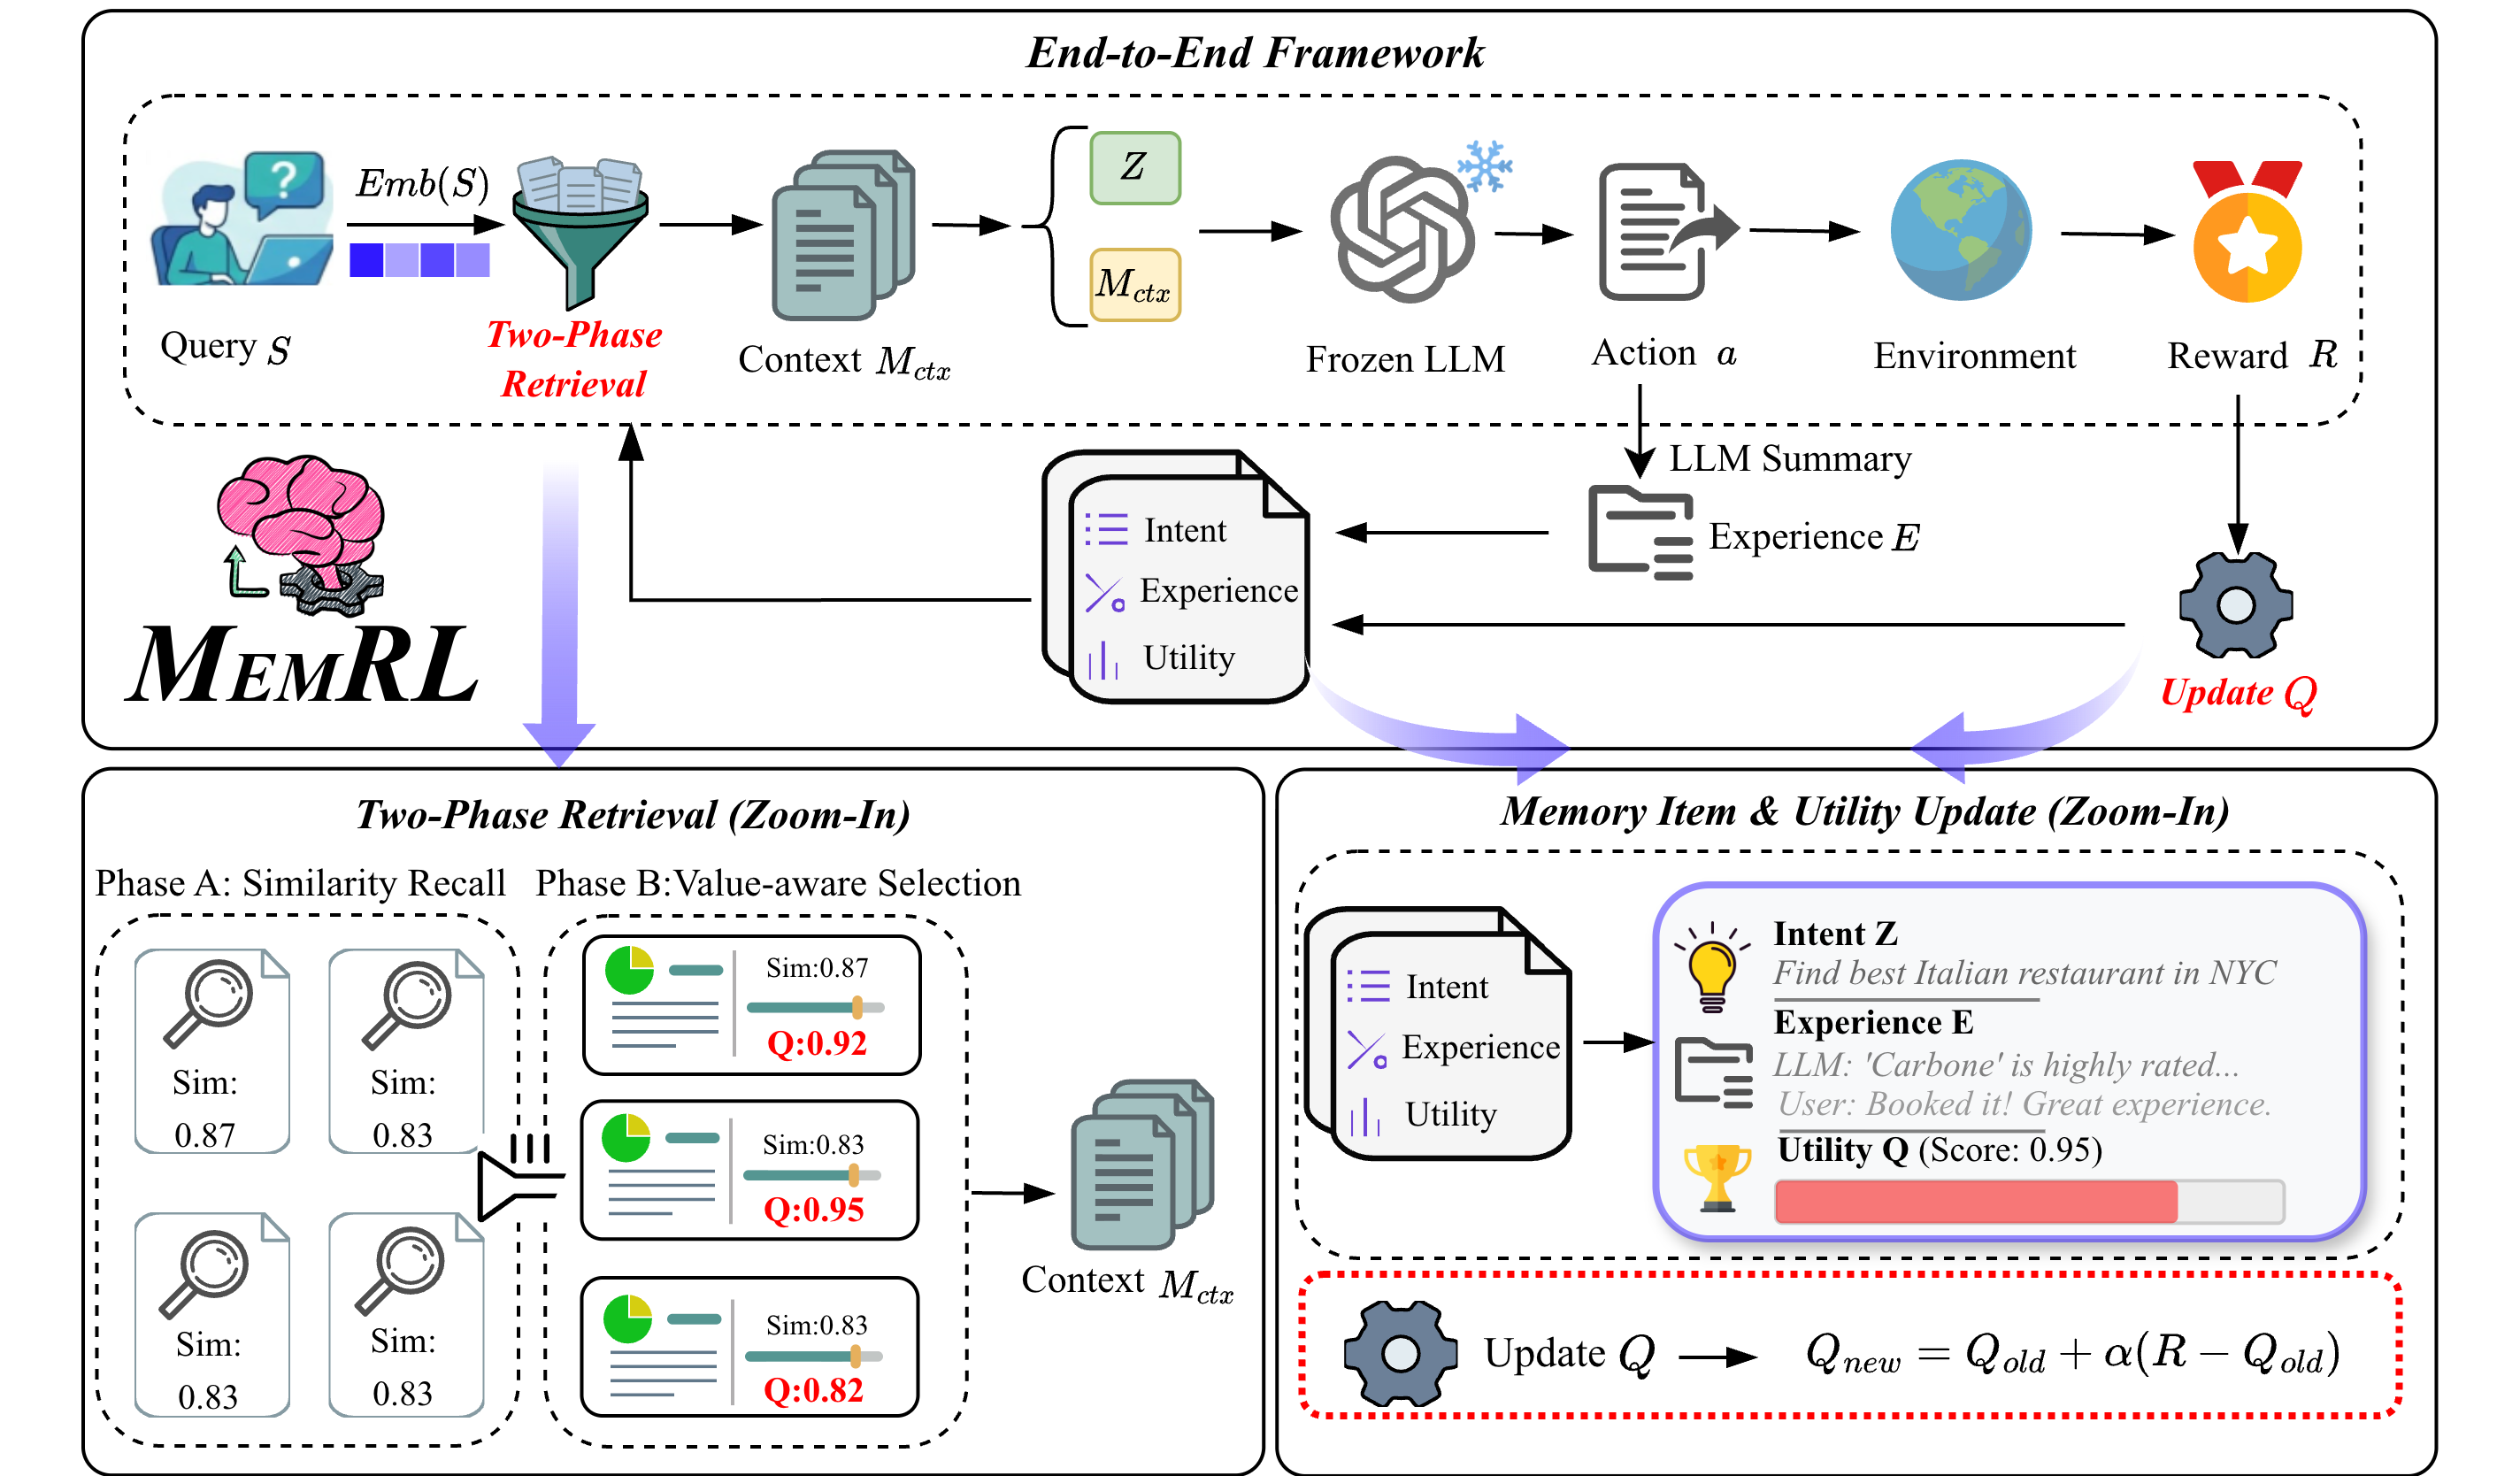
Paper: “MEMRL: SELF-EVOLVING AGENTS VIA RUNTIME REINFORCEMENT LEARNING ON EPISODIC MEMORY” Open-Source Code