transformers
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.
- 169k
- Python
- Apache-2.0
- 6 h ago
A web scraping tool to systematically extract the text of scientific papers and corresponding metadata from university accessible journals.
Repo NLPatVCU/PaperScraper, read from GitHub 17 min ago. NLPatVCU has not joined Take My Repo.
NLPatVCU/PaperScraper is a public repo on GitHub by NLPatVCU. A web scraping tool to systematically extract the text of scientific papers and corresponding metadata from university accessible journals. It declares the GPL-3.0 license on GitHub. It is written mainly in Python, has 232 stars and last changed on 2022-10-14. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-21.
GitHub is limiting requests or did not answer. The facts on this page still come from the last successful read.
Open on GitHubNLPatVCU/PaperScraper is a public repo on GitHub by NLPatVCU. A web scraping tool to systematically extract the text of scientific papers and corresponding metadata from university accessible journals.
It declares the GPL-3.0 license on GitHub.
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
Its last change on GitHub was on 2022-10-14. Take My Repo does not judge from that whether it is maintained.
Nobody has reviewed it on Take My Repo yet, which says nothing about its quality.
🤗 Transformers: the model-definition framework for state-of-the-art machine learning models in text, vision, audio, and multimodal models, for both inference and training.
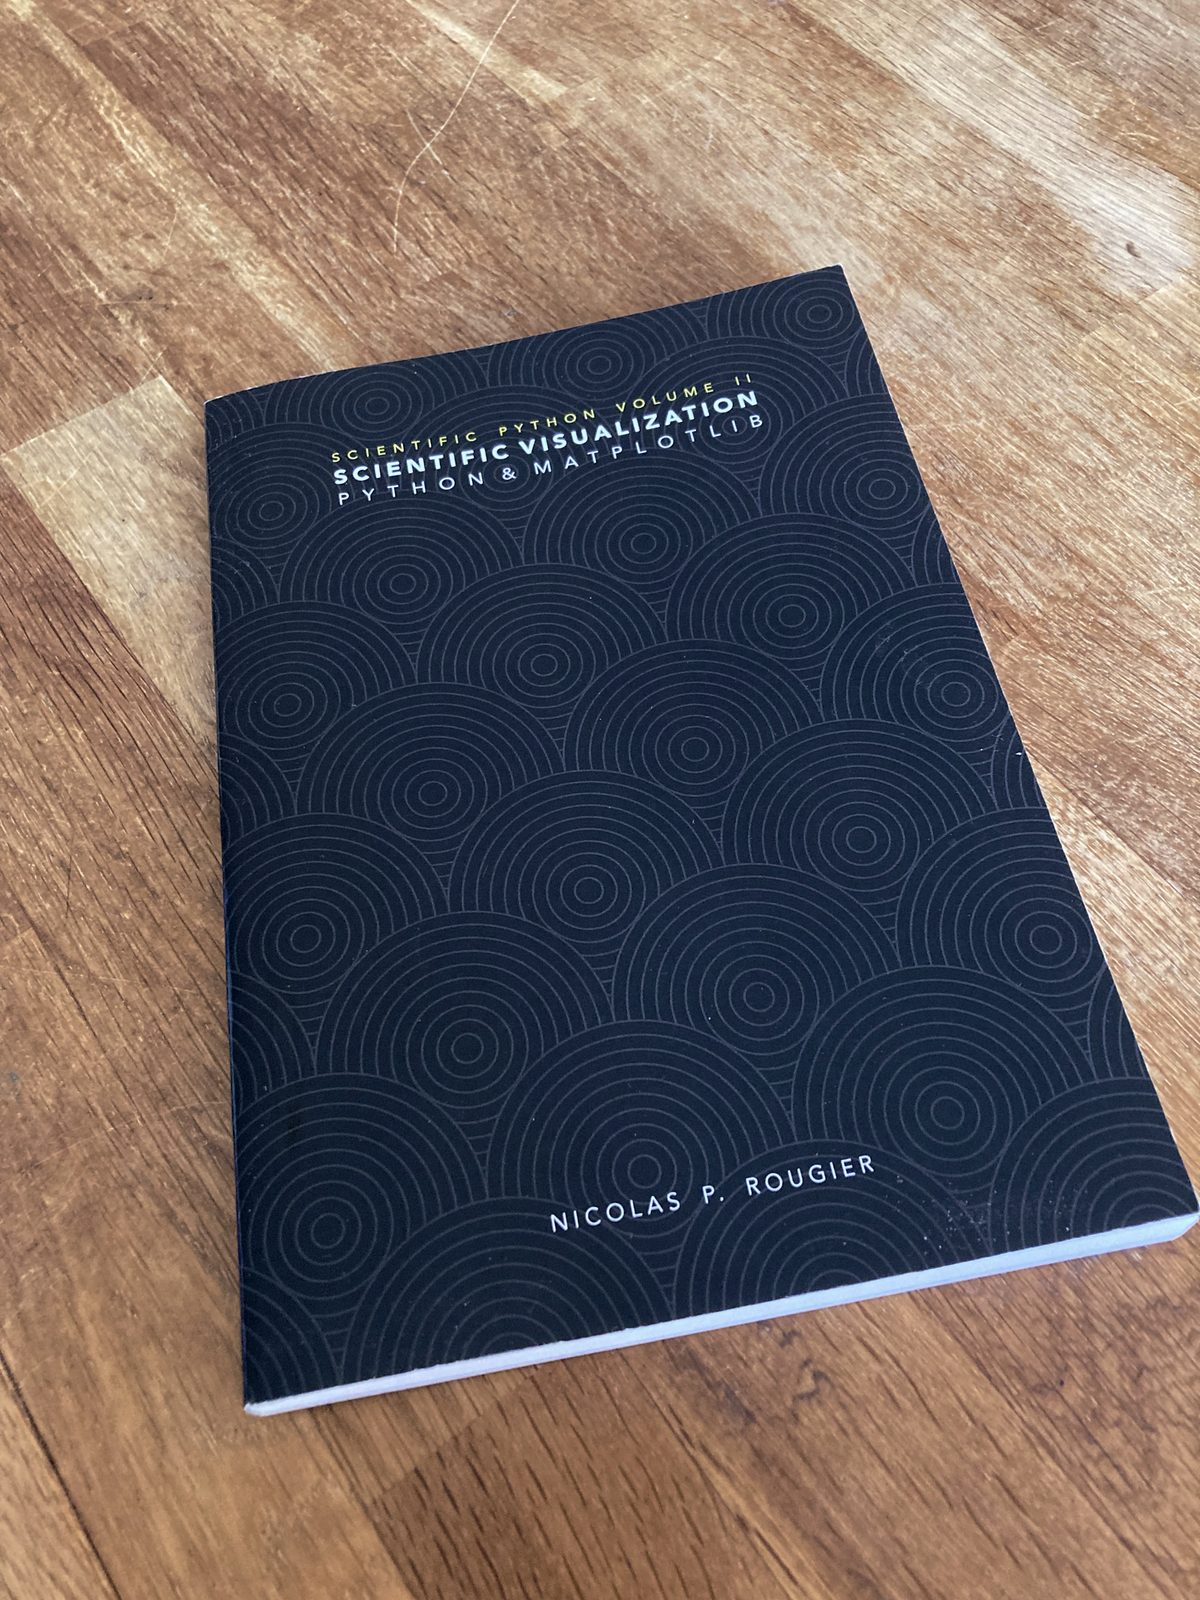
An open access book on scientific visualization using python and matplotlib
Implement a ChatGPT-like LLM in PyTorch from scratch, step by step
🎨 Toolkit for generating publication-quality plots for Cell, Nature and Science journals
A medaCy compatible model for clinical note information extraction.