llm-surgeon
Model Ablation & Quantization
- 0
- 3 wk ago
Repo NetwCodeProjects/llm-surgeon, read from GitHub 26 min ago. NetwCodeProjects has not joined Take My Repo.
In short
NetwCodeProjects/llm-surgeon is a public repo on GitHub by NetwCodeProjects. Model Ablation & Quantization. It declares no license on GitHub. Public does not mean open source: without a license, nobody is granted the right to reuse it. It is written mainly in Python, has 0 stars and last changed on 2026-11-02. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-21.
LLM Surgeon (Abliterate and Quantize)
Abliterates a Hugging Face model with Heretic, qualifies the result, keeps it as an immutable BF16 master and exports FP8 (llm-compressor) and GGUF (llama.cpp), each loaded and compared with the master before it counts. Optionally publishes to Hugging Face. Every artifact has a manifest with checksums and lineage.
Compatibility notice. This platform does not automatically verify that your model architecture is supported by the selected abliteration engine or quantization backend. Verify compatibility with the engines' official documentation before execution. Unsupported models or formats may fail during model loading, transformation, or export. The platform manages execution, dependencies, logs, and artifacts but does not guarantee compatibility with every model.
Requirements
OS:    Ubuntu 22.04/24.04, or a cloud GPU's PyTorch template (e.g. runpod/pytorch)
GPU:   NVIDIA with driver; small models also run on CPU (configs/acceptance/local-cpu.yaml)
Disk:  3–4× the model's BF16 size (the 27B release plans 500 GB)
The tools are installed by the program, pinned, inside the repository and the workspace. A missing host package is reported with its install command.
Profiles
A profile holds the settings one model architecture needs: which tensors FP8 must skip, which GGUF
converter version to use, which tensors to restore after abliteration. configs/pipeline.yaml loads it:
profiles:
  - profiles/qwen3_5.yaml    # Qwen3.5 and Qwen3.8 models
Profiles are per architecture, not per model. Qwen3.8-27B uses qwen3_5.yaml because it'sconfig.json
says "model_type": "qwen3_5". For a model with a different model_type, write a profile in
configs/profiles/ and list it here.
To find which profile a model needs, open its config.json
(https://huggingface.co/<org>/<model>/blob/main/config.json) and read model_type.
Changing the model
In configs/pipeline.yaml, as shipped:
profiles:
  - quantization/default.yaml        # every model; keep
  - profiles/qwen3_5.yaml            # the profile for the model's model_type

model:
  url: Qwen/Qwen3.8-27B              # org/model on Hugging Face
  revision: 1d4bf0f2ff6012fd82039f2fa52739d0dd7c60c0   # a commit of that repository, or null for the latest

evaluation:
  published_baselines: configs/baselines/qwen3.8-27b.yaml   # null unless you have that model's published numbers
Usage
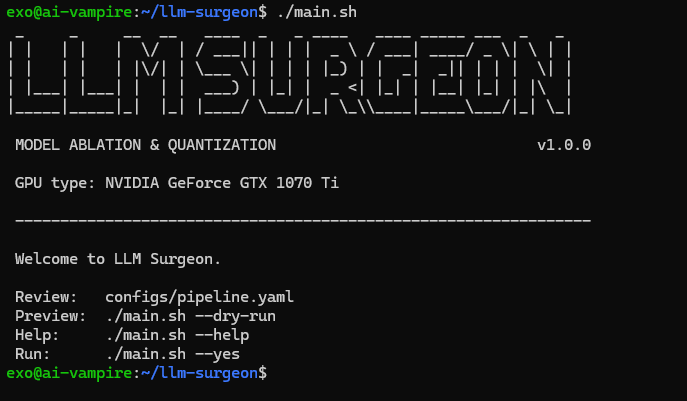
Review:   configs/pipeline.yaml
Preview:  ./main.sh --dry-run
Run:      ./main.sh --yes
Resume:   ./main.sh --resume RUN_ID
Publish:  ./main.sh --publish RUN_ID
Help:     ./main.sh --help
--yes skips confirmation prompts. Publishing follows publish: in the config: the shipped one uploads
public without asking. With enabled: ask, a new run asks first (--yes does not answer it): publish or
not, repository name, private or public, the formats by bit level. Uploads happen only when the run's
release record says ready (release).
Cloud GPU: workspace on the local disk (--output-dir /root/ws), run inside tmux, copy exports/ out
before the instance stops.
Stop early:     ./main.sh --through 2 --yes
Re-run stages:  ./main.sh --resume RUN_ID --from 5 --through 6 --rerun
Change config:  ./main.sh --resume RUN_ID --fork --quantizations fp8
Quantize only:  ./main.sh --model-url org/model --quantize-only --quantizations fp8,q4_k_m --yes
Inspect:        ./main.sh --status RUN_ID · --list-runs · --cleanup
Detail:         --verbose · --quiet
Stages
| ID | Stage | Result |
|---|---|---|
| 00 | preflight | host facts, disk and VRAM checks |
| 01 | environment | pinned tool environments (reused across runs) |
| 02 | acquire | model at a pinned commit, every file verified |
| 03 | published_baselines | the model card's own metrics, recorded with their source |
| 04 | prepare_engine | Heretic configuration, validated against the installed Heretic |
| 05 | abliterate | budgeted, resumable search; the best trial within the gates is exported |
| 06 | qualify | held-out refusal, benign and integrity checks on the candidate |
| 07 | select_master | promotion gates → immutable master |
| 08 | quantize | FP8 and GGUF exports |
| 09 | verify_exports | each export loaded in its runtime (vLLM, llama-server) and compared with the master |
| 10 | report_export | manifests, report, run summary |
Step by step: run walkthrough.
Status
Every stage has run end to end on a B300 (Qwen3.5-2B, native FP8 in vLLM) and an A100; each commit is accepted on CPU first (acceptance). The Qwen3.8-27B release is one B300 run (release). Verified and not verified: limitations.
Outputs
workspace/
├── exports/{bf16,fp8,gguf}/<name>/     deliverables, each with a manifest sidecar
├── runs/<run>/reports/report.md        stages, gates, loader tests, metric provenance, tool versions, time
├── runs/<run>/{logs,receipts,metrics}/ what happened, why, and the measurements
├── manifests/  assessments/            every artifact's manifest and its verification records
├── models/                             verified sources, candidates, the selected master
└── tools/  cache/                      pinned tool environments and caches
Documentation
run walkthrough · cli · configuration · release · troubleshooting · limitations · architecture · stages · study lifecycle · Heretic adapter · quantization · evaluation · assessments · artifact schema · security · Ubuntu · Lambda Stack profile · acceptance · implementation log · specification · contributing
License
The project's own license is not chosen yet. Third-party tools keep theirs (LICENSE-THIRD-PARTY.md); Heretic is AGPL-3.0.
Questions
What is llm-surgeon?
NetwCodeProjects/llm-surgeon is a public repo on GitHub by NetwCodeProjects. Model Ablation & Quantization.
Is llm-surgeon open source?
It declares no license on GitHub. Public does not mean open source: without a license, nobody is granted the right to reuse it.
Does llm-surgeon run on macOS, Windows or Linux?
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
How do I install llm-surgeon?
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
Is llm-surgeon still maintained?
Its last change on GitHub was on 2026-11-02. Take My Repo does not judge from that whether it is maintained.
What do people who ran llm-surgeon say?
Nobody has reviewed it on Take My Repo yet, which says nothing about its quality.