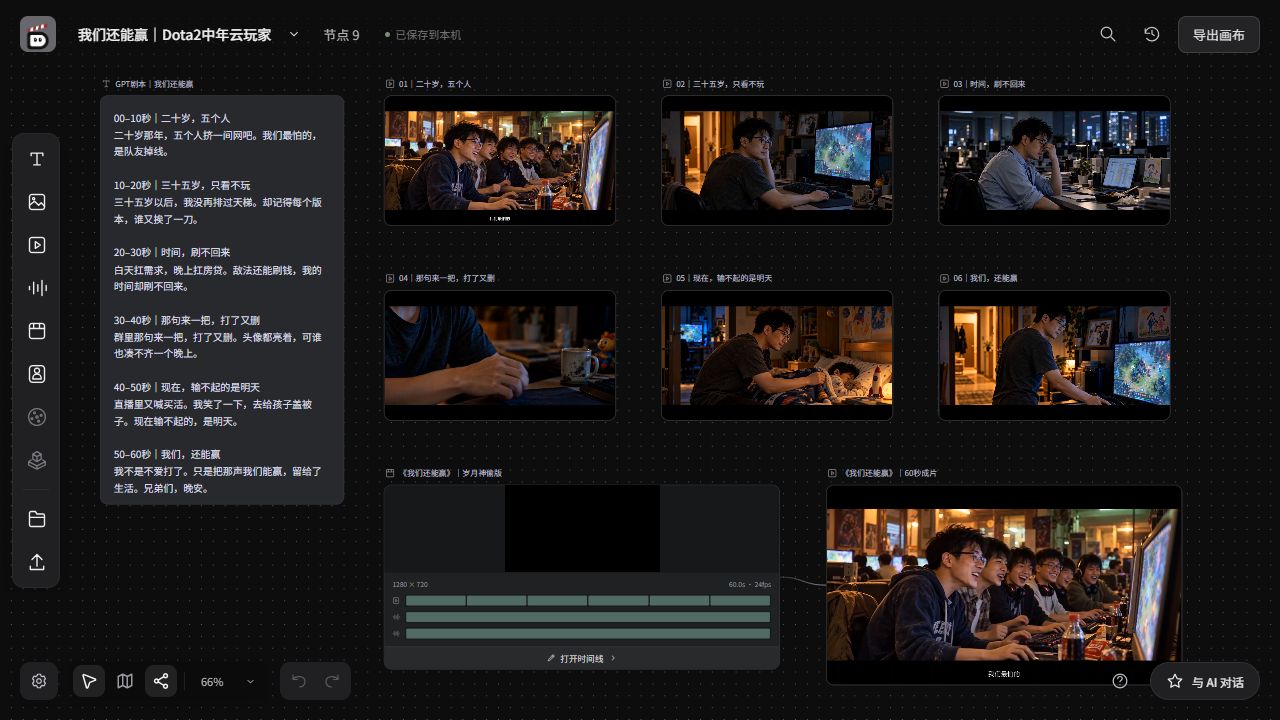
OpenDirector
Build an easy-to-use workflow for the next generation of video creation with agent
- 412
- TypeScript
- Apache-2.0
- 6 h ago
Agent skill for profiling MLX workloads on Apple Silicon — the macOS analog of ncu-style profile → diagnose → report workflows (timing harness, Metal GPU capture, powermetrics)
Repo ThinkFlowLab/mlx-perf, read from GitHub 1 min ago. ThinkFlowLab has not joined Take My Repo.
ThinkFlowLab/mlx-perf is a public repo on GitHub by ThinkFlowLab. Agent skill for profiling MLX workloads on Apple Silicon — the macOS analog of ncu-style profile → diagnose → report workflows (timing harness, Metal GPU capture, powermetrics). It declares the MIT license on GitHub. It is written mainly in Python, has 0 stars and last changed on 2026-10-02. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-19.
ThinkFlowLab/mlx-perf is a public repo on GitHub by ThinkFlowLab. Agent skill for profiling MLX workloads on Apple Silicon — the macOS analog of ncu-style profile → diagnose → report workflows (timing harness, Metal GPU capture, powermetrics).
It declares the MIT license on GitHub.
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
Its last change on GitHub was on 2026-10-02. Take My Repo does not judge from that whether it is maintained.
Nobody has reviewed it on Take My Repo yet, which says nothing about its quality.
Build an easy-to-use workflow for the next generation of video creation with agent
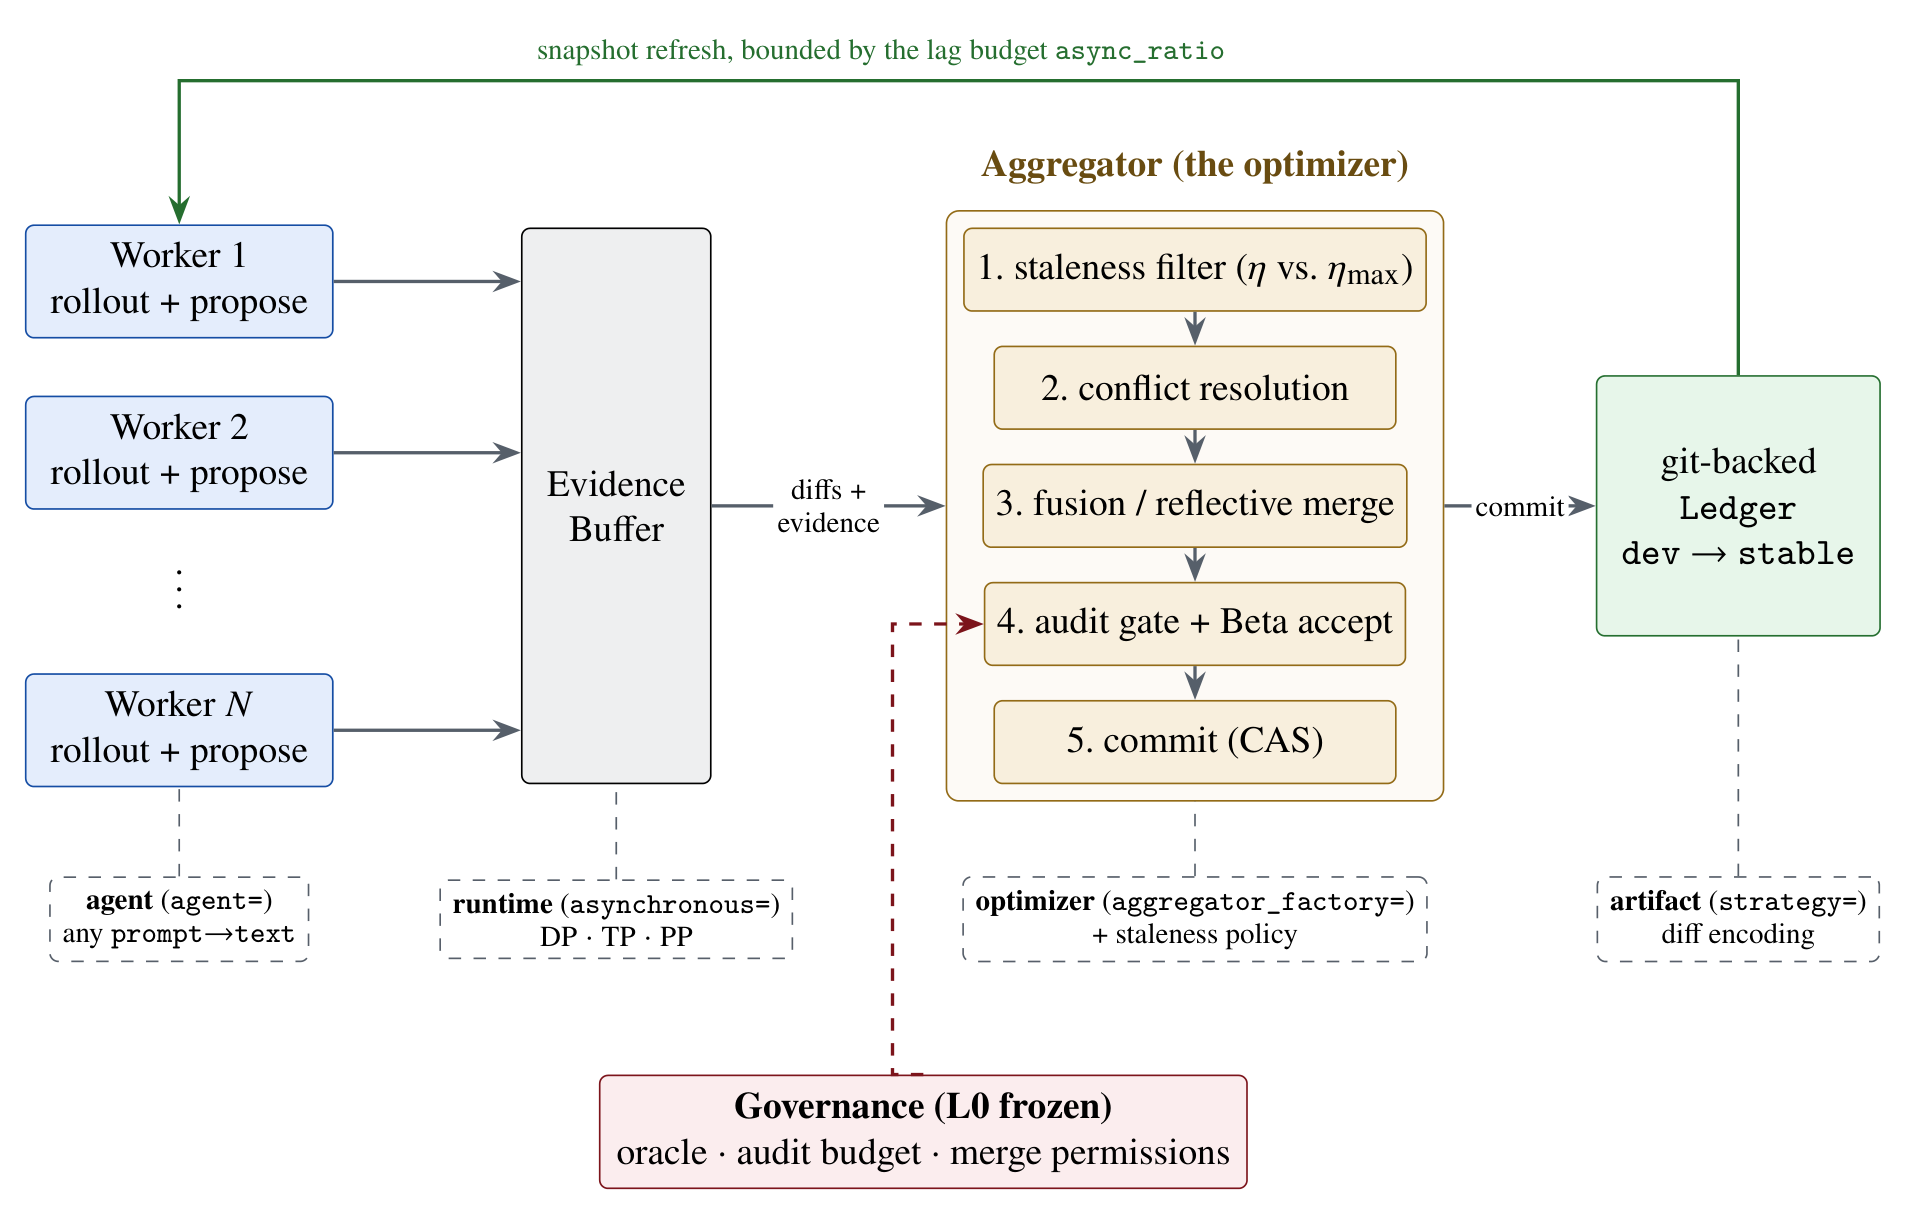
Gradient descent, but the parameters are agents — a parallel, asynchronous framework for self-evolving agents (skills, prompts, harnesses). Diffs are the gradients; the aggregator is the optimizer.
System 1 decision models (Jev, Laya, Cua-S1) as brain for agents: Browser use, computer use, games and robotics
Belle rings when it matters: an AI coworker in your team's chat that stays out of the way, speaks up when it can help, and respects who can see what.
An evaluation framework for AI agents. Bring any benchmark, agent or capability, run it on your machines, and inspect the evidence behind every score.