
my-claude-code-setup
Shared starter template configuration and CLAUDE.md memory bank system for Claude Code
- 2.7k
- Python
- MIT
- 12 d ago
The maintainer has not written a description at the source.
Repo centminmod/code-supernova-evaluation, read from GitHub 1 min ago. centminmod has not joined Take My Repo.
centminmod/code-supernova-evaluation is a public repo on GitHub by centminmod. It declares no license on GitHub. Public does not mean open source: without a license, nobody is granted the right to reuse it. It has 16 stars and last changed on 2025-09-30. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-21.
Updated ranking with Claude Sonnet 4.5 and newer models at https://github.com/centminmod/claude-sonnet-4.5-evaluation
Code-Supernova is new stealth LLM model released for free with Cline and Kilo Code and xAI Grok 4 Fast was also released. I wanted to test them for code analysis for my csfa.sh nftables wrapper script and GitHub workflow action test against other LLM models I use. This is for code analysis and not code generation. Code analysis would be useful for understanding code bases, writing documentation, troubleshooting code and planning.
CSFA (v1.3.1) is a CSF-like wrapper for nftables that provides familiar ConfigServer Security & Firewall commands mapped to modern nftables equivalents. The project uses a single Bash script (
csfa.sh) that manages firewall rules through a dedicated inet table called "csfa".
I have paid subscriptions and accounts with:
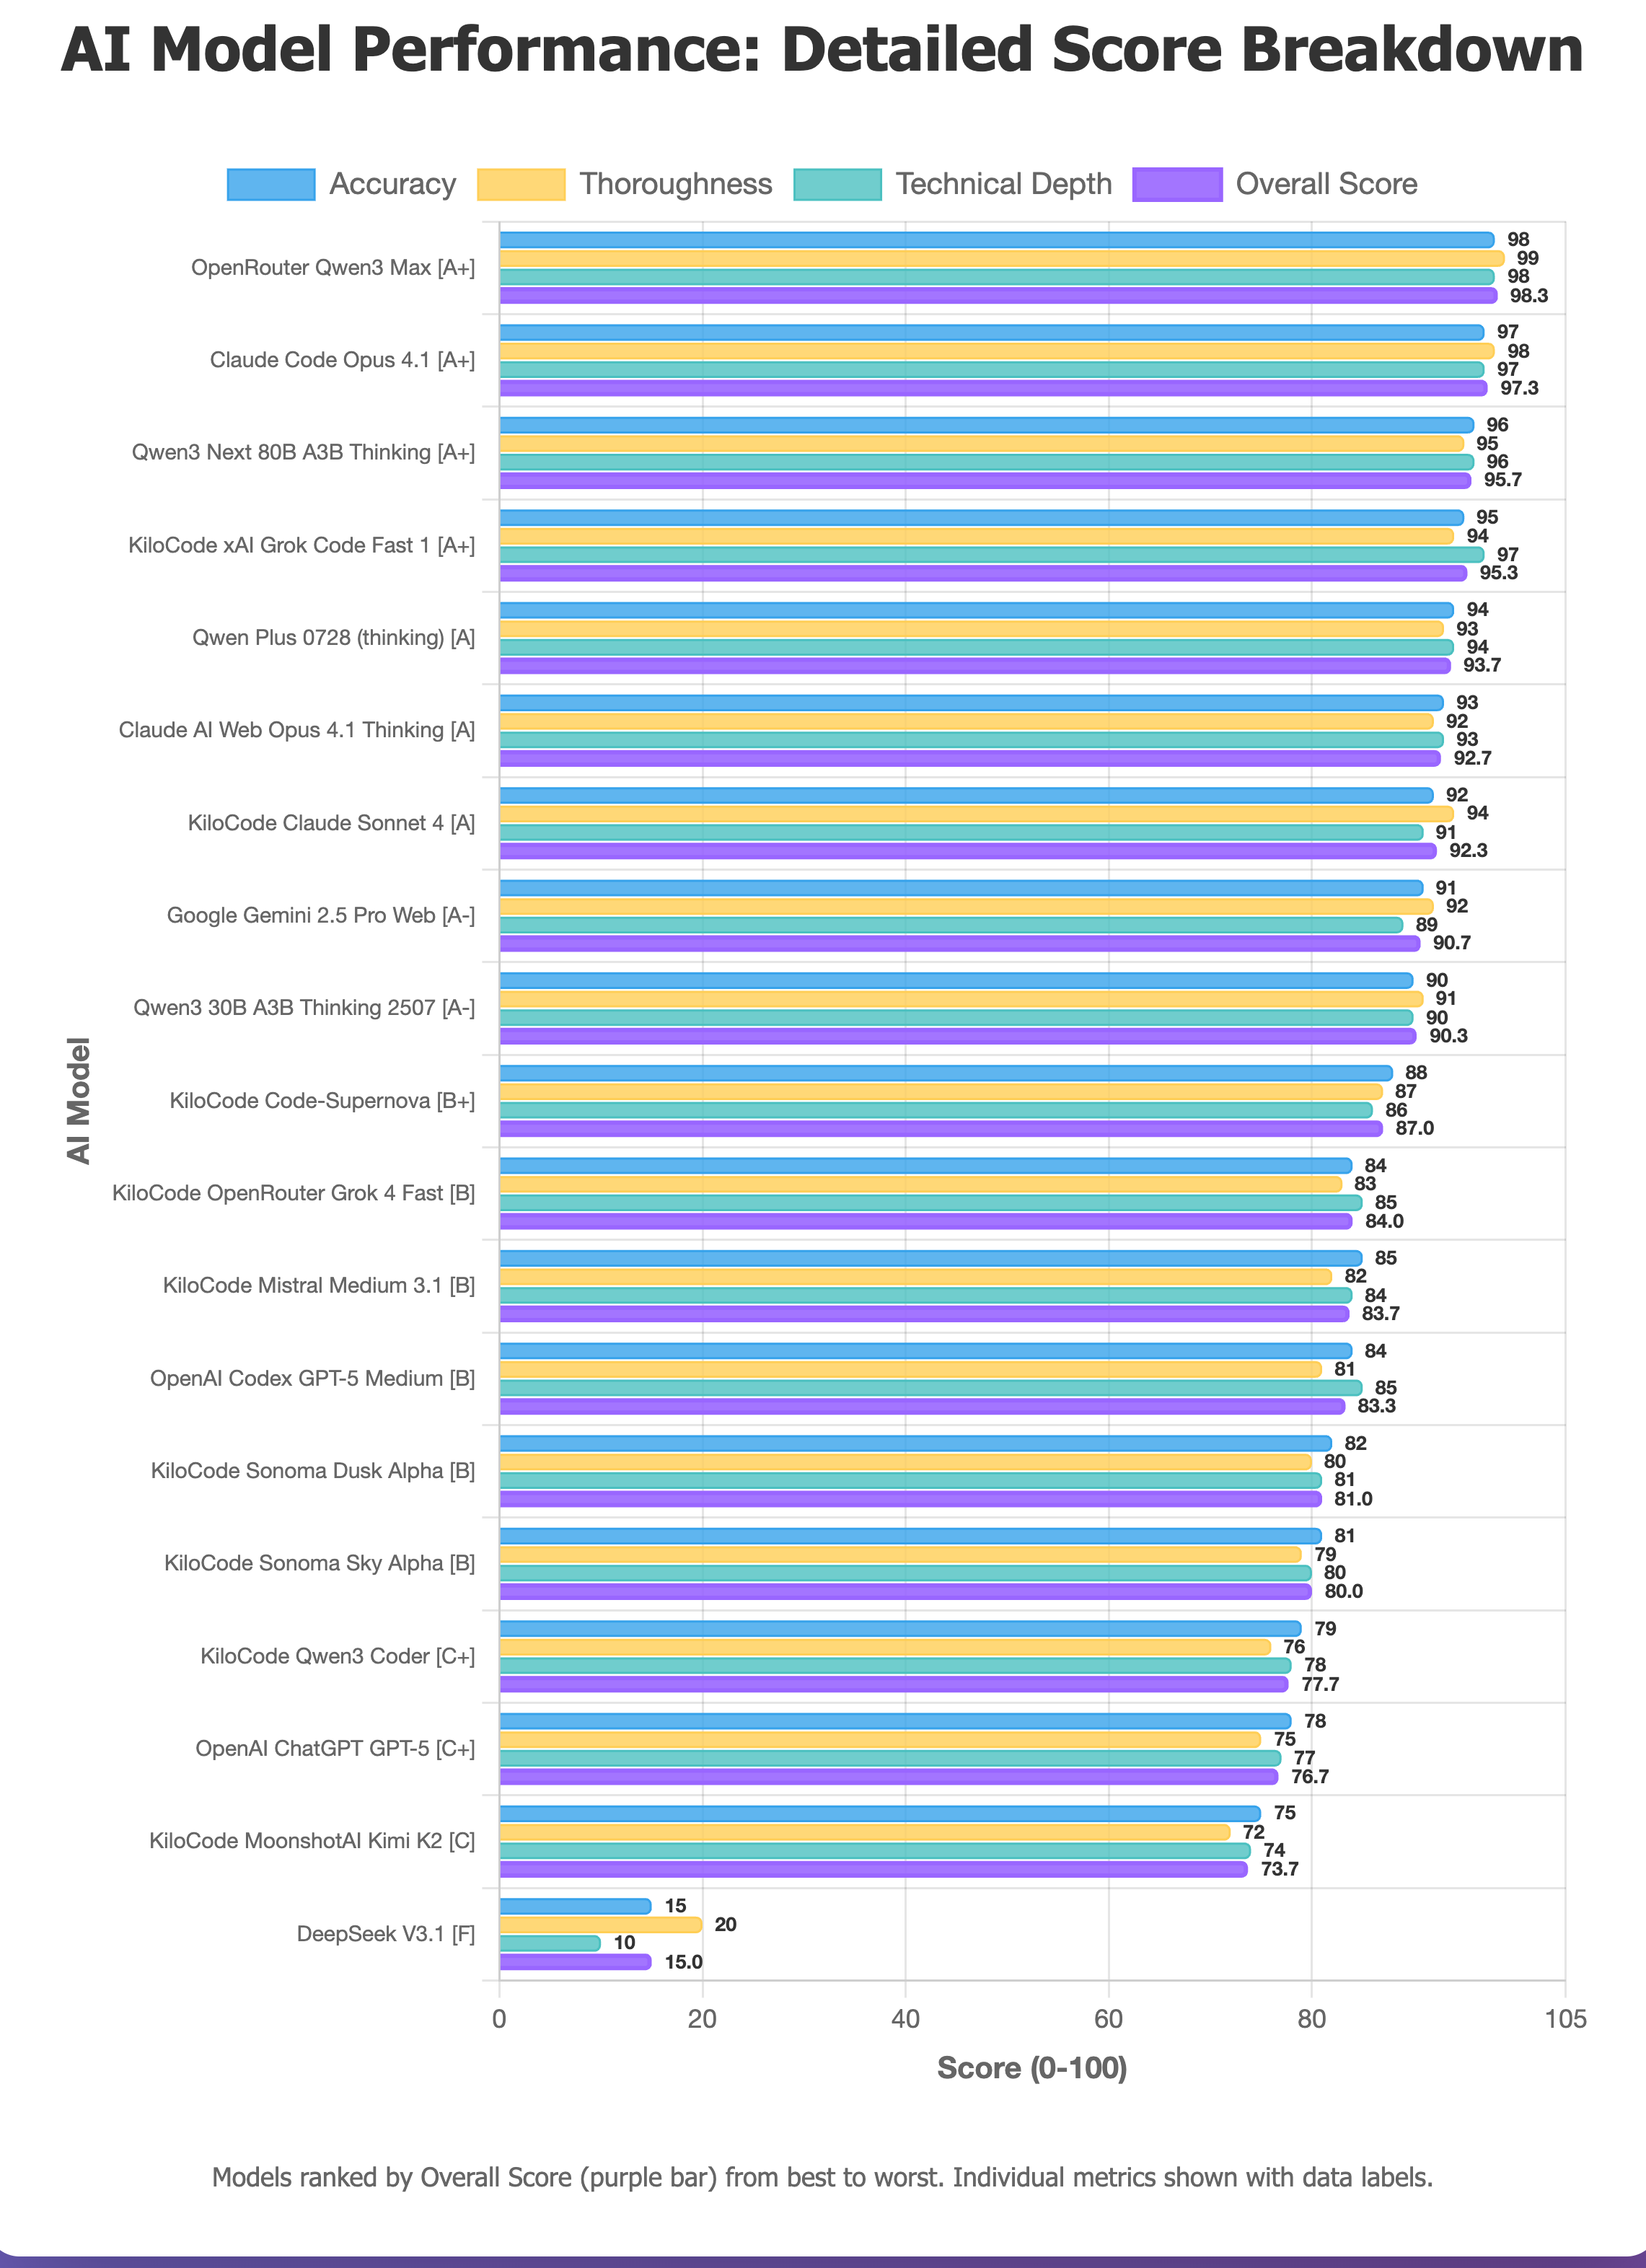
I tested 19 AI LLM models for code analysis and summaries and then used Claude Code Opus 4.1 evaluate and rank all 19 AI LLM model responses.
The 19 AI LLM models evaluated are (including costs for usage):
Note:
| Rank | AI Model | Accuracy (0-100) | Thoroughness (0-100) | Technical Depth (0-100) | Overall Score (0-100) | Grade |
|---|---|---|---|---|---|---|
| 1 | OpenRouter Qwen3 Max | 98 | 99 | 98 | 98.3 | A+ |
| 2 | Claude Code Opus 4.1 | 97 | 98 | 97 | 97.3 | A+ |
| 3 | Qwen3 Next 80B A3B Thinking | 96 | 95 | 96 | 95.7 | A+ |
| 4 | KiloCode xAI Grok Code Fast 1 | 95 | 94 | 97 | 95.3 | A+ |
| 5 | Qwen Plus 0728 (thinking) | 94 | 93 | 94 | 93.7 | A |
| 6 | Claude AI Web Opus 4.1 Thinking | 93 | 92 | 93 | 92.7 | A |
| 7 | KiloCode Claude Sonnet 4 | 92 | 94 | 91 | 92.3 | A |
| 8 | Google Gemini 2.5 Pro Web | 91 | 92 | 89 | 90.7 | A- |
| 9 | Qwen3 30B A3B Thinking 2507 | 90 | 91 | 90 | 90.3 | A- |
| 10 | KiloCode Code-Supernova | 88 | 87 | 86 | 87.0 | B+ |
| 11 | KiloCode OpenRouter Grok 4 Fast | 84 | 83 | 85 | 84.0 | B |
| 12 | KiloCode Mistral Medium 3.1 | 85 | 82 | 84 | 83.7 | B |
| 13 | OpenAI Codex GPT-5 Medium | 84 | 81 | 85 | 83.3 | B |
| 14 | KiloCode Sonoma Dusk Alpha | 82 | 80 | 81 | 81.0 | B |
| 15 | KiloCode Sonoma Sky Alpha | 81 | 79 | 80 | 80.0 | B |
| 16 | KiloCode Qwen3 Coder | 79 | 76 | 78 | 77.7 | C+ |
| 17 | OpenAI ChatGPT GPT-5 | 78 | 75 | 77 | 76.7 | C+ |
| 18 | KiloCode MoonshotAI Kimi K2 | 75 | 72 | 74 | 73.7 | C |
| 19 | DeepSeek V3.1 | 15 | 20 | 10 | 15.0 | F |

| Rank | Model Name | Score | Accuracy | Thoroughness | Key Strengths | Key Weaknesses |
|---|---|---|---|---|---|---|
| 1 | OpenRouter Qwen3 Max | 98.3/100 | Exceptional | Exceptional | Detailed feature breakdowns, structured formatting with tables/diagrams, systemd timer accuracy, OUTPUT chain cleanup explanation | Slightly verbose, could be more concise in executive summary |
| 2 | Claude Code Opus 4.1 | 97.3/100 | Excellent | Excellent | Professional report structure, comprehensive line counts, technical specifications section, clear v1.3.0/v1.3.1 separation | Could include more command examples |
| 3 | Qwen3 Next 80B A3B Thinking | 95.7/100 | Excellent | Excellent | Critical OUTPUT chain analysis, detailed temp rule tracking, race condition prevention understanding | Less structured formatting than top performers |
| 4 | KiloCode xAI Grok Code Fast 1 | 95.3/100 | Excellent | Excellent | Outstanding Mermaid diagrams, comprehensive command breakdown, systemd timer accuracy details | Very lengthy, some redundancy in explanations |
| 5 | Qwen Plus 0728 (thinking) | 93.7/100 | Excellent | Very Good | Clear v1.3.1 fixes understanding, good testing strategy coverage, accurate technical details | Less comprehensive than top tier, needs more implementation details |
| 6 | Claude AI Web Opus 4.1 Thinking | 92.7/100 | Very Good | Very Good | Well-structured analysis, good temp rule system understanding, CI testing innovation coverage | Slightly less technical depth than higher models |
| 7 | KiloCode Claude Sonnet 4 | 92.3/100 | Very Good | Excellent | Excellent line references, detailed function breakdown, good architectural overview | Could improve systemd integration explanation |
| 8 | Google Gemini 2.5 Pro Web | 90.7/100 | Very Good | Very Good | Excellent explanations for broader audience, well-formatted sections, good workflow breakdown | Could include more technical implementation details |
| 9 | Qwen3 30B A3B Thinking 2507 | 90.3/100 | Very Good | Very Good | Solid technical understanding, good CI coverage, matrix testing explanation | Lacks depth on v1.3.0+ advanced features |
| 10 | KiloCode Code-Supernova | 87.0/100 | Good | Good | Correct CSF identification, comprehensive feature list, understands systemd timers | Misses OUTPUT chain cleanup, lacks CI testing depth |
| 11 | KiloCode OpenRouter Grok 4 Fast | 84.0/100 | Good | Good | Clear technical sections, systemd timer understanding, race condition awareness | Response truncated, limited CI coverage, misses v1.3.1 fixes |
| 12 | KiloCode Mistral Medium 3.1 | 83.7/100 | Good | Good | Good relationship explanation between files, clear workflows | Lacks technical depth, misses advanced features |
| 13 | OpenAI Codex GPT-5 Medium | 83.3/100 | Good | Good | Concise bullet-point format, covers main features | Relatively brief, lacks detailed analysis |
| 14 | KiloCode Sonoma Dusk Alpha | 81.0/100 | Good | Good | Comprehensive feature list, matrix testing mentioned | Less detailed technical analysis |
| 15 | KiloCode Sonoma Sky Alpha | 80.0/100 | Good | Moderate | Very concise summary, covers basic functionality | Minimal depth, lacks advanced feature coverage |
| 16 | KiloCode Qwen3 Coder | 77.7/100 | Moderate | Moderate | Concise overview, identifies key components | Minimal technical detail, misses v1.3.0+ features |
| 17 | OpenAI ChatGPT GPT-5 | 76.7/100 | Moderate | Moderate | Clear structure, basic understanding shown | Incomplete OUTPUT chain coverage, lacks depth |
| 18 | KiloCode MoonshotAI Kimi K2 | 73.7/100 | Moderate | Moderate | Brief but accurate on basics | Lacks depth, no examples, misses critical features |
| 19 | DeepSeek V3.1 | 15.0/100 | Failed | Failed | None - fundamental misunderstanding | Completely wrong interpretation as "Code Security and Formatting Analysis" |
Key Strengths:
Key Weaknesses:
Key Strengths:
Key Weaknesses:
Key Strengths:
Key Weaknesses:
Key Strengths:
Key Weaknesses:
Key Strengths:
Key Weaknesses:
Key Strengths:
Key Weaknesses:
Key Strengths:
Key Weaknesses:
Key Strengths:
Key Weaknesses:
Key Strengths:
Key Weaknesses:
Key Strengths:
Key Weaknesses:
Key Strengths:
Key Weaknesses:
Key Strengths:
Key Weaknesses:
Key Strengths:
Key Weaknesses:
Key Strengths:
Key Weaknesses:
Key Strengths:
Key Weaknesses:
Key Strengths:
Key Weaknesses:
Key Strengths:
Key Weaknesses:
Key Strengths:
Key Weaknesses:
Major Error: Completely misunderstood the project as "Code Security and Formatting Analysis" instead of a firewall management tool. This represents a fundamental comprehension failure.
High-performing models demonstrated understanding through:
| Technical Aspect | Models That Covered It Well |
|---|---|
| Dual parsing modes (JSON/text) | 17/19 models |
| Temporary rule systemd timers | 15/19 models |
| OUTPUT chain cleanup (v1.3.1) | 8/19 models |
| Port specification formats | 13/19 models |
| Direction control (in/out/inout) | 14/19 models |
| Race condition prevention | 7/19 models |
| Handle-based rule management | 11/19 models |
| CI matrix testing | 15/19 models |
| AlmaLinux 10 container usage | 14/19 models |
| Artifact collection | 11/19 models |
The evaluation successfully differentiated models based on:
The evaluation reveals significant variance in AI models' ability to analyze complex technical systems. Top performers (OpenRouter Qwen3 Max, Claude Code Opus 4.1, Qwen3 Next 80B) demonstrated exceptional understanding of both the firewall management script and its testing infrastructure, accurately identifying critical features like OUTPUT chain cleanup and systemd timer implementation.
The analysis effectively separated models into clear performance tiers, with technical accuracy serving as the primary differentiator. The catastrophic failure of DeepSeek V3.1 serves as a reminder that even sophisticated models can fundamentally misunderstand context.
For technical code analysis tasks, this evaluation suggests preferring:
Models Tested: OpenRouter Qwen3 Max, Claude Code Opus 4.1, Qwen3 Next 80B A3B Thinking, KiloCode xAI Grok Code Fast 1, Qwen Plus 0728 (thinking), Claude AI Web Opus 4.1 Thinking, KiloCode Claude Sonnet 4, Google Gemini 2.5 Pro Web, Qwen3 30B A3B Thinking 2507, KiloCode Code-Supernova, KiloCode OpenRouter Grok 4 Fast, KiloCode Mistral Medium 3.1, OpenAI Codex GPT-5 Medium, KiloCode Sonoma Dusk Alpha, KiloCode Sonoma Sky Alpha, KiloCode Qwen3 Coder, OpenAI ChatGPT GPT-5, KiloCode MoonshotAI Kimi K2, DeepSeek V3.1
centminmod/code-supernova-evaluation is a public repo on GitHub by centminmod. Its maker has not written a description.
It declares no license on GitHub. Public does not mean open source: without a license, nobody is granted the right to reuse it.
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
Its last change on GitHub was on 2025-09-30. Take My Repo does not judge from that whether it is maintained.
Shared starter template configuration and CLAUDE.md memory bank system for Claude Code
Nobody has reviewed it on Take My Repo yet, which says nothing about its quality.

Shell menu based Nginx LEMP web stack auto installer (GPLv3 licensed) for AlmaLinux and Rocky Linux
Multi-AI documentation for OpenClaw: architecture, security audits, deployment guide
Self-hosted email verification script to clean up bad invalid email address lists. Supports various commercial email verification provider APIs all in one script