Cross-Lingual-Voice-Cloning
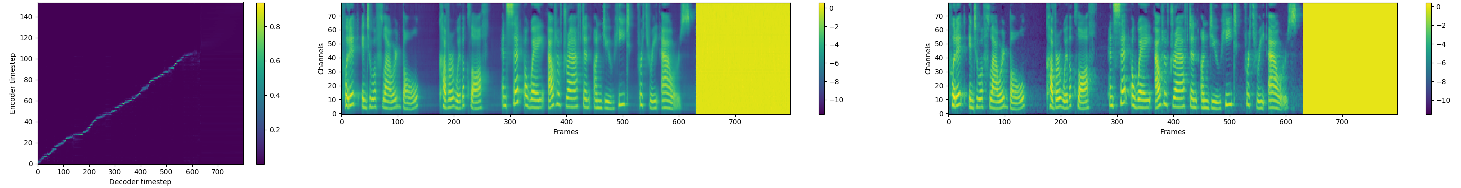
Tacotron 2 - PyTorch implementation with faster-than-realtime inference modified to enable cross lingual voice cloning.
- 359
- Jupyter Notebook
- BSD-3-Clause
- 4 y ago
Training and evaluation notebooks for Punctuation restoration using Transformers
Repo deterministic-algorithms-lab/PunctFormer, read from GitHub 10 min ago. deterministic-algorithms-lab has not joined Take My Repo.
deterministic-algorithms-lab/PunctFormer is a public repo on GitHub by deterministic-algorithms-lab. Training and evaluation notebooks for Punctuation restoration using Transformers. It declares no license on GitHub. Public does not mean open source: without a license, nobody is granted the right to reuse it. It is written mainly in Jupyter Notebook, has 1 stars and last changed on 2021-01-09. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-21.
deterministic-algorithms-lab/PunctFormer is a public repo on GitHub by deterministic-algorithms-lab. Training and evaluation notebooks for Punctuation restoration using Transformers.
It declares no license on GitHub. Public does not mean open source: without a license, nobody is granted the right to reuse it.
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
Its last change on GitHub was on 2021-01-09. Take My Repo does not judge from that whether it is maintained.
Nobody has reviewed it on Take My Repo yet, which says nothing about its quality.
Tacotron 2 - PyTorch implementation with faster-than-realtime inference modified to enable cross lingual voice cloning.
A pathway and collection of resources to learning Jax from beginning to advance.
This repository provides a selection of very basic and minimal notebooks for various NLP tasks in written in Jax.
This repository provides download and cleaning scripts for various datasets of NLP in Indic languages and converting them into a standard format.
XLM implementation with utilities to process and train on large multi-lingual datasets, with not enough RAM.