python-web
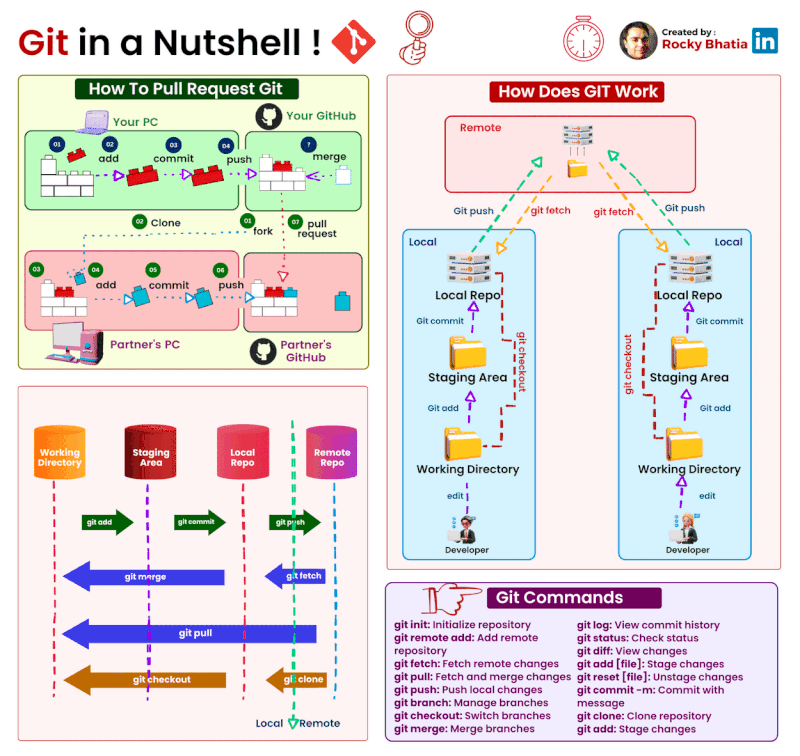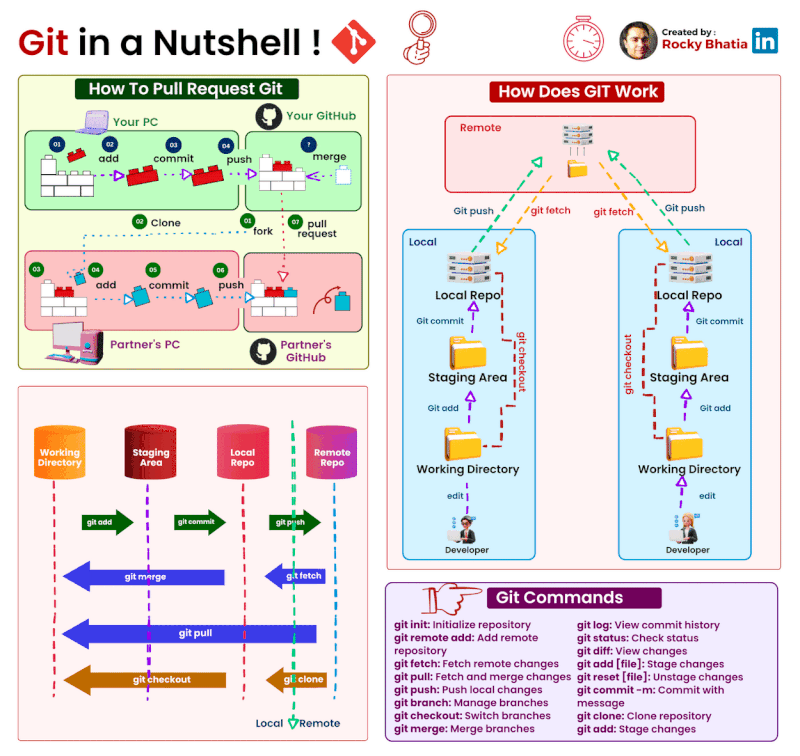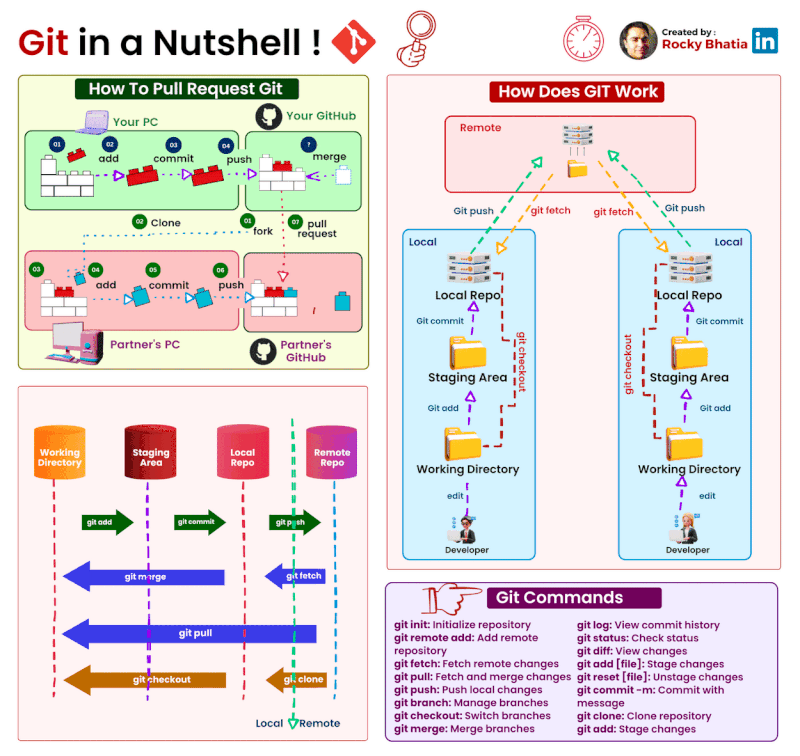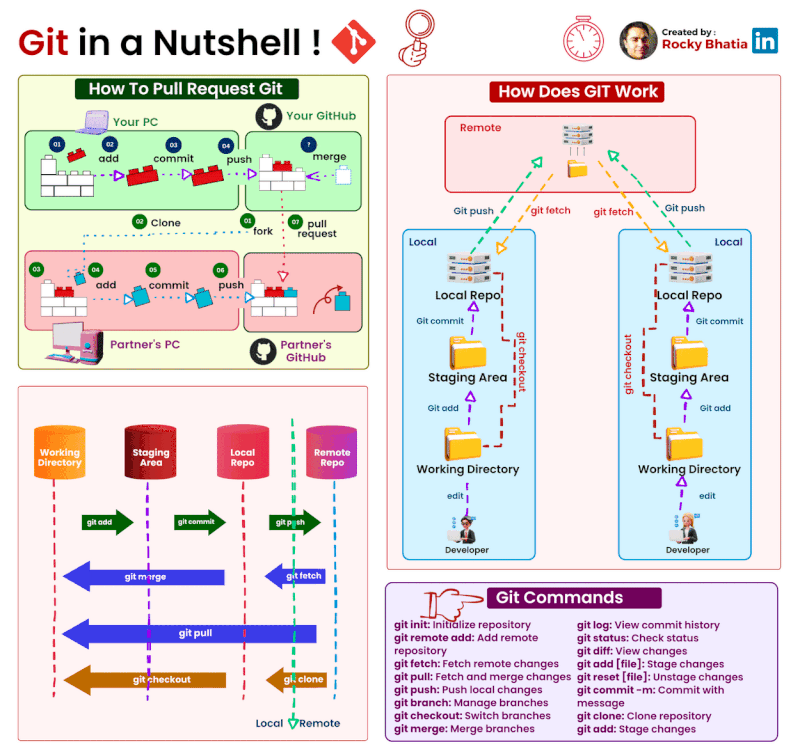
This topic explains how to implement web scraping and python web development. Web scraping topics such as scrapy, beautiful soup, and others will be covered. A case study based on a Malaysian website.
- 137
- 3 y ago
Repo drshahizan/python-web, read from GitHub 14 h ago. drshahizan has not joined Take My Repo.
In short
drshahizan/python-web is a public repo on GitHub by drshahizan. This topic explains how to implement web scraping and python web development. Web scraping topics such as scrapy, beautiful soup, and others will be covered. A case study based on a Malaysian website. It declares no license on GitHub. Public does not mean open source: without a license, nobody is granted the right to reuse it. It is written mainly in Jupyter Notebook, has 137 stars and last changed on 2023-06-19. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-21.
Don't forget to hit the :star: if you like this repo.
About Us
The information on this Github is part of the materials for the subject High Performance Data Processing (SECP3133). This folder contains general big data information as well as big data case studies using Malaysian datasets. This case study was created by a Bachelor of Computer Science (Data Engineering), Universiti Teknologi Malaysia student.

📚 Course: High Performance Data Processing
- Python for beginners
- Web scraping and Python web framework
- Exploratory data analysis
- Big data processing
Contents:

Web Scraping
- Grouping: Web Scraping
- Web Scraping with EDA and Visualization Using Python
- Python Web Scraping - Quick Guide
- Web Scraping of E-Commerce Website Using BeautifulSoup in Python
- Github: malaysia-election-data-scraping
- Applications and a Guide to Web Scraping
- Github:malaysiastockbiz_scraper
- An automated web scraping tool for Malaysia tourism
- 7 Python Libraries For Web Scraping To Master Data Extraction
- Web Scraping Freelancers in Malaysia
- Web Scraping, Regular Expressions, and Data Visualization: Doing it all in Python
- 5 Web Scraping Projects with Python
Tutorial
- Video: Web Scraping untuk laman web berkaitan Bursa Malaysia
- Video: Web Scraping (The Star Malaysia News)
- Video: Scraping YellowPages.my | Name, Website, Email, Phone | Yellow Pages Malaysia
- Video: Tutorial Web Scraper - Dengan Chrome Web Scraper
- Video: Cara Scraping Banyak Produk Tokopedia Dengan Tools Gratisan Chrome
- Python Web Scraping Tutorial: Step-By-Step
- Web Scraping Python Tutorial – How to Scrape Data From A Website

Selenium
- Web scraping E-commerce sites to compare prices with Python — Part 1
- Web scraping E-commerce sites to compare prices with Python — Part 2
- Web Scraping Election Results of PRU-15 (GE-15) using Python
Beautiful Soup
Scrapy
- Scrapy.org
- Github: Scrapy
- Python Scrapy Tutorial for Beginners
- Spider Web Crawler: Mudah.my
- Scrapy: Malaysia House Property
Requests
Lxml
🌟 Case Study: Web Scraping
| Team | Library | Website | GitHub |
|---|---|---|---|
| Group 10 | Beautiful soup | StudyMalaysia.com | |
| High Five | Beautiful soup | EduSpiral Consultant Services | |
| QwQ | Beautiful soup | States and federal territories of Malaysia | |
| SDS | Scrapy | Book Depository | |
| BigMac | Scrapy | CompAsia.com | |
| SIX | Scrapy | bukukita.com | |
| AdMiPeQa | Selenium | Lazada | |
| SamVerse | Selenium | Malaysia General Election (GE-15) | |
| Group 9 | Selenium | Lazada Shopee | |
| No Name | Requests | Puma: sneakers | |
| Quad | Lxml | Jobstreet.com |
Contribution 🛠️
Please create an Issue for any improvements, suggestions or errors in the content.
You can also contact me using Linkedin for any other queries or feedback.
Questions
What is python-web?
drshahizan/python-web is a public repo on GitHub by drshahizan. This topic explains how to implement web scraping and python web development. Web scraping topics such as scrapy, beautiful soup, and others will be covered. A case study based on a Malaysian website.
Is python-web open source?
It declares no license on GitHub. Public does not mean open source: without a license, nobody is granted the right to reuse it.
Does python-web run on macOS, Windows or Linux?
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
How do I install python-web?
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
Is python-web still maintained?
Its last change on GitHub was on 2023-06-19. Take My Repo does not judge from that whether it is maintained.