dify
Build Agentic workflows, RAG pipelines, with rich AI model and tool support on one collaborative workspace. Deploy on cloud, VPC, or self-hosted, so teams move from prototype to production without rebuilding the stack.
- 162k
- Python
- 26 min ago
An inspectable coding agent. Trace changes, diagnose failed runs, and share test evidence. Local-first Python, no-key demo, standalone HTML reports.
Repo hwfengcs/DM-Code-Agent, read from GitHub 1 min ago. hwfengcs has not joined Take My Repo.
hwfengcs/DM-Code-Agent is a public repo on GitHub by hwfengcs. An inspectable coding agent. Trace changes, diagnose failed runs, and share test evidence. Local-first Python, no-key demo, standalone HTML reports. It declares the MIT license on GitHub. It is written mainly in Python, has 152 stars and last changed on 2026-11-15. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-22.
A coding agent you can inspect.
Trace the changes. Diagnose the failure. Check the test evidence.
English · 简体中文
Interactive demo / Quick start / Real maintenance case / Docs
DM-Code-Agent works in your local repository and keeps an append-only record of each run. Follow the evidence in the terminal or browser, then export a report another developer can open.
Two runs. The same edit. Only one runs the tests.
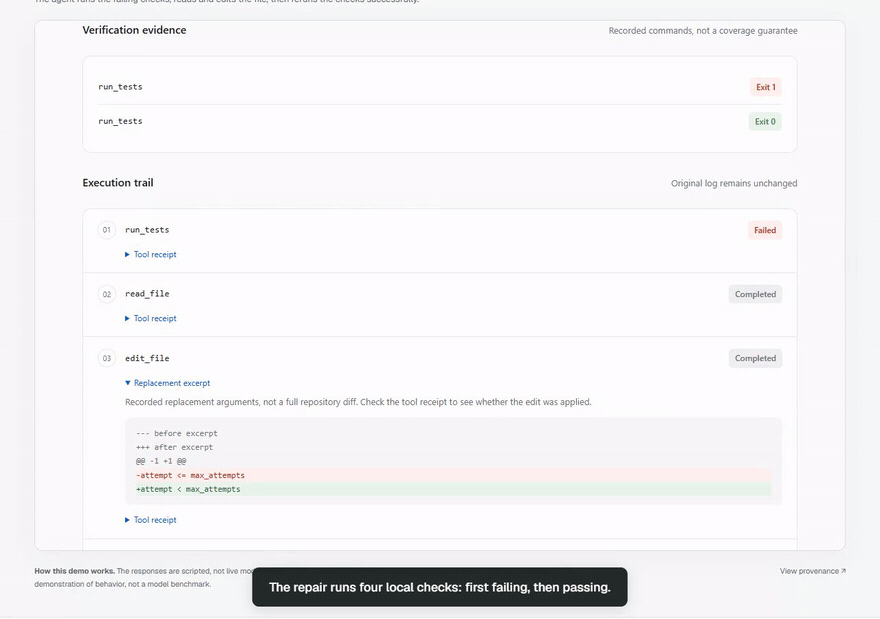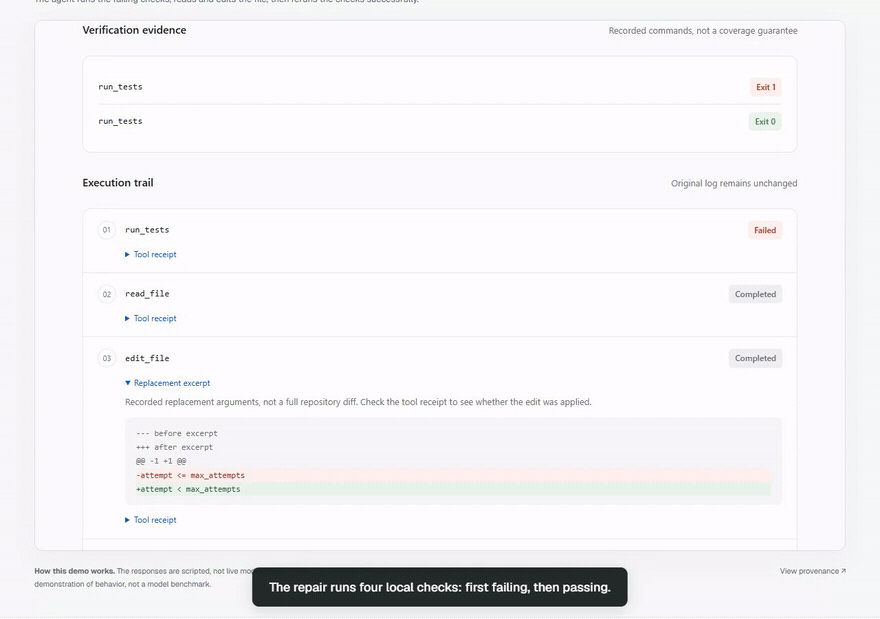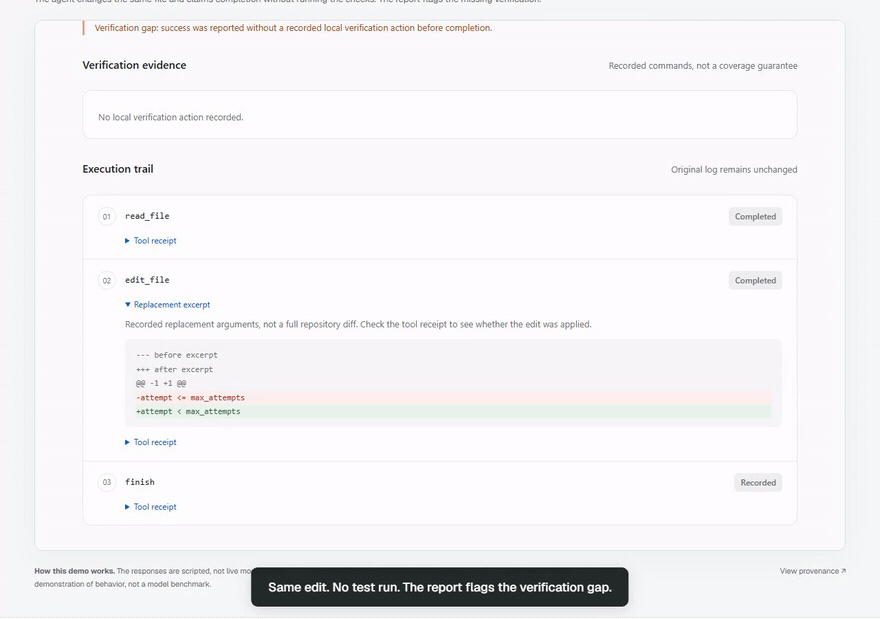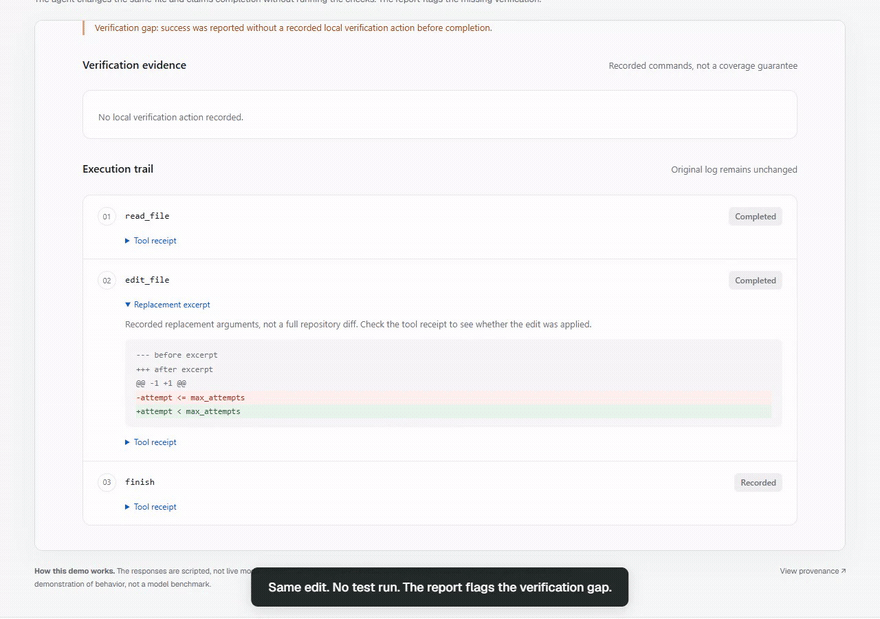
10-second excerpt of the real browser walkthrough. Scripted assistant decisions; real file edits and unittest checks. No model key required. Watch all 38 seconds.
Python 3.10+, three commands. The release wheel includes the browser console; no Node.js needed.
pip install "dm-code-agent[web] @ https://github.com/hwfengcs/DM-Code-Agent/releases/download/v2.1.1/dm_code_agent-2.1.1-py3-none-any.whl"
dm-agent-demo --output demo-run
dm-agent-web --sessions-dir demo-run/sessions --read-only
Open the complete local URL printed by the server. Choose verified.jsonl or unverified.jsonl
and inspect the difference. Use a new or empty output directory.
| Run | Evidence |
|---|---|
verified.jsonl |
A retry-boundary bug, a failing test, an edit, and passing checks |
unverified.jsonl |
The same edit without a test run; the analyzer flags the verification gap |
The scripted client drives the real agent, file tools, and Python unittest. It makes no model calls, reads no user configuration or extensions, and writes only to the chosen new or empty directory. It demonstrates inspectability, not model performance.
dm-agent-trace analyze demo-run/sessions/unverified.jsonl
dm-agent-trace export demo-run/sessions/verified.jsonl --output report.html --include-content
Open report.html without a server. The demo contains only bundled sample code. For real sessions,
export defaults to a structural summary; --include-content adds redacted task, tool, and edit
excerpts. Review those reports before sharing: redaction cannot recognize every secret.
Set your provider's key: DEEPSEEK_API_KEY, OPENAI_API_KEY, CLAUDE_API_KEY, or GEMINI_API_KEY.
Run from a Git checkout you can review:
dm-agent "Inspect this repository and identify the modules that most need tests" --provider deepseek --trace sessions/review.jsonl --show-steps
dm-agent-trace analyze sessions/review.jsonl
Configuration and first task · Xinference / local-model recipe · Web console
The agent can modify files and run commands with your local permissions; it is not a sandbox.
--trace is redacted by default. Full model I/O, checkpoints, and tool replay have separate,
explicit controls. Session privacy and replay.
| Your question | The evidence you can inspect |
|---|---|
| What changed? | Ordered tool calls, arguments, observations, and replacement excerpts |
| Where did it fail? | Failure-stage analysis and recovery attempts |
| Did it verify? | Recorded validation actions and a verification-gap signal |
| What changed between runs? | Trace comparison and per-task benchmark regressions |
| What happened to old context? | Compaction appends derived records; originals remain available |
The CLI and console share the same analysis functions. Standalone HTML reports need no server. Recorded checks are not a proof of correctness, and replacement excerpts are not a complete Git diff. Explicit replay and checkpoint-based forks are available for local investigation.
12 targeted checks passed. The broader suite still failed.
A live model attempted to repair a historical defect in this repository. Two broader checks remained failing, and the agent exhausted its step budget. The incomplete result is preserved with its patch, supplied tests, token usage, and an independent offline reproduction.
Inspect the live run · Read and reproduce the case
Small failures, useful lessons. Each article links its original evidence and an offline reproduction.
| Story | What we learned |
|---|---|
| More steps did not establish a better agent | Pass counts rose from 22 to 24, alongside four regressions and 30.6% more estimated tokens. |
| When source code says “error” | from errors import NotFound was mistaken for tool failure; reclassification removed 38 false positives in the inspected traces. |
| Find the text before changing the code | Content-anchored edits addressed a line-range failure mode, then exposed another bug. |
The bundled benchmark has 30 hidden-test tasks across coding and maintenance. Historical runs support conclusions about those configurations, not a leaderboard claim. The demo is not an evaluation. Methodology · Project status · Research logs.
git clone https://github.com/hwfengcs/DM-Code-Agent.git
cd DM-Code-Agent
uv sync --frozen --extra dev
uv run --frozen dm-agent-demo --output demo-run
uv run --frozen python -m pytest
uv run --frozen python -m dm_agent.evals.cli --variant full --task direct_finish
The contribution guide and agent instructions list the complete checks. Extension examples show how to add behavior outside the kernel.
The homepage, setup guide, local-model recipe, and articles are bilingual; deeper reference docs are mostly in Chinese. Reproducible issues and focused contributions are welcome.
If the evidence helps, give the project a star.
hwfengcs/DM-Code-Agent is a public repo on GitHub by hwfengcs. An inspectable coding agent. Trace changes, diagnose failed runs, and share test evidence. Local-first Python, no-key demo, standalone HTML reports.
It declares the MIT license on GitHub.
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
Its last change on GitHub was on 2026-11-15. GitHub counts 1 open issue and pull requests. Take My Repo does not judge from that whether it is maintained.
Nobody has reviewed it on Take My Repo yet, which says nothing about its quality.
Build Agentic workflows, RAG pipelines, with rich AI model and tool support on one collaborative workspace. Deploy on cloud, VPC, or self-hosted, so teams move from prototype to production without rebuilding the stack.
Independent Auditing of AI Agents. Run by human or the agent itself, to answer the most crucial question in the AI Agent Economy. Is the agent doing what is supposed to do? With iFixAi you can have this answer in less than 120 seconds.
Reverse engineer anything with agents, from app behavior down to native binaries.
The agent harness performance optimization system. Skills, instincts, memory, security, and research-first development for Claude Code, Codex, Opencode, Cursor and beyond.