flux-dev-4bit
Flux dev quantized implementation
- 1
- 21 mo ago
Repo pythonlessons/flux-dev-4bit, read from GitHub 1 min ago. pythonlessons has not joined Take My Repo.
In short
pythonlessons/flux-dev-4bit is a public repo on GitHub by pythonlessons. Flux dev quantized implementation. It declares no license on GitHub. Public does not mean open source: without a license, nobody is granted the right to reuse it. It is written mainly in Jupyter Notebook, has 1 stars and last changed on 2025-03-08. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-18.
AI models this project points to
Flux.1-dev model with 4 bit Quantization
Flux.1 has arrived, setting a new benchmark in the world of open-weight image models. With 12 billion parameters, it surpasses industry giants like Midjourney V6, OpenAI’s Dall-E 3, and Stability AI’s SD3 Ultra in terms of image quality and performance.
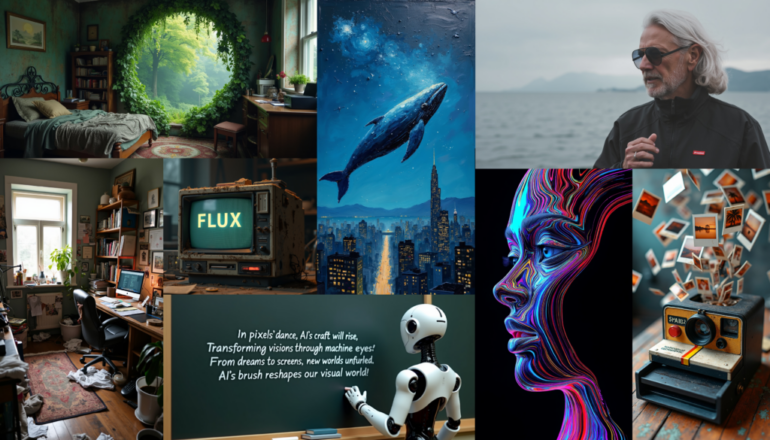
Flux is an innovative text-to-image AI model developed by Black Forest Labs that has quickly gained popularity among generative AI enthusiasts and digital artists. Its ability to generate high-quality images from simple text prompts sets it apart. The Flux 1 family includes three versions of their image generator models:
- Flux.1-pro (private and paid https://docs.bfl.ml/pricing/)
- Flux.1-dev (open source https://huggingface.co/black-forest-labs/FLUX.1-dev)
- Flux.1-schnell (open source https://huggingface.co/black-forest-labs/FLUX.1-schnell)
Even thought, these models are already very efficient, and might be ran on consumer GPU, it is always good to have a more efficient version. This repository contains a 4-bit quantized version of the Flux.1-dev model, which is a lighter version of the original model that can be run on consumer GPUs with less VRAM.
Personally, I have 1080TI GPU, so I can't run the full dev or schnell model, and if I use some tweaks to offload the model to CPU, it will take a long time to generate an image. So, I decided to find some other way to run the model on my GPU, and I found that 4-bit quantization is a good way to reduce the model size and VRAM usage. And I was able to generate images on my GPU!
So I didn't quantized the model, but someoen else did, and I just tried their way. The original repo is https://github.com/HighCWu/flux-4bit.
Note:
- The model is quantized to 4-bit, which means that the model is smaller, faster, and can be run on consumer GPUs with less VRAM.
- To run this model, you must have GPU with at least 8GB VRAM (can run with reduced width and height).
- Because model is quantized, the quality of the generated images may be slightly lower than the original model.
- If you don't have GPU with 8GB VRAM, you can try on colab implementation here and then download results.
- To download original
black-forest-labs/FLUX.1-devmodel you will need to download it from Hugging Face model hub here, or download it usingtransformerslibrary and adding your API key.
How to use
-
Clone the repo (or copy
model.pyfile to your project):git clone https://github.com/pythonlessons/flux-dev-4bit cd flux-dev-4bit -
Install requirements:
pip install -r requirements.txt
-
Run in python:
import os
import json
import torch
import typing
from diffusers import FluxPipeline

from model import T5EncoderModel, FluxTransformer2DModel

def run_flux_pipeline_batch(
    prompts: typing.List[str],
    output_names: typing.List[str] = None,
    output_folder: str = "output",
    height: int = 512,
    width: int = 512,
    guidance_scale: float = 3.5,
    num_inference_steps: int = 50,
    max_sequence_length: int = 512,
    model_id: str = "black-forest-labs/FLUX.1-dev",
    quant_model_id: str = "HighCWu/FLUX.1-dev-4bit",
    seed: int = None,
    metadata: str = 'metadata',
) -> None:
    """
    Run the Flux pipeline on a batch of prompts and save the results to disk.

    Args:
        prompts: A list of prompts to generate images for.
        output_names: A list of output file names to save the images as. If None, the images will be named
            "flux-dev-4bit_<n>.png" where n is the number of images saved so far.
        output_folder: The folder to save the images in. If None, the images will be saved in the current working directory.
        height: The height of the generated images in pixels.
        width: The width of the generated images in pixels.
        guidance_scale: The guidance scale for the text-to-image model.
        num_inference_steps: The number of inference steps to take for each prompt.
        max_sequence_length: The maximum sequence length to use for the text-to-image model.
        model_id: The ID of the base model to use for the pipeline.
        quant_model_id: The ID of the quantized model to use for the pipeline.
        seed: An optional seed to use for the PyTorch random number generator. If None, no seed will be used.
        metadata: An optional folder to save metadata about the generated images in. If None, no metadata will be saved.

    Returns:
        None
    """
    if output_folder and not os.path.exists(output_folder):
        os.makedirs(output_folder)

    if metadata and not os.path.exists(metadata):
        os.makedirs(metadata)

    # Load the model components once
    text_encoder_2 = T5EncoderModel.from_pretrained(
        quant_model_id,
        subfolder="text_encoder_2",
        torch_dtype=torch.bfloat16,
    )
    transformer = FluxTransformer2DModel.from_pretrained(
        quant_model_id,
        subfolder="transformer",
        torch_dtype=torch.bfloat16,
    )
    pipe = FluxPipeline.from_pretrained(
        model_id,
        text_encoder_2=text_encoder_2,
        transformer=transformer,
        torch_dtype=torch.bfloat16,
    )
    pipe.remove_all_hooks()
    pipe = pipe.to("cuda")
    pipe.enable_attention_slicing()

    # Ensure output_names matches prompts in length
    if output_names is None:
        output_names = [None] * len(prompts)

    for prompt, output_name in zip(prompts, output_names):
        print(f"Processing prompt: {prompt[:150]}...")  # Display part of the prompt for context

        image = pipe(
            prompt,
            height=height,
            width=width,
            guidance_scale=guidance_scale,
            output_type="pil",
            num_inference_steps=num_inference_steps,
            max_sequence_length=max_sequence_length,
            generator=torch.Generator("cpu").manual_seed(seed) if isinstance(seed, int) else None,
        ).images[0]

        if output_name:
            output_path = os.path.join(output_folder, output_name)
        else:
            output_files = len([f for f in os.listdir(output_folder) if f.endswith(".png")])
            output_name = f"flux-dev-4bit_{output_files}.png"
            output_path = os.path.join(output_folder, output_name)

        image.save(output_path)
        print(f"Saved to: {output_path}")

        # Save metadata
        if metadata:
            metadata_path = os.path.join(metadata, output_name.replace(".png", ".json"))
            metadata_dict = {
                "prompt": prompt,
                "height": height,
                "width": width,
                "guidance_scale": guidance_scale,
                "num_inference_steps": num_inference_steps,
                "max_sequence_length": max_sequence_length,
                "model_id": model_id,
                "quant_model_id": quant_model_id,
                "seed": seed,
                "gpu": torch.cuda.get_device_name(0),
                'output_path': output_path,
            }
            with open(metadata_path, "w") as f:
                json.dump(metadata_dict, f, indent=4)

    # Release GPU memory after processing all prompts
    del text_encoder_2, transformer, pipe, image  # Delete model and image variables
    torch.cuda.empty_cache()  # Clear PyTorch CUDA cache

prompts = [
    "old man with glasses portrait, photo, 50mm, f1.4, natural light, Pathéchrome",
    "A playful and photorealistic image of a golden retriever wearing a chef's hat and apron, standing at a kitchen counter making pizza. The counter is covered in flour, and the dog's paw is lifting a slice with melted cheese stretching. Include realistic fur texture and playful eyes.",
    "A beautiful, anime-style portrait of a young girl with expressive eyes, wearing a futuristic astronaut helmet, vibrant orange and pink flowers surrounding the helmet, surreal composition",
    "A girl astronaut exploring the cosmos, floating among planets and stars, high quality detail, anime screencap, studio Ghibli style, illustration, high contrast, masterpiece, best quality",
    "Masterpiece, best quality, girl, collarbone, wavy hair, looking at viewer, blurry foreground, upper body, necklace, contemporary, plain pants, intricate, print, pattern, ponytail, freckles, red hair, dappled sunlight, smile, happy",
]

run_flux_pipeline_batch(prompts=prompts)
-
Results from above code:


Questions
What is flux-dev-4bit?
pythonlessons/flux-dev-4bit is a public repo on GitHub by pythonlessons. Flux dev quantized implementation.
Is flux-dev-4bit open source?
It declares no license on GitHub. Public does not mean open source: without a license, nobody is granted the right to reuse it.
Does flux-dev-4bit run on macOS, Windows or Linux?
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
How do I install flux-dev-4bit?
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
Is flux-dev-4bit still maintained?
Its last change on GitHub was on 2025-03-08. Take My Repo does not judge from that whether it is maintained.
What do people who ran flux-dev-4bit say?
Nobody has reviewed it on Take My Repo yet, which says nothing about its quality.