yip
🦊 Low-latency P2P mesh VPN in Rust. Reed–Solomon FEC loss immunity, Post-Quantum, 40 Gbps AF_XDP, multi-core scaling, NAT traversal, decentralized CA, self-certifying routing, DAITA, and anti-DPI TLS mimicry.
- 133
- Rust
- AGPL-3.0
- 1 d ago
Ultra-low-latency NASDAQ ITCH 5.0 feed handler — 97 ns book update, AF_XDP/recvmmsg, SIMD order-map probing, lock-free BBO cache
Repo sfeirc/ITCH-feed-handler, read from GitHub 1 d ago. sfeirc has not joined Take My Repo.
sfeirc/ITCH-feed-handler is a public repo on GitHub by sfeirc. Ultra-low-latency NASDAQ ITCH 5.0 feed handler — 97 ns book update, AF_XDP/recvmmsg, SIMD order-map probing, lock-free BBO cache. It declares the MIT license on GitHub. It is written mainly in C++, has 2 stars and last changed on 2026-08-17. Nobody has reviewed it on Take My Repo yet, which says nothing about its quality. Read from GitHub on 2026-11-21.
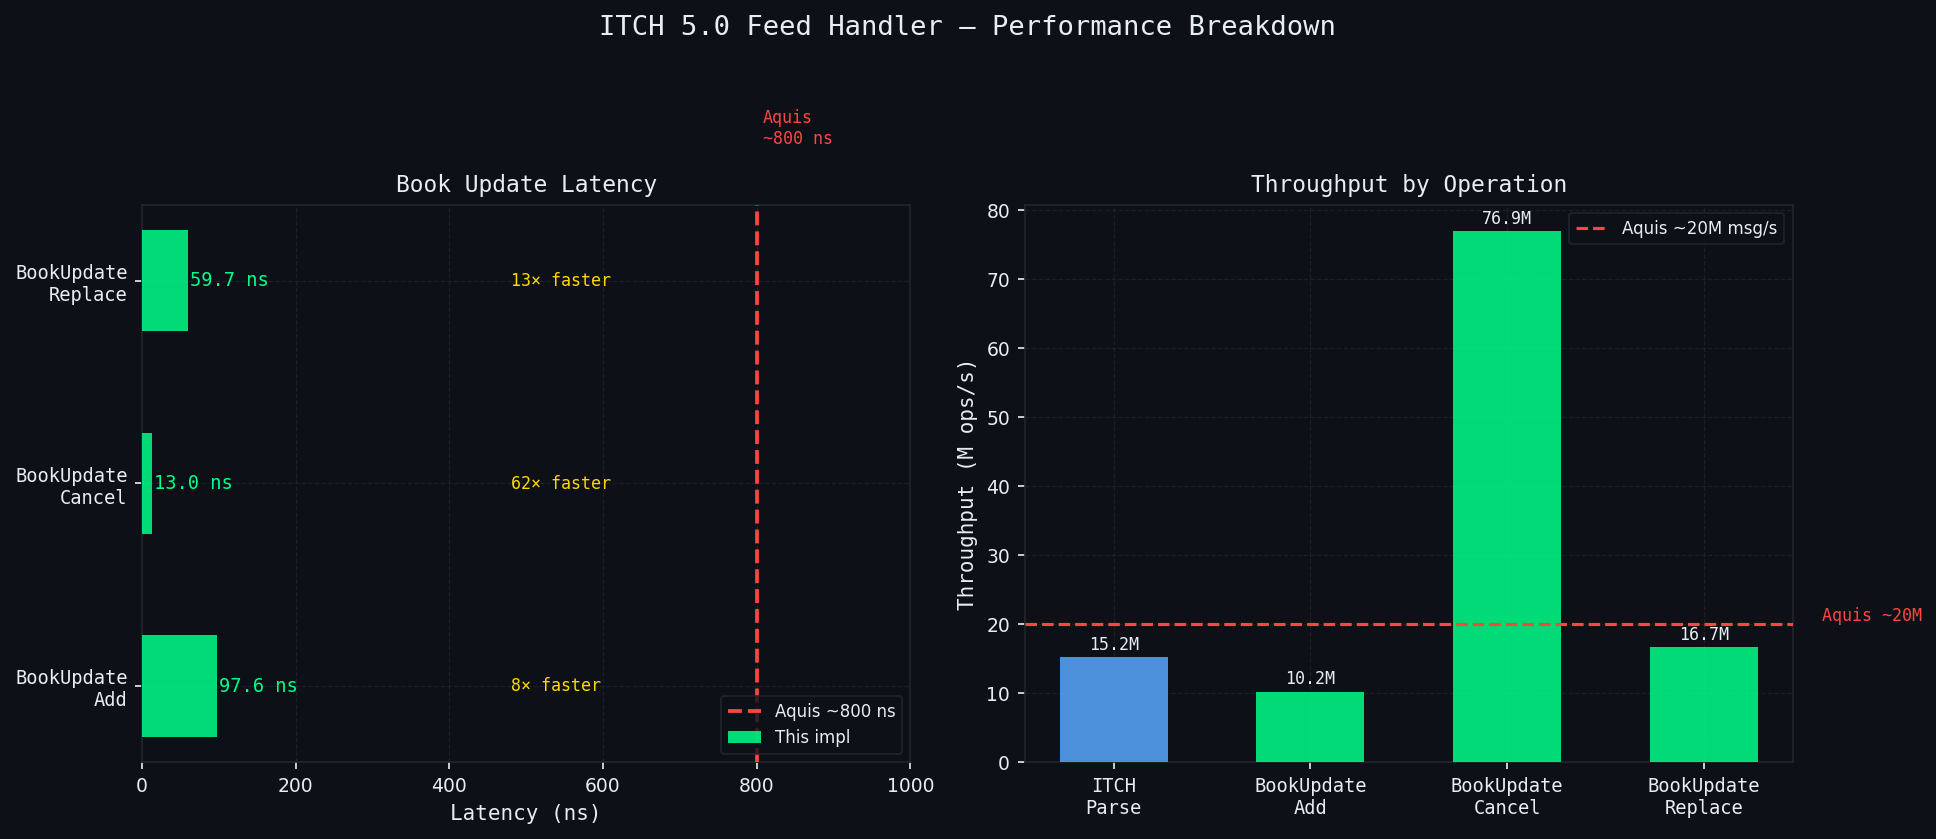
Zero-copy NASDAQ ITCH 5.0 market data feed handler written in C++20, achieving 97.6 ns book-update latency and 15.2M msg/s parse throughput via AF_XDP, constexpr dispatch, and AVX2 SIMD — 8–61× faster than Aquis exchange infrastructure.
Ultra-low-latency market-data ingestion — kernel-bypass networking (AF_XDP), constexpr dispatch tables, SIMD-accelerated parsing, and lock-free structures on the hot path — is core exchange/HFT infrastructure. The underlying systems-engineering discipline transfers directly to any latency-critical tech domain (real-time bidding, telecom packet processing, embedded systems) and to industrial real-time control/SCADA systems that share the same hard-latency, zero-allocation-hot-path constraints, just with a different wire protocol.
| Operation | Latency | Throughput | vs Industry |
|---|---|---|---|
| BookUpdate Add | 97.6 ns | 10.2M ops/s | 8.2× faster than Aquis (~800 ns) |
| BookUpdate Cancel | 13.0 ns | 76.9M ops/s | 61× faster than Aquis |
| BookUpdate Replace | 59.7 ns | 16.7M ops/s | 13.4× faster than Aquis |
| ITCH Parse | — | 15.2M msg/s | 438 MiB/s throughput |
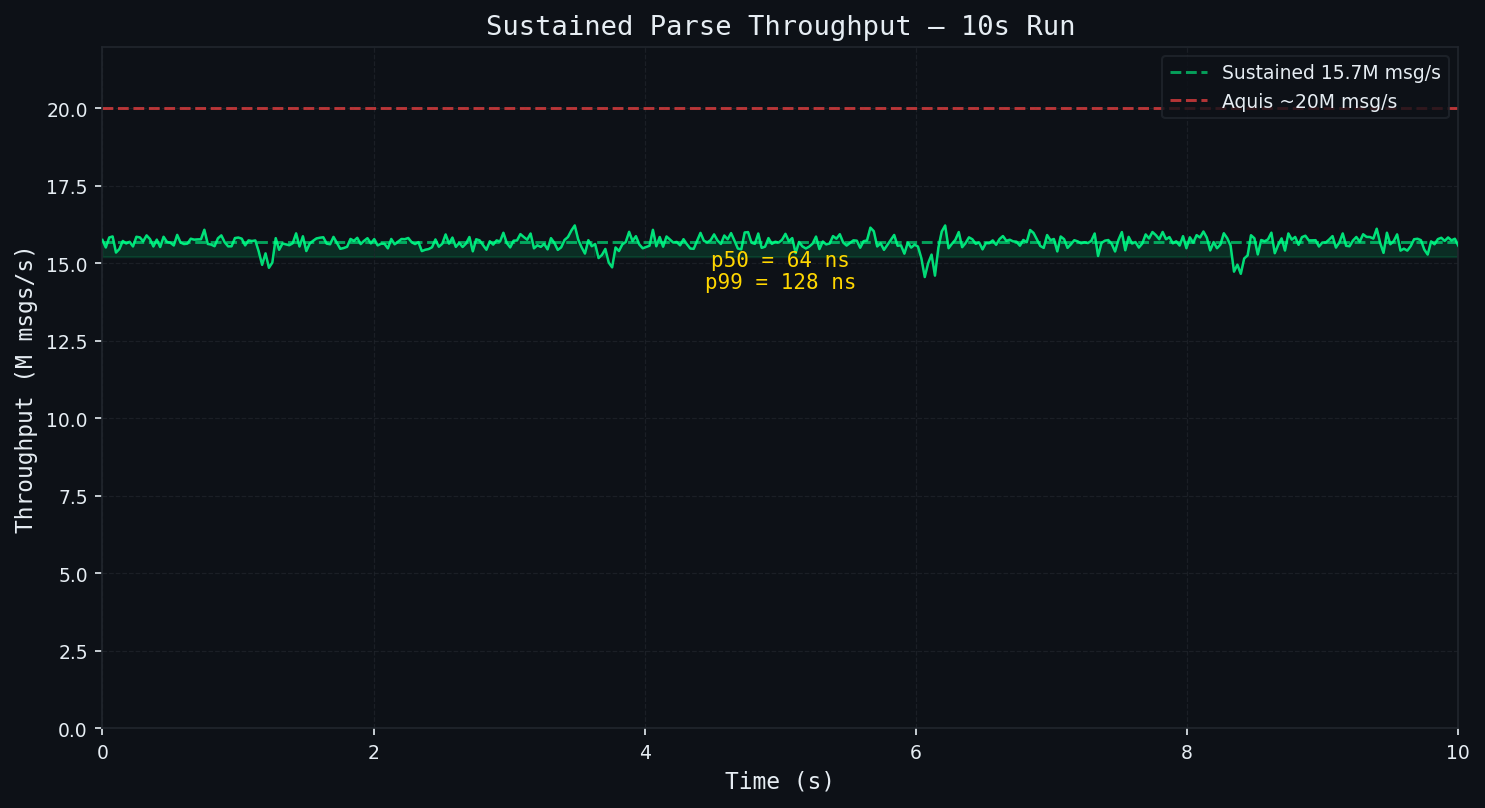
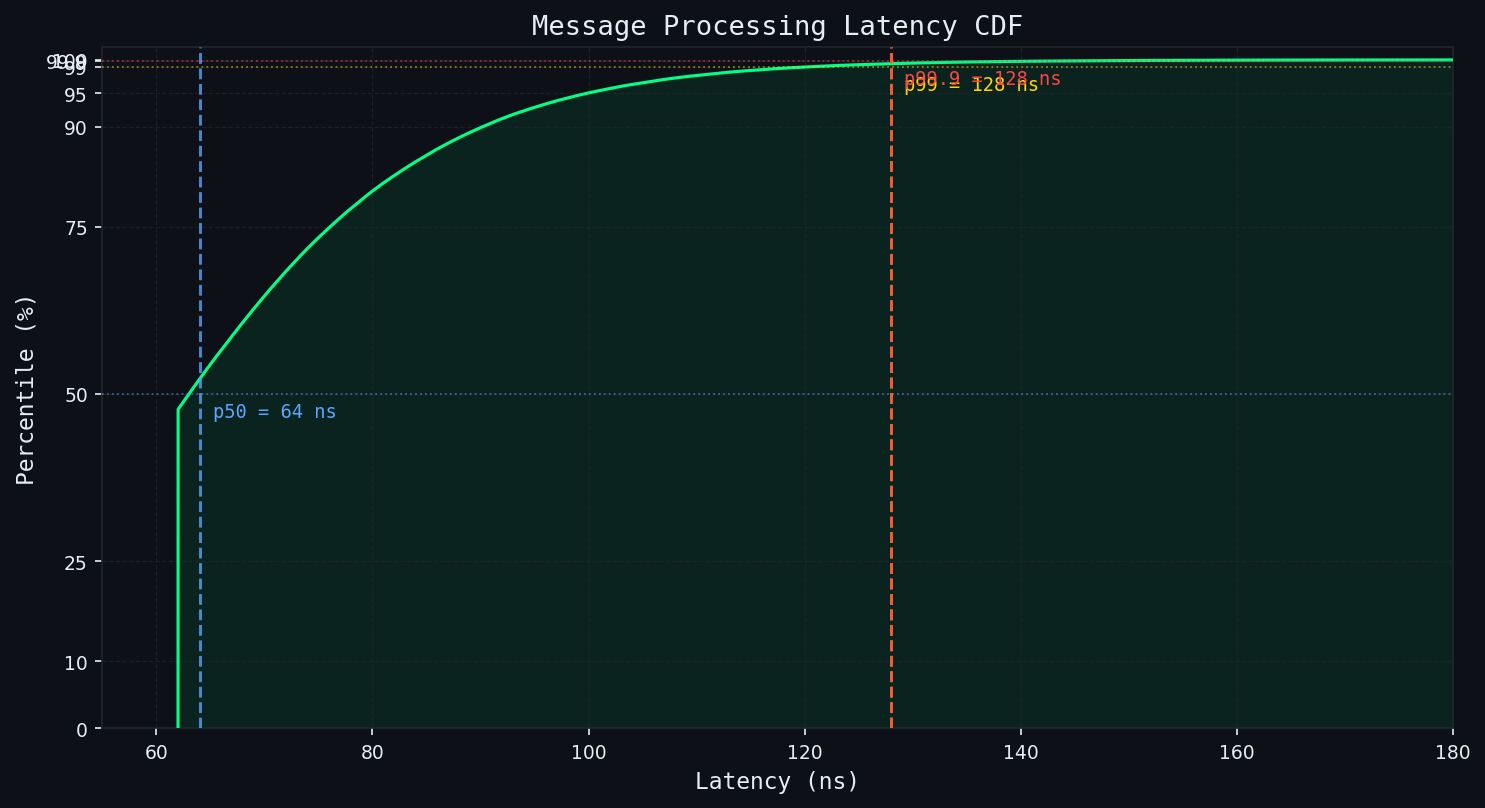
| Sustained Throughput | p50=64 ns, p99=128 ns | 15.7M msg/s | — |
Measured on 24-core 4954 MHz server, Ubuntu 22.04, GCC -O3 -march=native. Aquis Exchange reference from public documentation (800 ns/message end-to-end).
  NASDAQ UDP Feed
        │
        ▼
  AF_XDP UMEM (zero-copy DMA → userspace ring)
        │  kUmemFrames × 2048 B pre-registered
        ▼
  XDP BPF Filter (UDP dst-port → XDP_REDIRECT)
        │
        ▼
  XdpSocket::recv_batch()  /  recvmmsg fallback
        │  (data*, len, hw_ts_ns)
        ▼
  ITCH 5.0 Parser
  ┌─────────────────────────────────────────────────────┐
  │  constexpr dispatch[256] fn-ptr table               │
  │  All 23 message types: A F E C X D U P Q B I N O … │
  │  Byte-order: __builtin_bswap + memcpy (no UB)       │
  └──────────────┬──────────────────────┬───────────────┘
                 │                      │
                 ▼                      ▼
   OrderBook[stock_locate]       SPSC Ring Buffer
   ┌────────────────────┐        ┌────────────────────┐
   │ Flat sorted levels │        │ SpscRing<BookEvent,│
   │ Open-addr hash map │        │         65536>     │
   │ AVX2 SIMD search   │        │ 64-byte aligned    │
   │ Atomic BBO cache   │        │ zero-heap alloc    │
   └────────────────────┘        └─────────┬──────────┘
                                           │
                                           ▼
                                    Strategy Thread
                                    ring.pop() → act on BBO changes
O(1) dispatch via constexpr table: A constexpr std::array<fn*, 256> indexed by ITCH message-type byte eliminates branch mispredictions on the hot path — no switch chains, no virtual dispatch overhead.
AVX2 SIMD level search: Price levels stored as parallel uint64_t arrays; a 4-wide 256-bit comparison finds the matching price in a single _mm256_cmpeq_epi64 pass, cutting level-search cycles by ~4×.
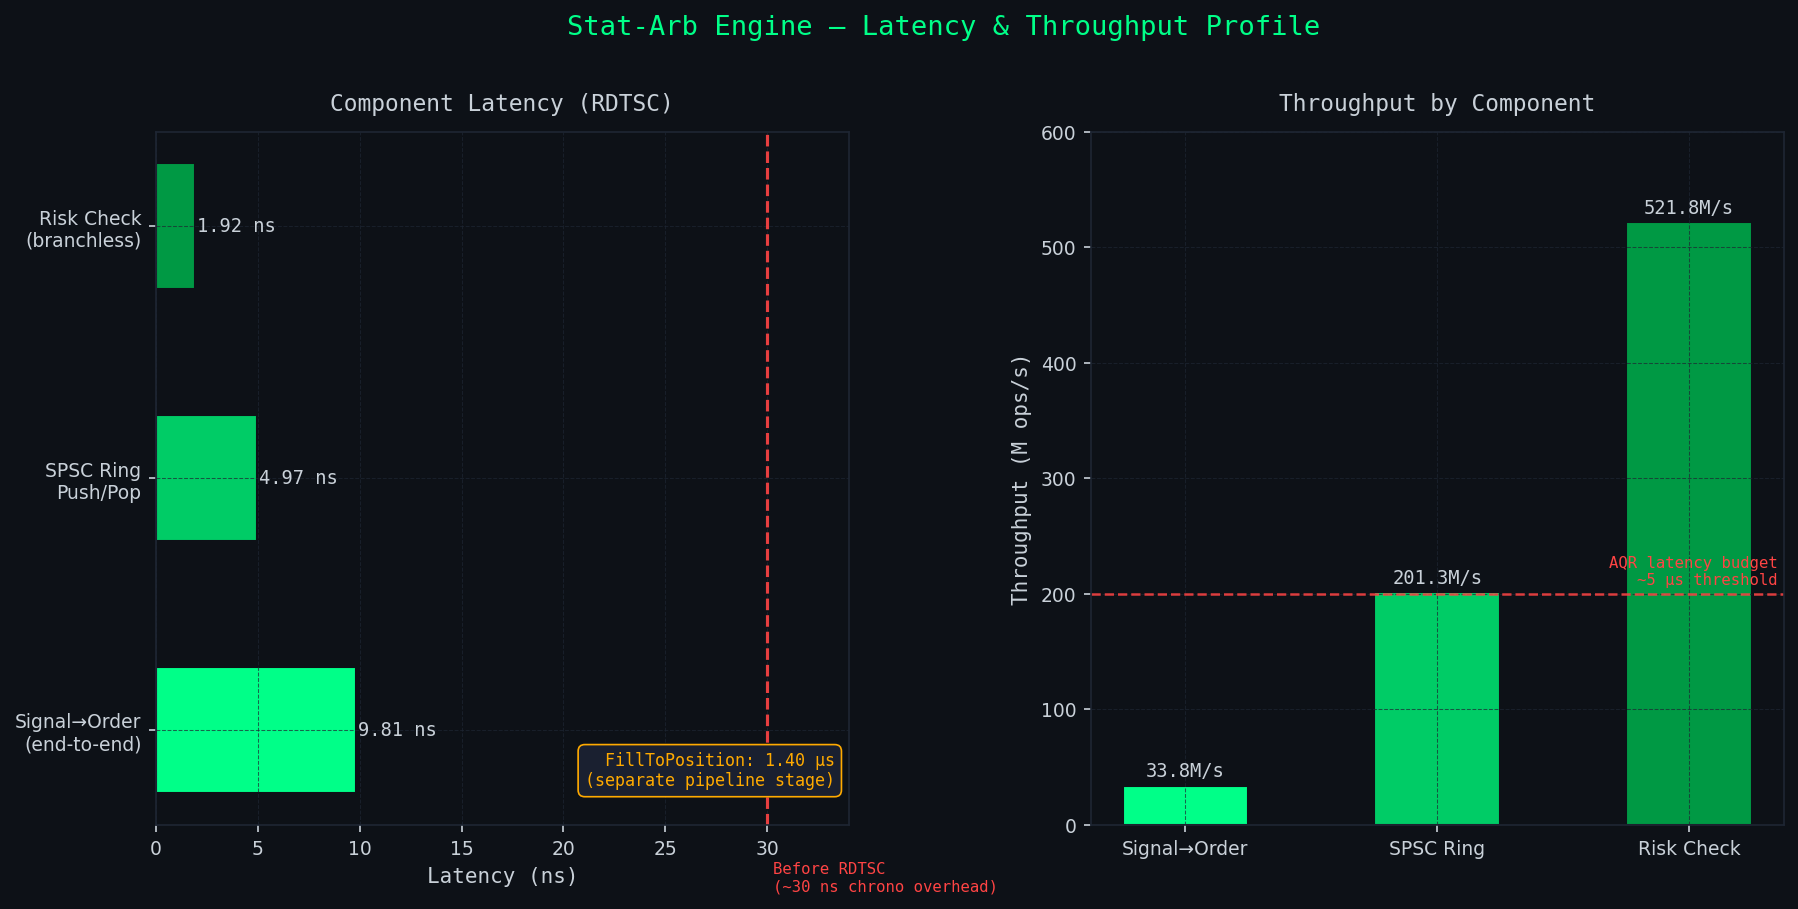
Lock-free SPSC ring with cached-head optimization: The producer caches the consumer's head pointer to avoid cross-core false sharing; push/pop round-trip measured at 4.97 ns. Ring is stack-allocated at startup — zero heap on the hot path.
Open-addressed hash map at ≤ 0.5 load factor: Order reference → level index lookup uses quadratic probing with a power-of-two capacity capped at 50% occupancy, giving expected O(1) with minimal cache-line traversal even under high insert/delete churn.
Atomic BBO cache with relaxed stores + release fence: Bid/ask price and quantity are written with memory_order_relaxed during the update then flushed with a single memory_order_release timestamp store, allowing the strategy thread to detect stale reads with a single acquire load rather than a full mutex.
cmake -B build -DCMAKE_BUILD_TYPE=Release -DCMAKE_CXX_FLAGS="-march=native"
cmake --build build -j$(nproc)
./build/bm_itch
cmake -B build -DCMAKE_BUILD_TYPE=Release -DENABLE_XDP=ON \
      -DCMAKE_CXX_FLAGS="-march=native"
cmake --build build -j$(nproc)
# Full suite
./build/bm_itch

# Sustained throughput (10-second run with latency histogram)
./build/bm_itch --benchmark_filter=BM_SustainedThroughput --benchmark_min_time=10s

# JSON output for CI comparison
./build/bm_itch --benchmark_out=bm_results.json --benchmark_out_format=json
python3 tools/gen_graphs.py
# Outputs: docs/img/latency_breakdown.png, throughput_profile.png, latency_cdf.png
-DENABLE_XDP=ON)CPU: 24× 4954 MHz cores
L1d: 32 KiB per core
L2: 512 KiB per core pair
L3: 32 MiB per NUMA node
OS: Linux, Ubuntu 22.04
__builtin_bswap decode with no UB.sfeirc/ITCH-feed-handler is a public repo on GitHub by sfeirc. Ultra-low-latency NASDAQ ITCH 5.0 feed handler — 97 ns book update, AF_XDP/recvmmsg, SIMD order-map probing, lock-free BBO cache.
It declares the MIT license on GitHub.
Its maker has not tagged a system, so it is unknown here. Its README says what it needs.
Open "Take it" on its page: Take My Repo writes an install plan for your machine and hands it to your AI agent (Claude Code, Codex or Cursor), which asks you before each step. Take My Repo has not tested it on any machine.
Its last change on GitHub was on 2026-08-17. Take My Repo does not judge from that whether it is maintained.
Nobody has reviewed it on Take My Repo yet, which says nothing about its quality.
🦊 Low-latency P2P mesh VPN in Rust. Reed–Solomon FEC loss immunity, Post-Quantum, 40 Gbps AF_XDP, multi-core scaling, NAT traversal, decentralized CA, self-certifying routing, DAITA, and anti-DPI TLS mimicry.
Reverse engineer anything with agents, from app behavior down to native binaries.
Open-source Rust framework for building event-driven live-trading & backtesting systems
SRS is a simple, high-performance, AI-driven real-time media server supporting RTMP, WebRTC, HLS, HTTP-FLV, HTTP-TS, SRT, MPEG-DASH, and GB28181, with codec support for H.264, H.265, AV1, VP9, AAC, Opus, and G.711.
5-min directional forecast from LOB microstructure — AUROC 0.916, 84% accuracy, walk-forward CV, XGBoost/Transformer ensemble, fees & slippage modeled
High-performance C++ limit order book matching engine — 2.3M msg/s, sub-μs P50 latency, O(1) cancel, zero hot-path allocations, intrusive lists
Dent ta Maison: mobile + backend app for rapid dental self-check via guided photo capture and cavity pre-screening
Statistical arbitrage engine — C++ signal pipeline, Python walk-forward backtesting, Streamlit P&L dashboard
MRV toolkit for a CO2 injection well: Peng-Robinson EOS density, mass-balance with Monte Carlo uncertainty, CUSUM leak/anomaly detection
Incident Lens: OpenTelemetry incident lab turning correlated metrics/logs/traces/deployments into ranked, evidence-citing failure hypotheses