16bit


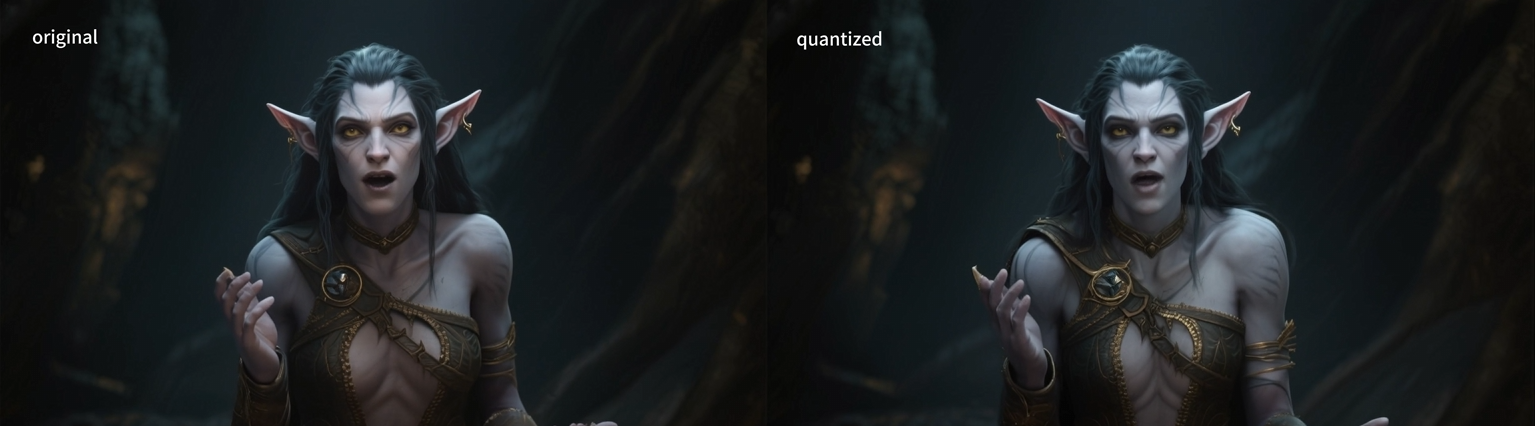
Wan2.2-Animate-14B-Quant-Compression
Mixed-precision quantization scheme (16/8/4bit mixed quantization) for the Wan2.2-Animate-14B model. Compresses the original 35GB base model to 17GB, balancing inference performance and model size.
- 3
- Python
- 11 mo ago

Meta-Llama-3-70B-Instruct-abliterated-v3.5-IMat-GGUF
Text generation model, used with gguf.
- 2
- 5.3k
- llama3
- 2 y ago
StagAI-CyberSecurity-26B-A4B-v2-VLM-GGUF-BF16
Image text to text model, used with gguf.
- 0
- 814
- apache-2.0
- 5 wk ago
StagAI-CyberSecurity-26B-A4B-v2-VLM-MLX-BF16
Image text to text model, used with mlx.
- 0
- 169
- apache-2.0
- 5 wk ago
Phi-3-mini-4k-instruct-update2024_07_03-IMat-GGUF
Text generation model, used with gguf.
- 0
- 6.5k
- mit
- 2 y ago