qwen38-27b-flash-mtp
Own your tokens: Qwen3.8-27B-Flash-MTP - a 27B ternary model on an 8 GB laptop GPU at 70 t/s. Launchers, features.ini and a chat client. Binaries on Releases, weights on Hugging Face.
- 8
- C++
- Apache-2.0
- 3 wk ago
Own your tokens: Qwen3.8-27B-Flash-MTP - a 27B ternary model on an 8 GB laptop GPU at 70 t/s. Launchers, features.ini and a chat client. Binaries on Releases, weights on Hugging Face.
Chinese-calibrated Gemma-4-26B RP on 8GB - three-tier ubatch recipe (64K/118K/128K), NO_PINNED, measured PP/TG
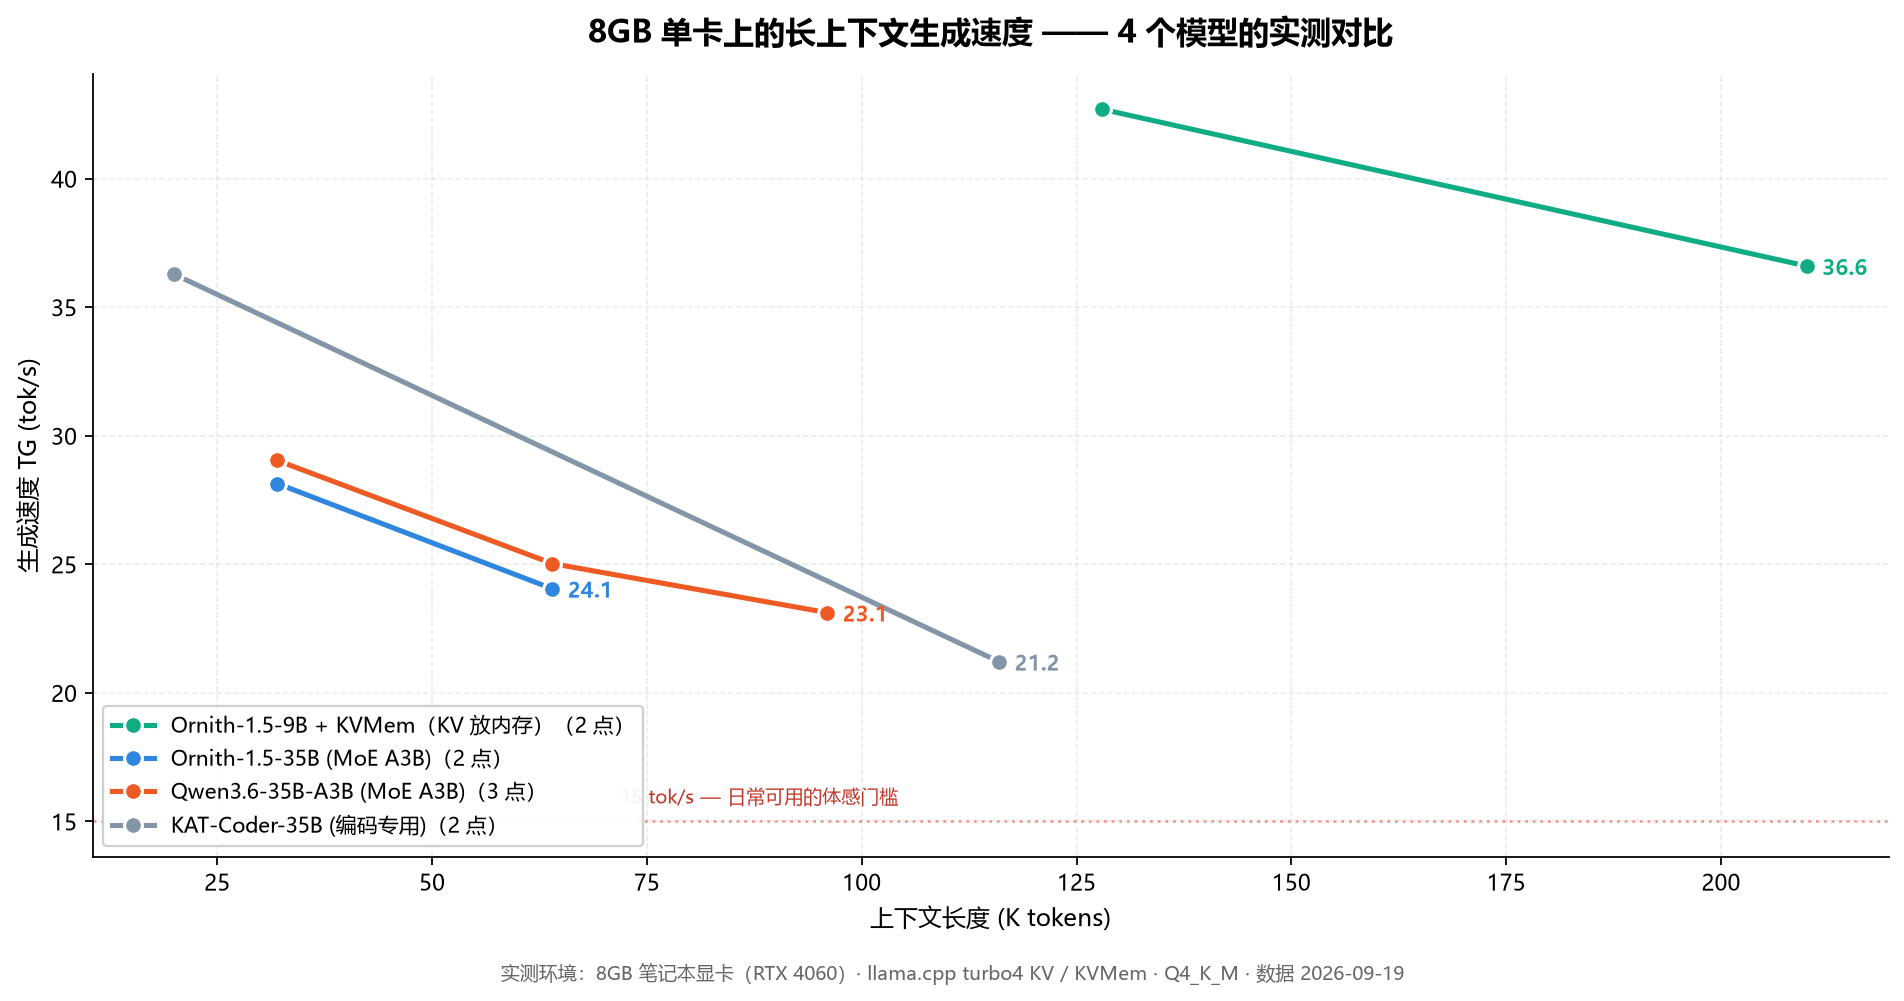
KAT-Coder-V2.5-Dev 35B on 8GB - depth curves to 124K (PP 850), thinking governance flags, multi-round tool-loop fix, agentic bench
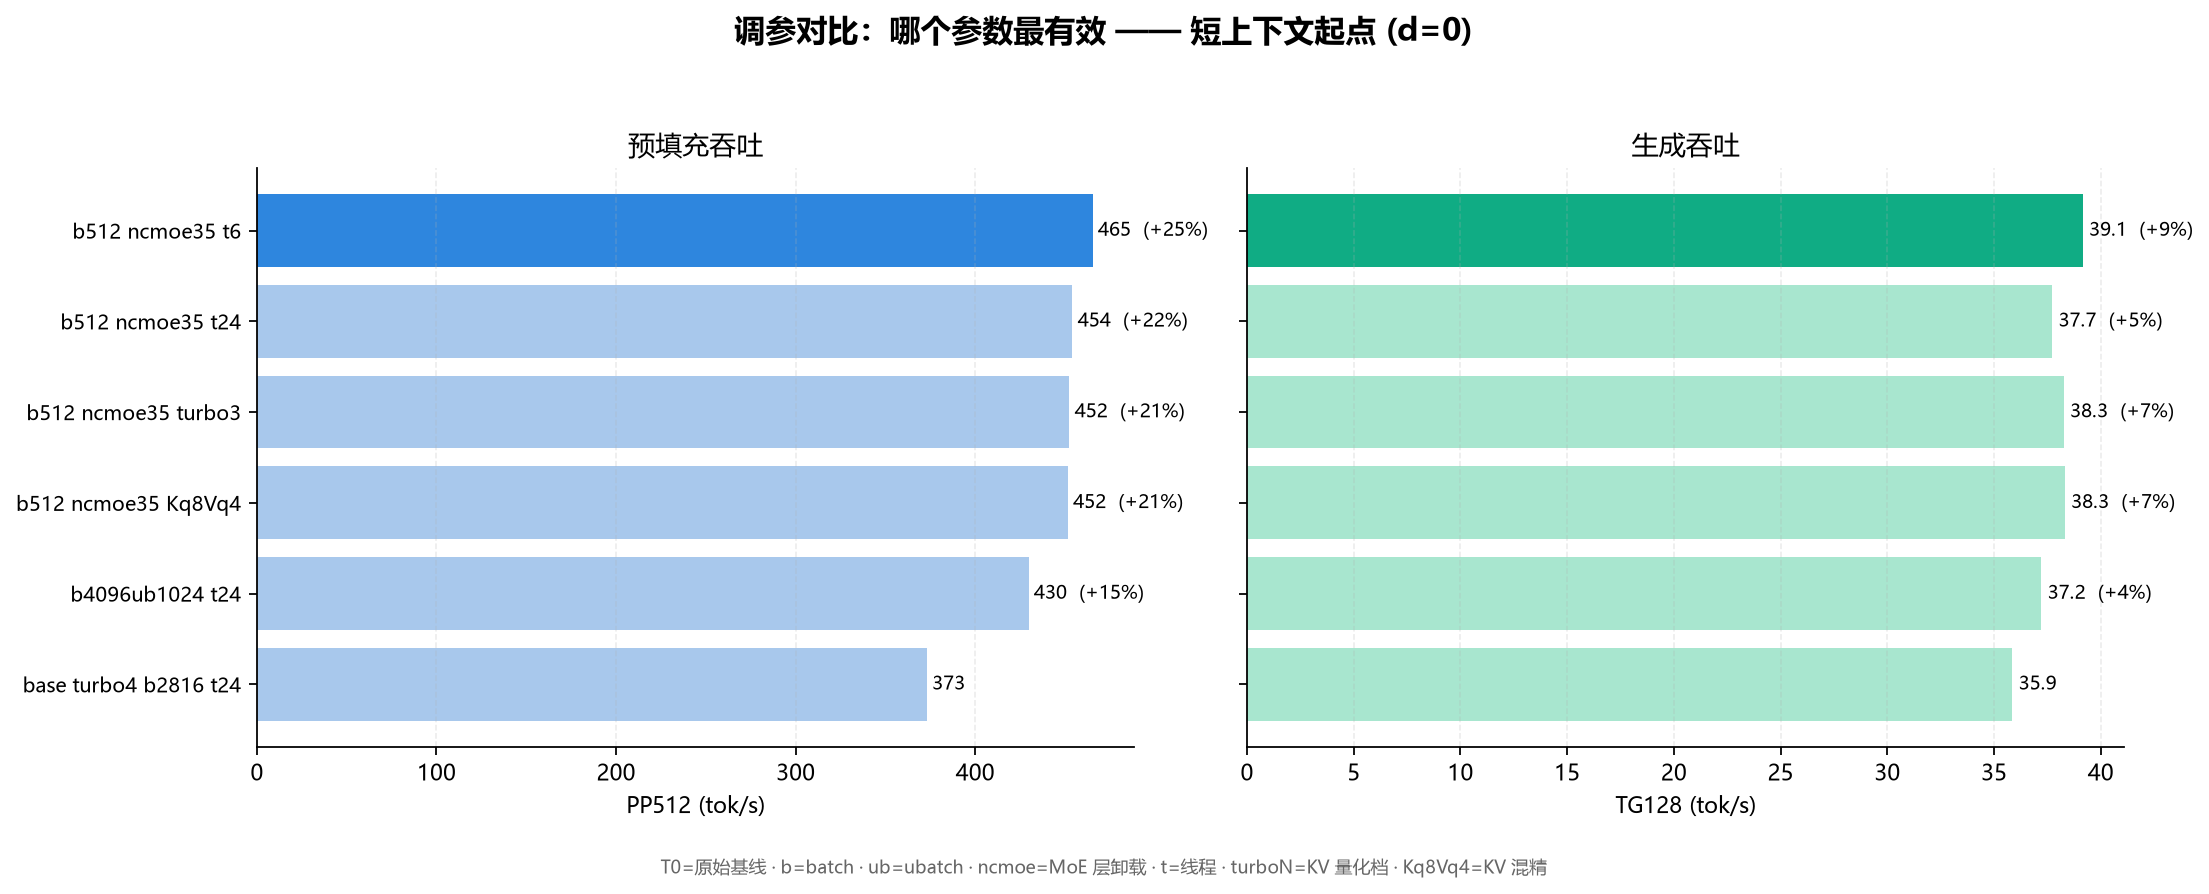
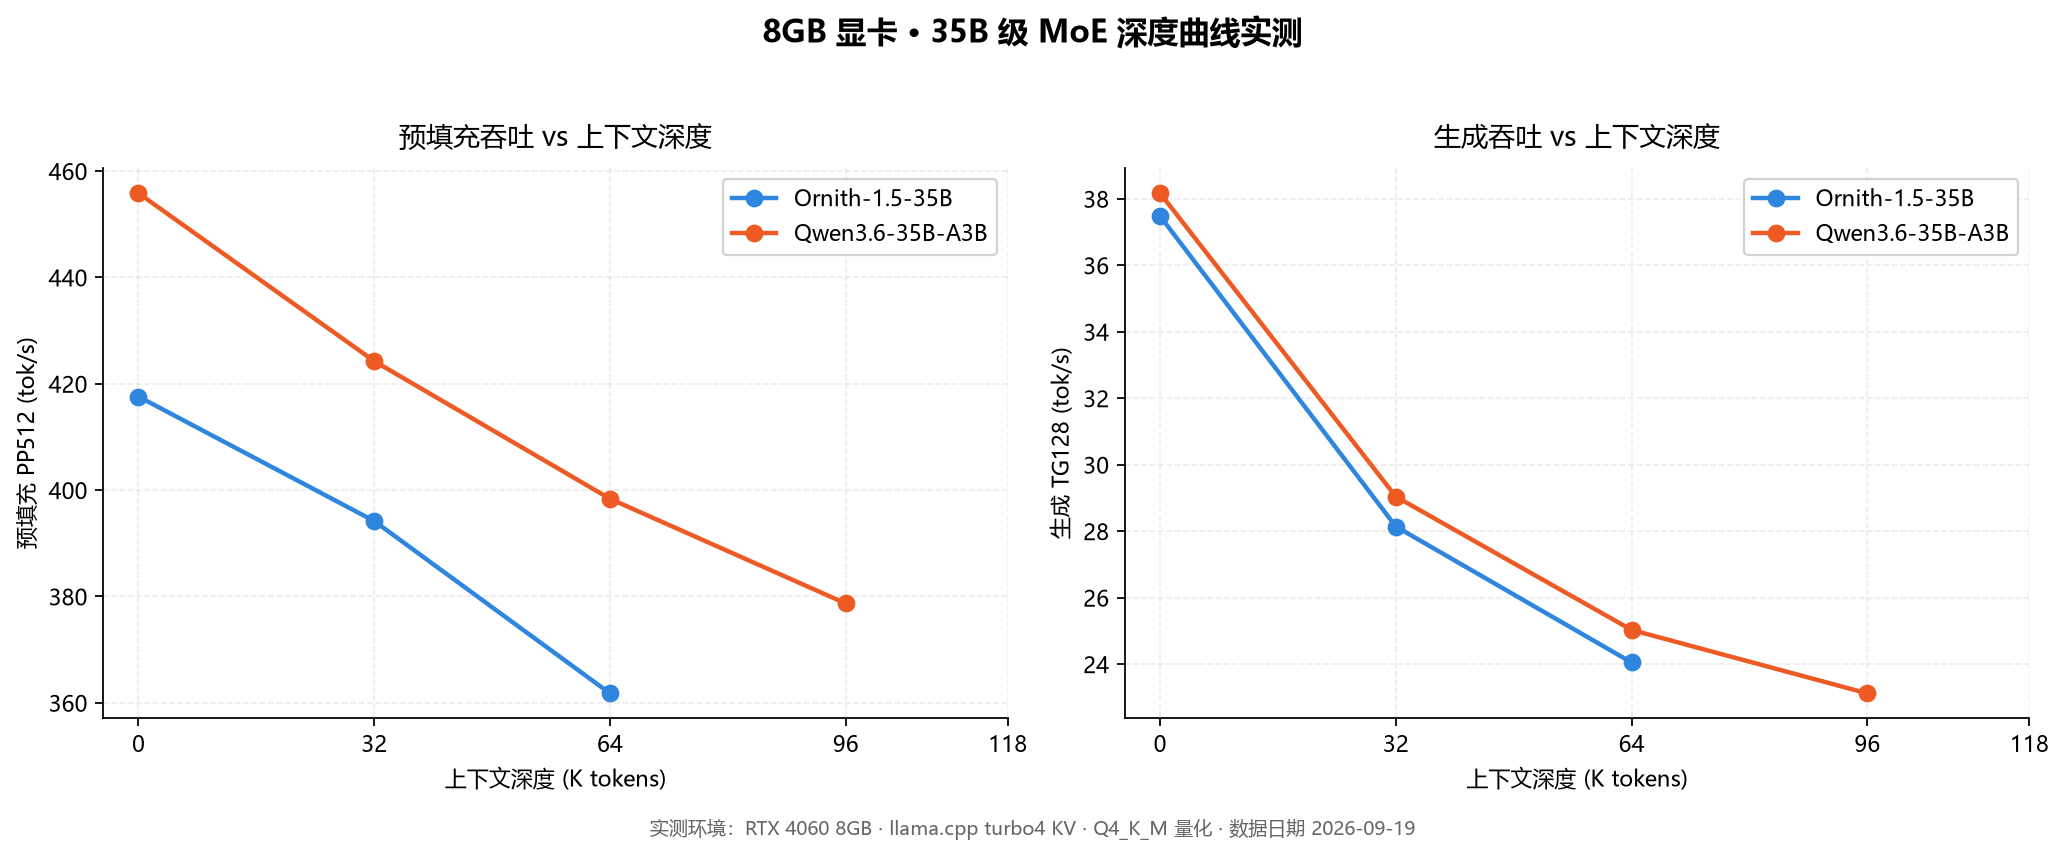
Qwen3.6-35B-A3B on 8GB - baseline production config and measured depth curves (turbo4 KV)
Ornith-1.5-35B-A3B on RTX 4060 8GB - measured depth curves (PP/TG to 118K) + turbo4 KV production config + tool-loop fix
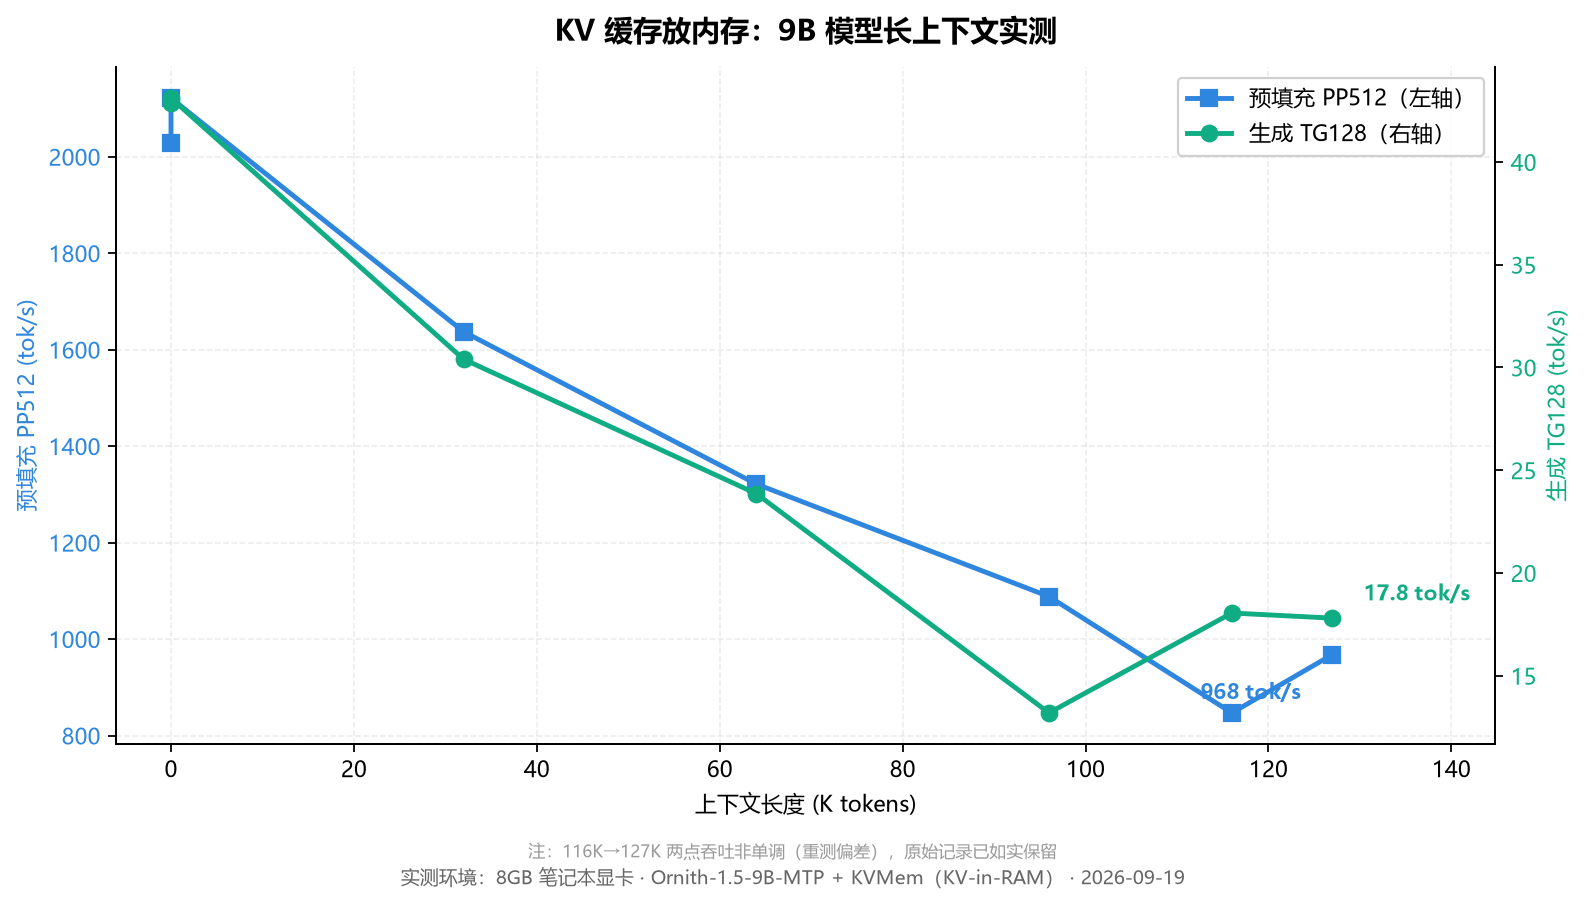
Ornith-1.5-9B-MTP + KVMem on 8GB - KV-in-RAM long context 128K@42.7 tok/s, 210K@36.6, production config and limits
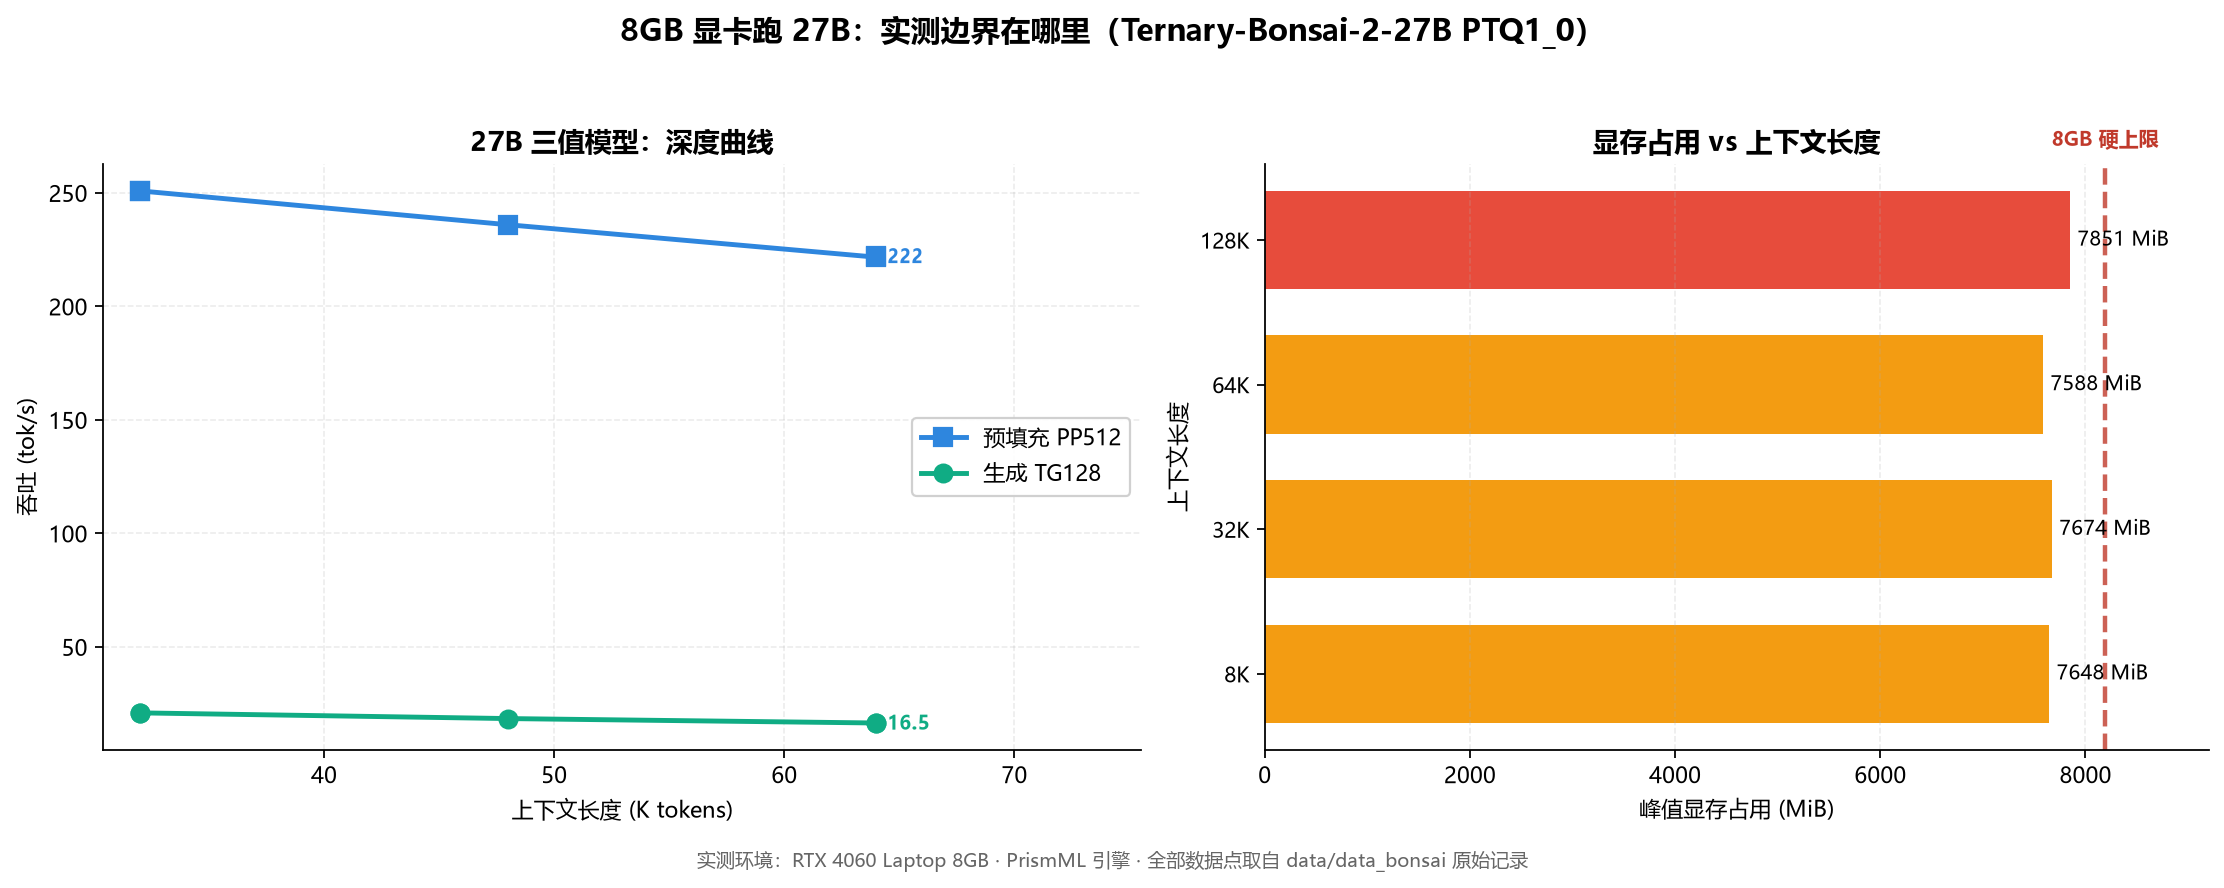
Ternary-Bonsai-2-27B (PTQ1_0 QAT) on 8GB - PrismML b10709 A/B (+15% PP/+24% TG), quality gate, production config