keras-adamw
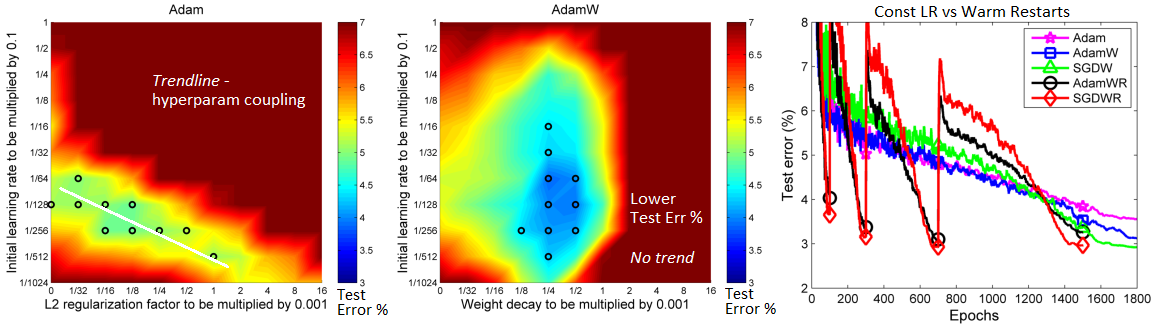
Keras/TF implementation of AdamW, SGDW, NadamW, Warm Restarts, and Learning Rate multipliers
- 168
- Python
- MIT
- 5 y ago
Keras/TF implementation of AdamW, SGDW, NadamW, Warm Restarts, and Learning Rate multipliers
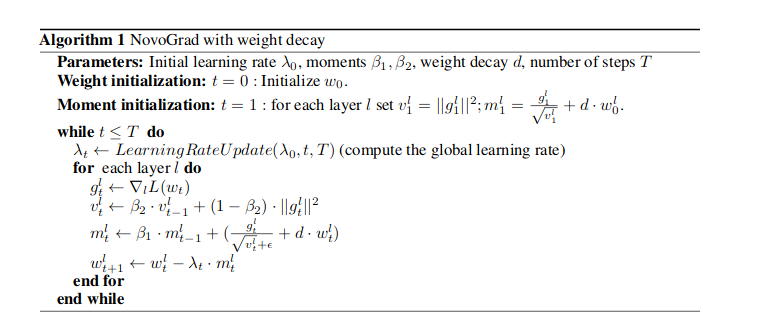
Quasi Hyperbolic Rectified DEMON Adam/Amsgrad with AdaMod, Gradient Centralization, Lookahead, iterative averaging and decorrelated Weight Decay
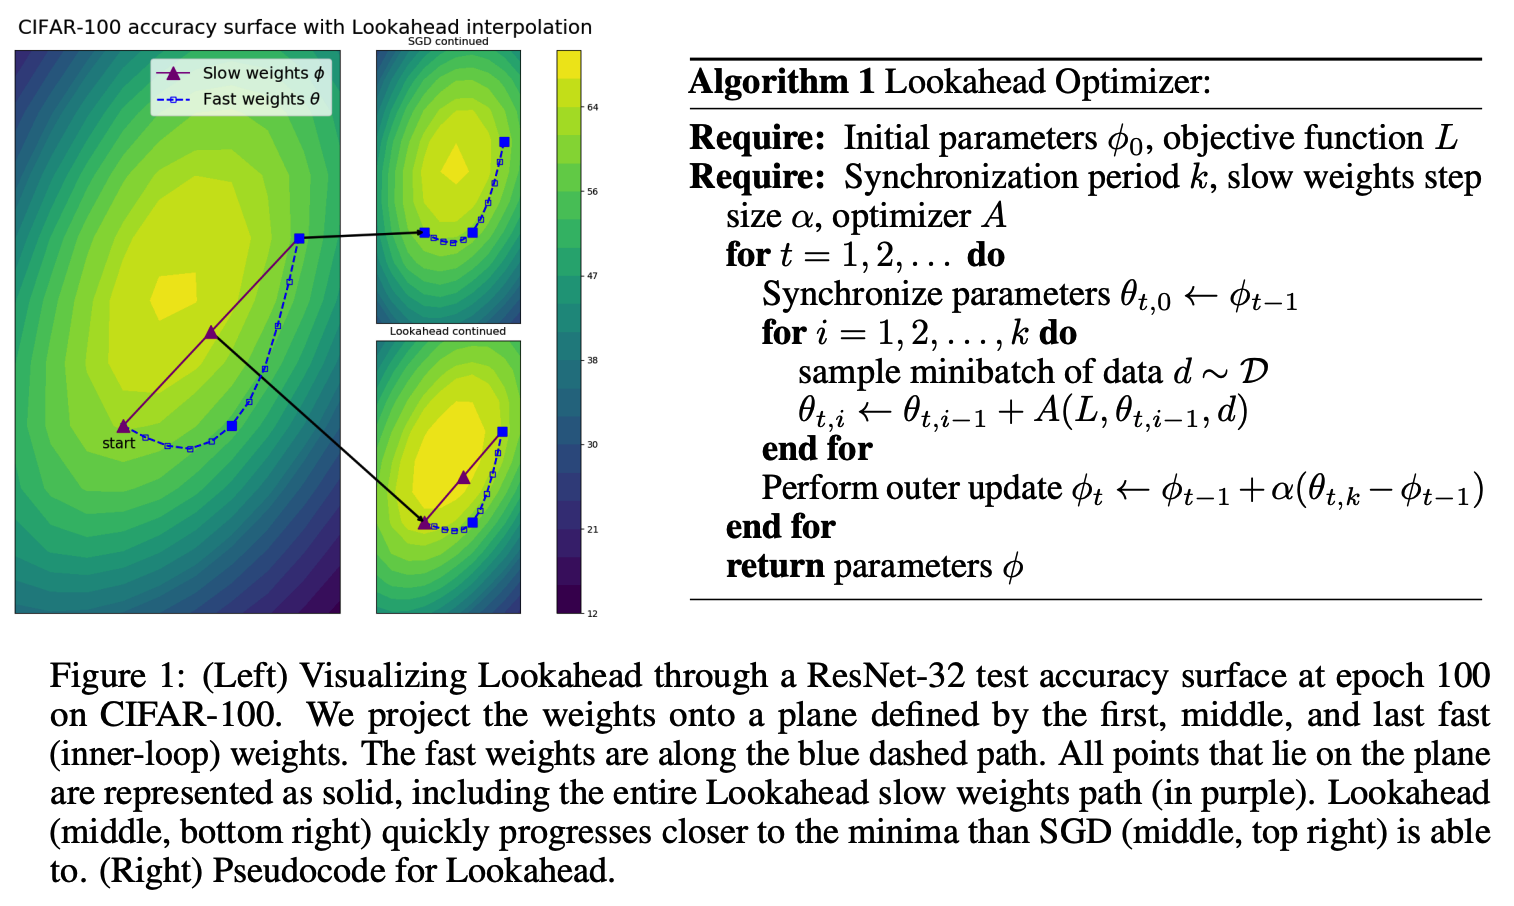
Pytorch implementation of lookahead optimizer(https://arxiv.org/pdf/1907.08610.pdf) and RAdam(https://arxiv.org/pdf/1908.03265.pdf)
Why momentum/AdamW can outperform SGD — a Tangible lesson.
Runs in the browser on Hugging Face
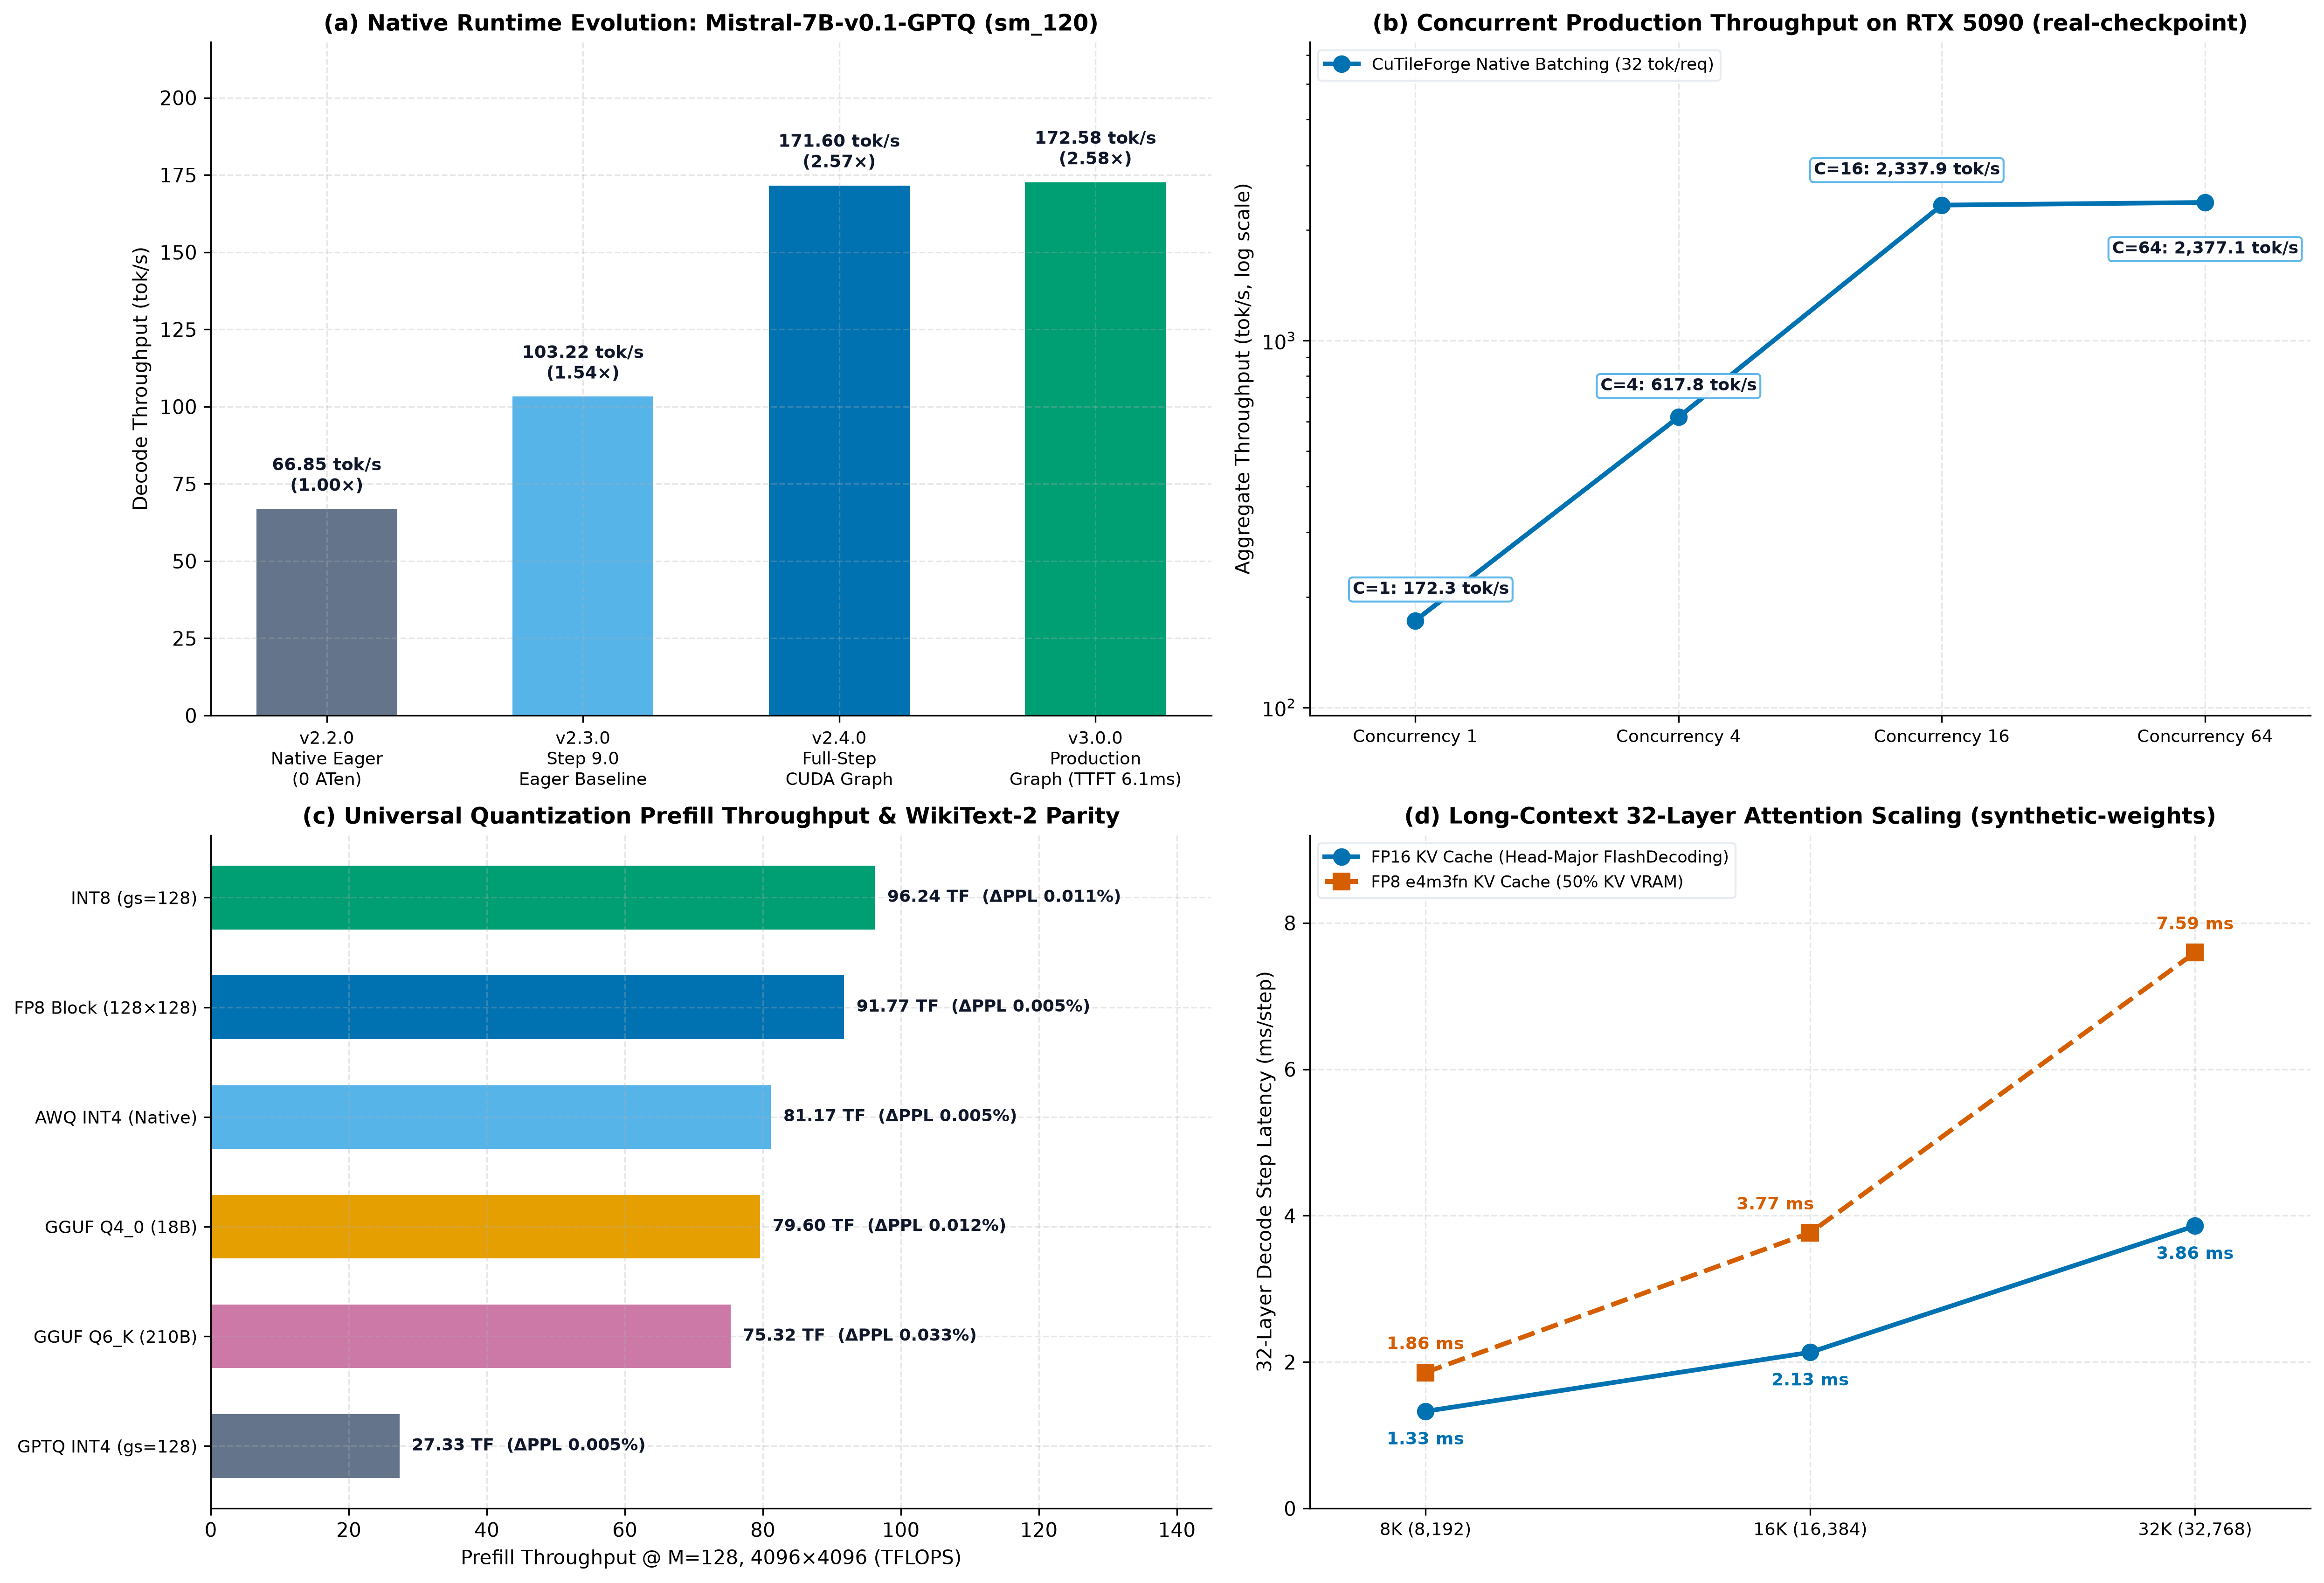
CuTileForge v3.0.0: Native tile-fusion compiler & universal quantization engine on NVIDIA CuTile. Zero-ATen CUDA-graph decode at 172 tok/s, 2,377 tok/s batch serving, 13 model families, 70B hybrid on a single 32 GB GPU (sm_89 ↔ sm_120).
reproduce Adam, AdamW, Adafactor optimizors with pytorch, and introduce popular optimizers in the training of the LLMs.
Progressive Ames house-price modeling with metric-aligned MLPs, feature engineering, CatBoost, and a TabPFN-dominant ensemble.
Matched loss and gradient covariance, different adaptive-optimizer errors: proofs, exact examples, and reproducible numerical evidence
Yapay Zeka Optimizasyon Algoritmaları