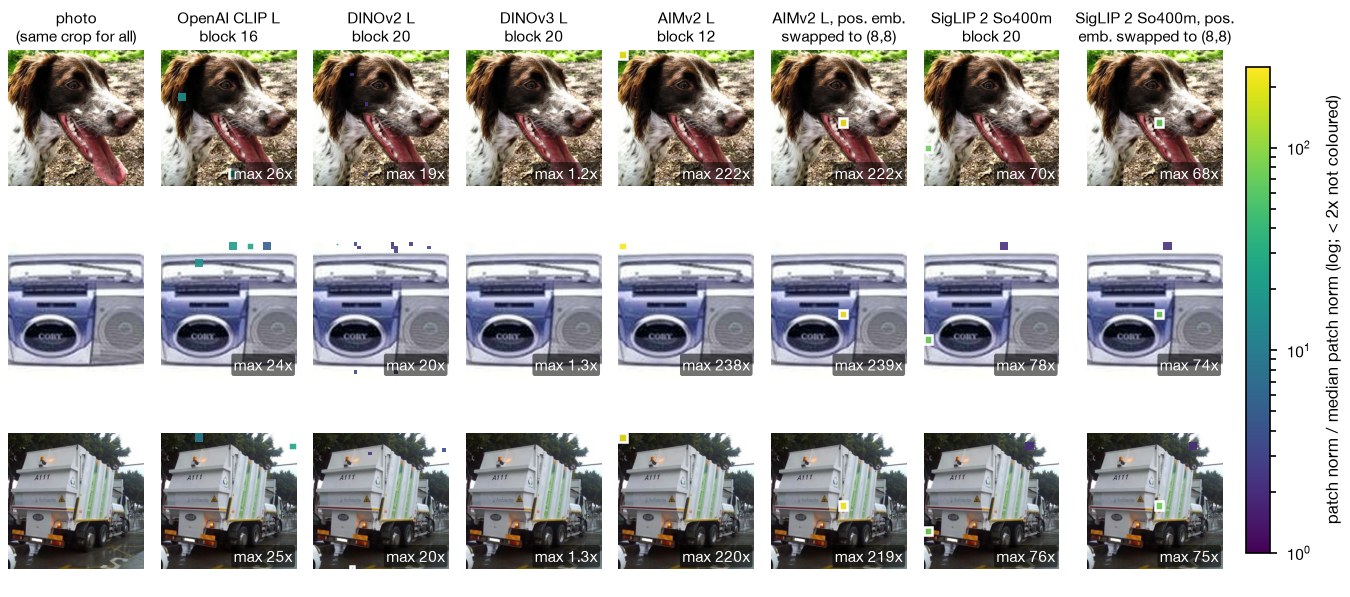
hard-coded-attention-sinks
Hard-coded attention sinks in vision encoders (AIMv2, SigLIP So400m, PaliGemma, LLaVA-OneVision): where they live, how they work, and how to move them
- 0
- Python
- MIT
- 2 wk ago
Hard-coded attention sinks in vision encoders (AIMv2, SigLIP So400m, PaliGemma, LLaVA-OneVision): where they live, how they work, and how to move them
Zero shot image classification model, used with transformers.
