Video-LLaMA
[EMNLP 2023 Demo] Video-LLaMA: An Instruction-tuned Audio-Visual Language Model for Video Understanding
- 3.1k
- Python
- BSD-3-Clause
- 2 y ago
[EMNLP 2023 Demo] Video-LLaMA: An Instruction-tuned Audio-Visual Language Model for Video Understanding
A most Frontend Collection and survey of vision-language model papers, and models GitHub repository. Continuous updates.
Caption images across your datasets with state of the art models from Hugging Face and Replicate!
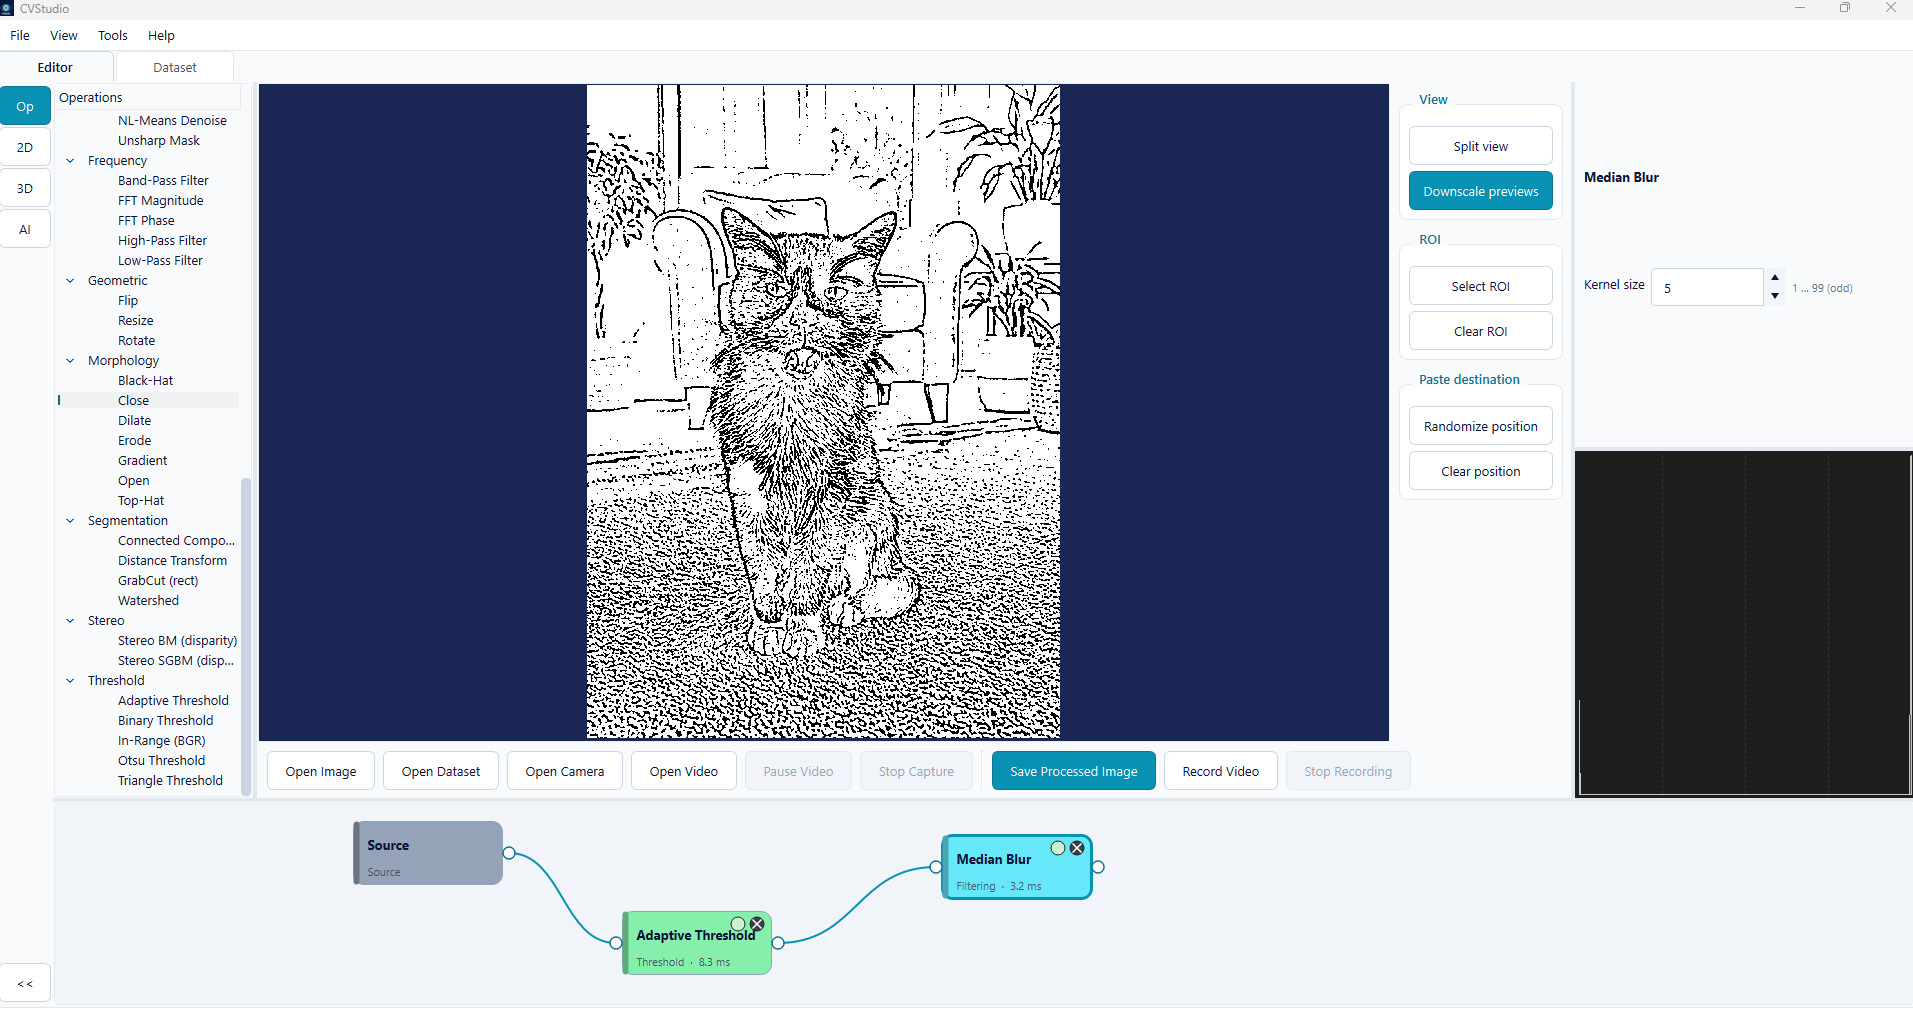
Interactive OpenCV playground — chain image processing operations with live preview.
Self-healing defense framework for Vision-Language Models that detects adversarial prompts and safely rewrites them using image context, with Flask UI and explainable audit logs.