CosyVoice
Multi-lingual large voice generation model, providing inference, training and deployment full-stack ability.
- 24k
- Python
- Apache-2.0
- 6 mo ago
Multi-lingual large voice generation model, providing inference, training and deployment full-stack ability.
A single Gradio + React WebUI with extensions for ACE-Step, OmniVoice, Kimi Audio, Piper TTS, GPT-SoVITS, CosyVoice, XTTSv2, DIA, Kokoro, OpenVoice, ParlerTTS, Stable Audio, MMS, StyleTTS2, MAGNet, AudioGen, MusicGen, Tortoise, RVC, Vocos, Demucs, SeamlessM4T, and Bark!
🍦 Speech-AI-Forge is a project developed around TTS generation model, implementing an API Server and a Gradio-based WebUI.
Cute voice assistant built on ESP32 to help users with reminders, productivity, and daily conversations.
Turn any e-book into a chaptered audiobook in your own voice: free, fully local. CosyVoice 3 or Fish Audio Drama 3 (80+ languages, several voices), no cloud needed
LightTTS is a lightweight TTS inference framework optimized for CosyVoice2 and CosyVoice3, enabling fast and scalable speech synthesis in Python and supports stream and bistream modes.
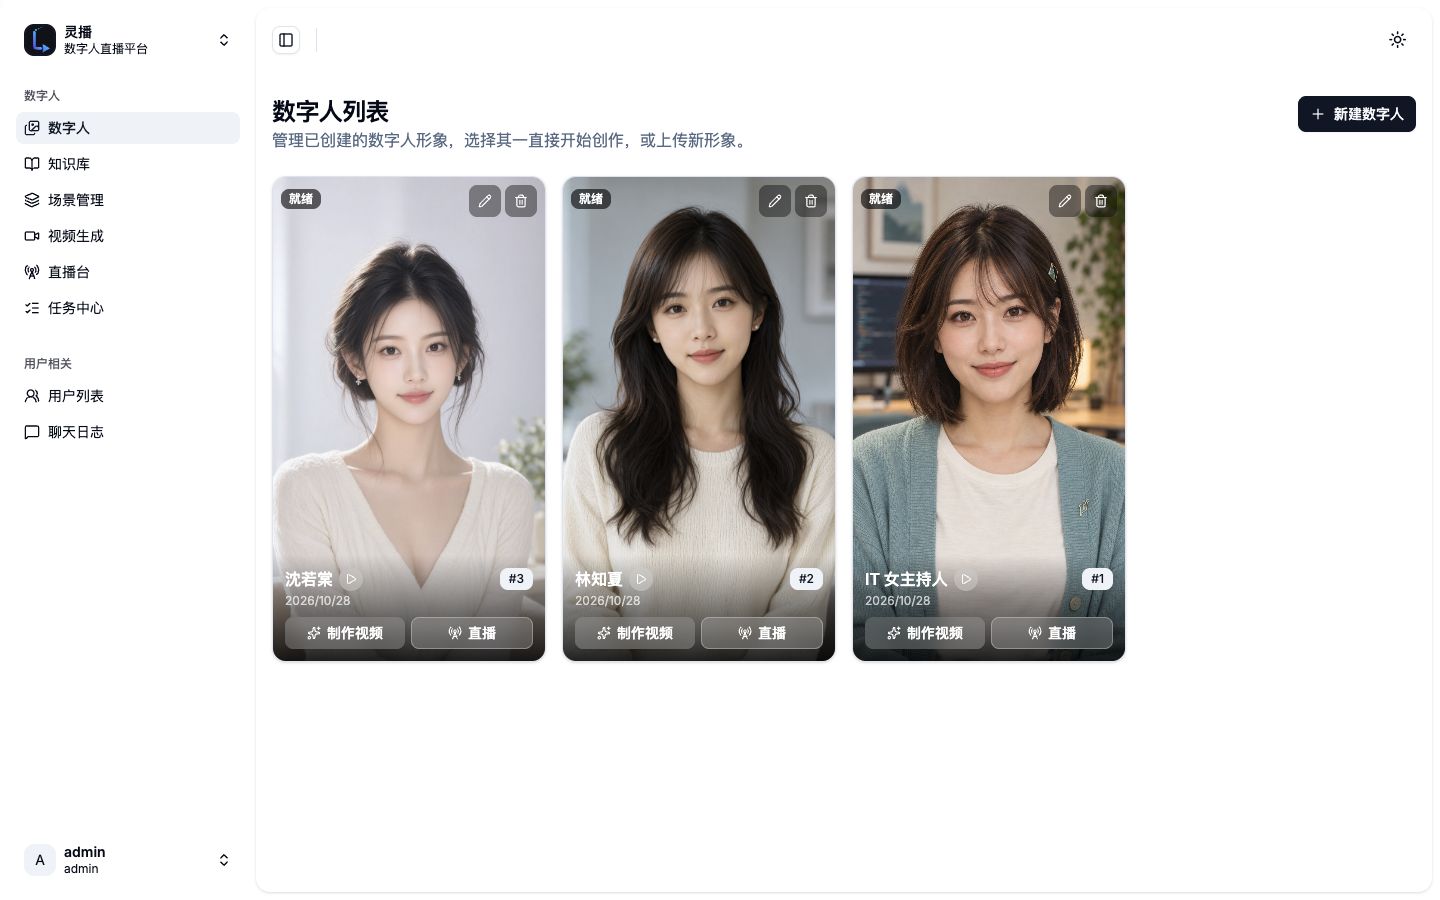
Interactive AI avatar live streaming with Qwen SSE, CosyVoice3 voice cloning and MuseTalk 1.5 lip-sync. Chrome chat collection, autonomous hosting, viewer programmes, wardrobe changes and media caching. Go/Gin, React/Next.js, Python, MariaDB, Redis, RustFS and FFmpeg/SRS.