flux
A fast communication-overlapping library for tensor/expert parallelism on GPUs.
- 1.4k
- C++
- Apache-2.0
- 15 mo ago
A fast communication-overlapping library for tensor/expert parallelism on GPUs.
🚀🚀🚀 This repository lists some awesome public CUDA, cuda-python, cuBLAS, cuDNN, CUTLASS, TensorRT, TensorRT-LLM, Triton, TVM, MLIR, PTX and High Performance Computing (HPC) projects.
CUDA编程练习项目-Hands-on CUDA kernels and performance optimization, covering GEMM, FlashAttention, Tensor Cores, CUTLASS, quantization, KV cache, NCCL, and profiling.
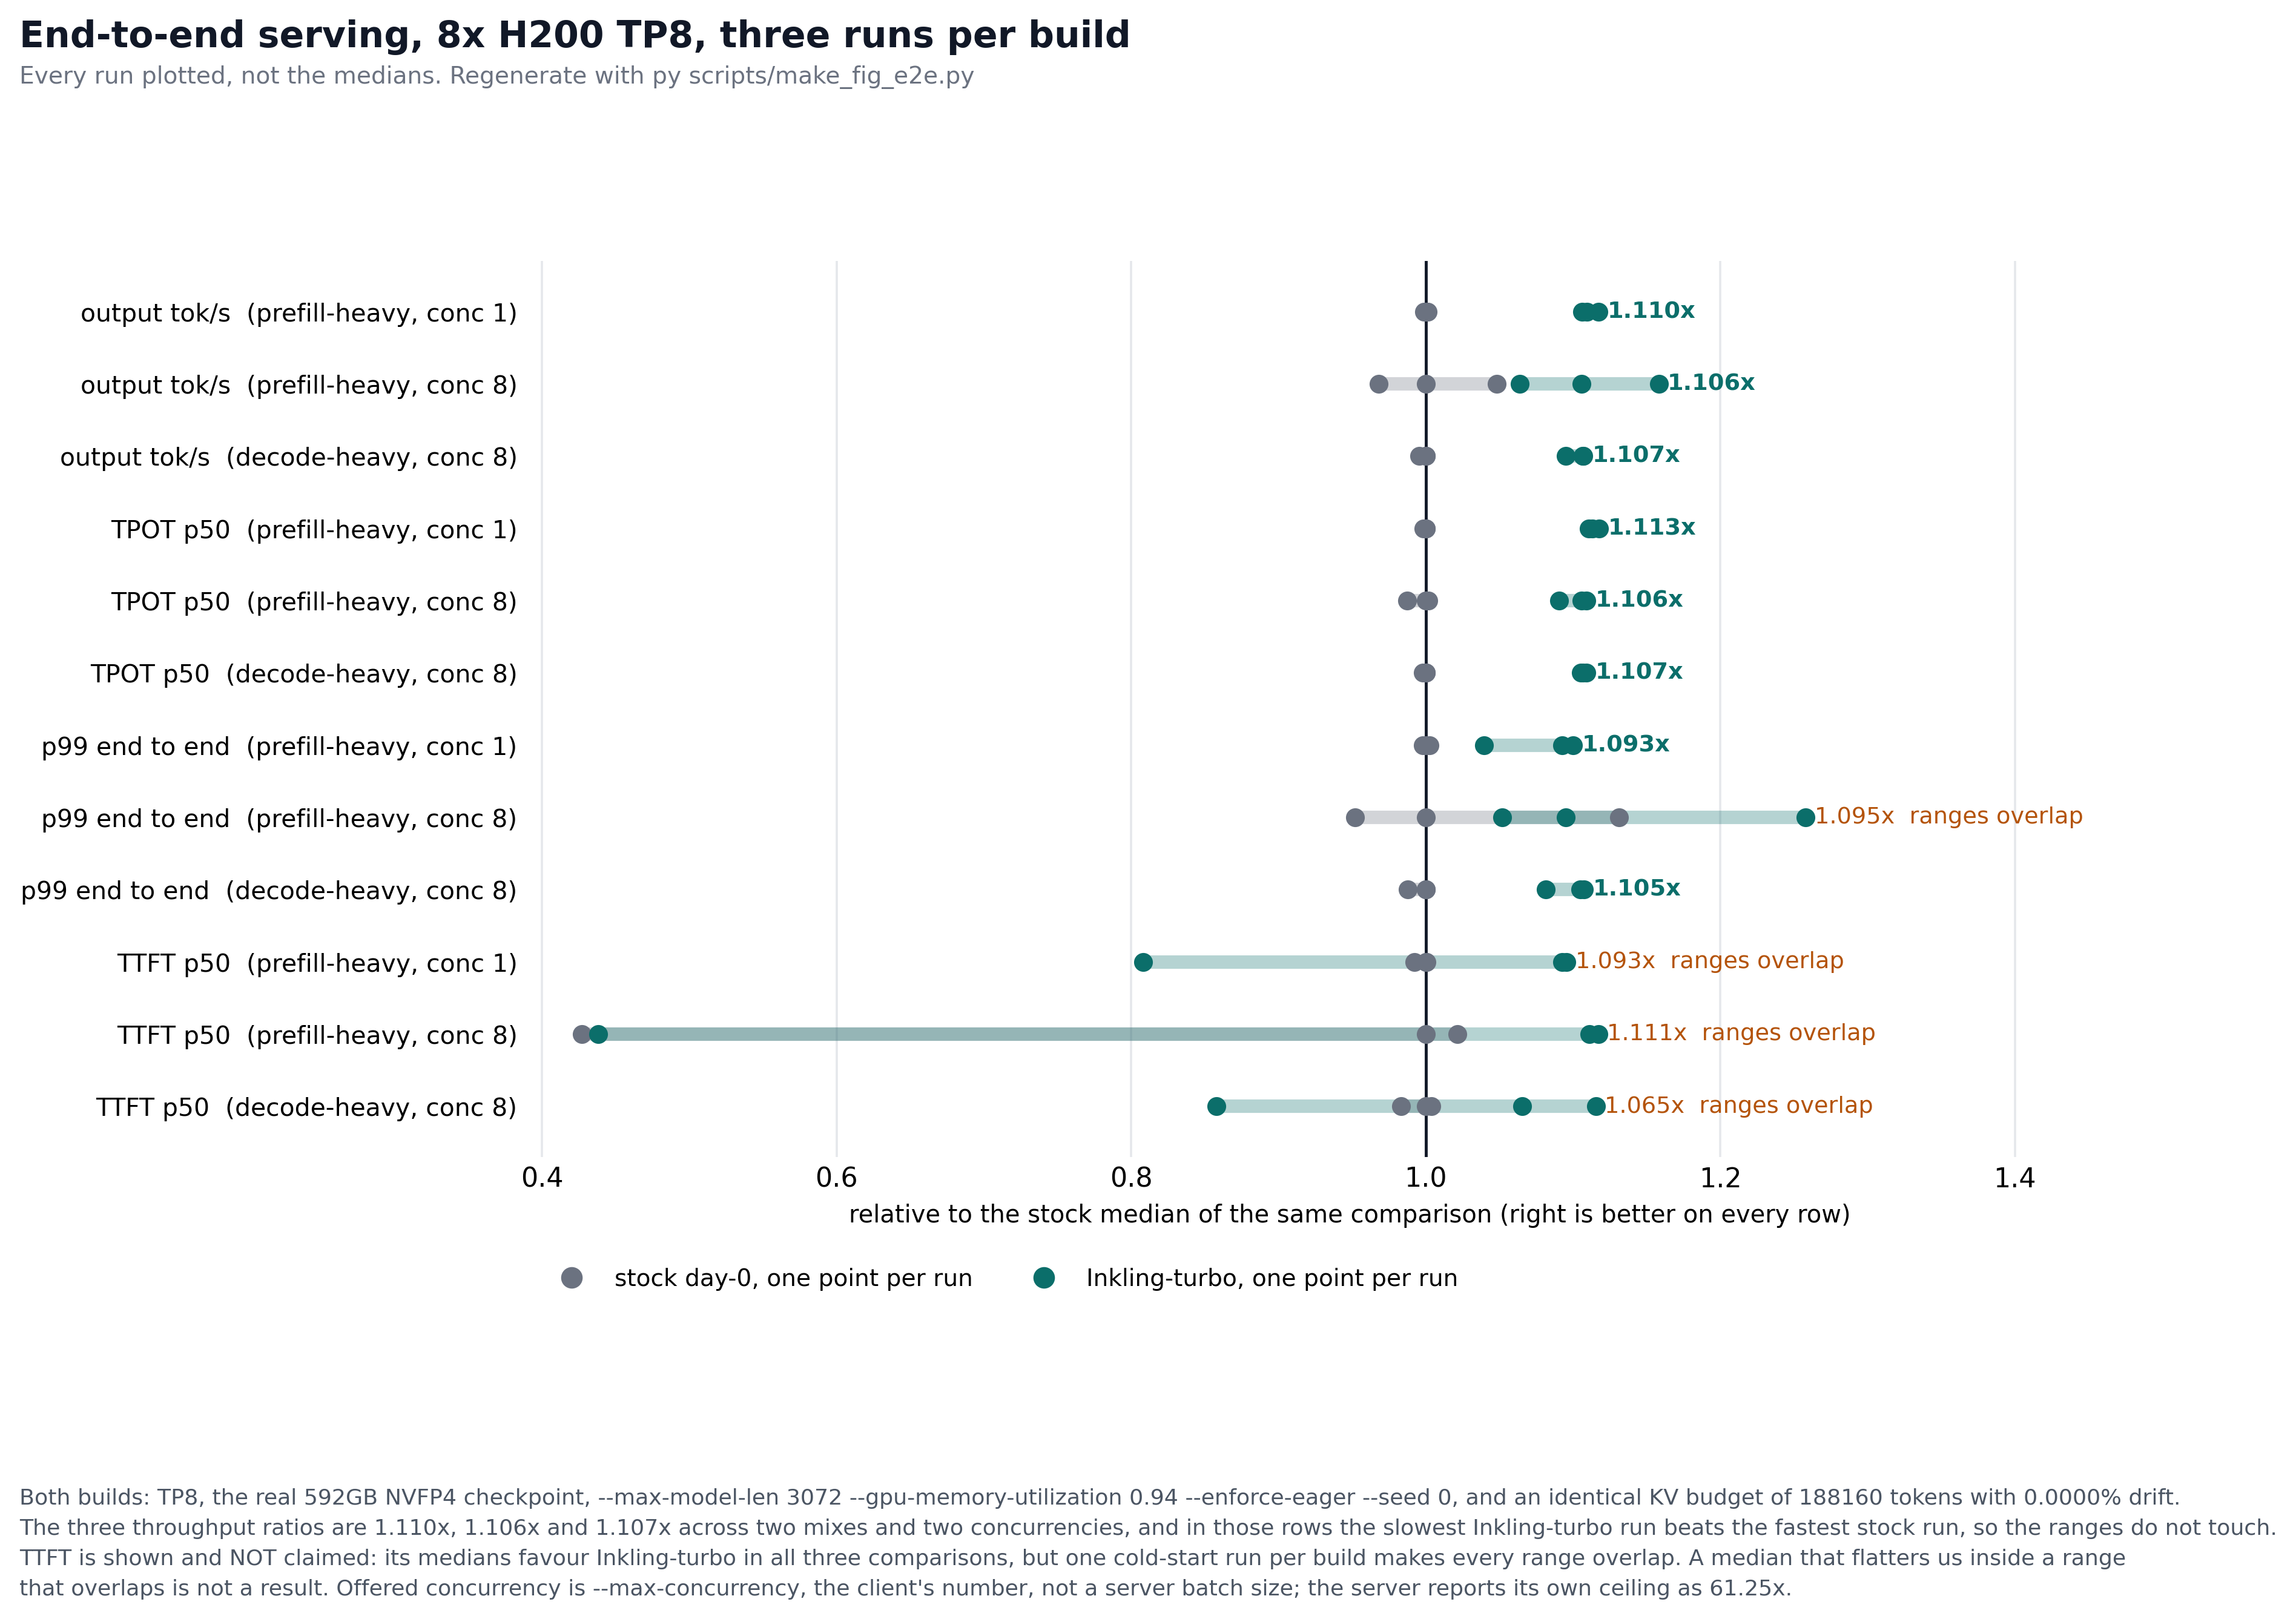
Faster attention kernels for serving TML's Inkling model on vLLM. 2.7x over the shipping path on H100, and the only implementation that runs on A100.
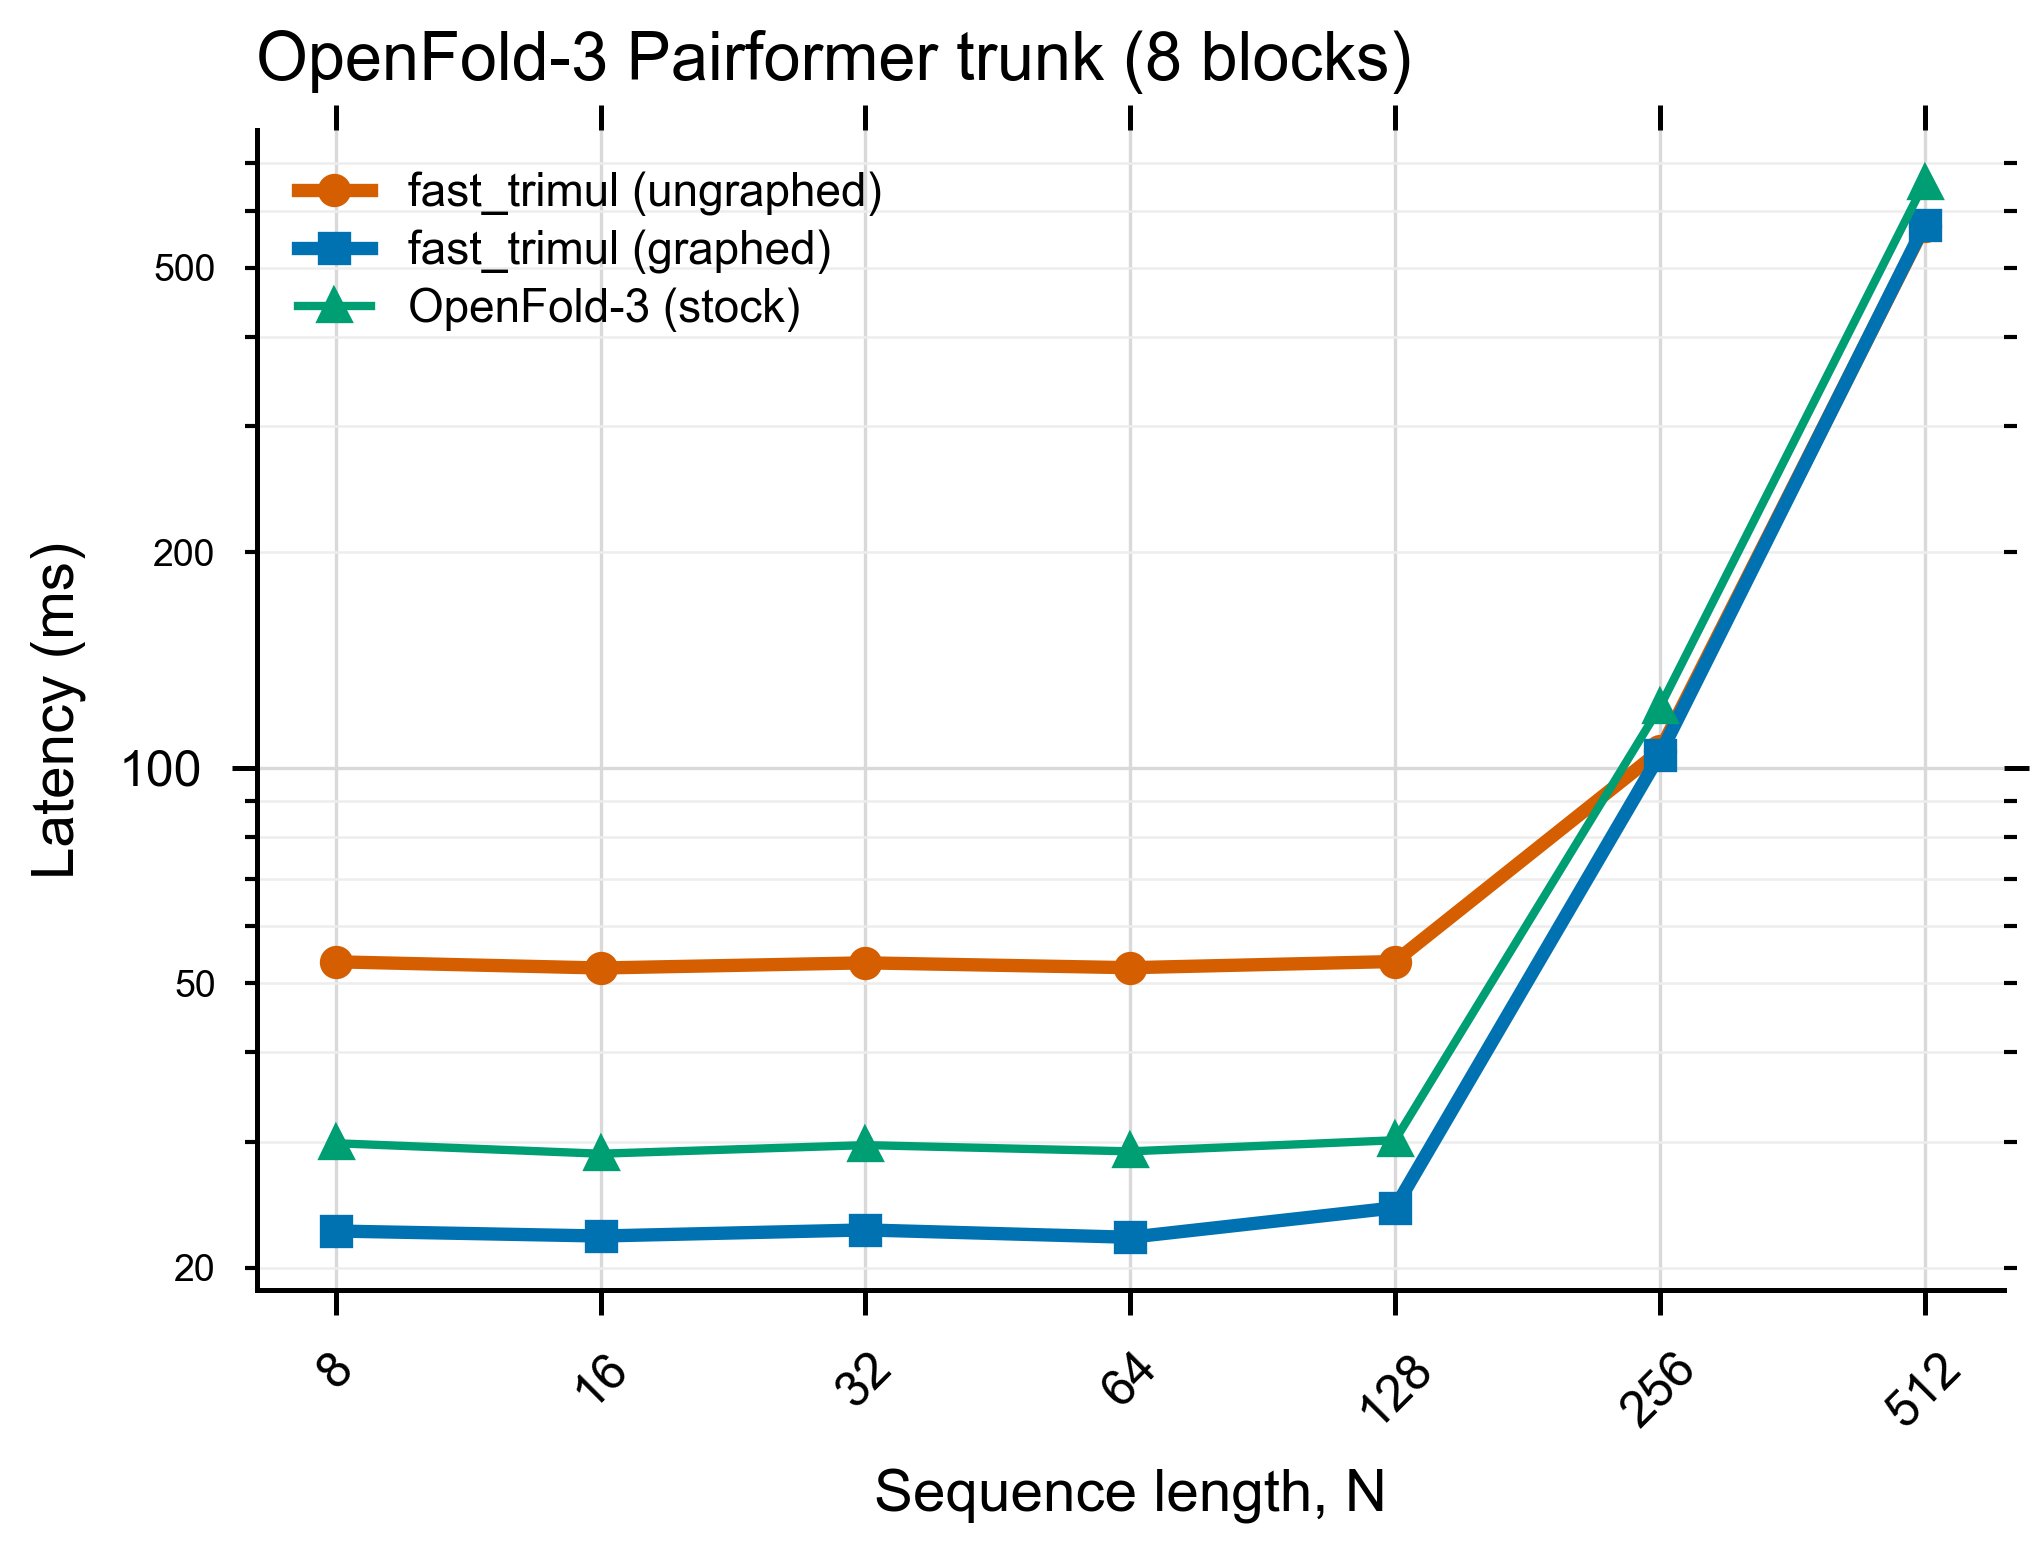
A drop-in, hardware-agnostic library for Fused Triangle Multiplicative Updates across AlphaFold3-family models, powered by CUTLASS CuTe kernels.