cleanlab
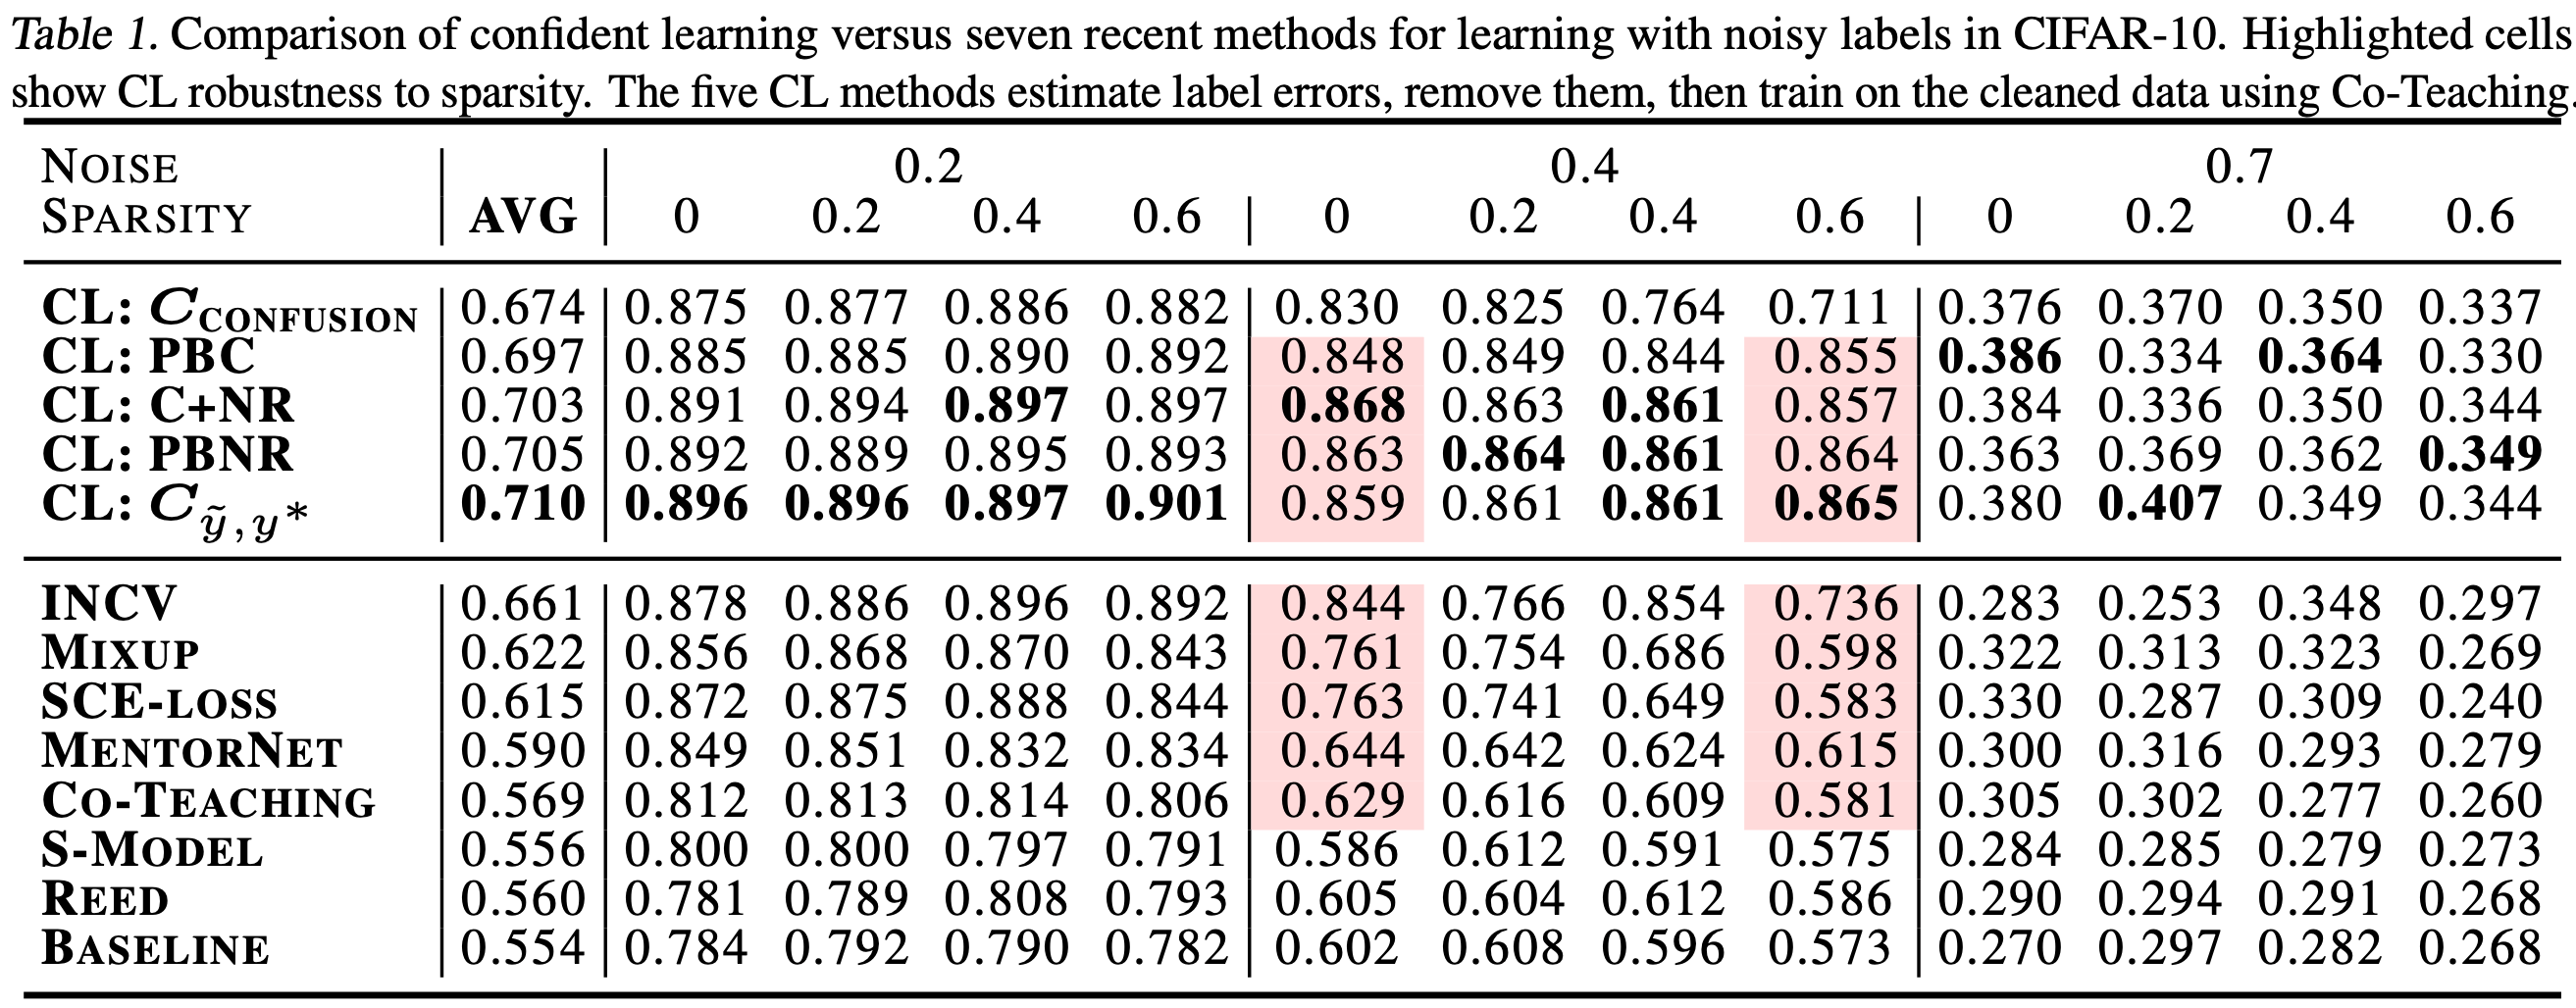
Cleanlab's open-source library is the standard data-centric AI package for data quality and machine learning with messy, real-world data and labels.
- 12k
- Python
- Apache-2.0
- 10 mo ago
Cleanlab's open-source library is the standard data-centric AI package for data quality and machine learning with messy, real-world data and labels.
The data scientist's open-source choice to scale, assess and maintain natural language data. Treat training data like a software artifact.
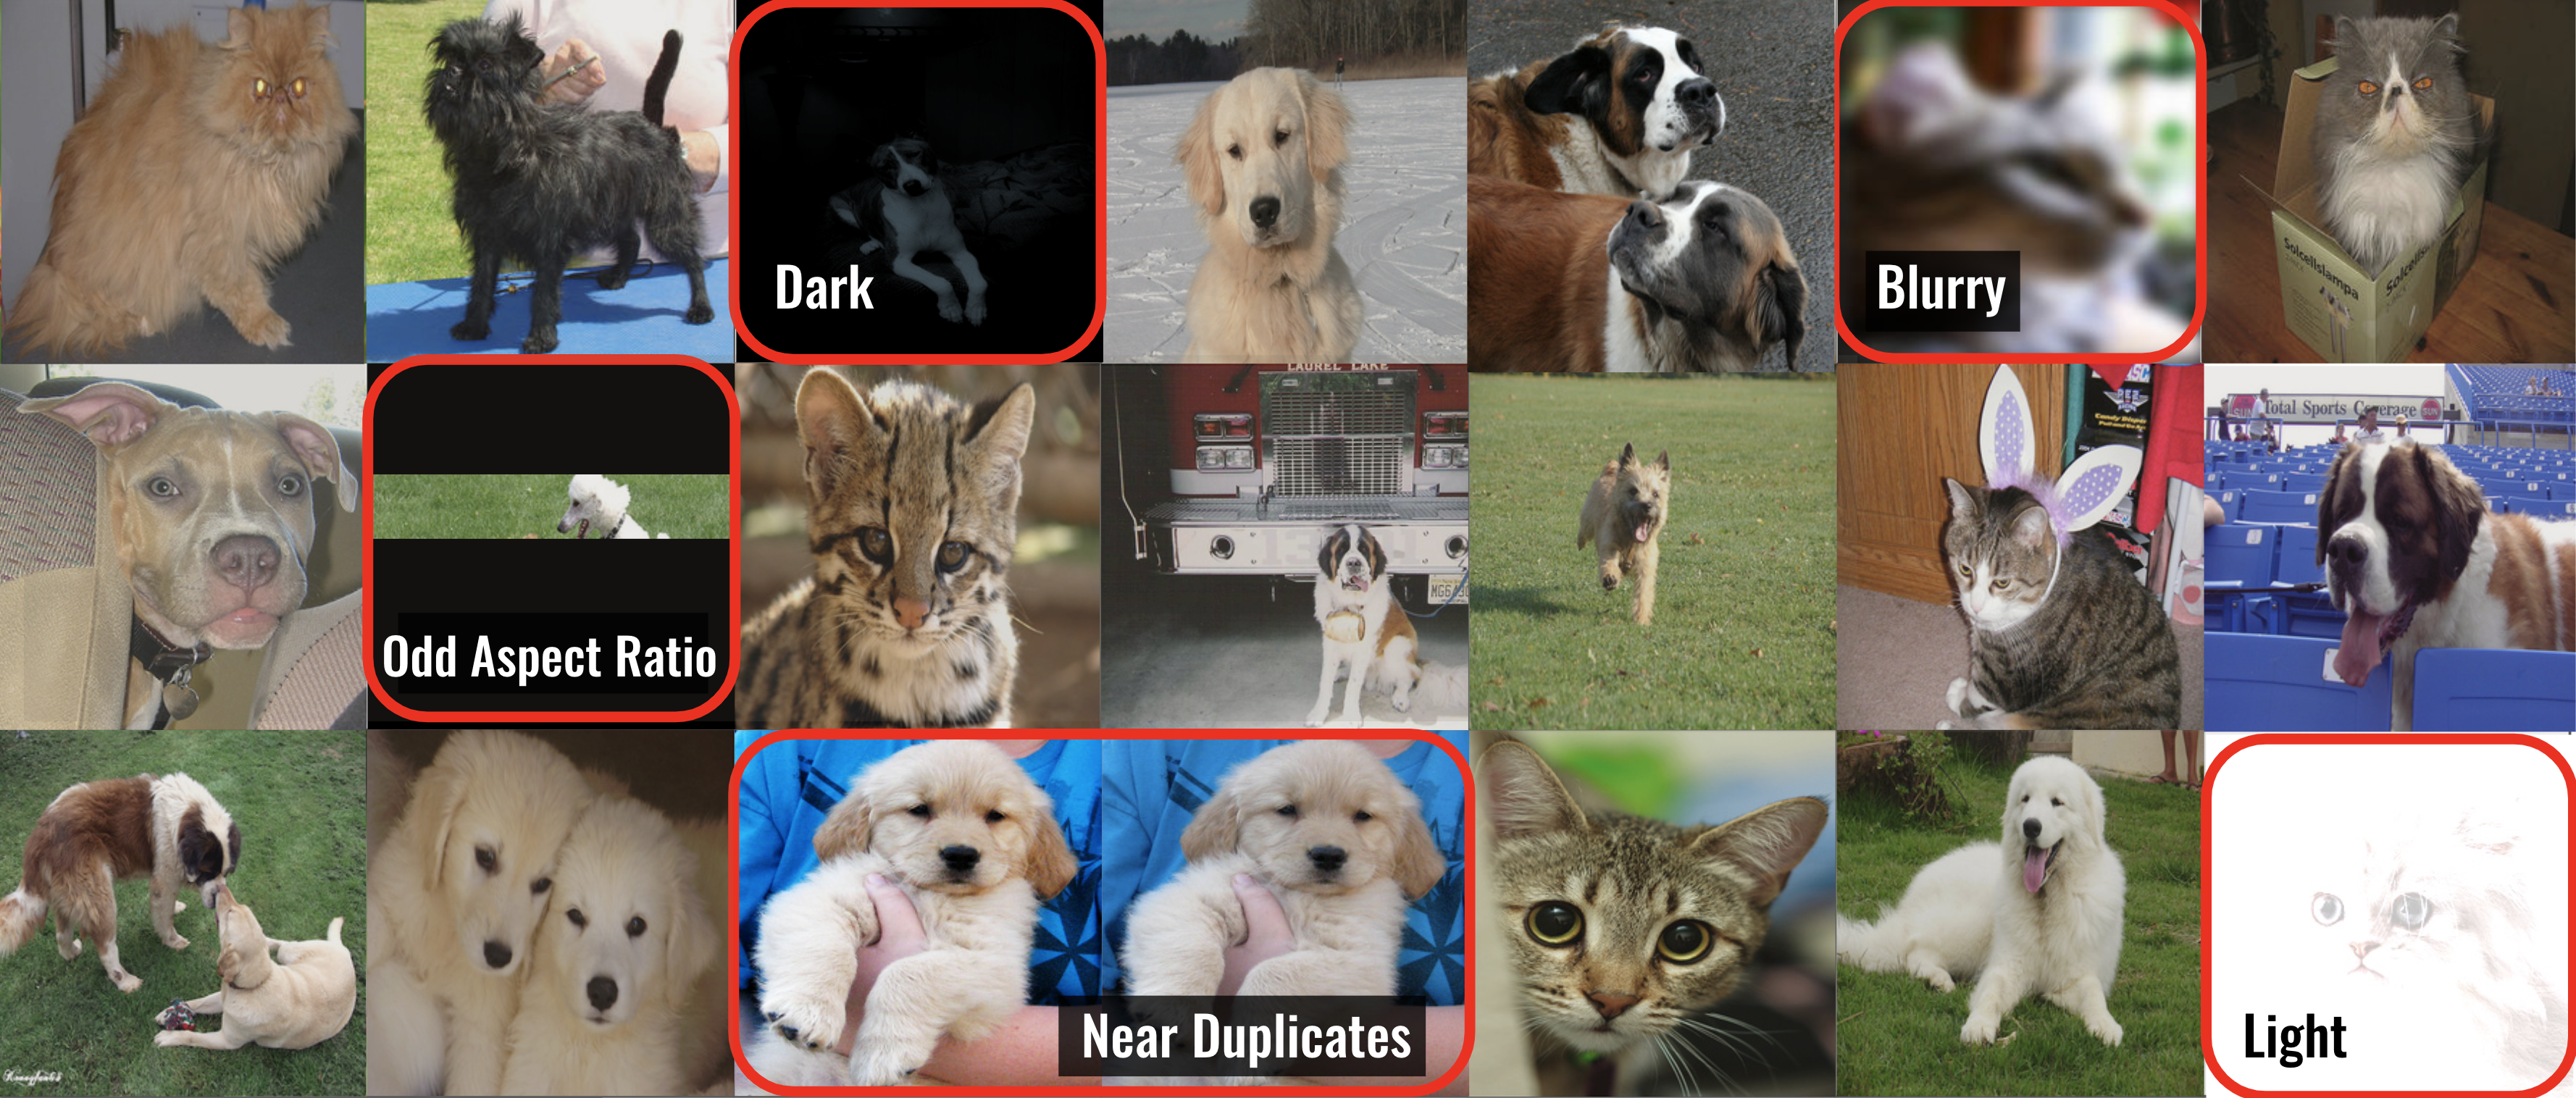
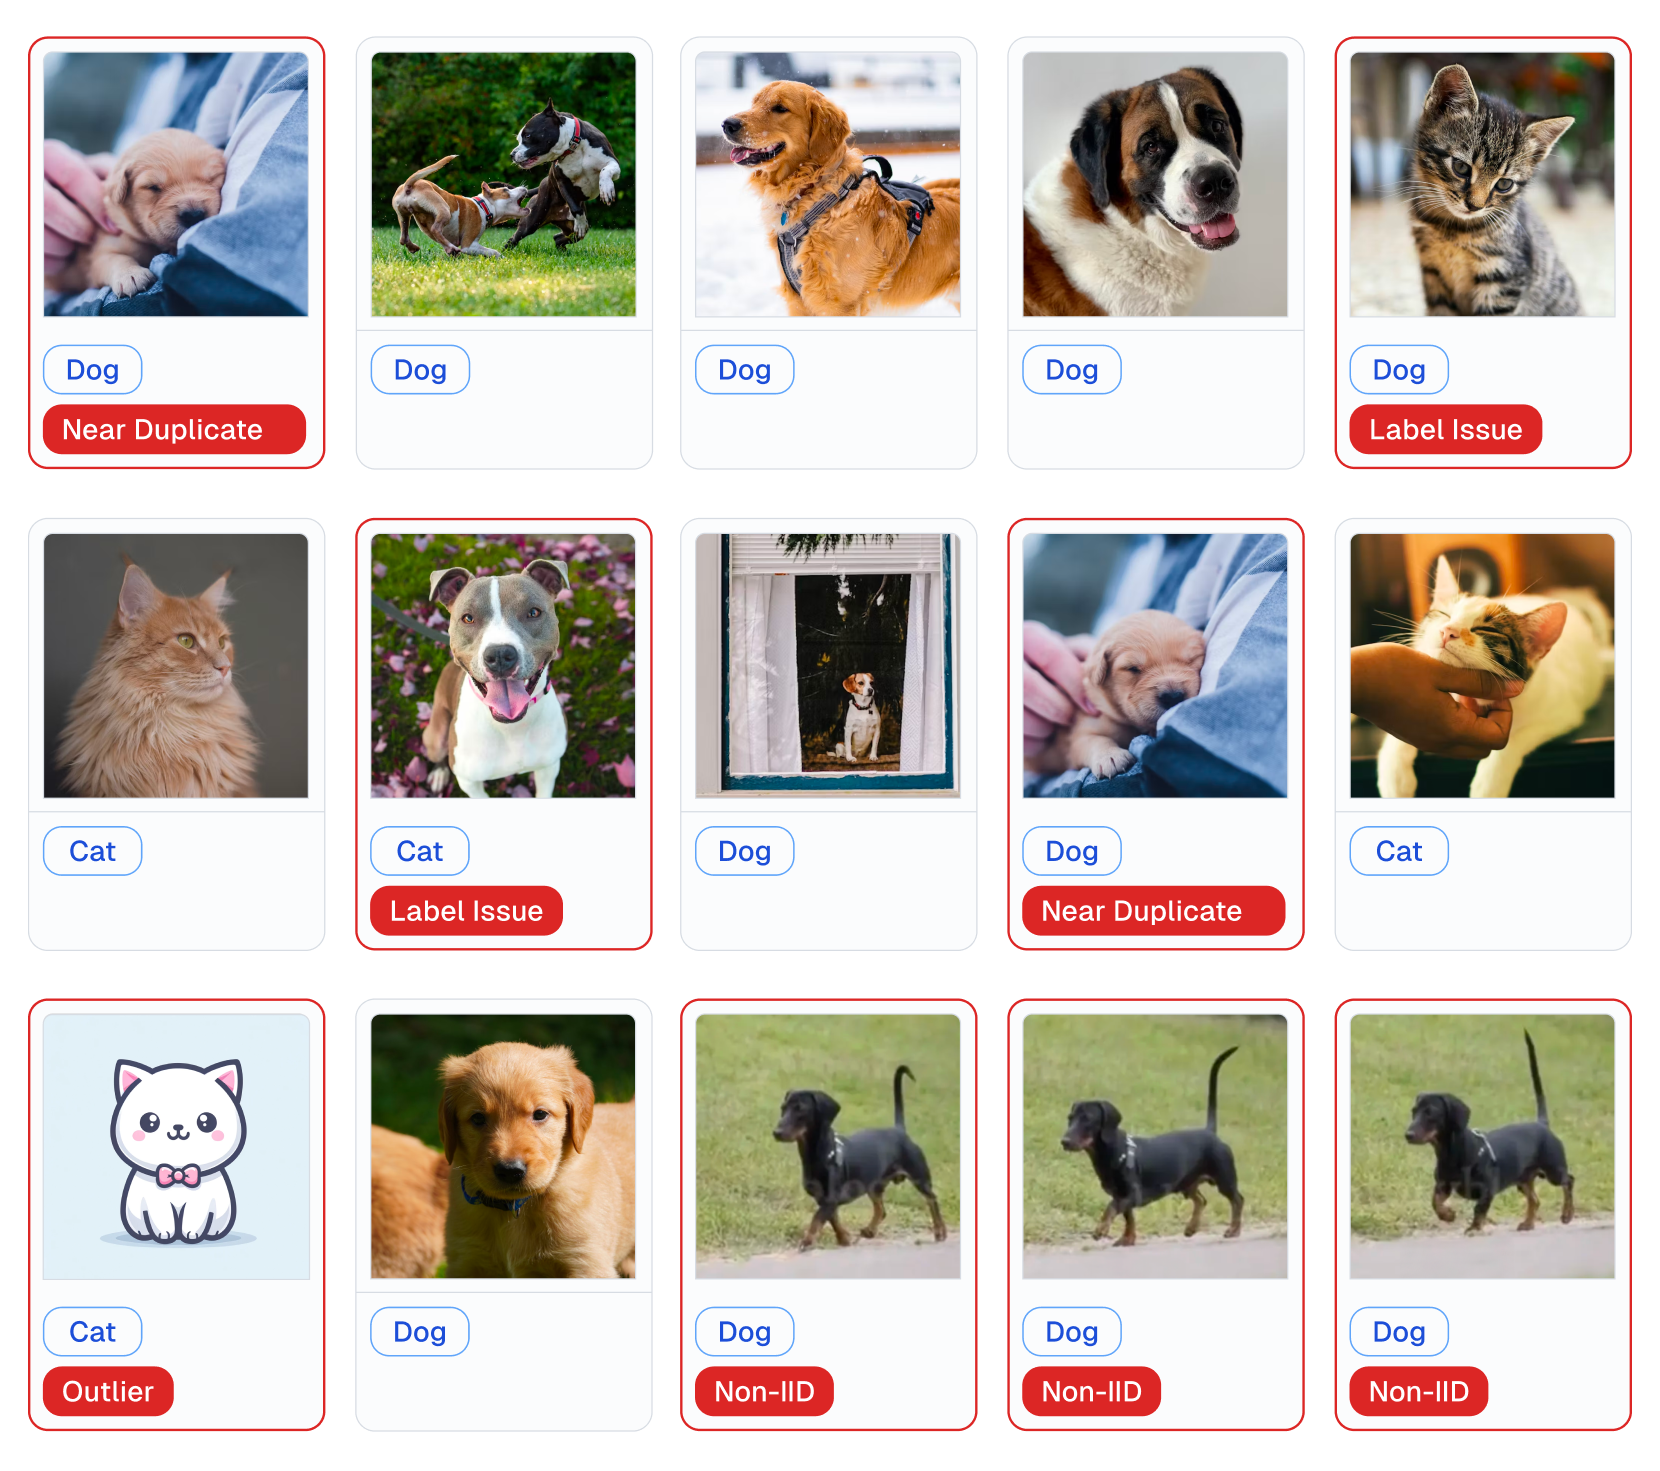
Automatically find issues in image datasets and practice data-centric computer vision.
Curated list of open source tooling for data-centric AI on unstructured data.
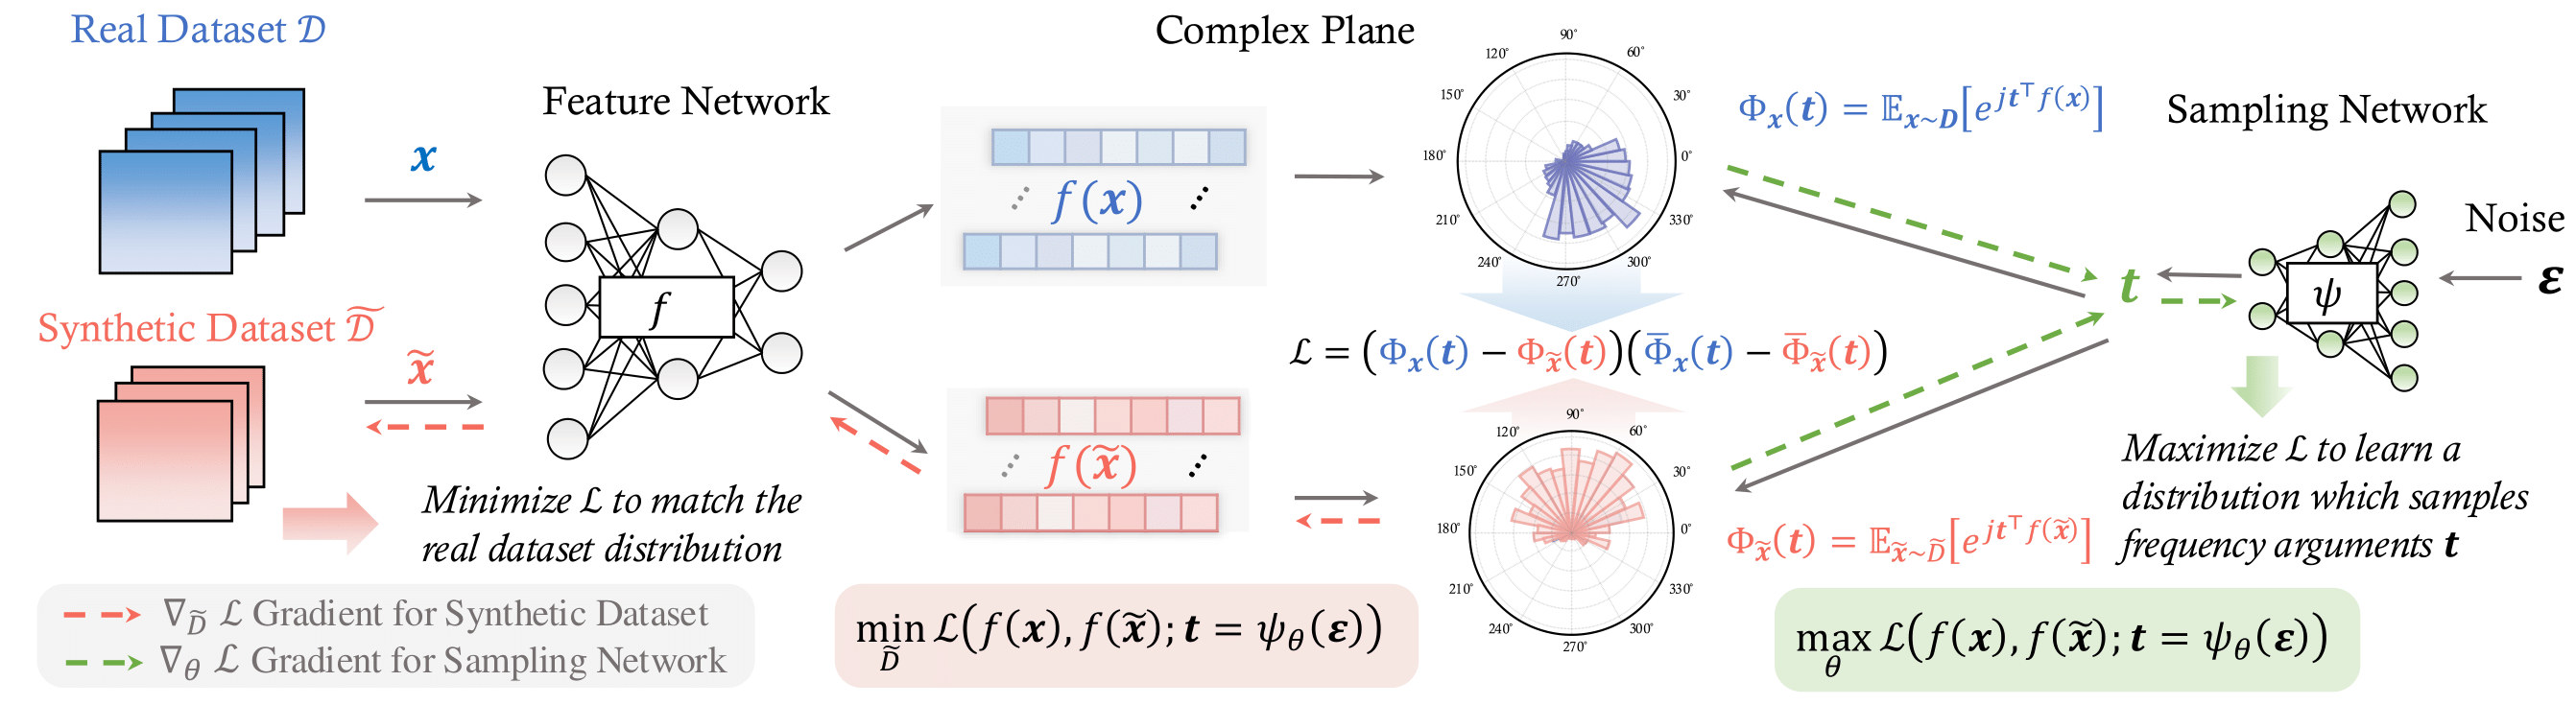
Official PyTorch implementation of the paper "Dataset Distillation with Neural Characteristic Function: A Minmax Perspective" (NCFM) in CVPR 2025 (Full Score, Highlight).
Lab assignments for Introduction to Data-Centric AI, MIT IAP 2024 👩🏽💻
🏭 Mega Scale Multimodal DataPipeline for SOTA Foundation Models
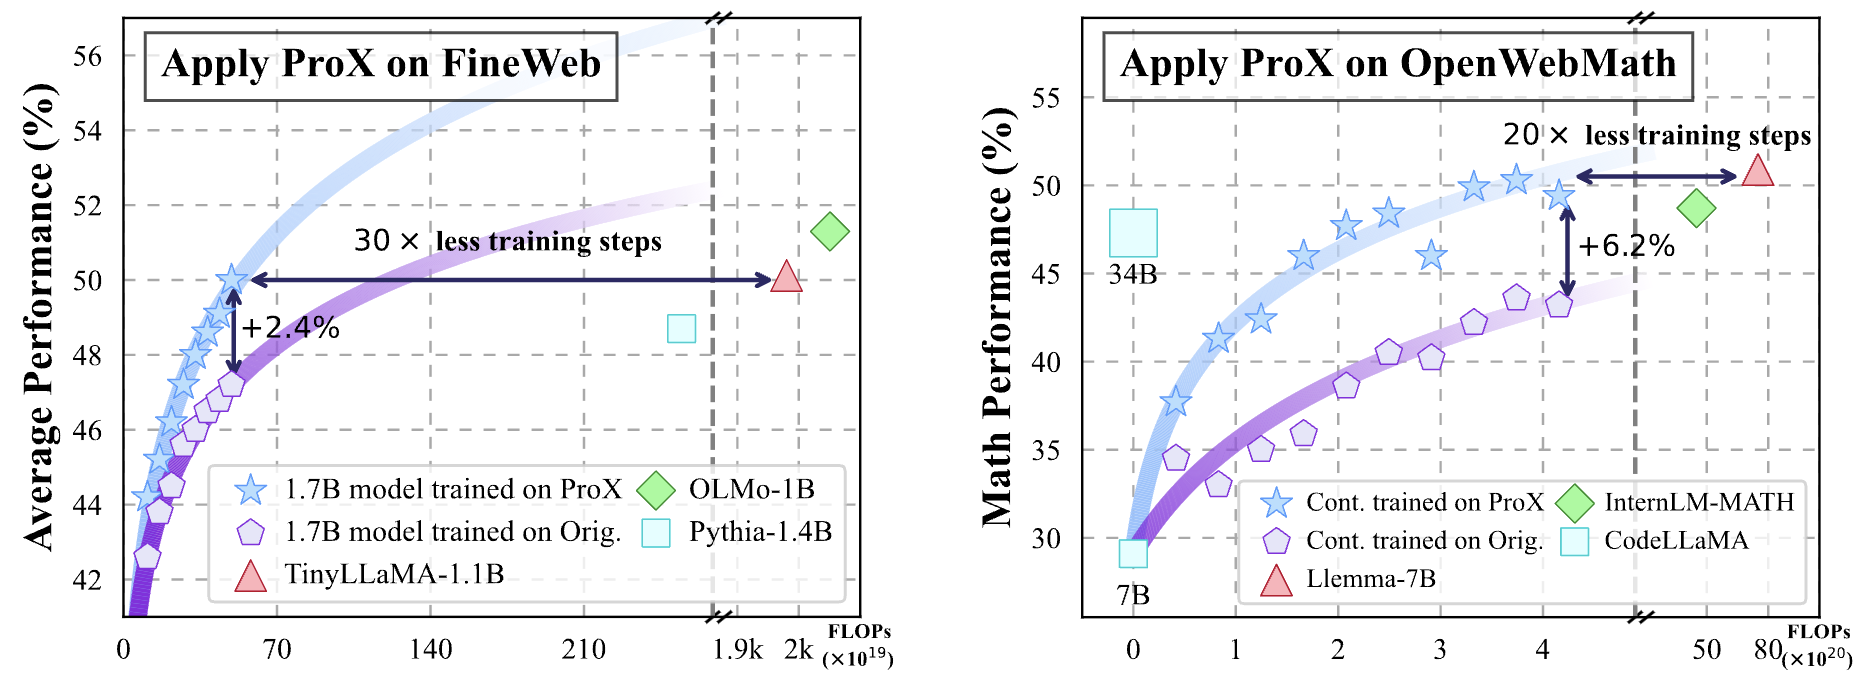
[ICML 2025] Programming Every Example: Lifting Pre-training Data Quality Like Experts at Scale
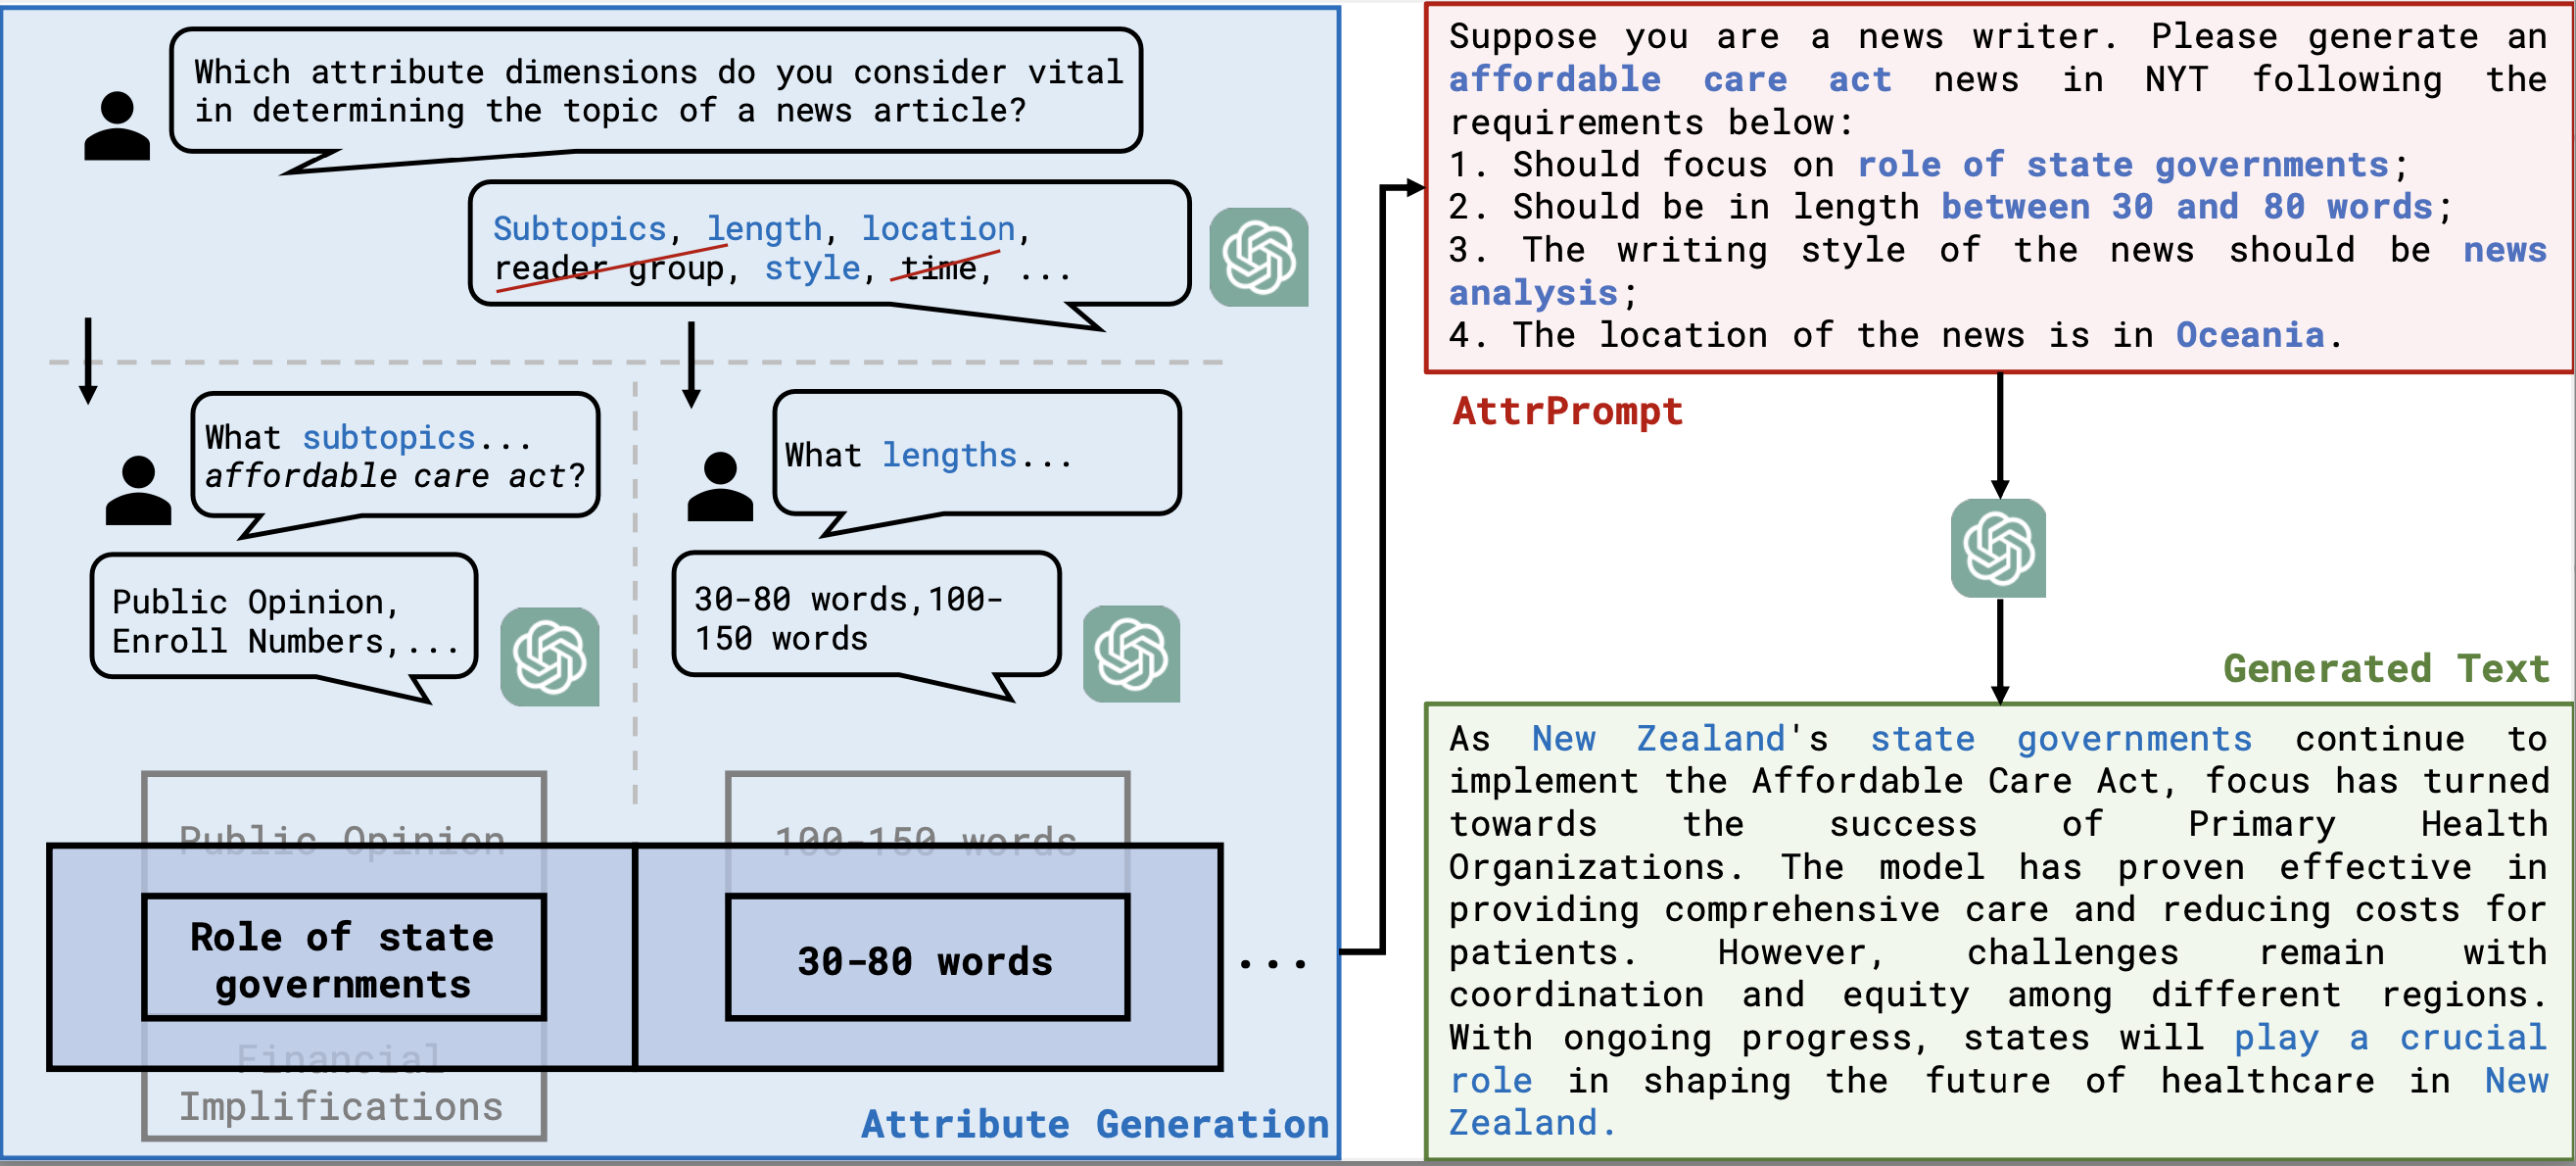
[NeurIPS 2023] This is the code for the paper `Large Language Model as Attributed Training Data Generator: A Tale of Diversity and Bias`.
Notebooks demonstrating example applications of the cleanlab library
nbsynthetic is simple and robust tabular synthetic data generation library for small and medium size datasets
A curated list of awesome open source tools and commercial products to catalog, version, and manage data 🚀
Frontiers in Neuroinformatics 2022: Local Label Point Correction for Edge Detection of Overlapping Cervical Cells
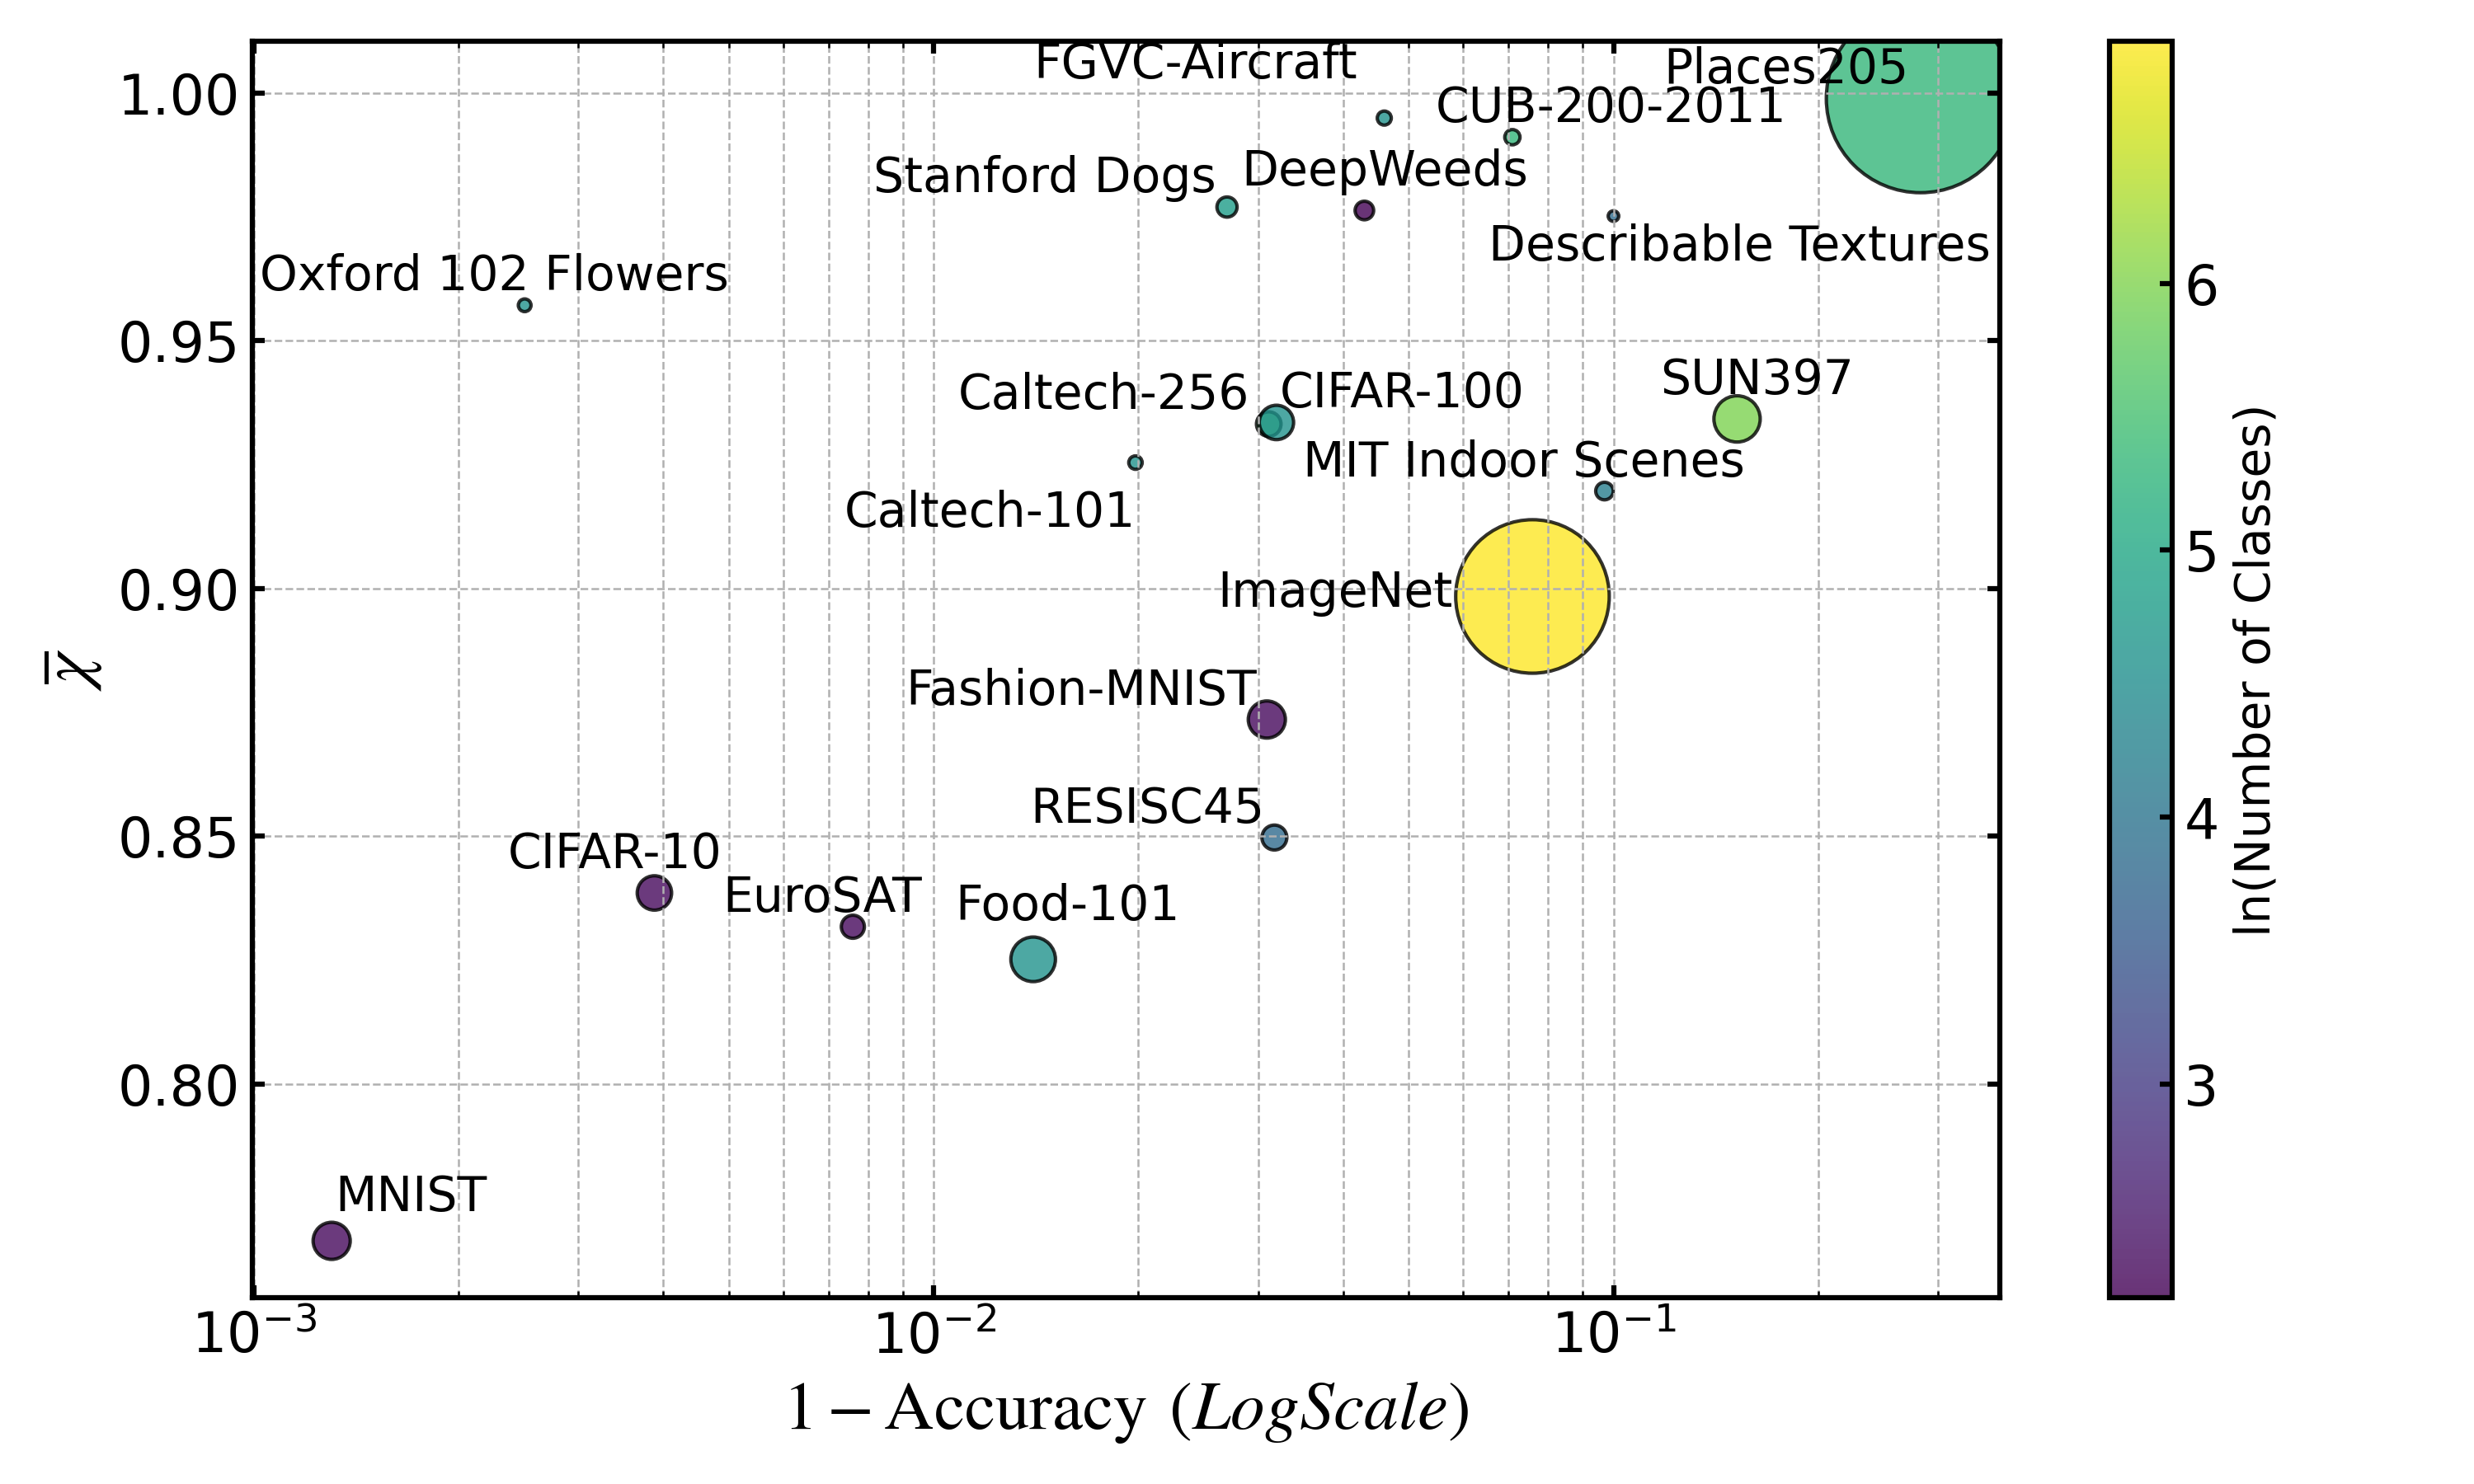
Estimate dataset difficulty and detect label mistakes using reconstruction error ratios!
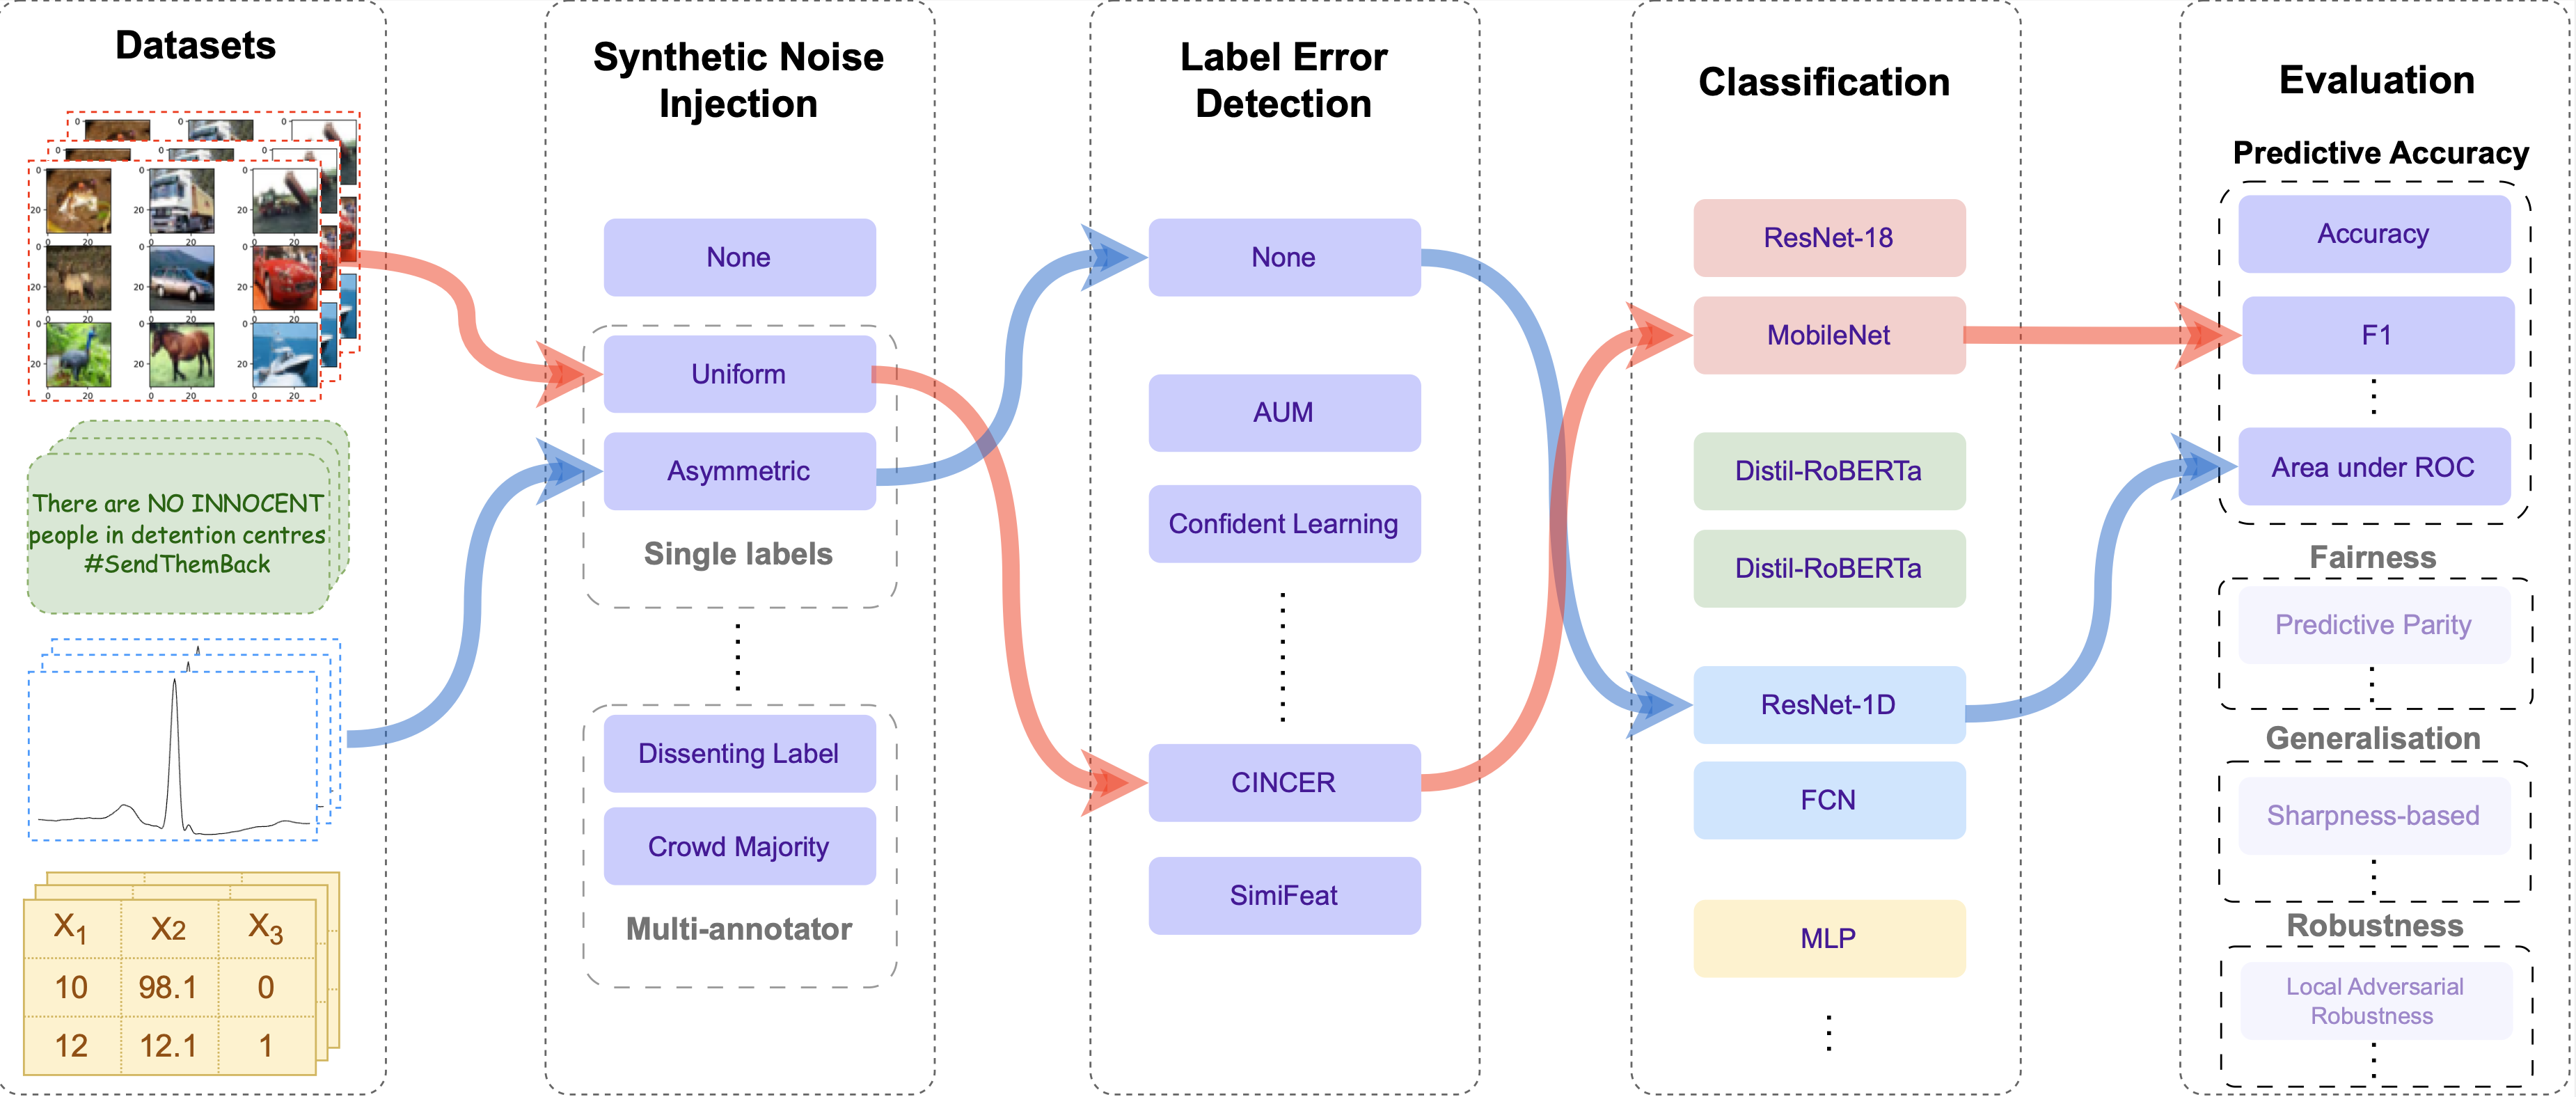
AQuA: A Benchmarking Tool for Label Quality Assessment, NeurIPS'23 D&B
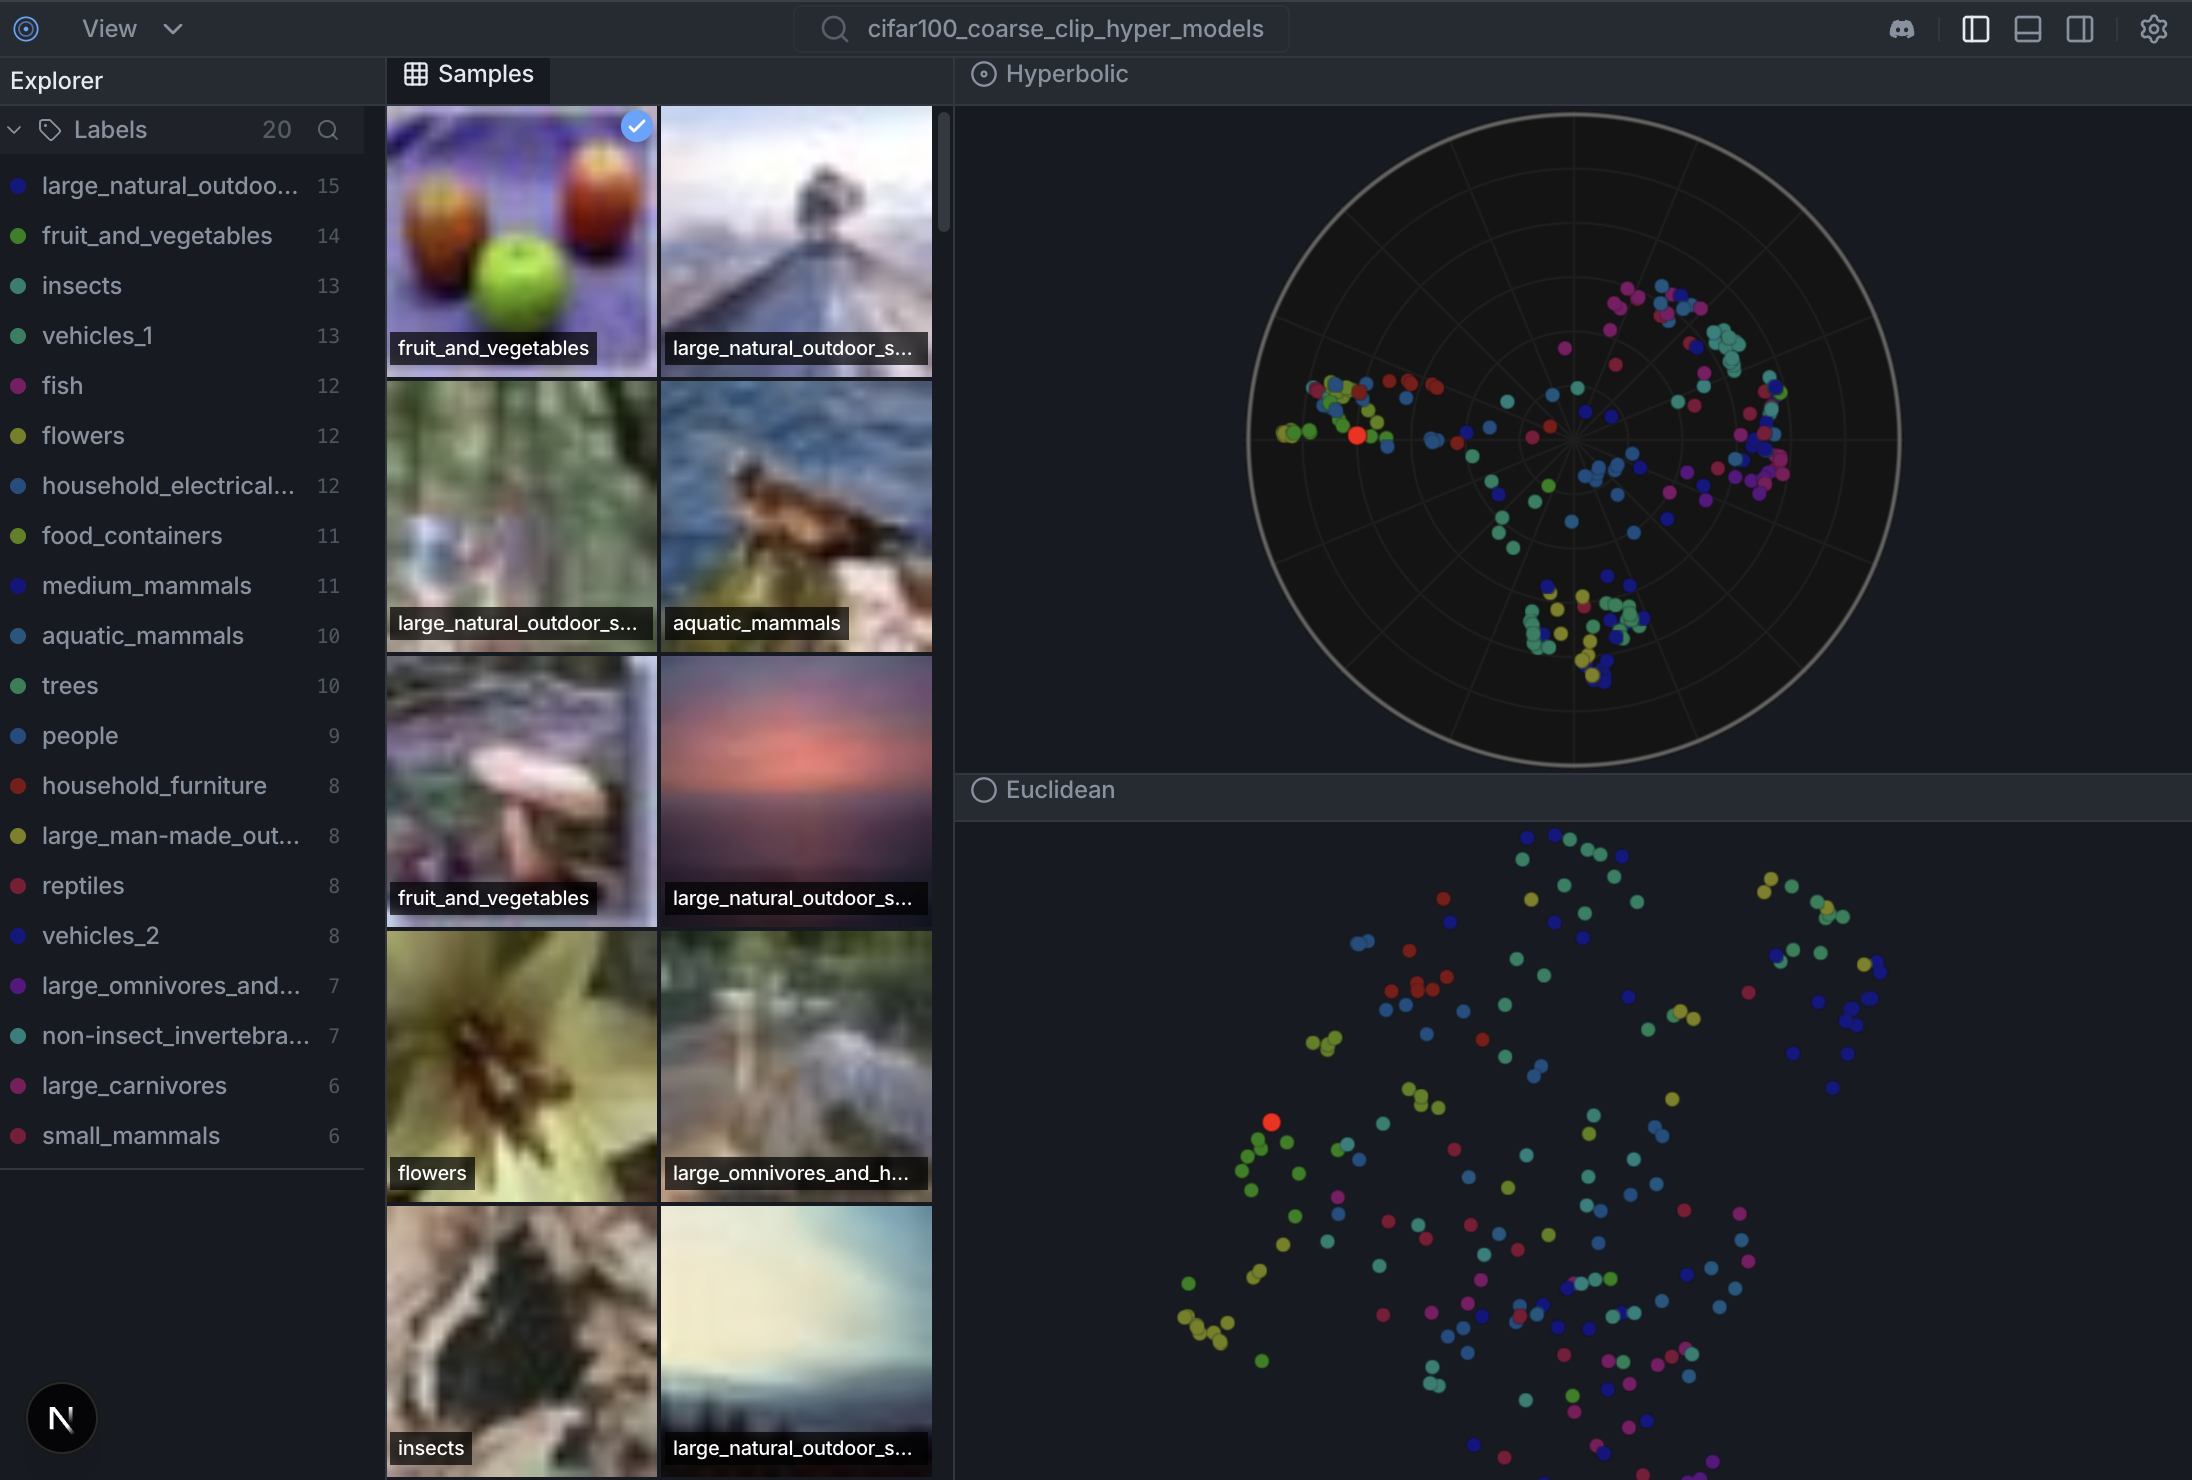
HyperView curates datasets and provides model introspection in hyperbolic and Euclidean geometries.
Codes for a Top 5% finish in the Data-Centric AI Competition organized by Andrew Ng and DeepLearning.AI
Goldener - Make your data even more valuable - Open source data-centric orchestration for the full AI lifecycle
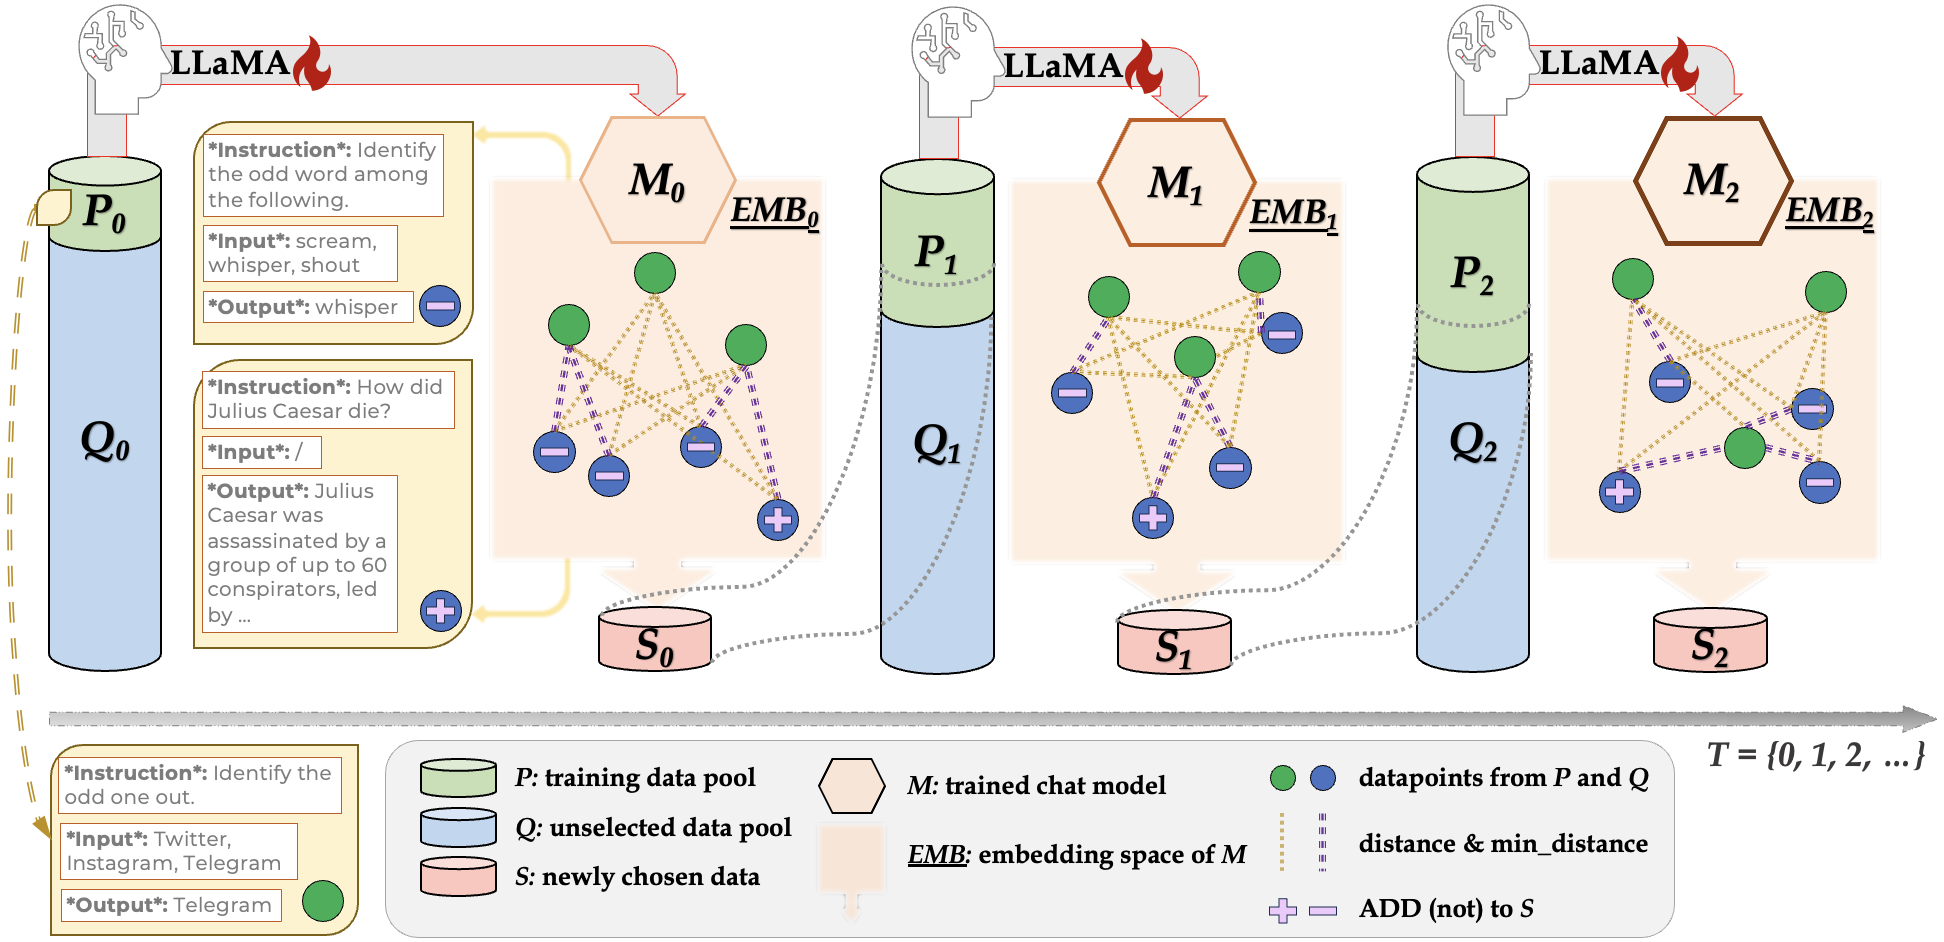
Implementation of TSDS: Data Selection for Task-Specific Model Finetuning. An optimal-transport framework for selecting domain-specific and task-specific training data to improve LLM finetuning and instruction tuning.
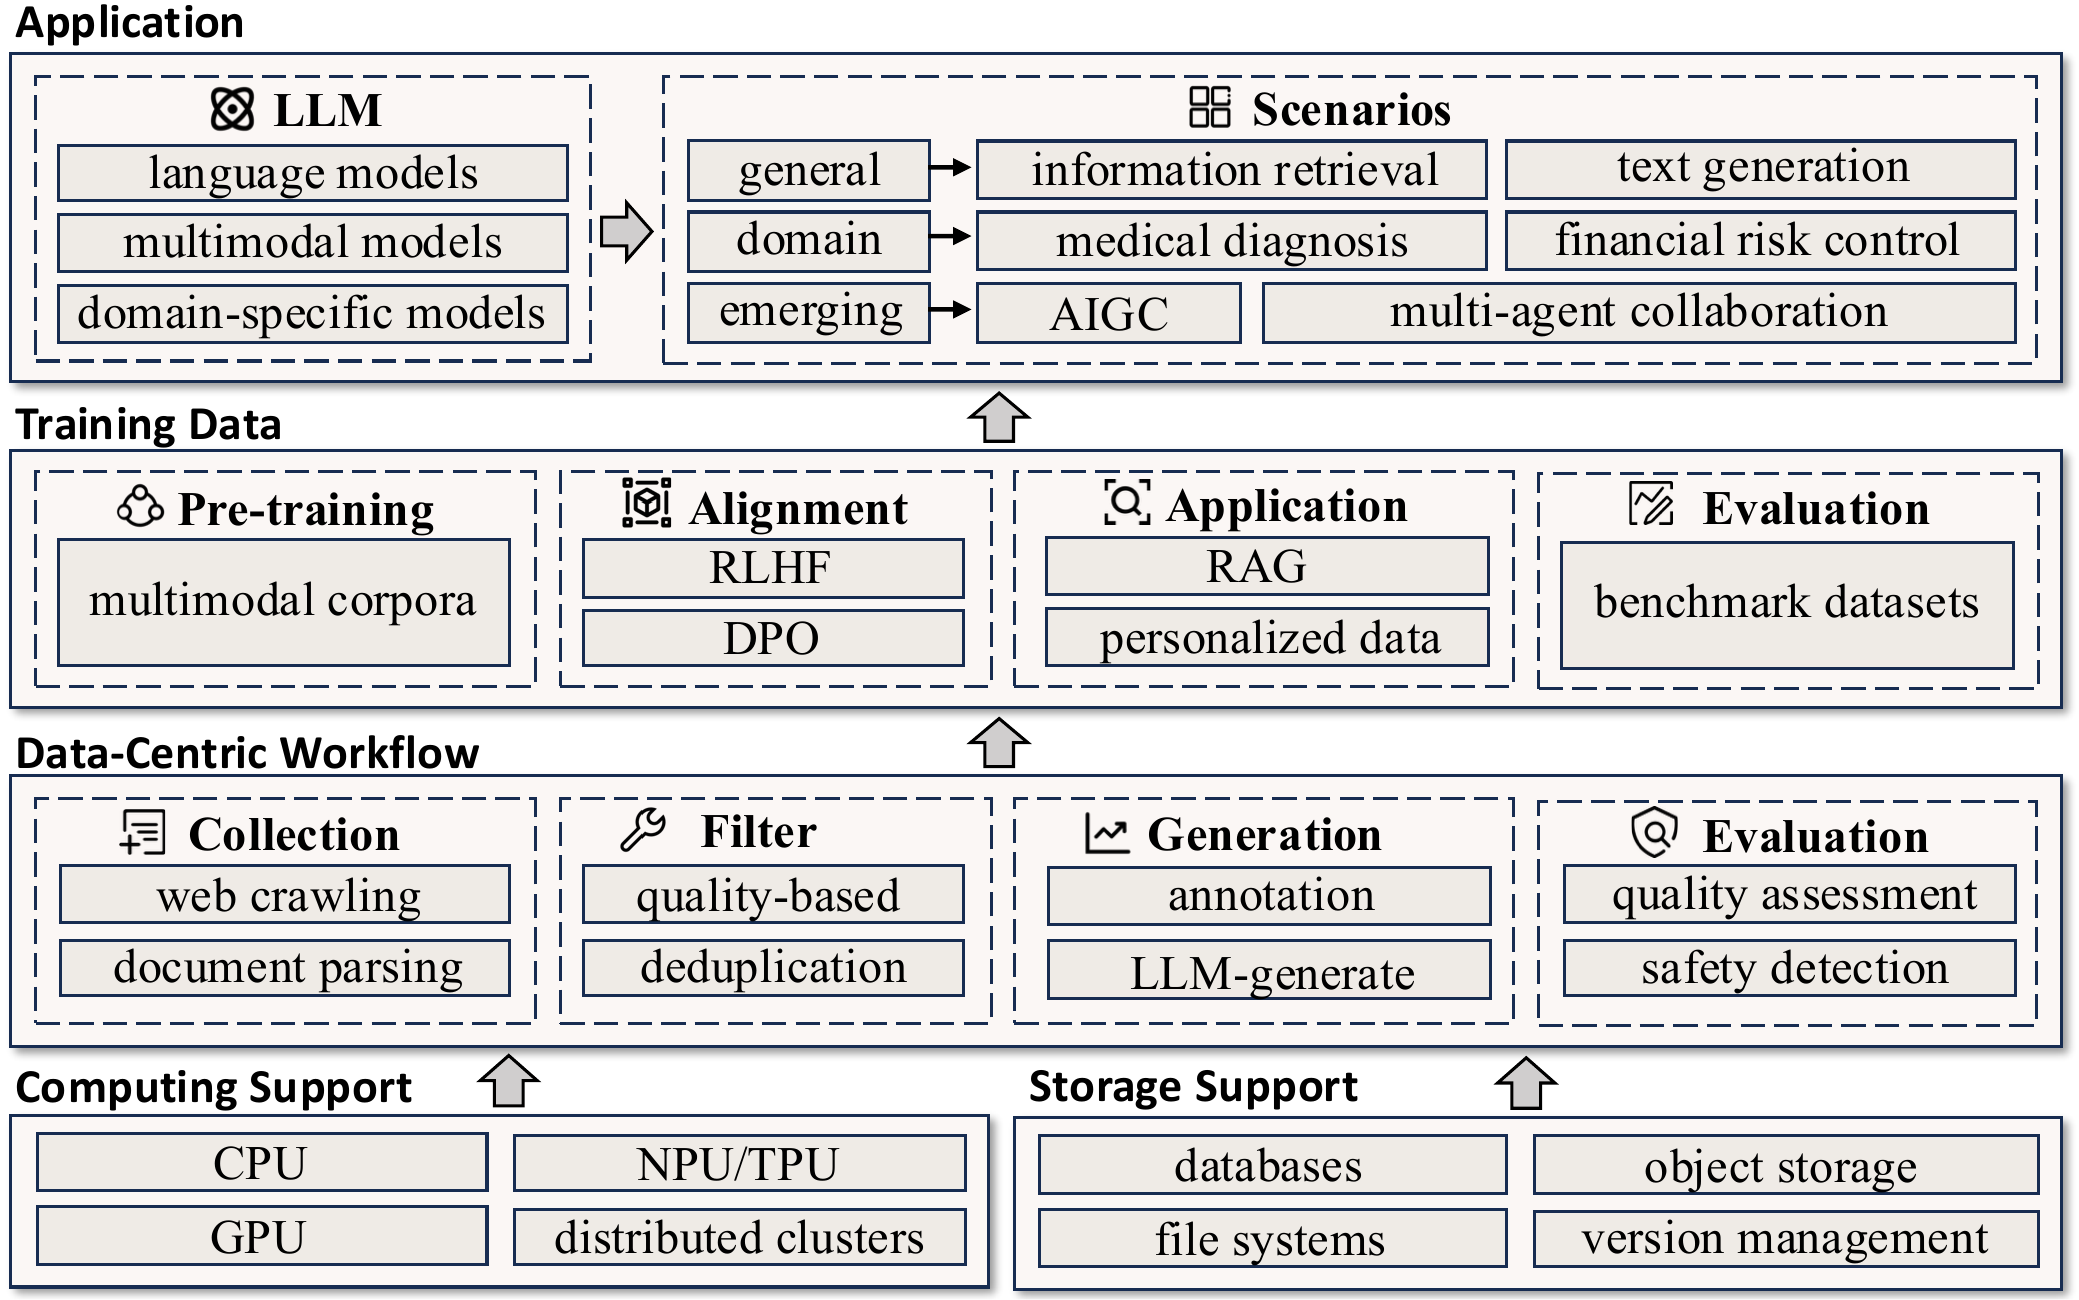
Data Preparation for Large Language Models — a curated companion to our JCST 2026 survey. Covers Pre-training, Continual Pre-training, and Post-training (SFT/RLHF/RLAIF) across collection, filtering, dedup, generation, evaluation.
Compute clustering on your data in a visual, intuitive way with FiftyOne and Sklearn!
Semantically search through OCR text blocks with Qdrant, Sentence Transformers, and FiftyOne!
Filter a float-valued field on two ranges simultaneously with this FiftyOne Plugin!
LLM learns to fix data, not models — GRPO RL env.
Runs in the browser on Hugging Face