OpenMetadata
The Open Context Layer for Data and AI , OpenMetadata is the open platform for building trusted data context and business semantics for humans, AI assistants, and agents.
- 16k
- TypeScript
- Apache-2.0
- 3 h ago
The Open Context Layer for Data and AI , OpenMetadata is the open platform for building trusted data context and business semantics for humans, AI assistants, and agents.
Database governance built for humans and agents — controlling changes and access across every major database.
LeanCTX is the Context Gateway for AI Systems. Select task-relevant context, apply supported controls, connect local knowledge and inspect recorded evidence. Open-source Engine: CLI, MCP, hooks and supported proxy paths.
The dbt-native data observability solution for data & analytics engineers. Monitor your data pipelines in minutes. Available as self-hosted or cloud service with premium features.
Apache Iceberg REST Catalog in Rust — access control, credential vending and audit for every engine and AI agent. Apache 2.0.
qData is an open-source data governance and data development platform that integrates ETL, data development, metadata management, data quality, data assets, API services, and AI-powered data Q&A.
The open source knowledgehouse for your company. Marmot knows what your data means, governs who may use it and runs every query your people and agents make, checked and recorded. Catalog, lineage, governed SQL and an MCP server in one Go binary.
282+ structured privacy & data protection skills for AI agents. GDPR, CCPA, EU AI Act, HIPAA, LGPD, PIPL, DPDP Act.
Main repo including core data model, data marts, data quality tests, and terminology sets.
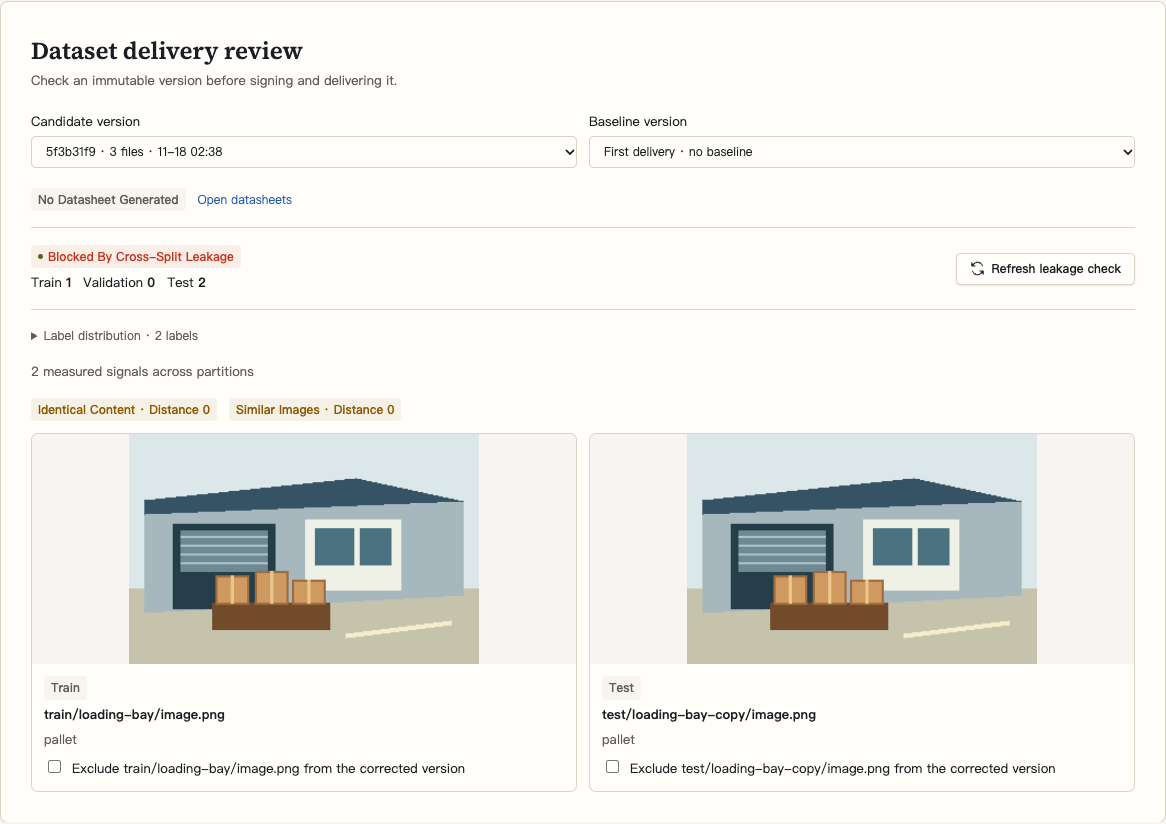
Local-first dataset workbench for visual QA, human-approved releases, and traceable metrics.
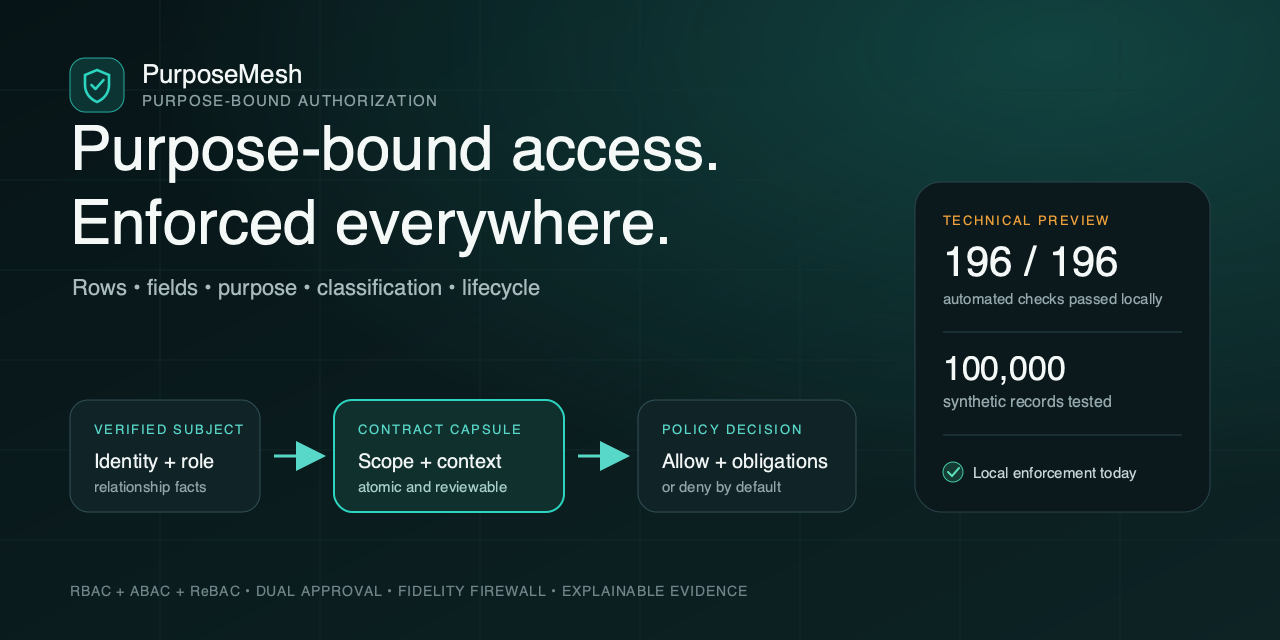
Purpose-bound authorization reference: RBAC + ABAC + ReBAC, row/field controls, fidelity gates, lifecycle governance, and a tested 100K synthetic-data path.
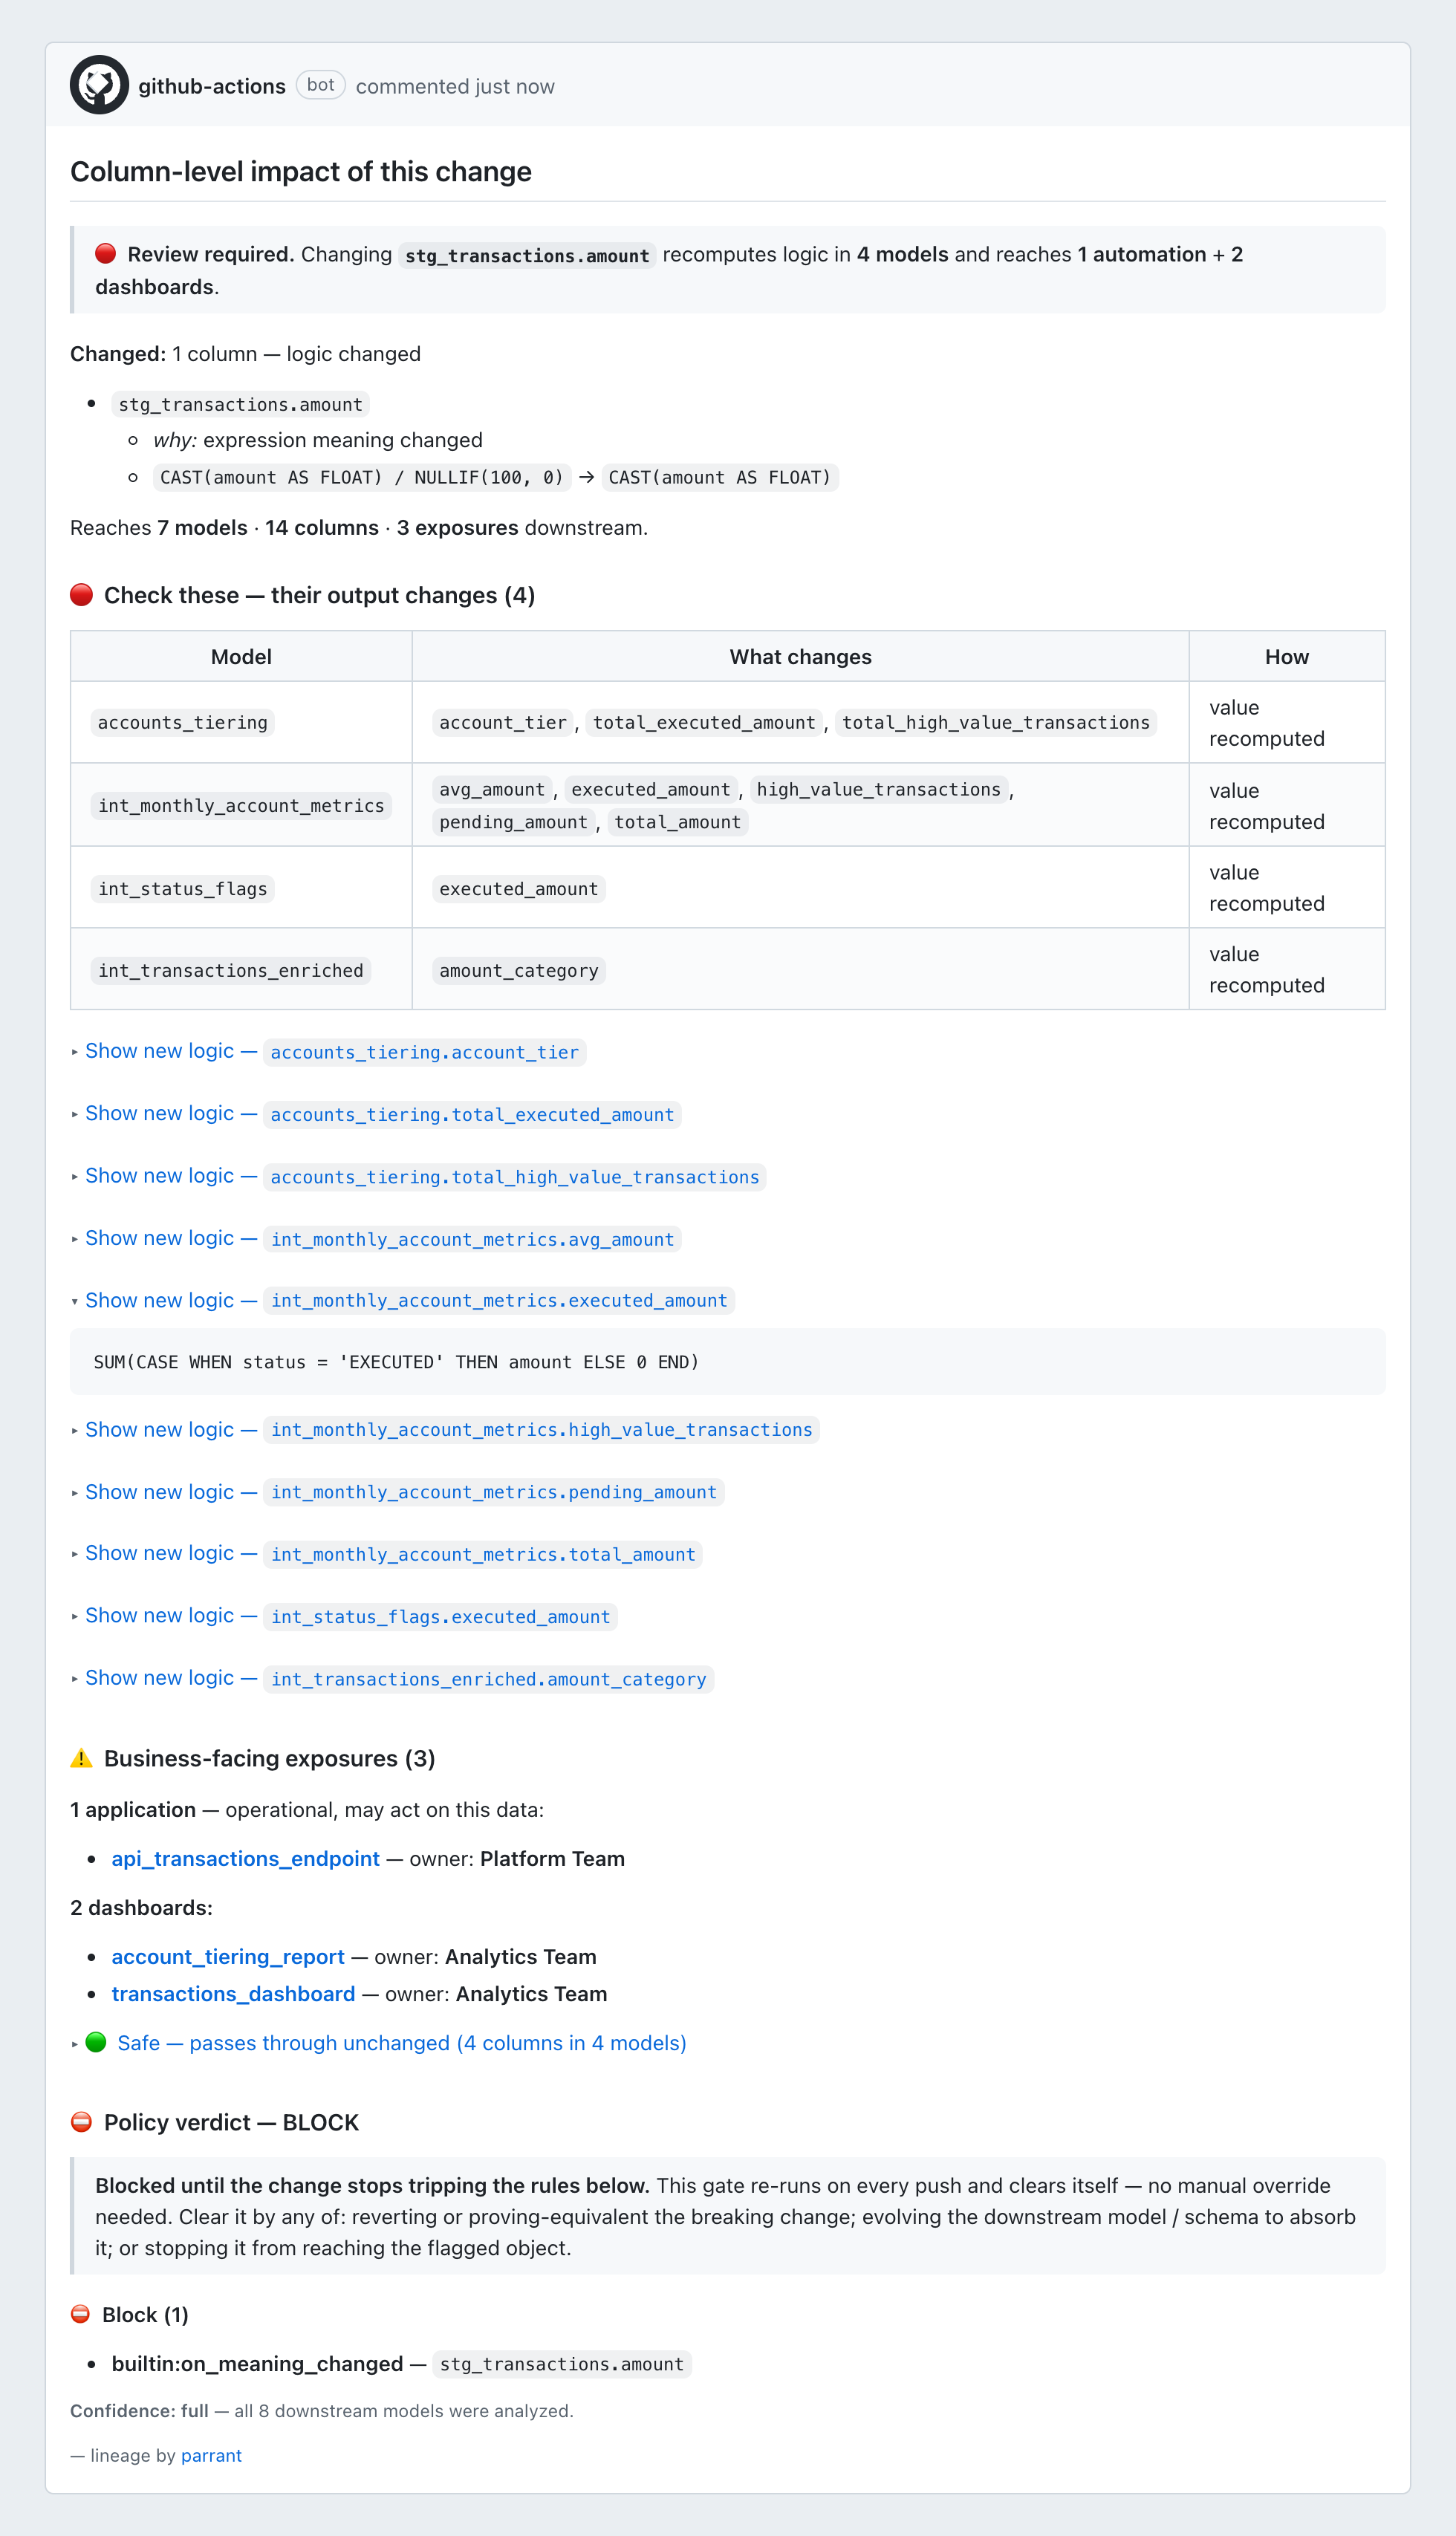
A change-impact decision engine for dbt. Column-level lineage plus a policy-gated verdict on every PR — what breaks, what to rebuild — computed offline from your dbt artifacts. No warehouse, no dbt run. Powered by SQLGlot.
Discover, mask, and verify sensitive data in SQL databases — an auditable scan → mask → validate workflow for safe database copies.
Mapping of DWH database tables to business entities, attributes & metrics in Python, with automatic creation of flattened tables
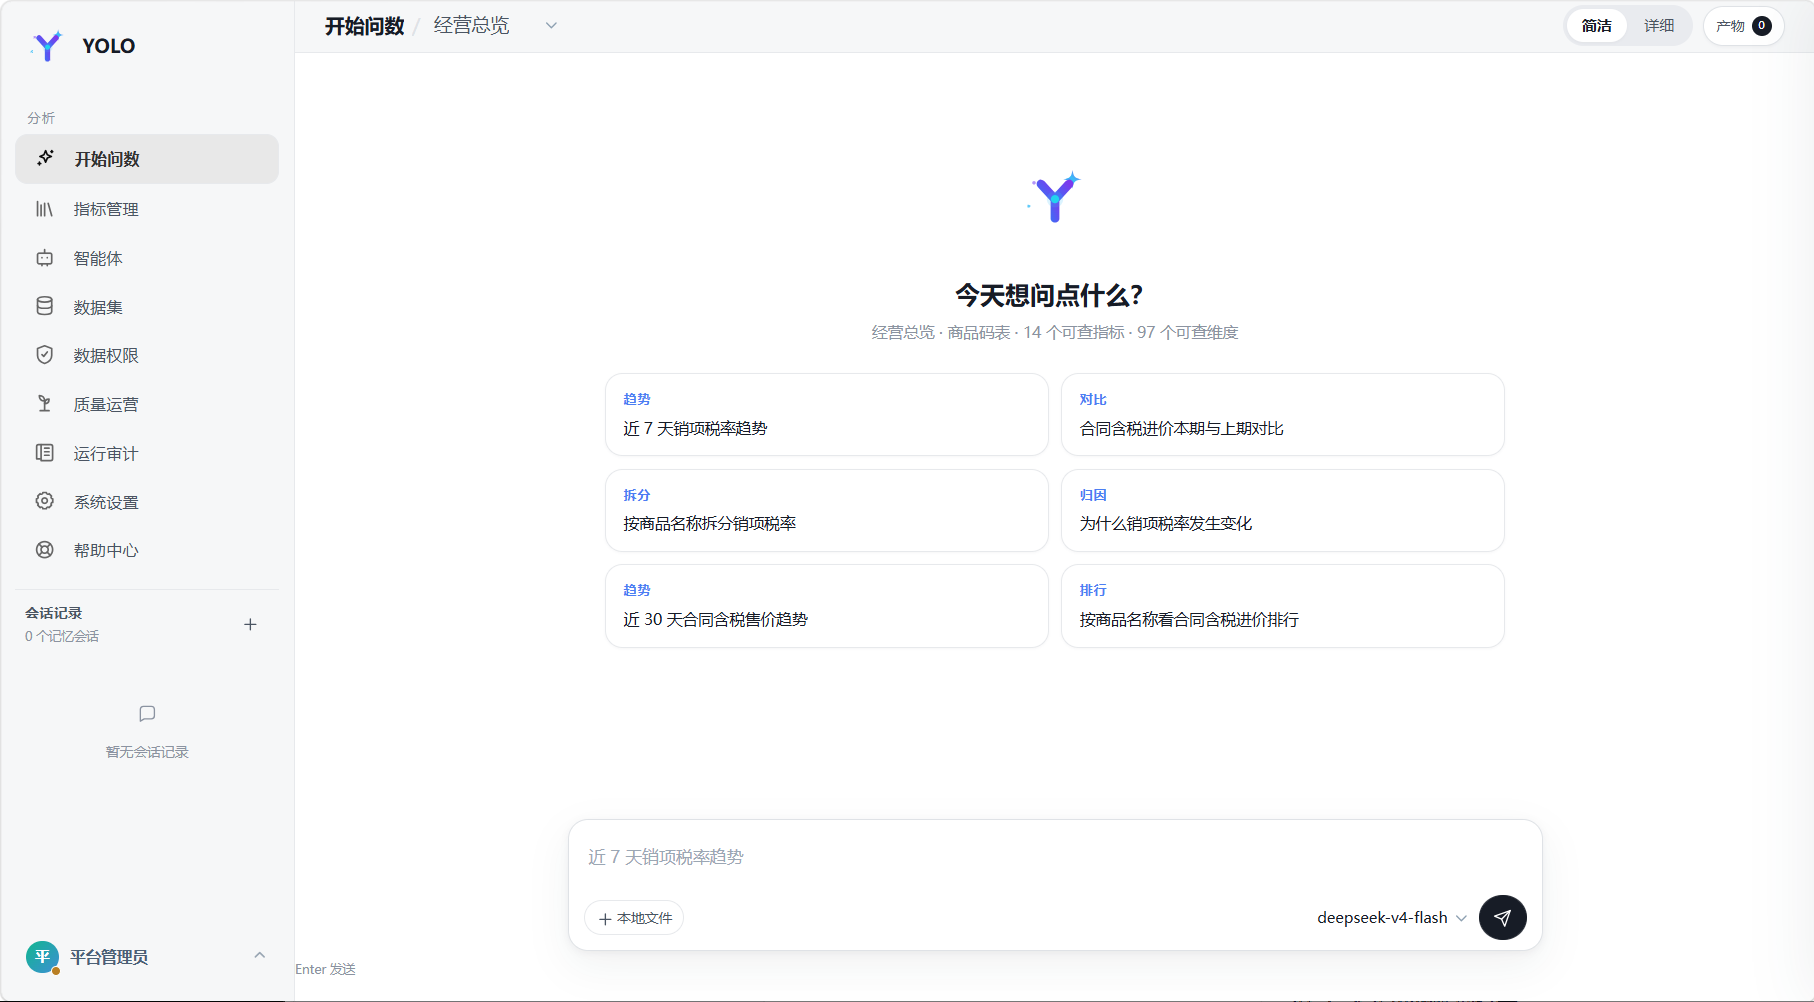
先进且稳定的企业级智能分析平台;面向企业问数、洞察分析的Data Agent,基于数据分析方法论打造可审计、可治理、可复现workflow
A starter dbt project and synthetic claims dataset for trying out the Tuva Project.
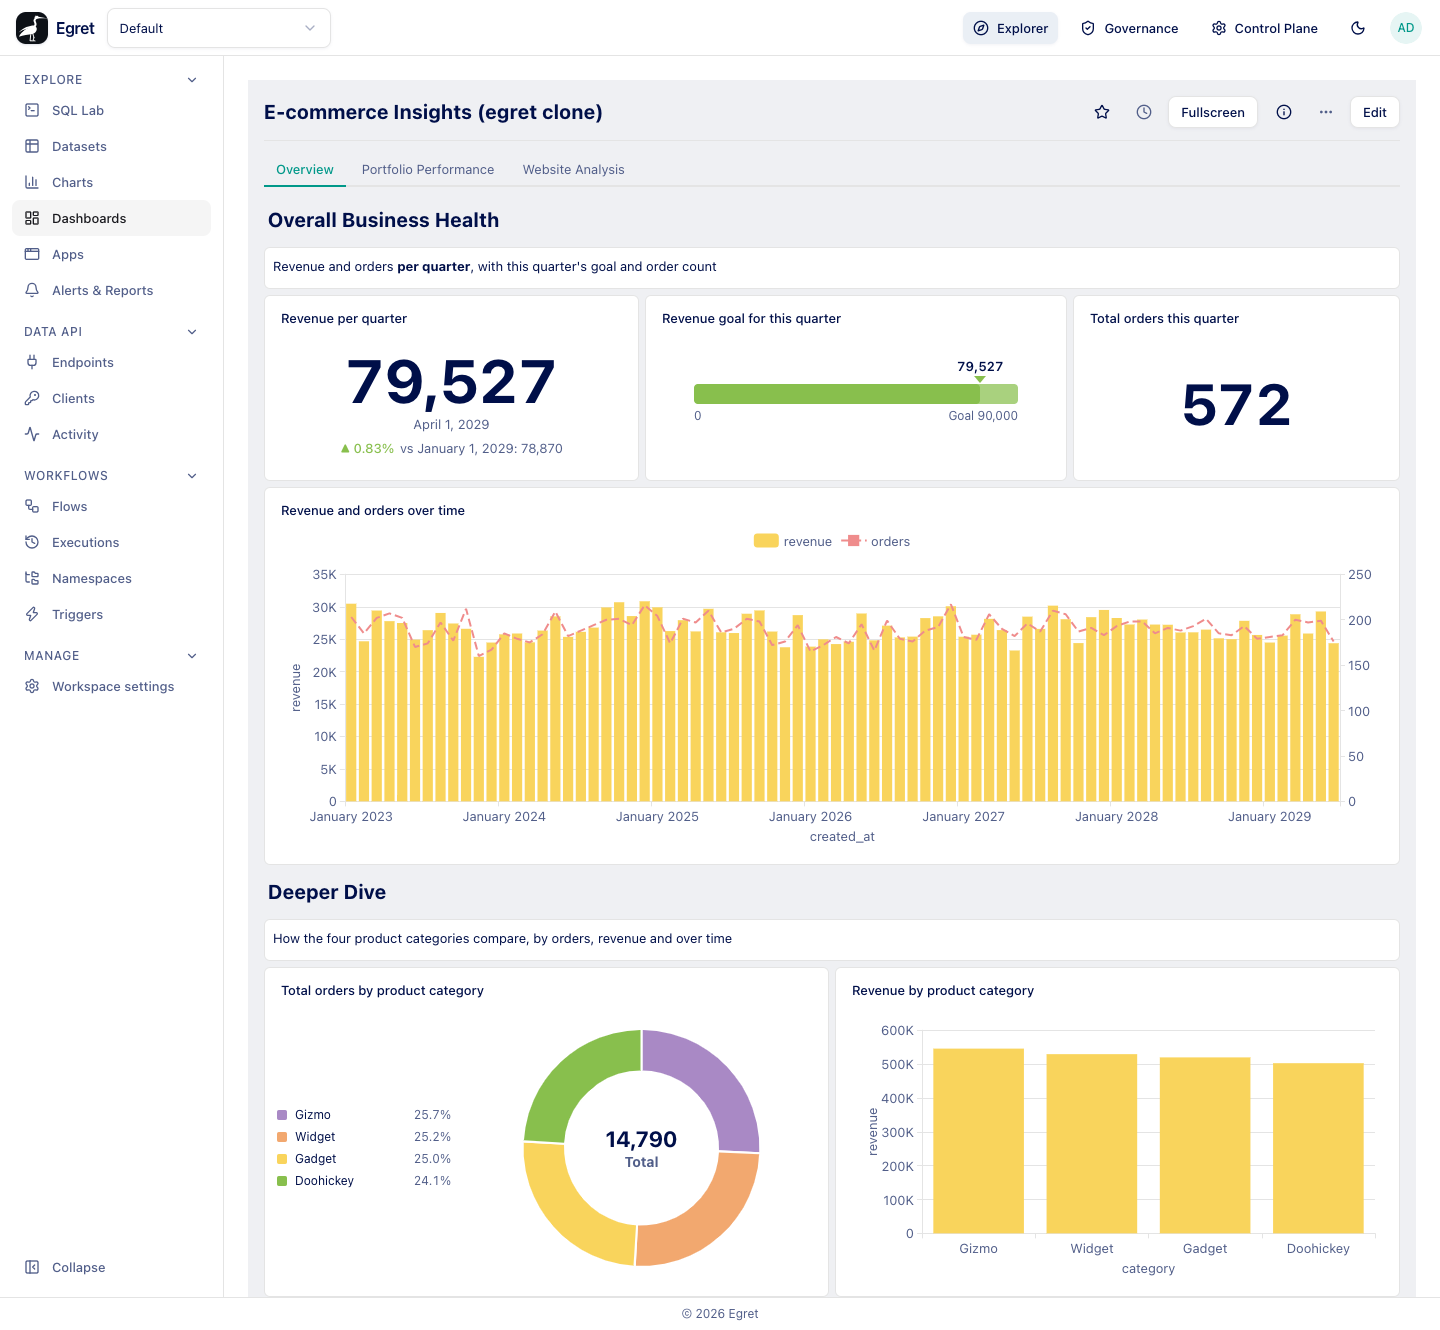
Open-source, multi-tenant data platform: isolated workspaces with BI, Data API, workflows and data apps on a shared Iceberg lakehouse, with access policy enforced in Trino and StarRocks. Written in Rust.
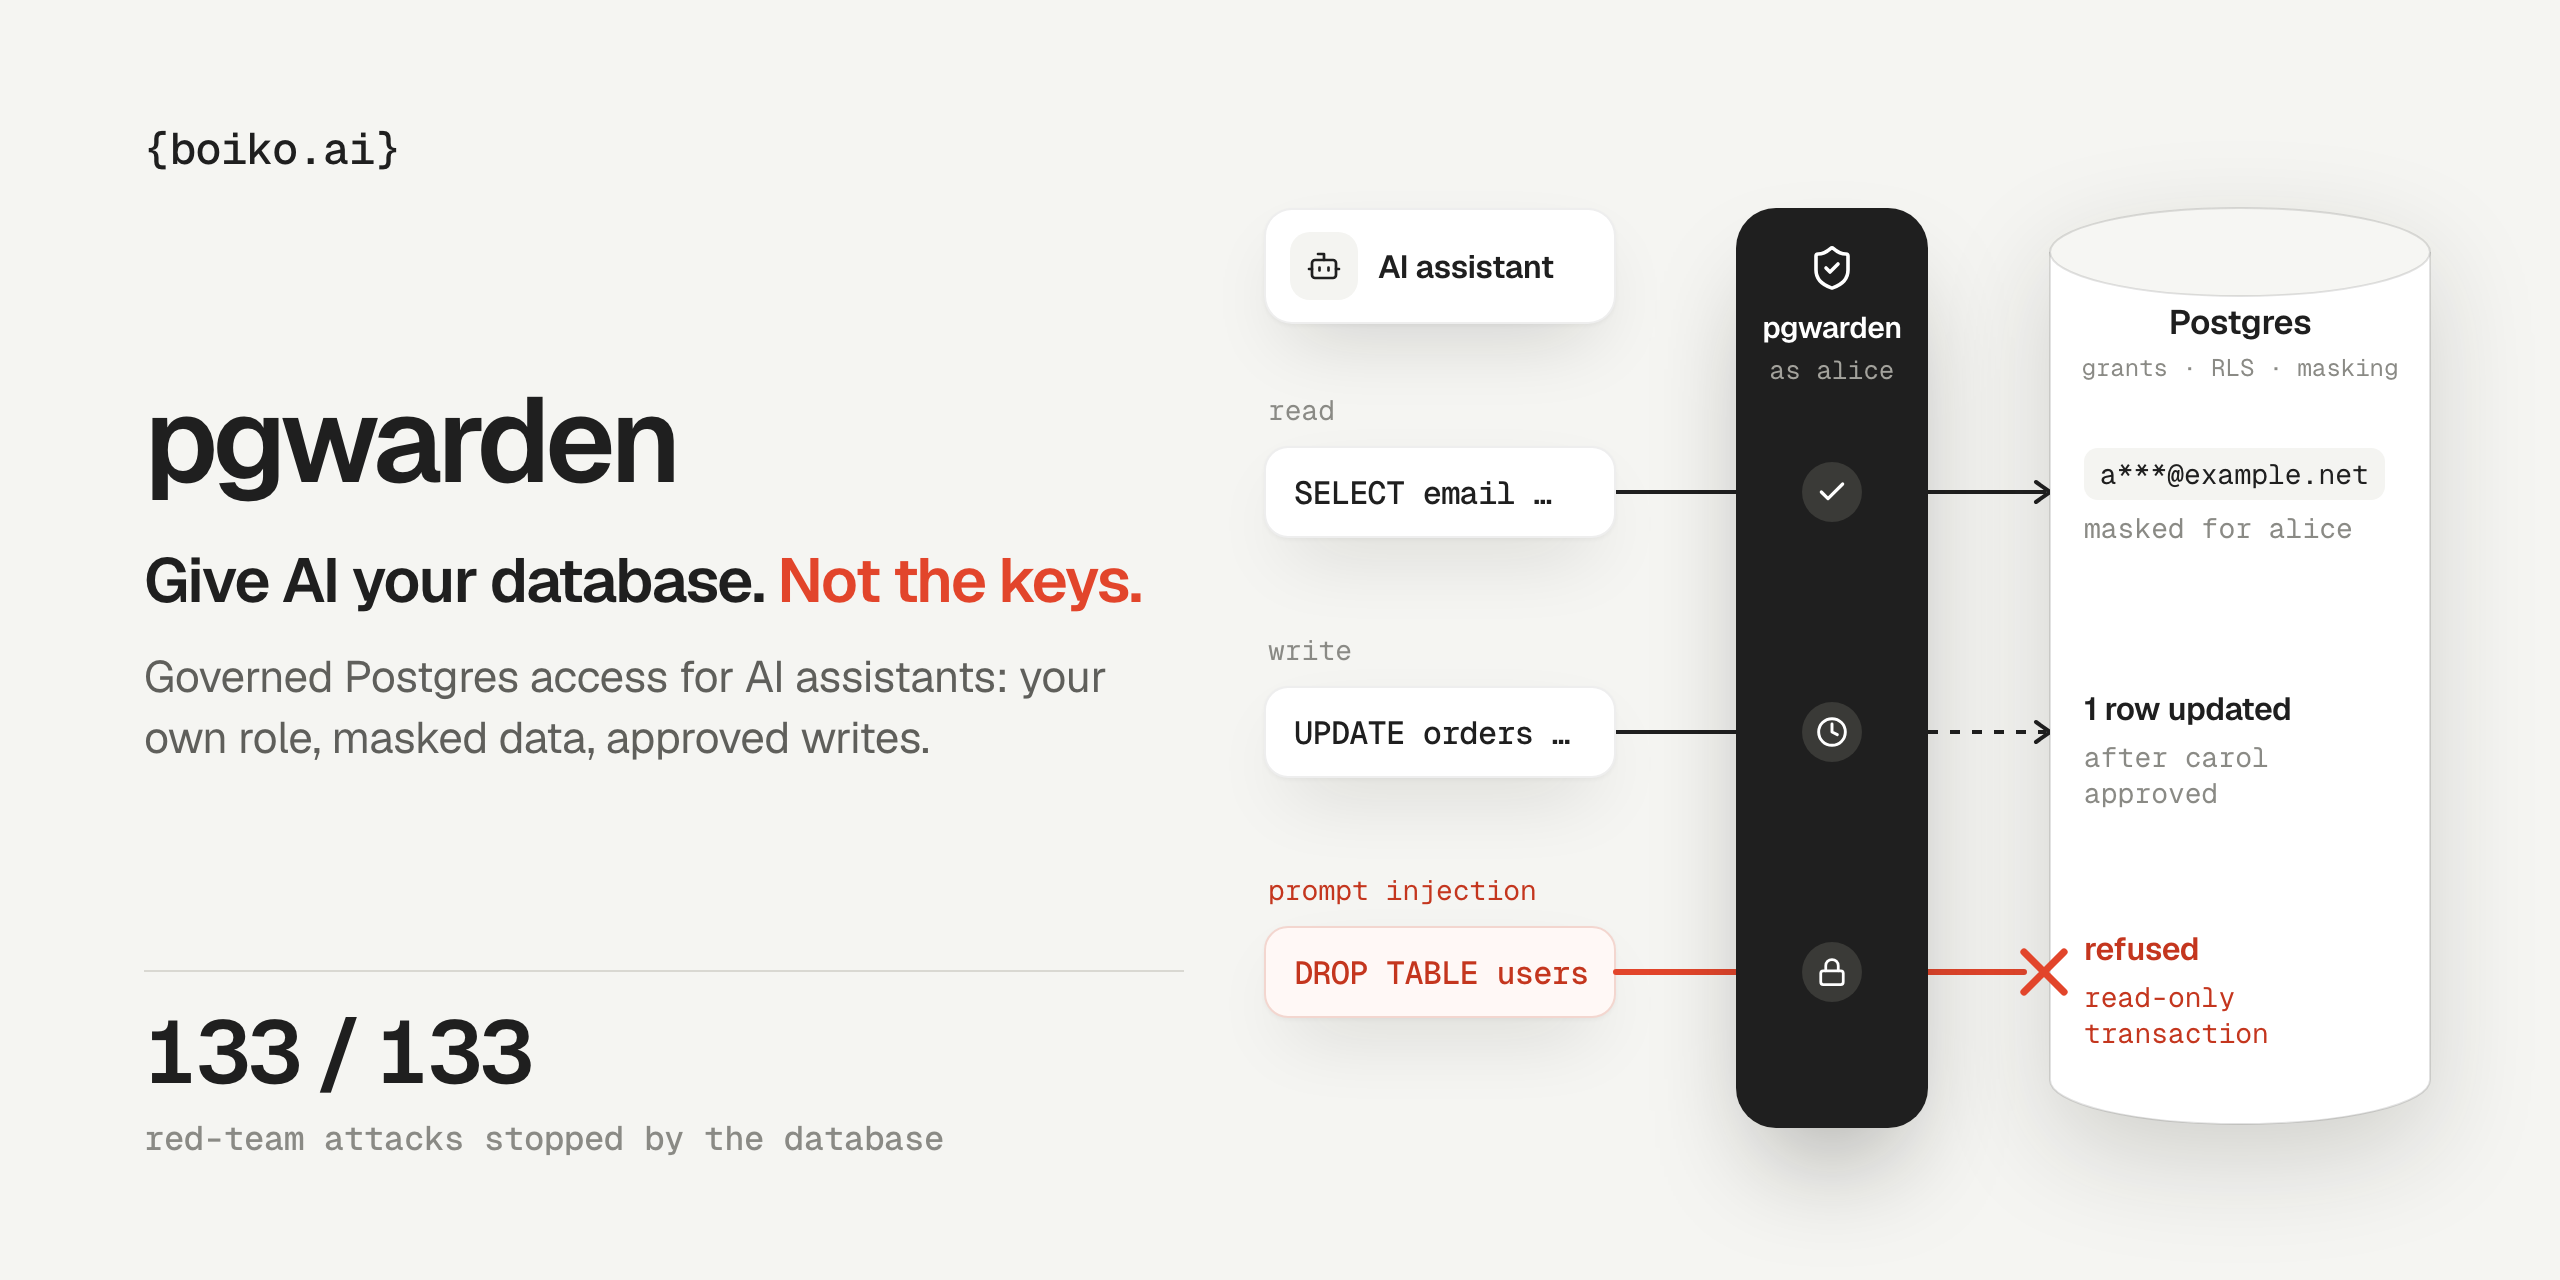
Give AI assistants access to Postgres with per-user permissions and human approval for writes.
This connector is a dbt project that maps Medicare CCLF claims data to the Tuva Input Layer.
High-performance, API-compatible drop-in replacement for Confluent Schema Registry. Avro, Protobuf & JSON Schema with PostgreSQL, MySQL, Cassandra storage. Built-in RBAC, client side field encryption, data contracts, audit logging. No Kafka dependency. Apache 2.0.
Data Workers MCP agents. Data Workers is the Autonomous Agentic Data Platform: reduce your data ops to zero, with agents that run the whole data platform. The platform lives at dataworkers.io.
An *open specification* multi-language, multi-protocol to describe your Data Protection rules and Personal Identifying Information as part of your schema
Maps Medicare LDS claims data to the Tuva Input Layer so you can easily run the Tuva Project.
A dbt project that transforms messy public provider datasets into usable data for the Tuva Project.
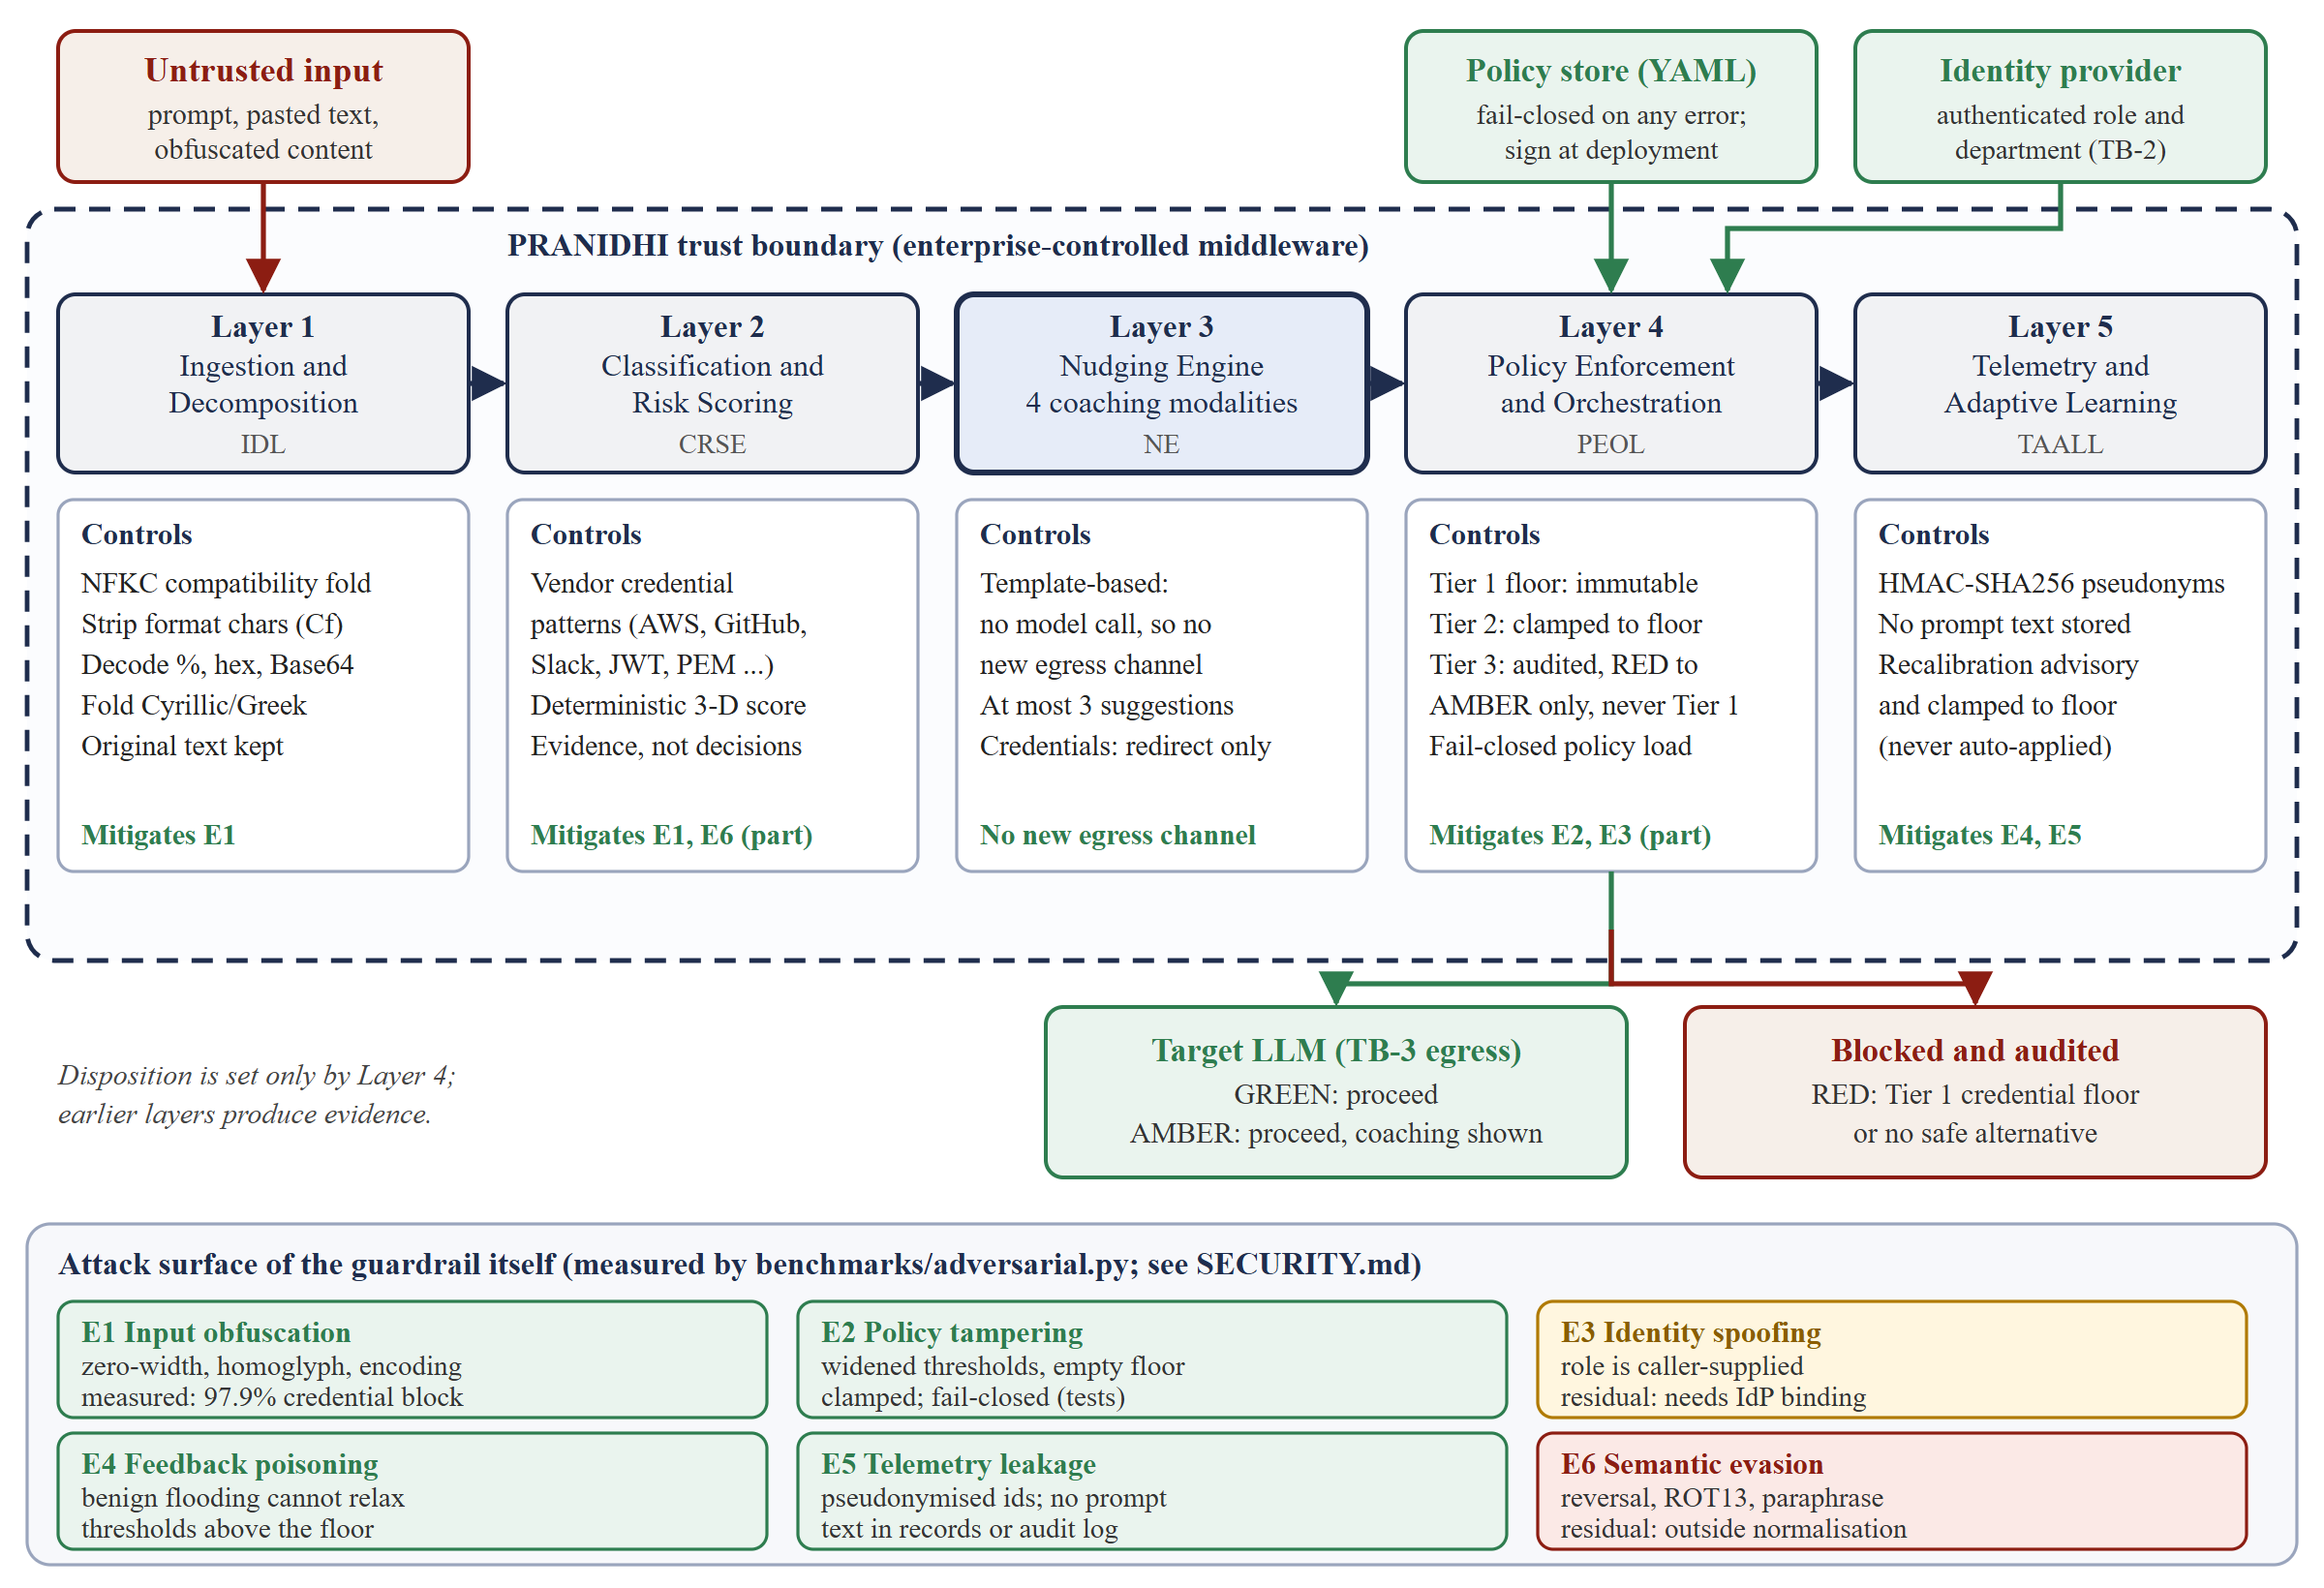
Pre-prompt coaching for enterprise AI: scores risky prompts, teaches users to rewrite them safely, and enforces tightening-only policy tiers. Security-hardened v0.2.0 with reproducible benchmarks.
Read-only CLI for Segment.com — inspect sources, destinations, tracking plans, transformations, delivery, audit trail. LLM-actionable.
This repository contains a set of three projects that showcase modern data engineering, reporting, and governance capabilities using Microsoft Fabric. The work is structured to represent the responsibilities of a Senior / Lead Analytics Engineer within a large energy company operating at scale.
Genesis Preflight is a zero-dependency Rust command-line tool that ensures your scientific datasets are AI-ready for the Genesis Mission by validating them against the full FAIR principles (Findable, Accessible, Interoperable, Reusable) and automatically generating all required documentation.
Policy-first API and policy gate for AI/CLI workflows: detect sensitive data, decide allow/transform/deny, and emit auditable receipts.
Text classification model, used with transformers.