gpu-telemetry
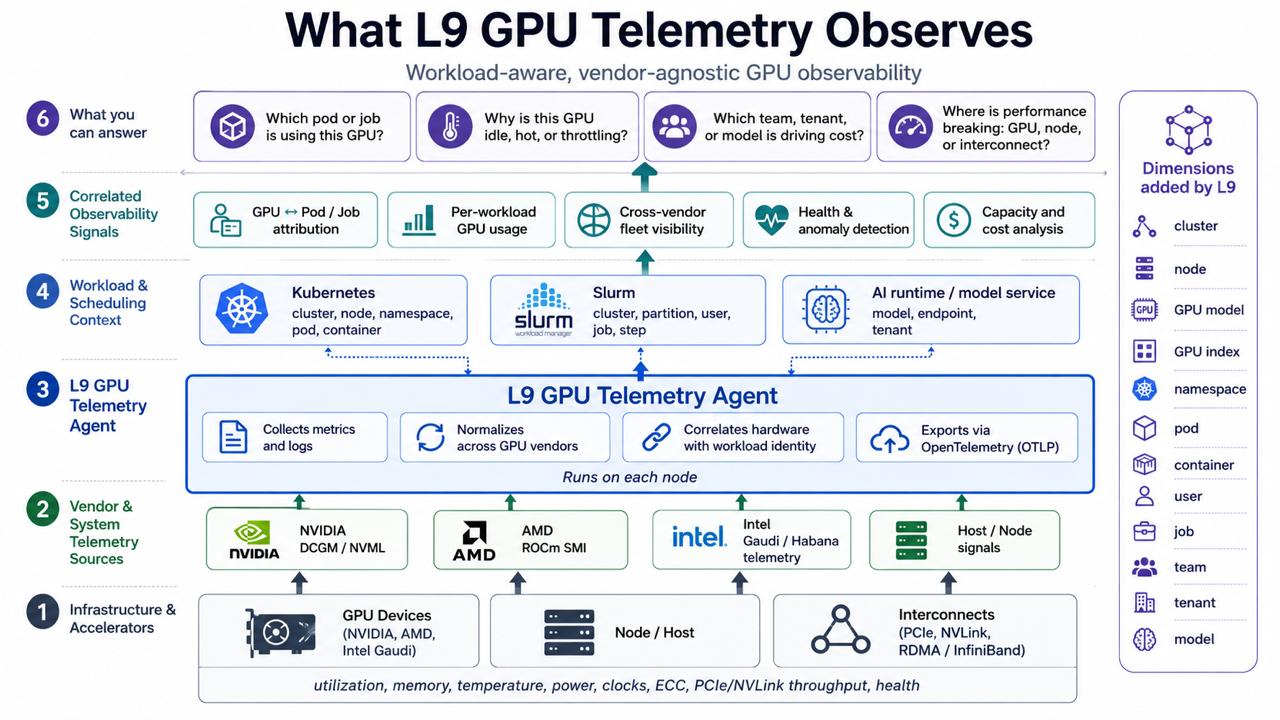
GPU Observability with workload attribution. One OTLP agent per node ties hardware metrics (NVIDIA, AMD, Intel Gaudi) to the K8s pod or Slurm job burning the GPU.
- 78
- Python
- MIT
- 3 wk ago
GPU Observability with workload attribution. One OTLP agent per node ties hardware metrics (NVIDIA, AMD, Intel Gaudi) to the K8s pod or Slurm job burning the GPU.
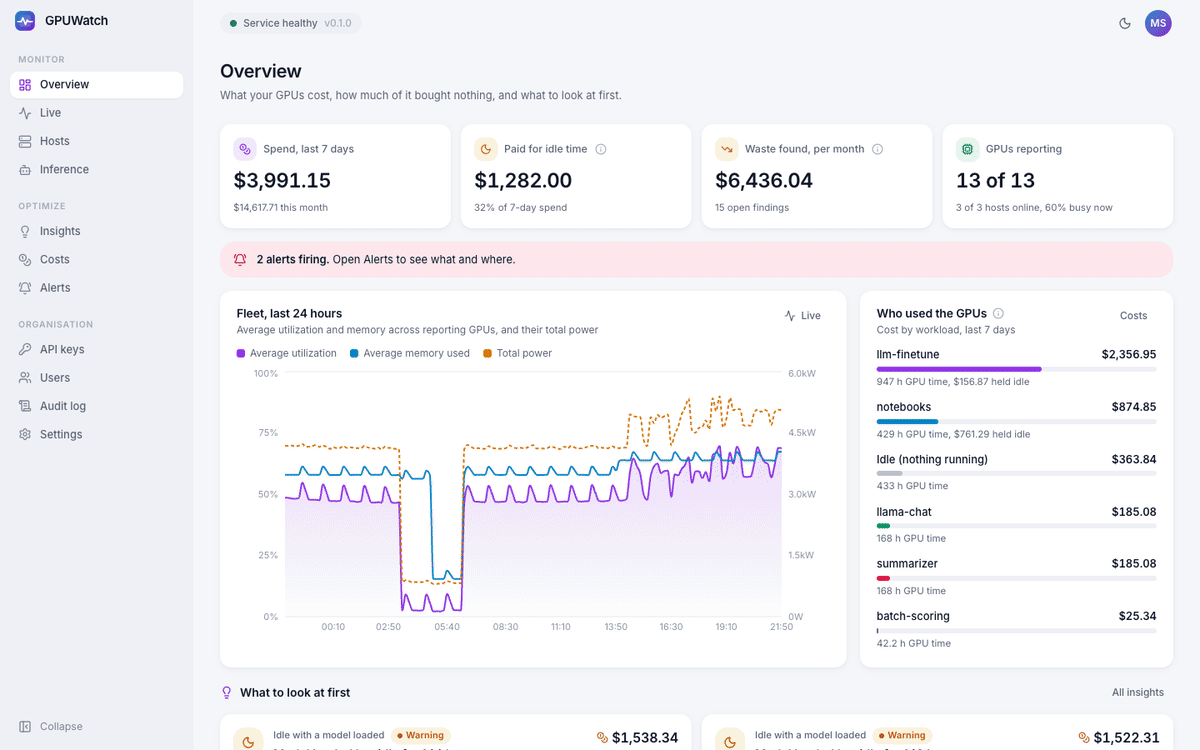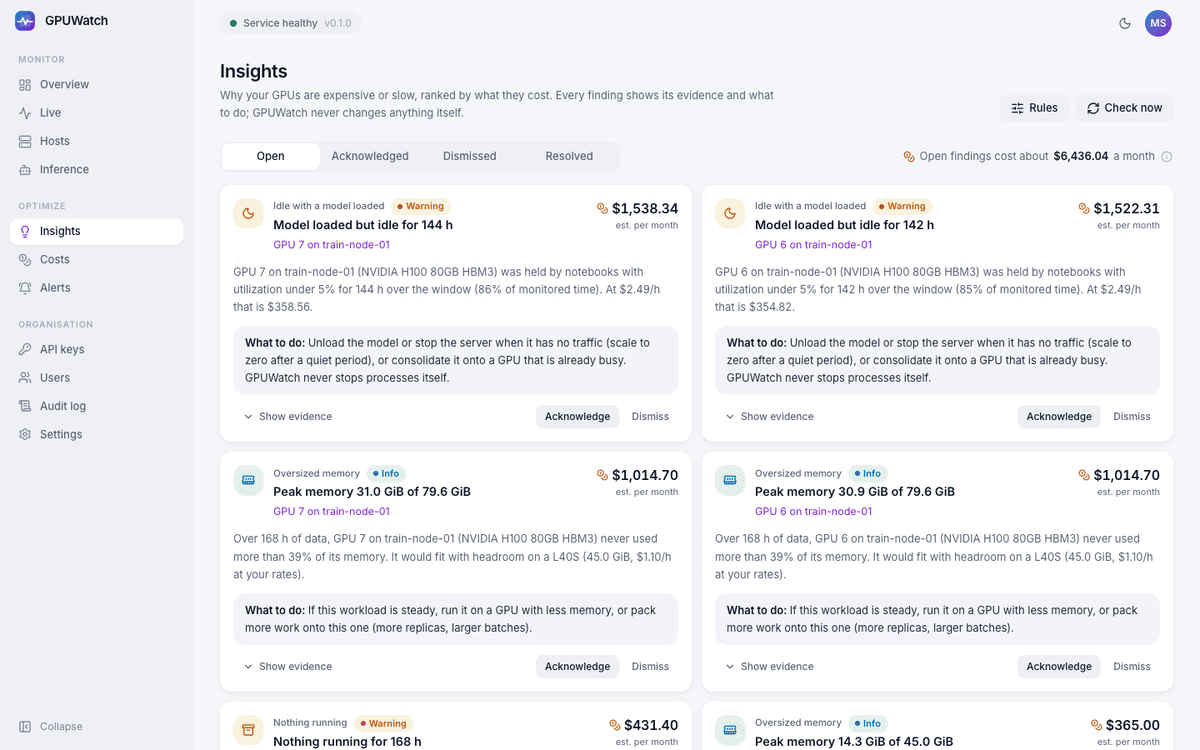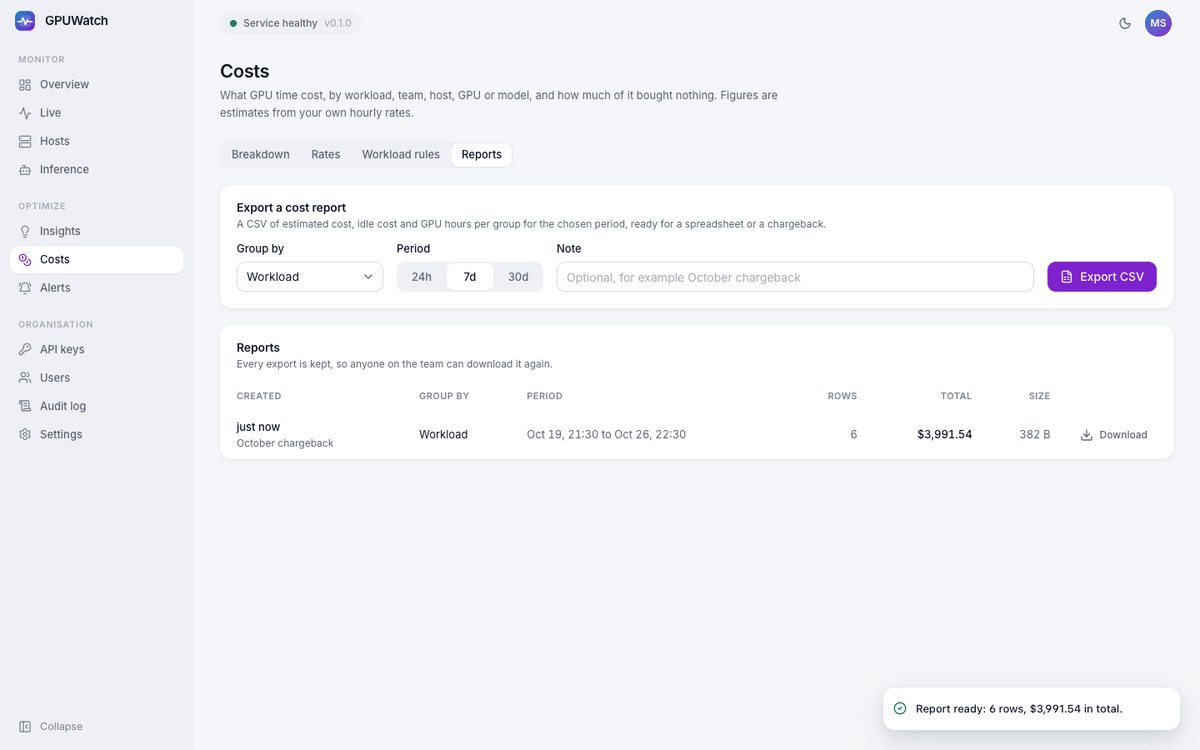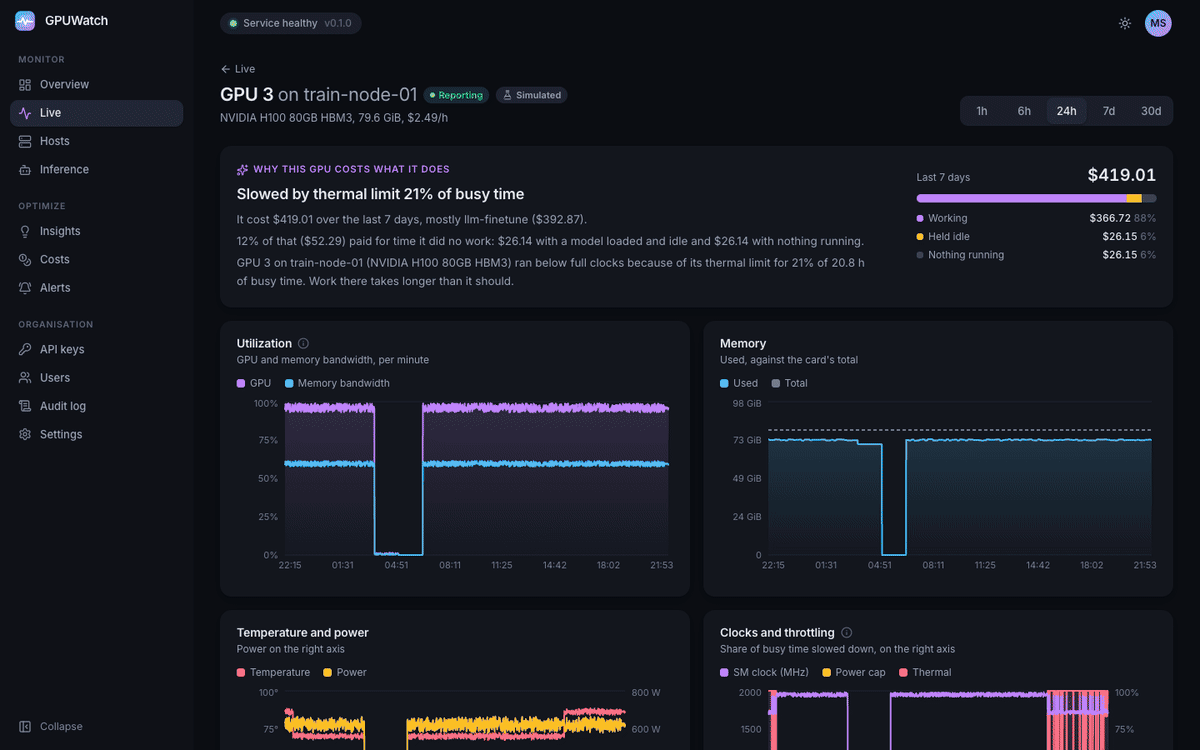
Self-hosted GPU monitoring and cost intelligence: live NVIDIA metrics, idle and waste detection, exact per-workload cost attribution, alerts and inference metrics, with a demo mode that needs no GPU.
Production LLM serving infrastructure using Triton Inference Server, vLLM, and Ray Serve with OpenAI-compatible endpoints. Includes Kubernetes autoscaling configs driven by DCGM GPU metrics and a BentoML packaging path for portable model deployment.