SageAttention
[ICLR2025, ICML2025, NeurIPS2025 Spotlight] Quantized Attention achieves speedup of 2-5x compared to FlashAttention, without losing end-to-end metrics across language, image, and video models.
- 4k
- Cuda
- Apache-2.0
- 10 mo ago
[ICLR2025, ICML2025, NeurIPS2025 Spotlight] Quantized Attention achieves speedup of 2-5x compared to FlashAttention, without losing end-to-end metrics across language, image, and video models.
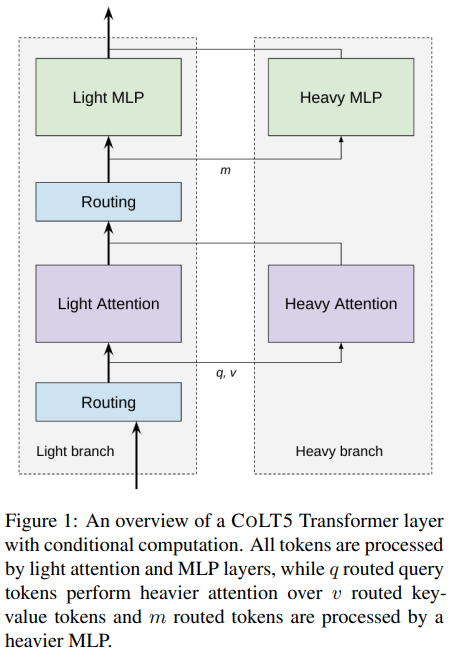
Implementation of the conditionally routed attention in the CoLT5 architecture, in Pytorch