LLMCompiler
[ICML 2024] LLMCompiler: An LLM Compiler for Parallel Function Calling
- 1.9k
- Python
- MIT
- 2 y ago
[ICML 2024] LLMCompiler: An LLM Compiler for Parallel Function Calling
A curated collection of papers, benchmarks, surveys, and tools for model quantization, covering low-bit networks, LLMs, multimodal and generative models, vector and lattice quantization, and efficient deployment.
Efficient AI Backbones including GhostNet, TNT and MLP, developed by Huawei Noah's Ark Lab.
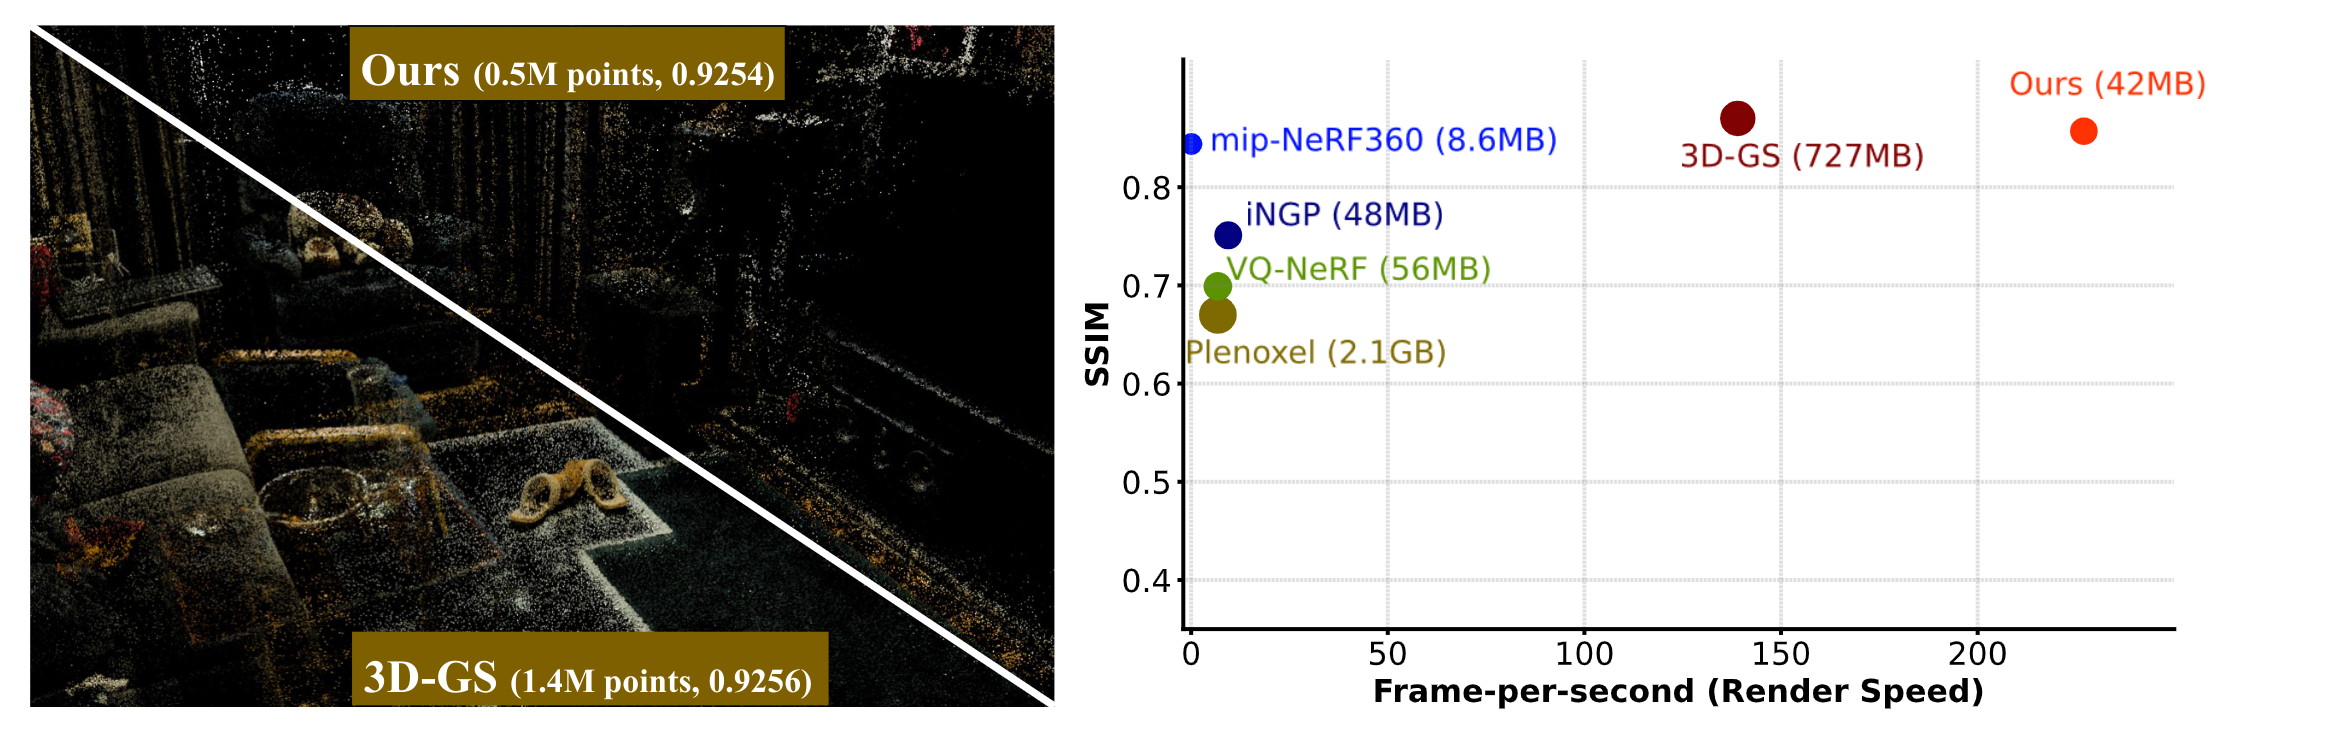
[NeurIPS 2024 Spotlight]"LightGaussian: Unbounded 3D Gaussian Compression with 15x Reduction and 200+ FPS", Zhiwen Fan, Kevin Wang, Kairun Wen, Zehao Zhu, Dejia Xu, Zhangyang Wang
List of papers related to neural network quantization in recent AI conferences and journals.
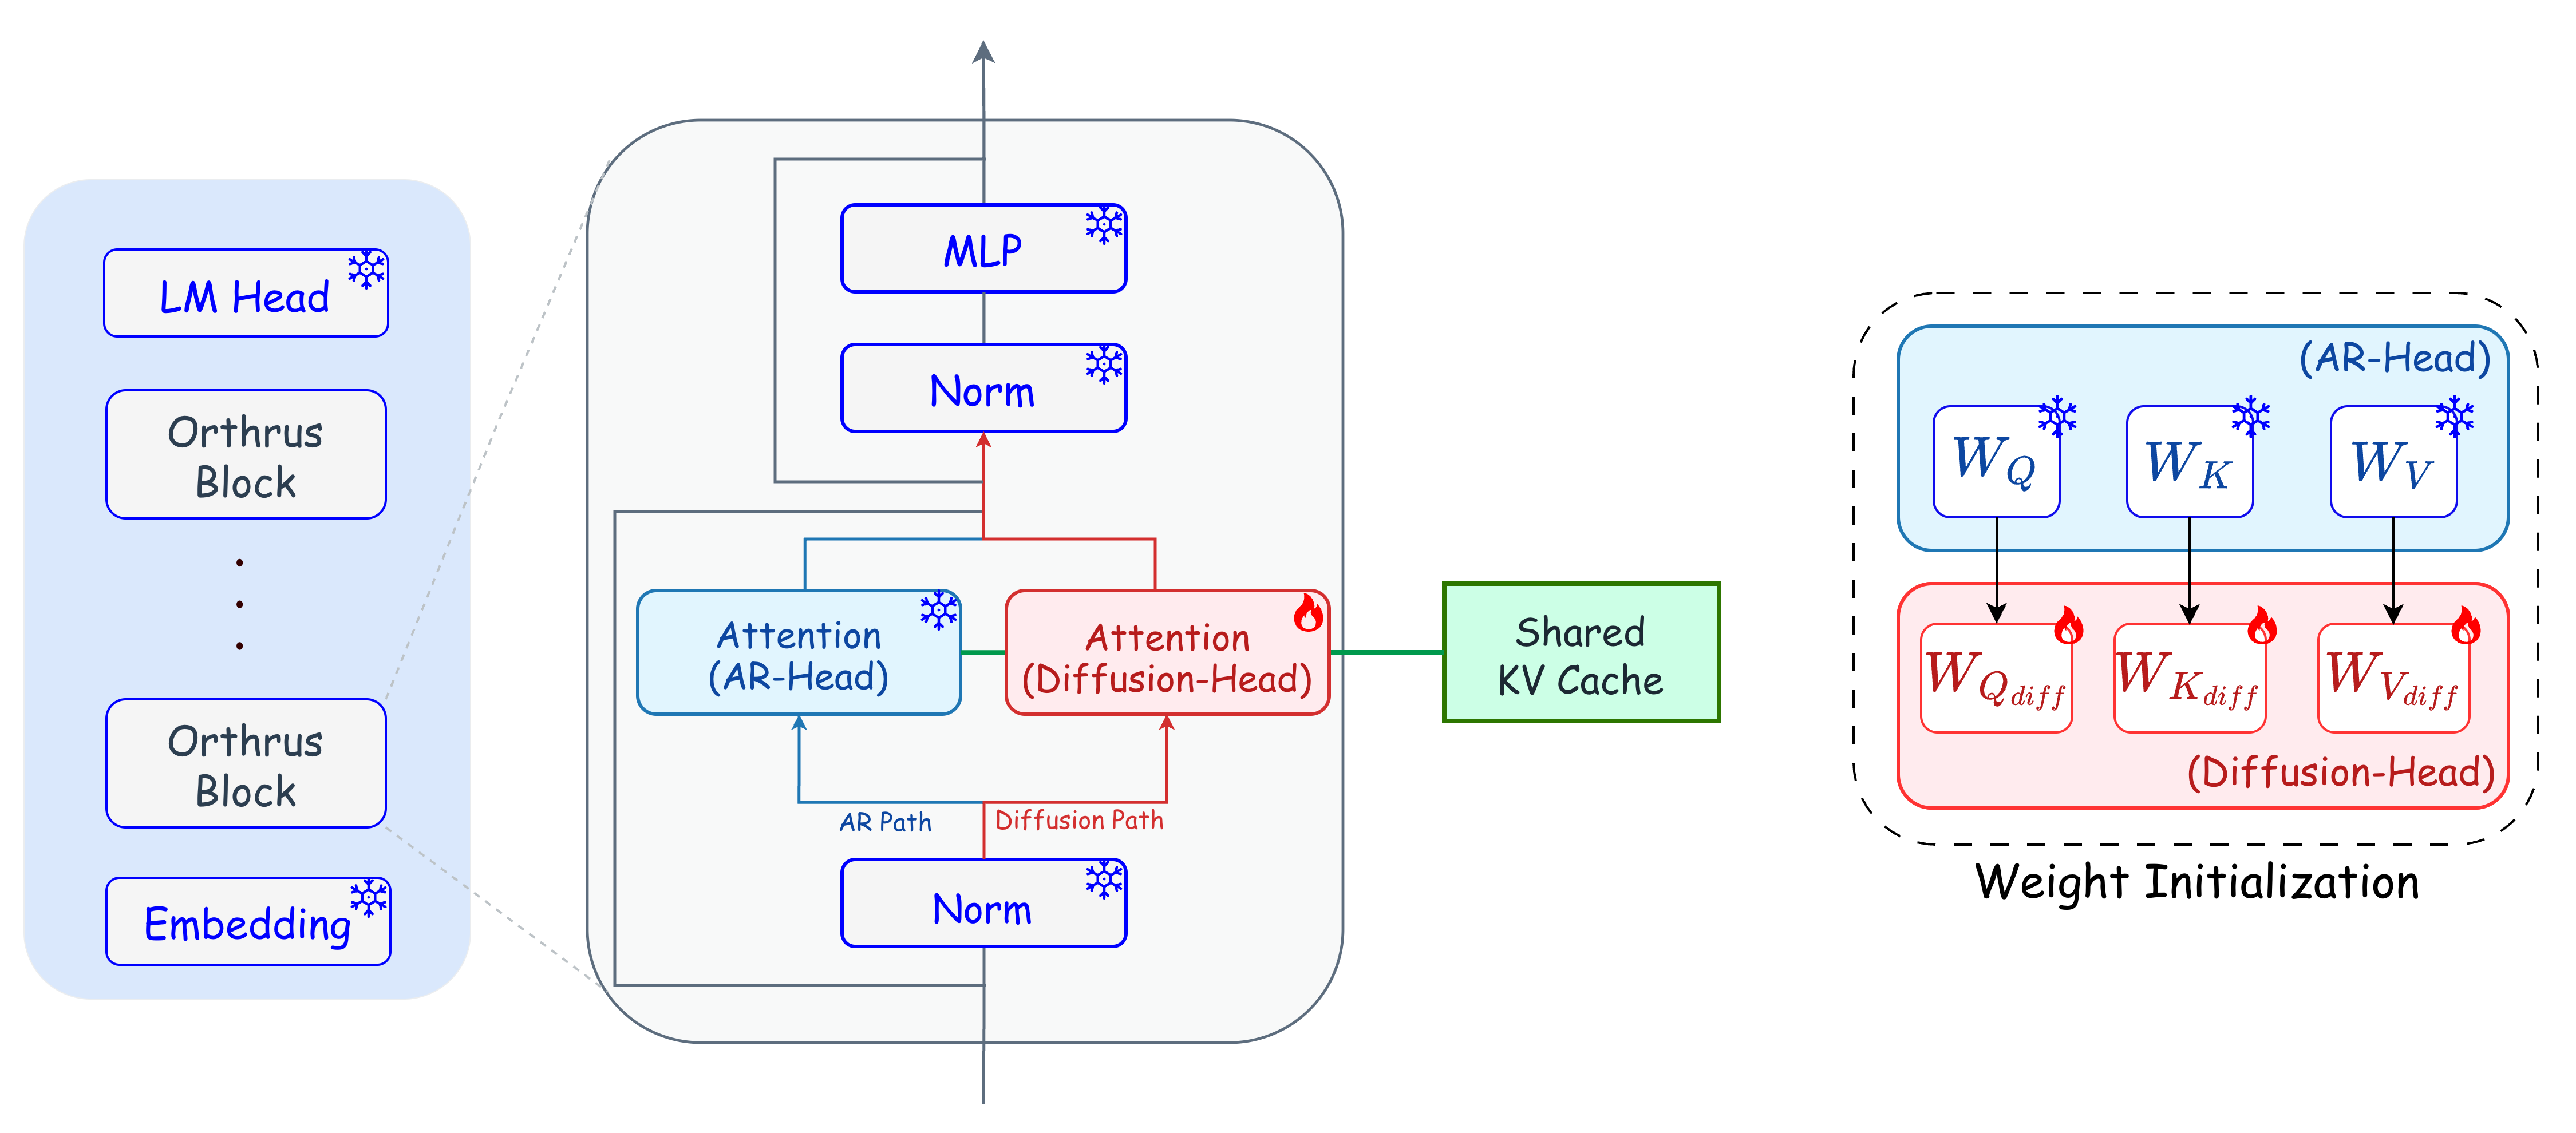
[NeurIPS 2026 Spotlight] Fast, lossless LLM inference via dual-view diffusion decoding.
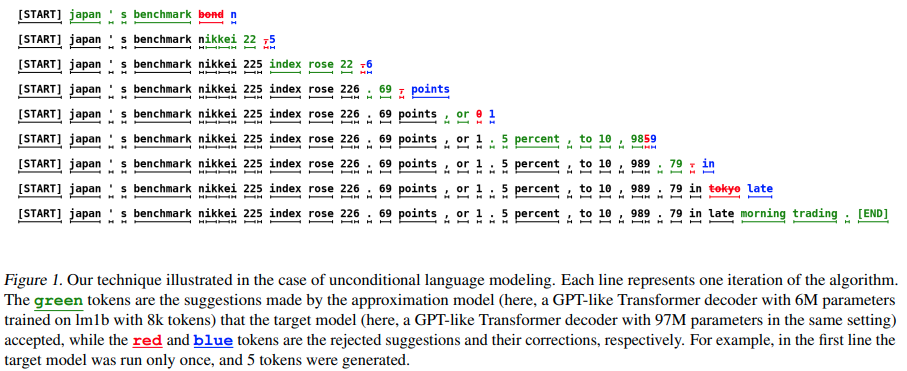
Explorations into some recent techniques surrounding speculative decoding
A curated list of papers and code on efficient diffusion models for image, video, world modeling, and language generation. Covering acceleration, quantization, compression, caching, and distillation.
Official implementation of "AReA: Adaptive Receptive-Field Attention for Efficient High-Resolution Diffusion Transformers"
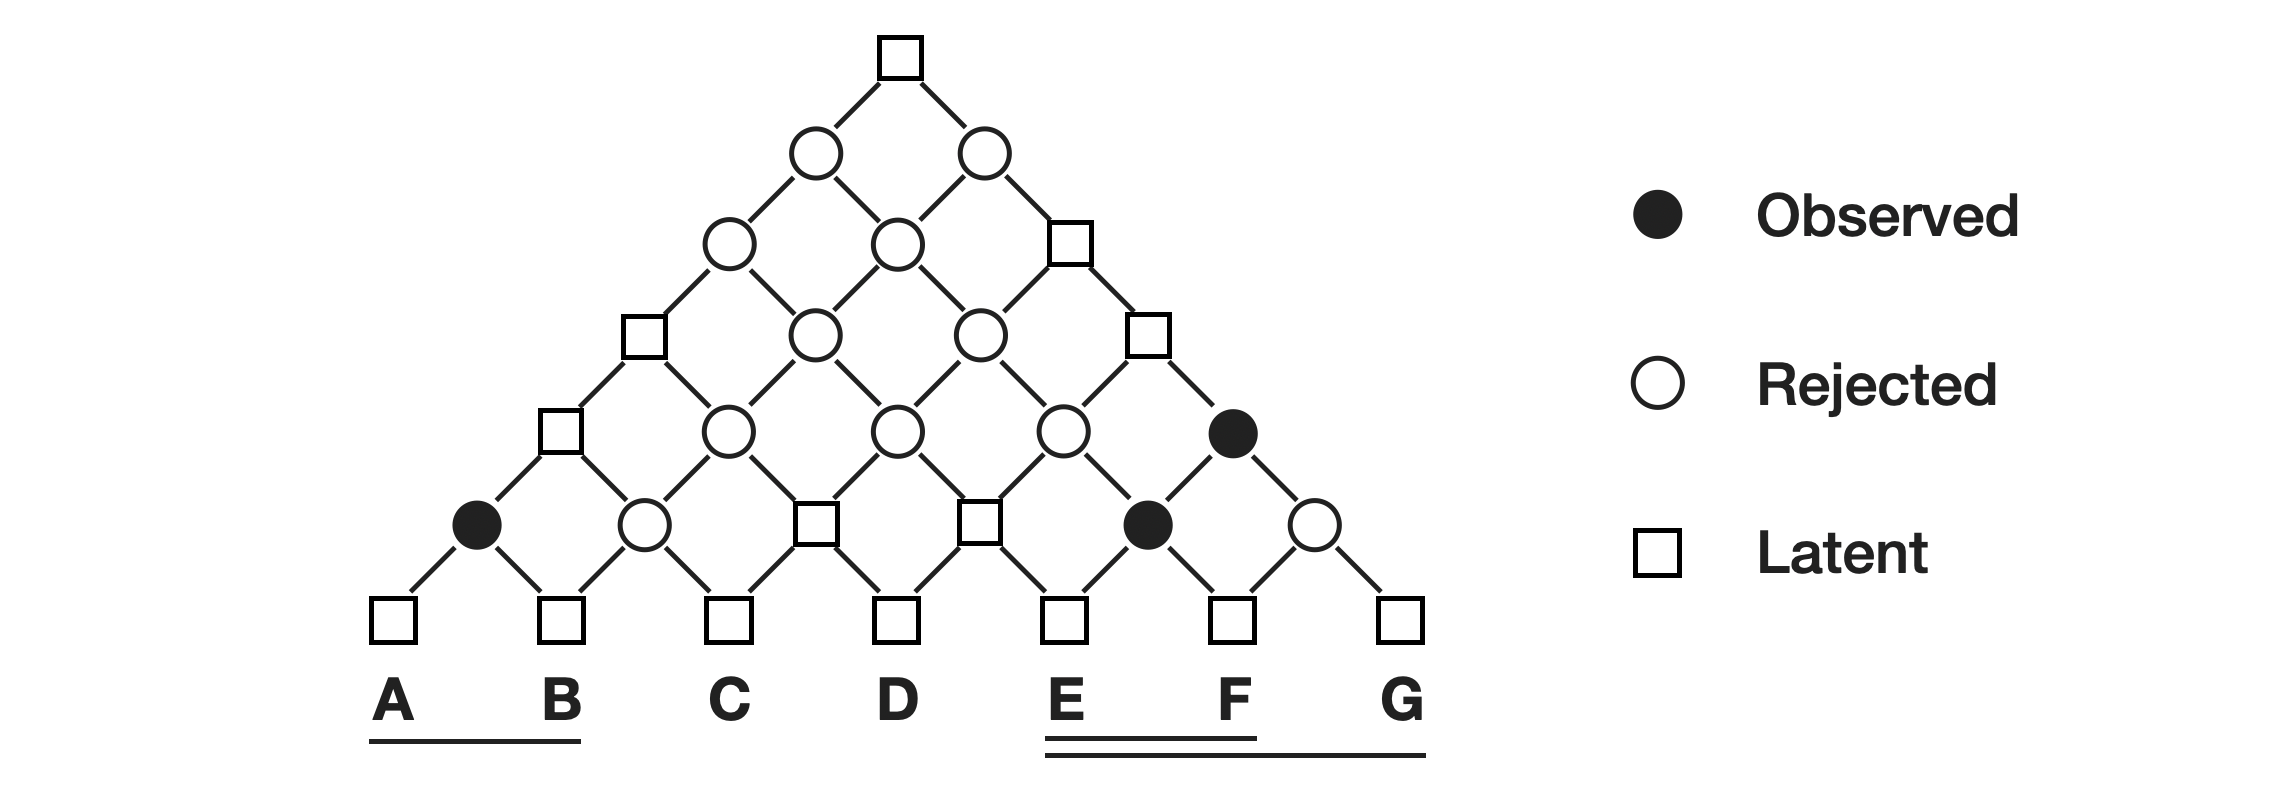
Implementation of AAAI 21 paper: Nested Named Entity Recognition with Partially Observed TreeCRFs
Implementation of ICML 22 Paper: Scaling Structured Inference with Randomization