Speech-AI-Forge
🍦 Speech-AI-Forge is a project developed around TTS generation model, implementing an API Server and a Gradio-based WebUI.
- 1.4k
- Python
- AGPL-3.0
- 6 mo ago
🍦 Speech-AI-Forge is a project developed around TTS generation model, implementing an API Server and a Gradio-based WebUI.
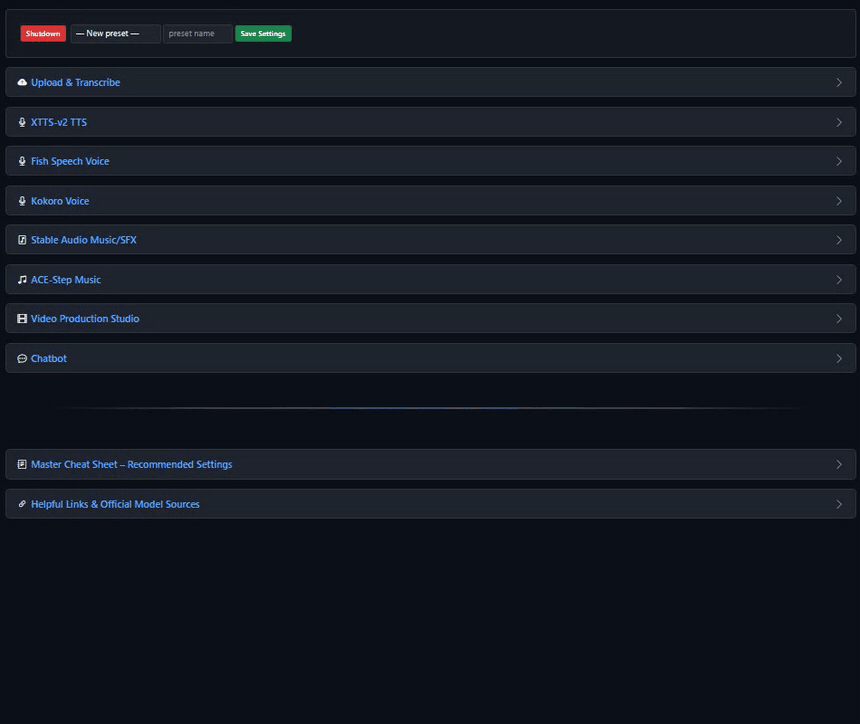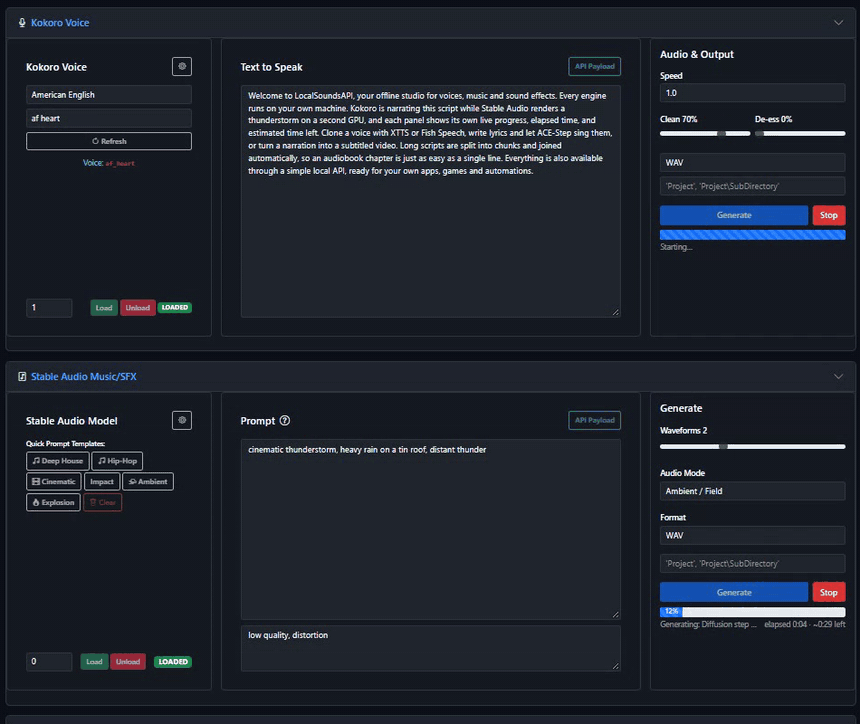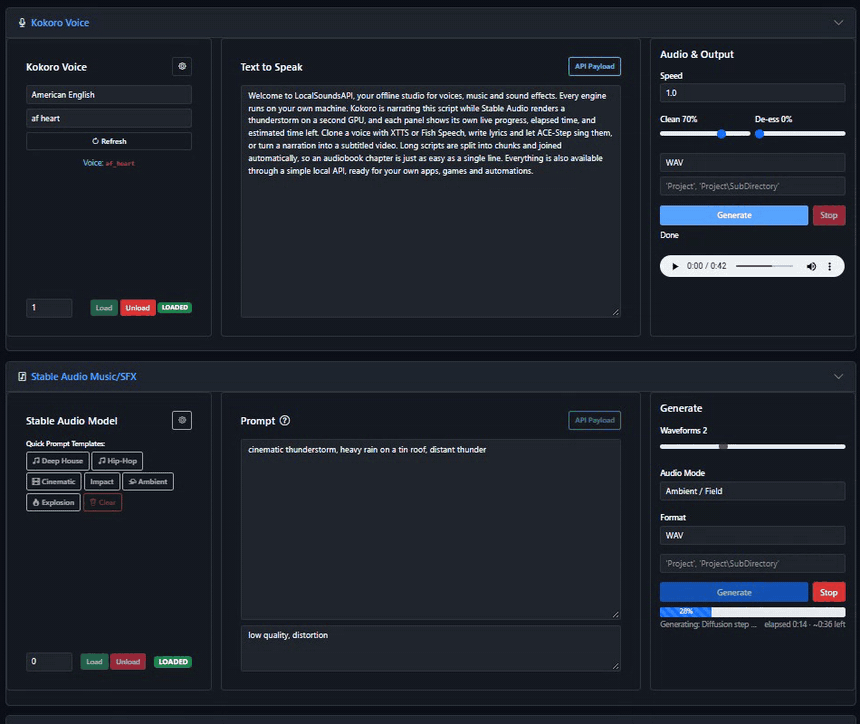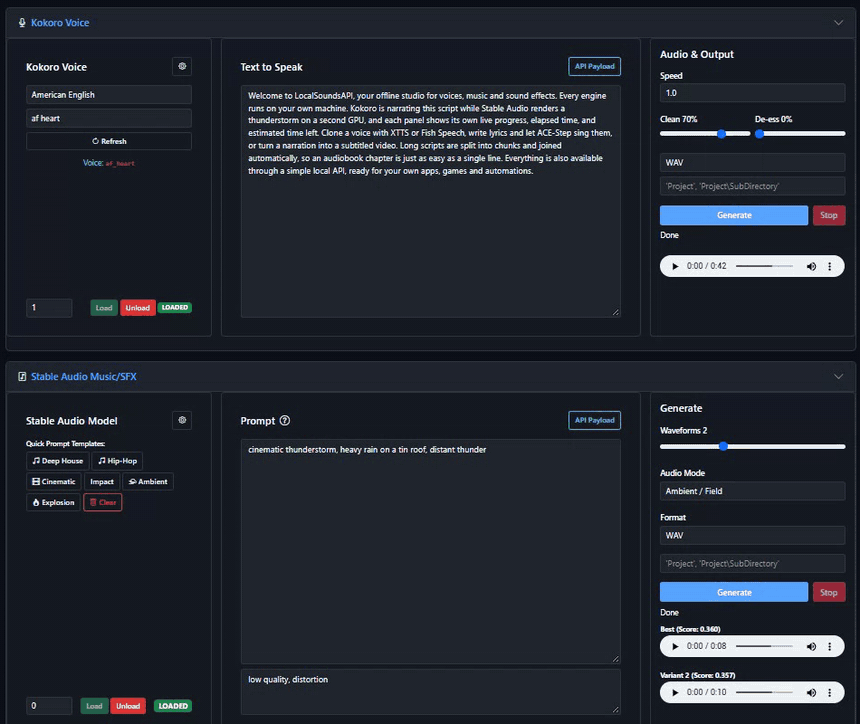
Portable offline AI audio studio with web UI & local API – XTTS, Fish Speech, Kokoro, Stable Audio, ACE-Step, voice cloning, music gen (no install)
19 speech engines + Whisper: Kokoro, XTTS v2, F5-TTS, Chatterbox, Fish Speech, Bark, Dia, Higgs Audio, Qwen Omni, VibeVoice, SpeechT5, Parler, OuteTTS, VITS, Edge, Voxtral, VoxCPM2, CSM and Orpheus. Voice cloning, SRT, audio editor, CLI/API. Offline Kokoro included. From portable-linux-in-a-box.
Open text-to-speech engines on one platform: CosyVoice, F5-TTS, GPT-SoVITS, OmniVoice, Qwen3-TTS, VoxCPM, Fish Speech and IndexTTS. They share one web UI, one command line and one HTTP API. Speak, clone and design voices, convert and edit speech, read whole books with a cast of voices, and fine-tune models on your own recordings.
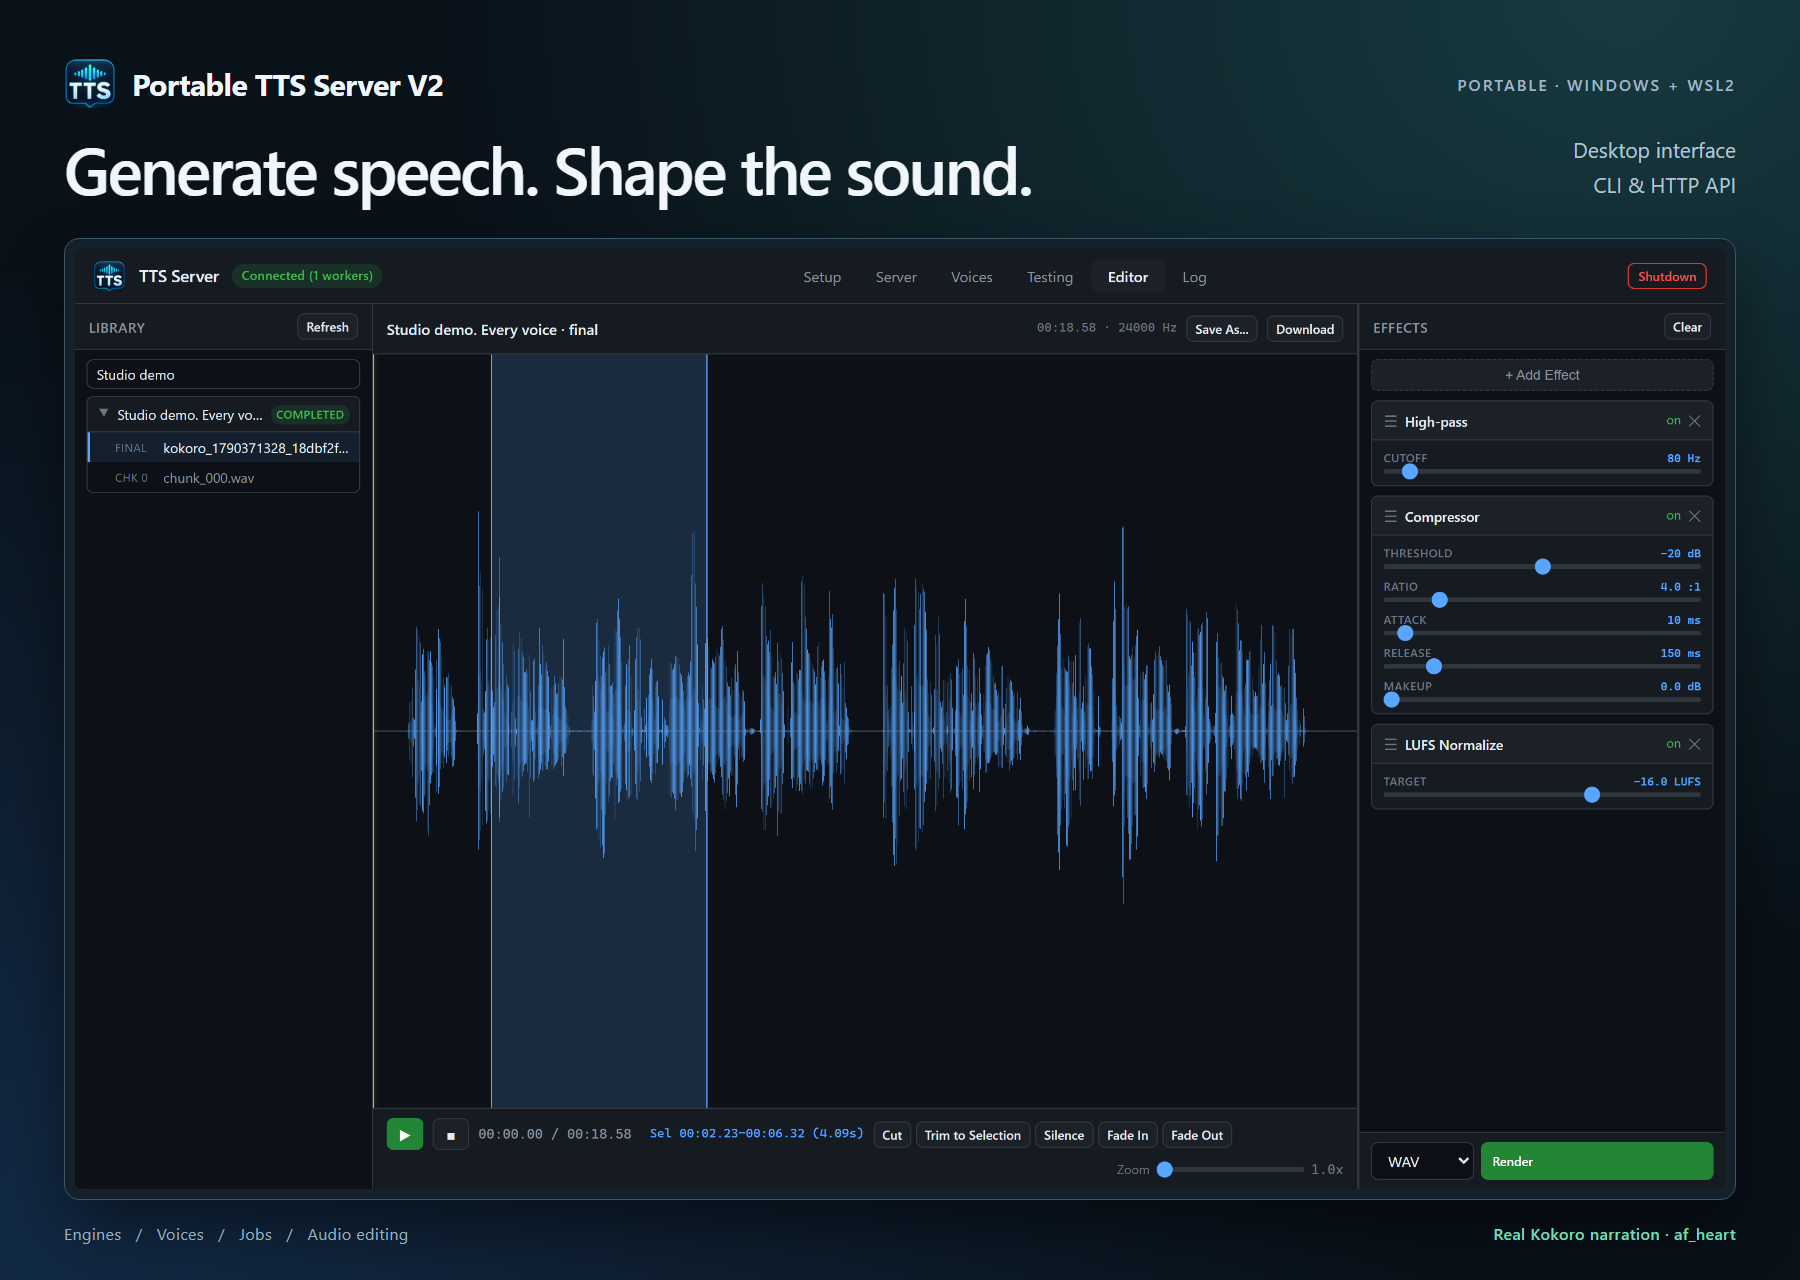
Portable multi-GPU text-to-speech server for Windows — 10 AI models, gateway + worker architecture, 7-stage audio pipeline, Whisper verification, one-click install (no system Python, no Docker, no admin rights)
FastAPI wrapper for Fish Audio S2 Pro via local s2.cpp/FishS2Sharp runtime.