mmaemu
Bit-exact emulation of NVIDIA tensor-core FP8 GEMMs (torch._scaled_mm, Transformer Engine) as an H100 PCIe or RTX 4060 computes them, on the CPU or another CUDA GPU
- 64
- Python
- Apache-2.0
- 9 d ago
Bit-exact emulation of NVIDIA tensor-core FP8 GEMMs (torch._scaled_mm, Transformer Engine) as an H100 PCIe or RTX 4060 computes them, on the CPU or another CUDA GPU
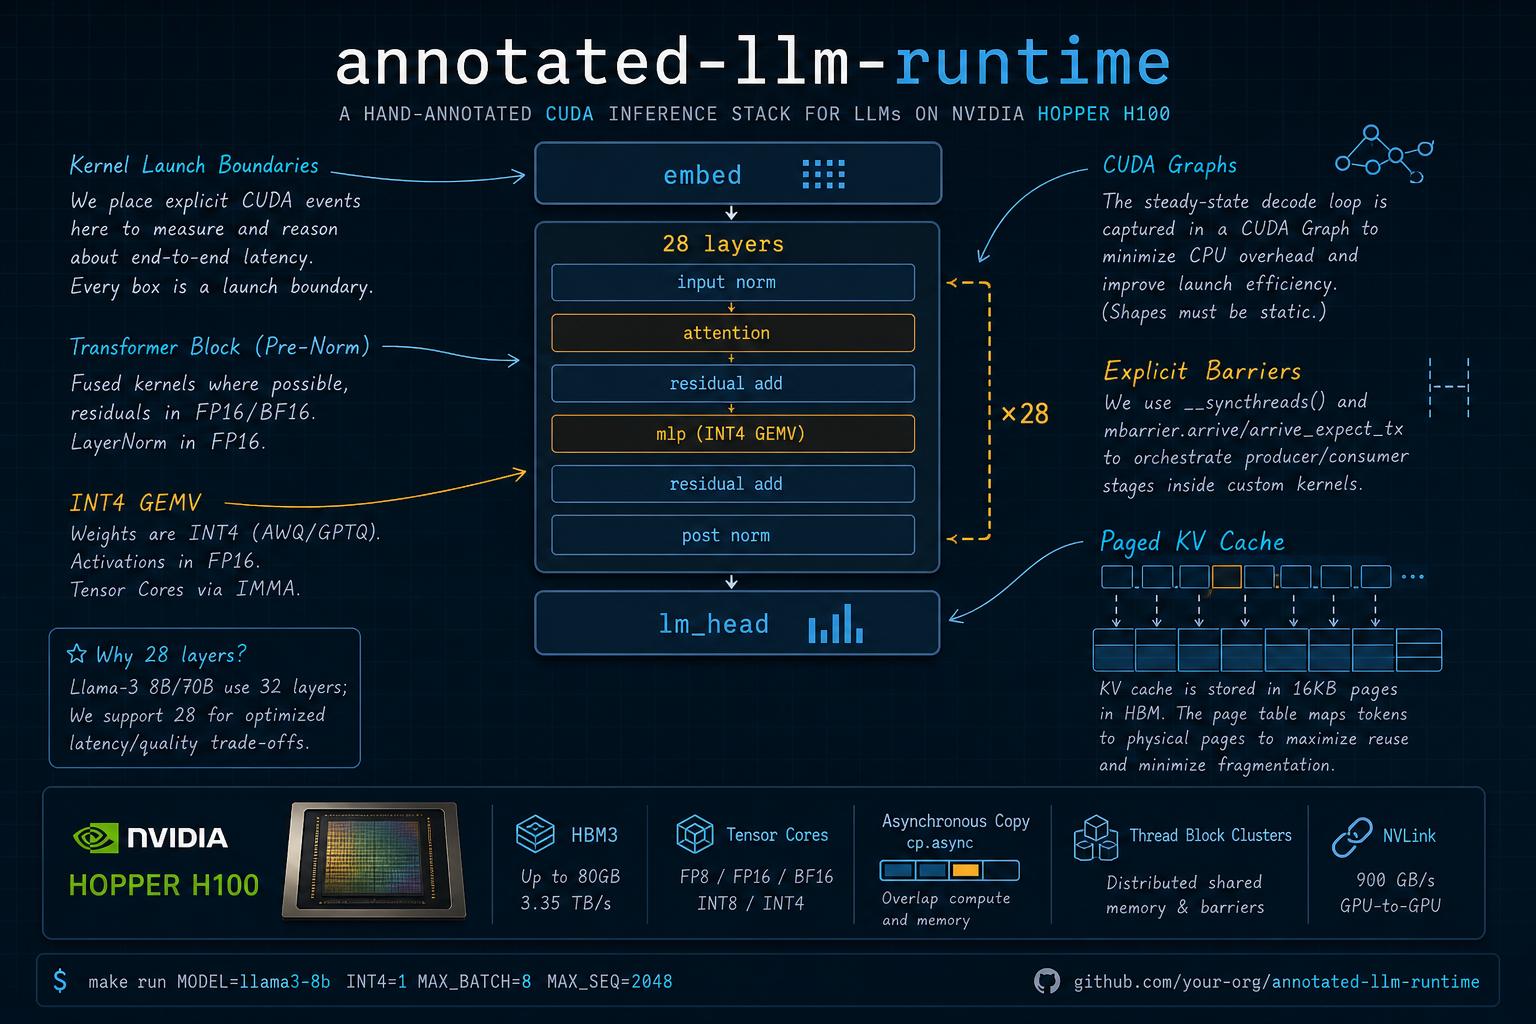
From-scratch, heavily-annotated CUDA inference runtime for Qwen2.5-Coder-7B on H100 (sm_90). Custom INT4 packer, fused GEMV, paged KV, split-KV attention, CUDA graph decode — every hot path commented for the why. Educational, not a llama.cpp replacement.
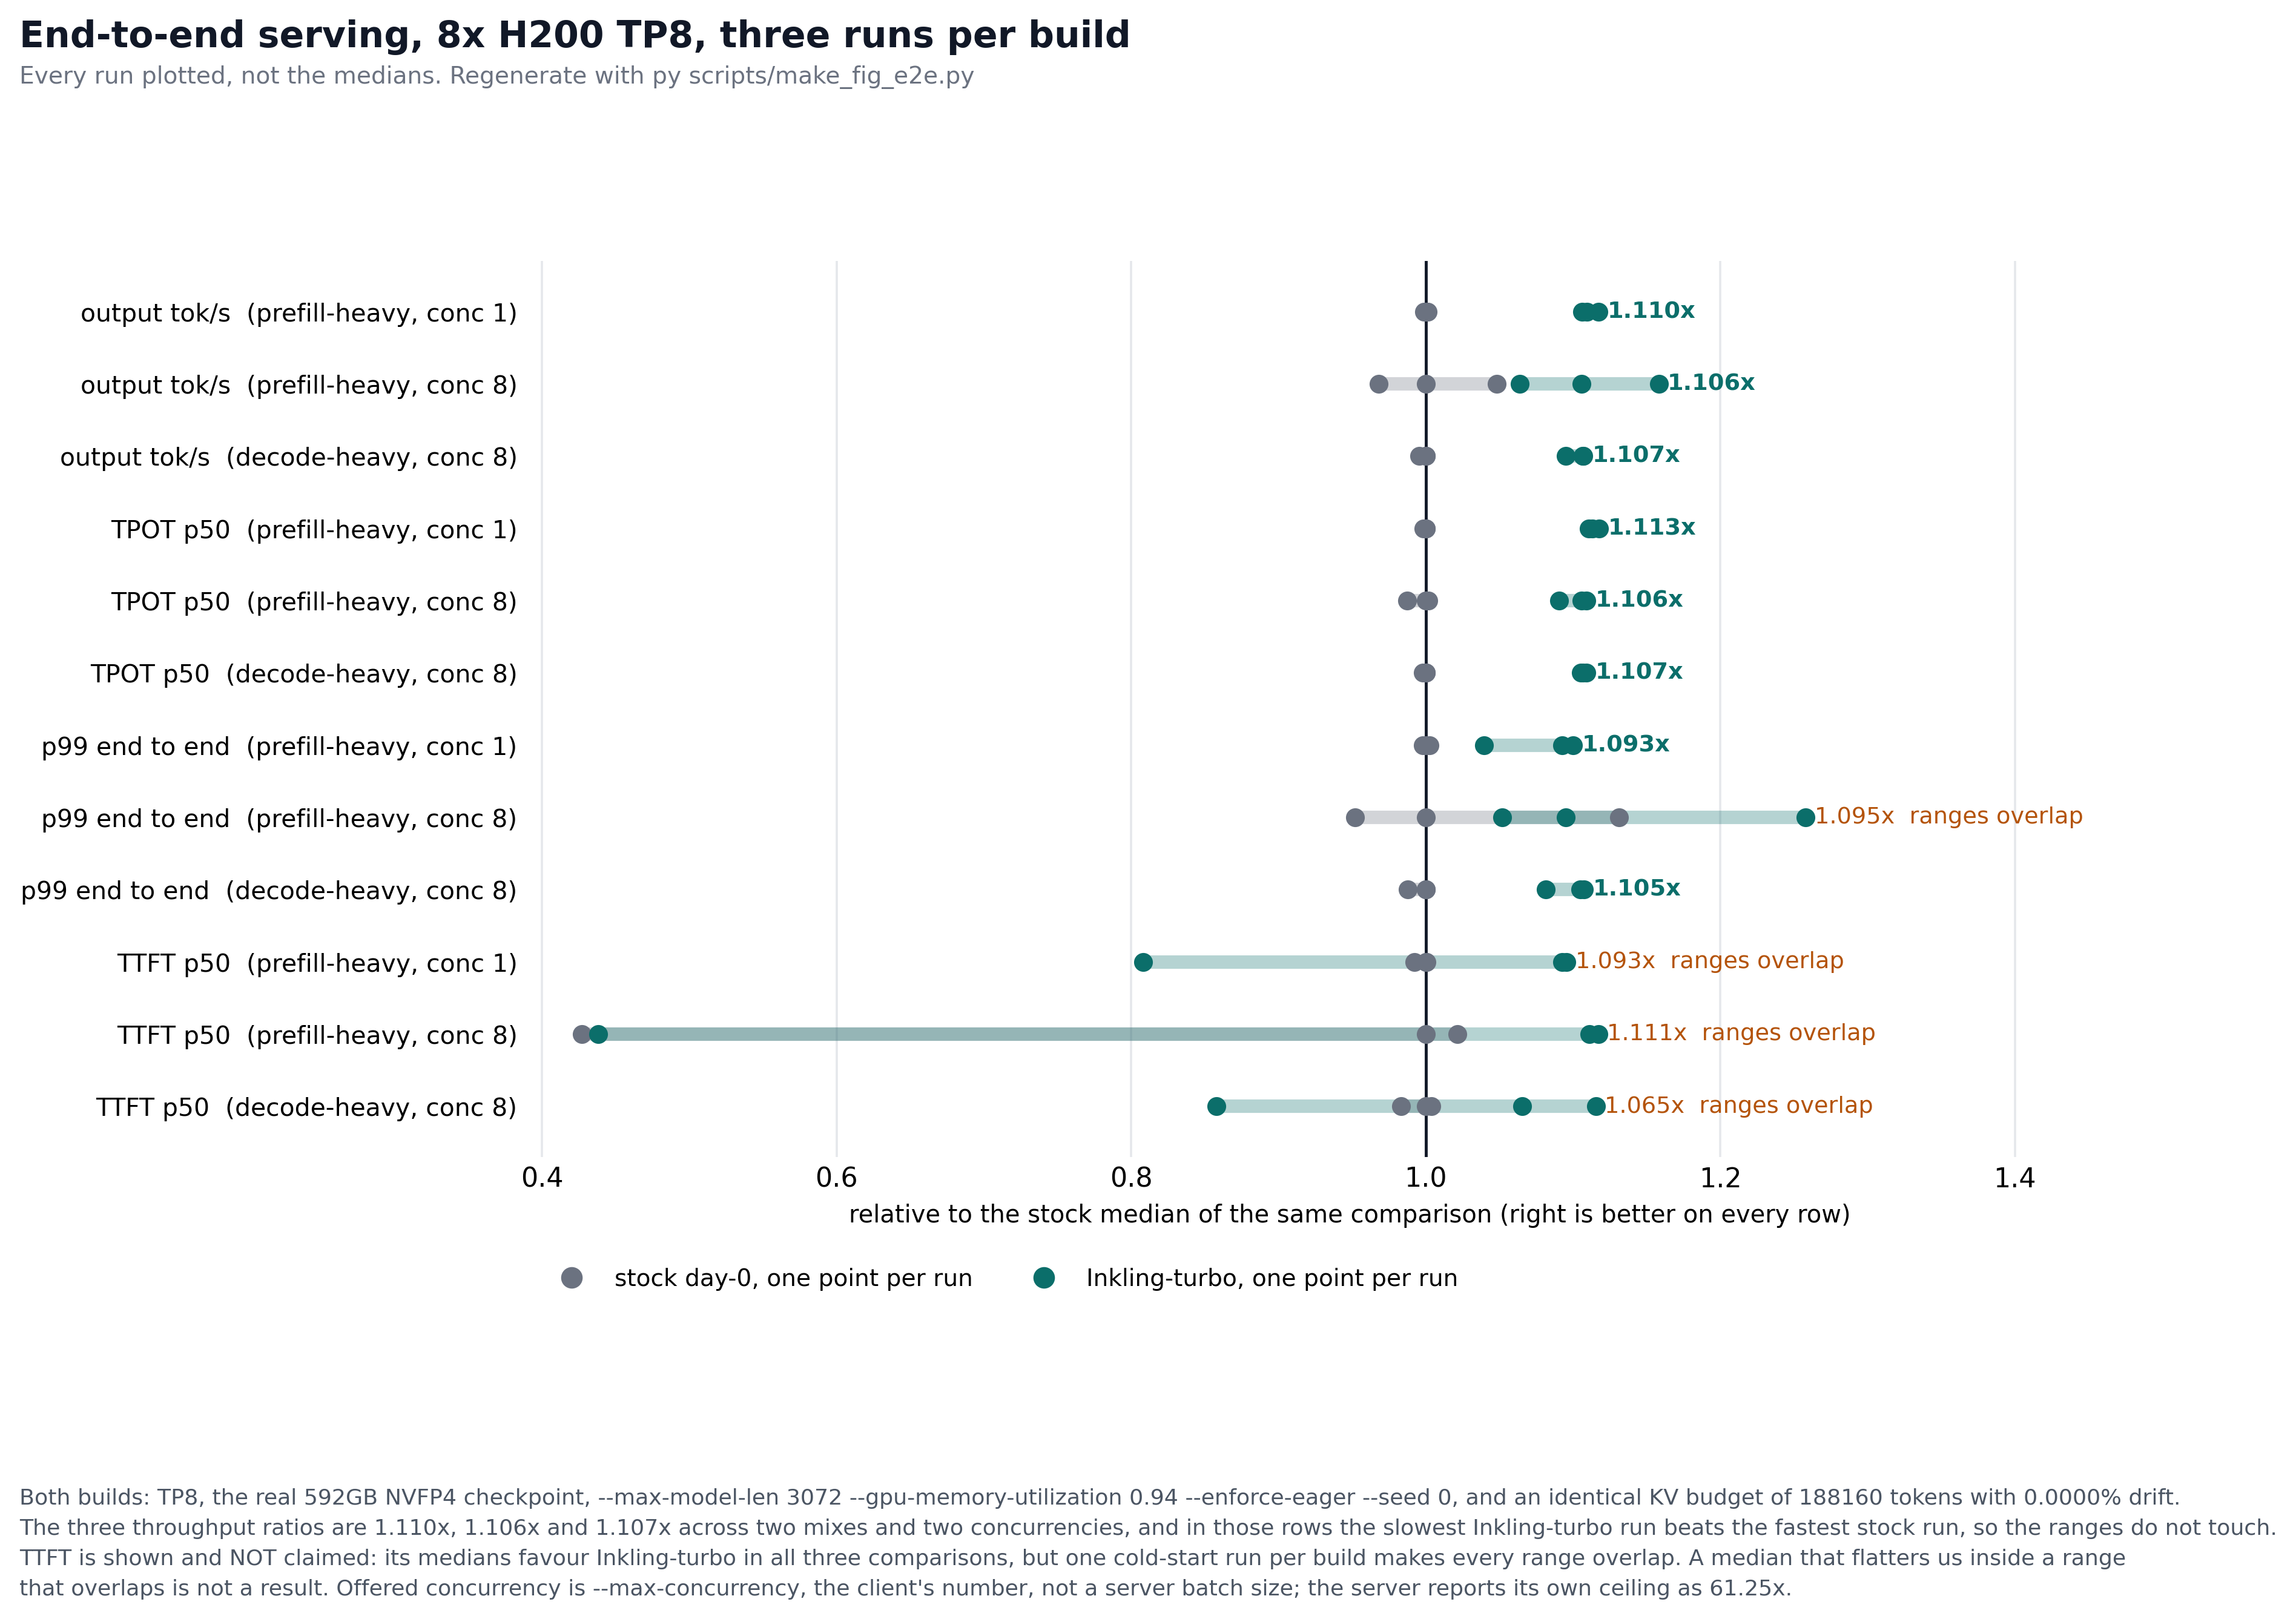
Faster attention kernels for serving TML's Inkling model on vLLM. 2.7x over the shipping path on H100, and the only implementation that runs on A100.
A single executable notebook showing how to use turbopairformer, developed by Lambda, Stevens Institute of Technology, and OpenFold — standalone CUDA kernels for the two most expensive operations in an AlphaFold3-style pair stack.
Does prefill/decode disaggregation pay for an MoE model? SLO-first goodput benchmark of Qwen3-30B-A3B on 4x H100 and 8x A100 with vLLM, llm-d and NVIDIA Dynamo, with per-request data.