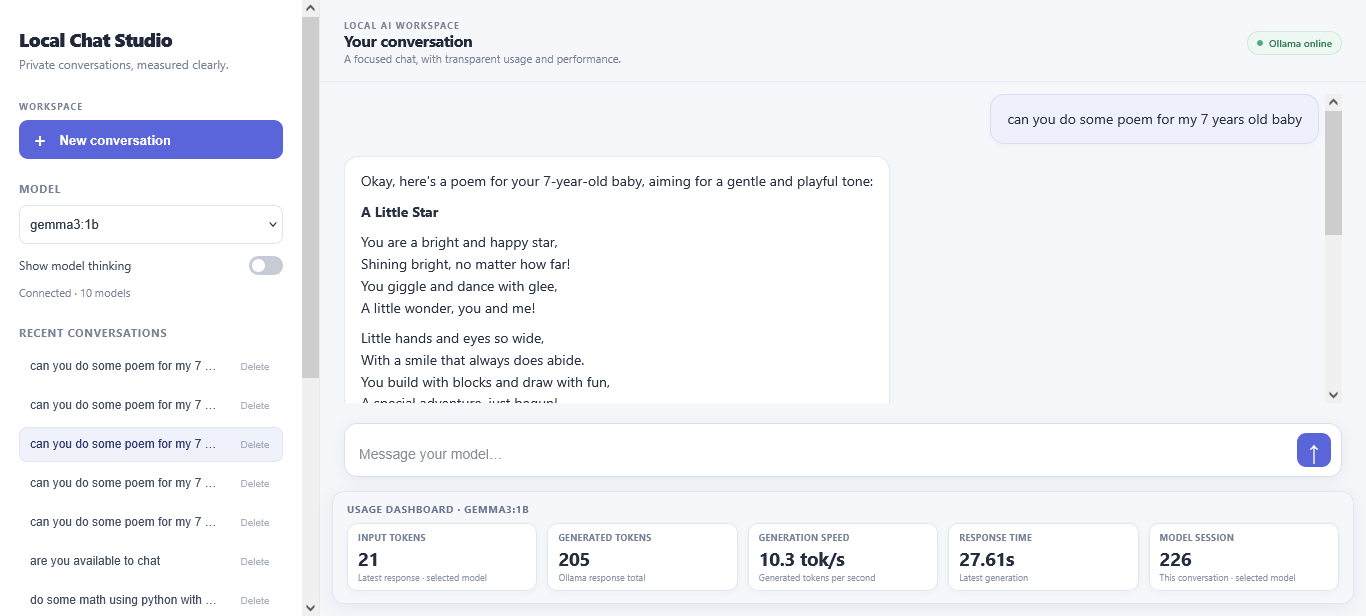
Local-LLM-Token-Speed-Studio-with-Ollama
Local LLM performance benchmarking studio built with Ollama to measure and analyze inference speed, token generation throughput, response latency, and model performance. Compare multiple locally hosted Large Language Models, monitor generation metrics, evaluate CPU-based inference and visualize benchmarking results through an interactive interface.
- 2
- Python
- MIT
- 1 d ago
