ramalama
RamaLama is an open-source developer tool that simplifies the local serving of AI models from any source and facilitates their use for inference in production, all through the familiar language of containers.
- 3.1k
- Python
- MIT
- 5 d ago
RamaLama is an open-source developer tool that simplifies the local serving of AI models from any source and facilitates their use for inference in production, all through the familiar language of containers.
Local inference that behaves like a frontier API: Qwen3.8-Flash-Next on AMD Strix Halo plus small NPU models, over the OpenAI and Anthropic APIs on one port.
A set of performant RDNA/HIP patches against llama.cpp focusing on high speed inferencing with numerics assurance
An inference framework customized for AI MAX 395, compatible with both Linux and Windows, and supports deploying only qwen3.8-flash-next. This project is for reference and learning purposes only. 为AI MAX 395定制的推理框架,Linux和Windows通用,只能部署qwen3.8-flash-next。本项目仅供参考学习使用。
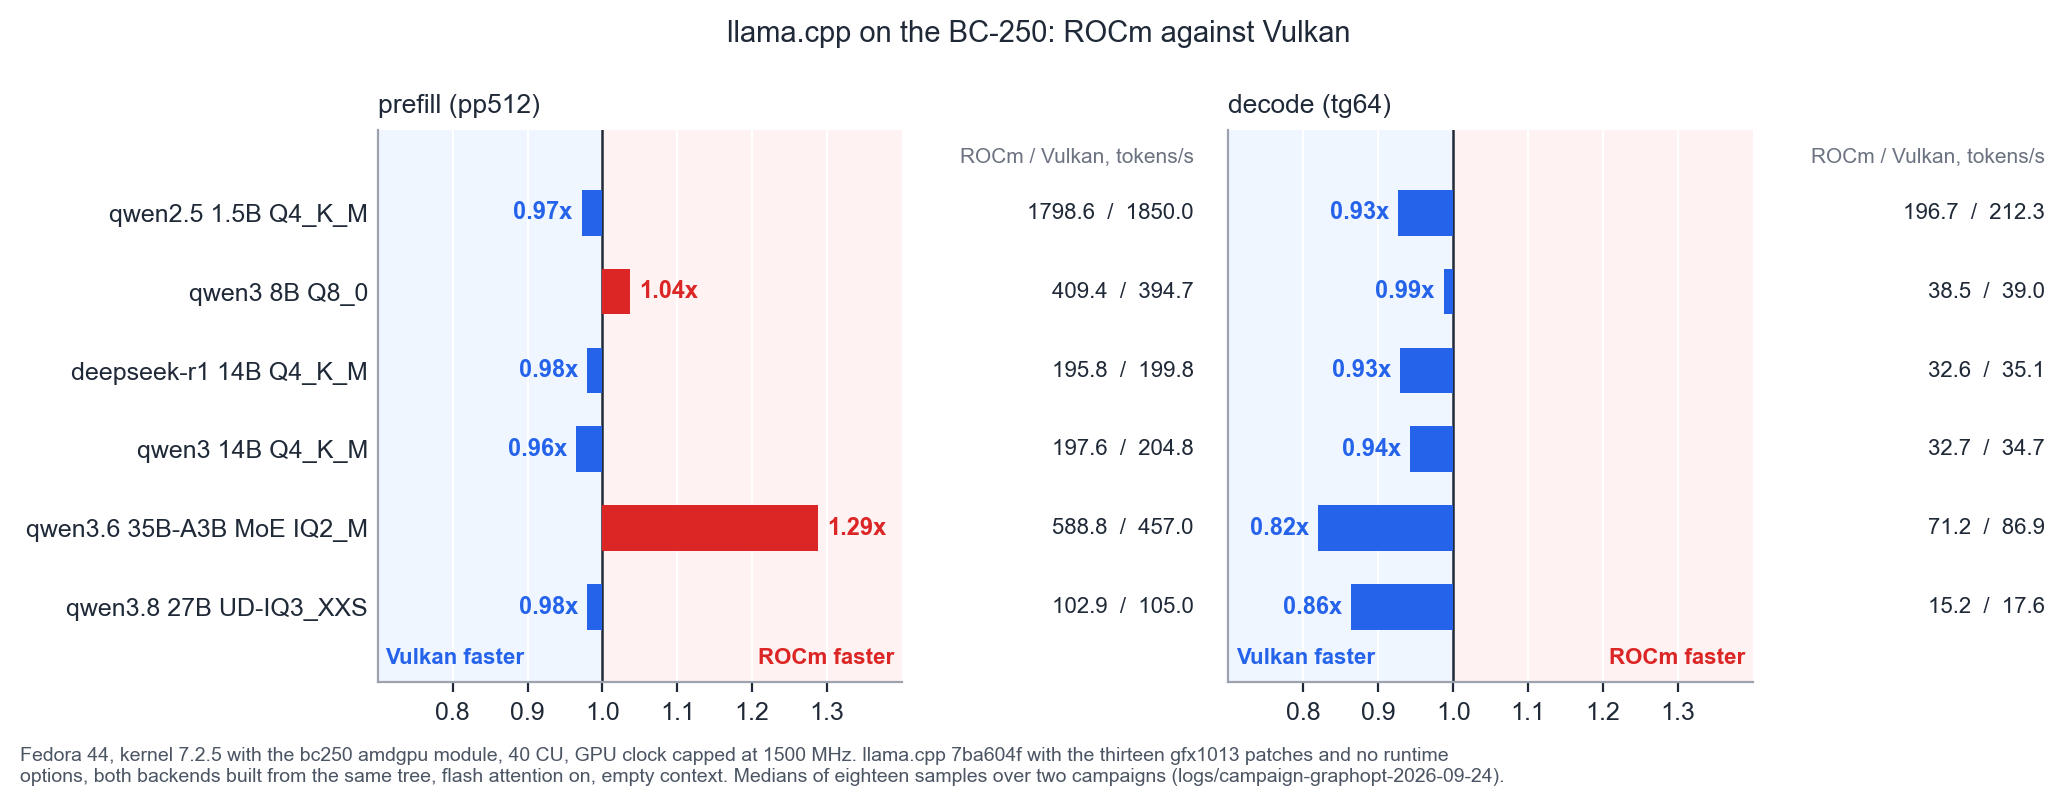
ROCm/HIP investigation on the AMD BC-250 (gfx1013 Cyan Skillfish), with a Vulkan comparison
Fast vLLM on AMD Strix Halo: one docker command for Qwen, Gemma, LFM and more, up to 31x faster prefill and ~2x decode vs stock vLLM at long context.
GSQ (Gumbel-Softmax Quantization) ported to AMD ROCm: gfx1200/gfx1201 (RDNA4) and gfx115x (RDNA3.5 APUs)