firecrawl
Knowledge infrastructure to make your agents smarter. Search, scrape and access 550+ data providers through one API.
- 206k
- TypeScript
- AGPL-3.0
- 11 h ago
Knowledge infrastructure to make your agents smarter. Search, scrape and access 550+ data providers through one API.
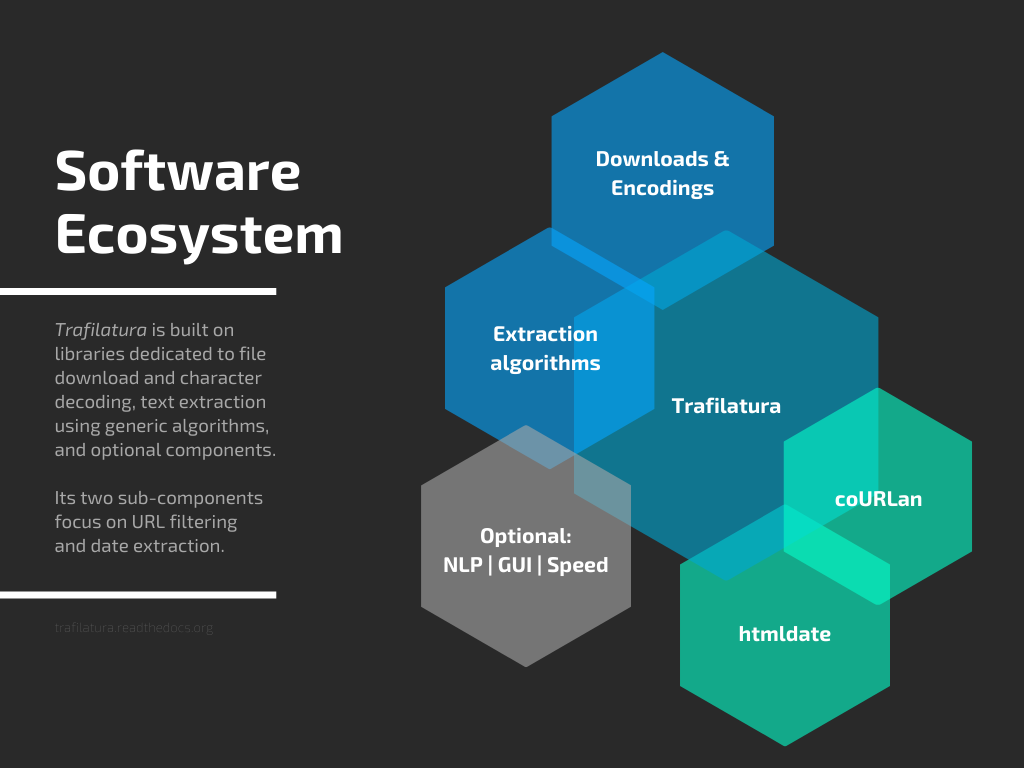
Python & Command-line tool to gather text and metadata on the Web: Crawling, scraping, extraction, output as CSV, JSON, HTML, MD, TXT, XML
CommonMark/Markdown Java parser with source level AST. CommonMark 0.28, emulation of: pegdown, kramdown, markdown.pl, MultiMarkdown. With HTML to MD, MD to PDF, MD to DOCX conversion modules.
Fast, local-first web content extraction for LLMs. Scrape, crawl, extract structured data — all from Rust. CLI, REST API, and MCP server.
Fast, lightweight Firecrawl/Tavily alternative in Rust. Web scraper, crawler & search API with MCP server for AI agents. Drop-in Firecrawl-compatible API (/scrape, /crawl, /search). 2.3x faster than Tavily, 1.5x faster than Firecrawl in 1K-URL benchmarks. 6 MB RAM, single binary. Self-host or use managed cloud.
Any file → clean Markdown for AI agents: PDF, Word, PowerPoint, Excel, EPUB, HTML and web pages, images (OCR), audio and video (metadata, subtitles, transcripts). A fast Rust MCP server and CLI that runs on your machine. No API key.
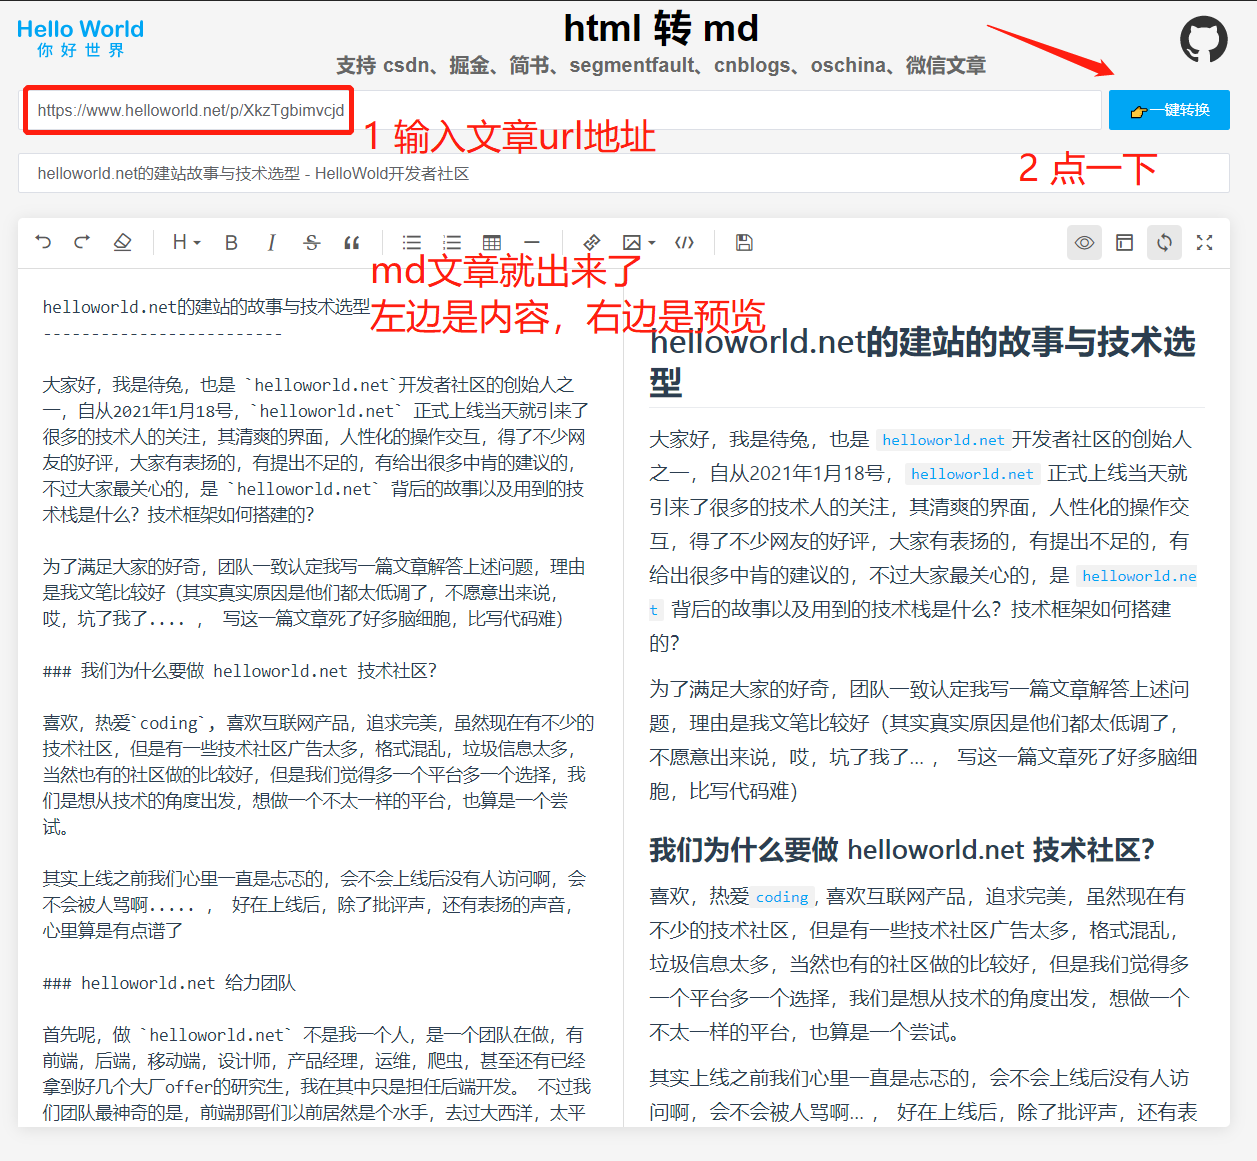
md/html 双向流水线 · 三个能力一站式:万物→md / md→精美html / html→md。封装 markitdown + Pandoc + html-to-markdown + trafilatura。4 套反 AI slop 主题。Claude Code skill.
🔥 This repository contains complete application examples, including websites and other projects, developed using Firecrawl.
100% free and full open-source edge Firecrawl alternative with better links extraction for agents - that you can deploy to cloudflare or vercel by yourself.
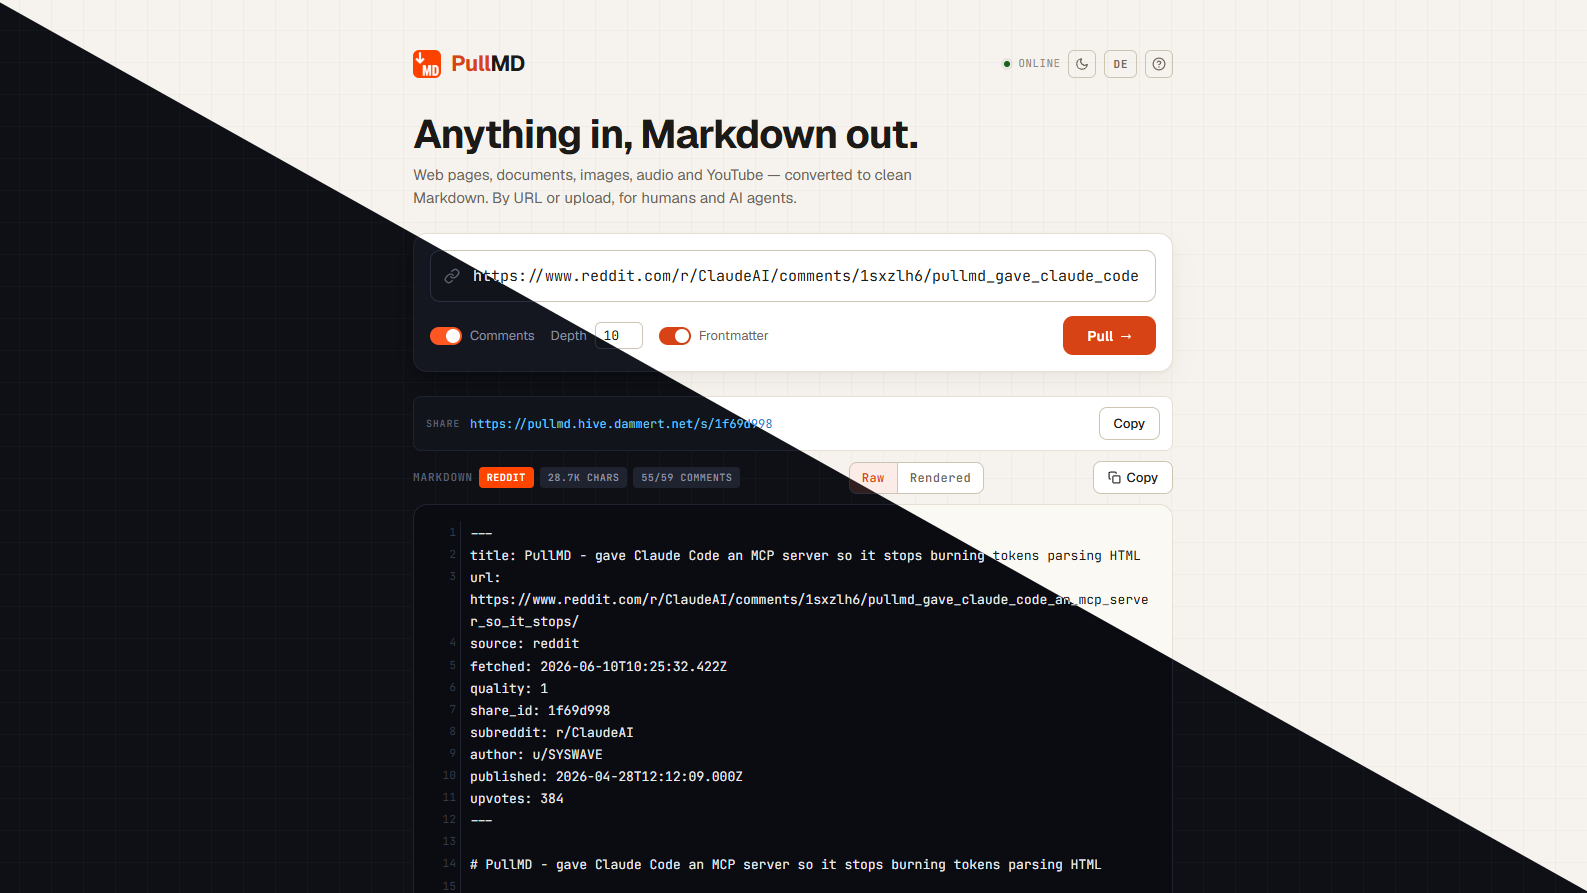
Self-hosted URL- and file-to-Markdown service for humans and AI agents - web pages, documents, images, audio, YouTube. PWA + REST + MCP + Claude Code skill, Reddit-aware, refreshable share links.
A multithreaded 🕸️ web crawler that recursively crawls a website and creates a 🔽 markdown file for each page, designed for LLM RAG
📋 Browser extension to copy text as Markdown (with GFM and MathML support)
Full-content web fetcher for AI agents — Chrome TLS fingerprinting, browser impersonation, multi-strategy article extraction, and web scraping.
Local-first web & document ingestion engine in Rust — HTTP/browser capture, layout-aware PDF/Office/OCR parsing, persistent sync, verifiable data graphs, and evidence-grounded AI context.
A fast, lightweight HTML to Markdown converter optimized for LLM consumption. Uses proven parsing libraries to deliver clean, well-structured markdown with intelligent content extraction and noise filtering.
Pareto-optimal models for cleaning the web — fast, encoder-based main-content extraction from HTML.
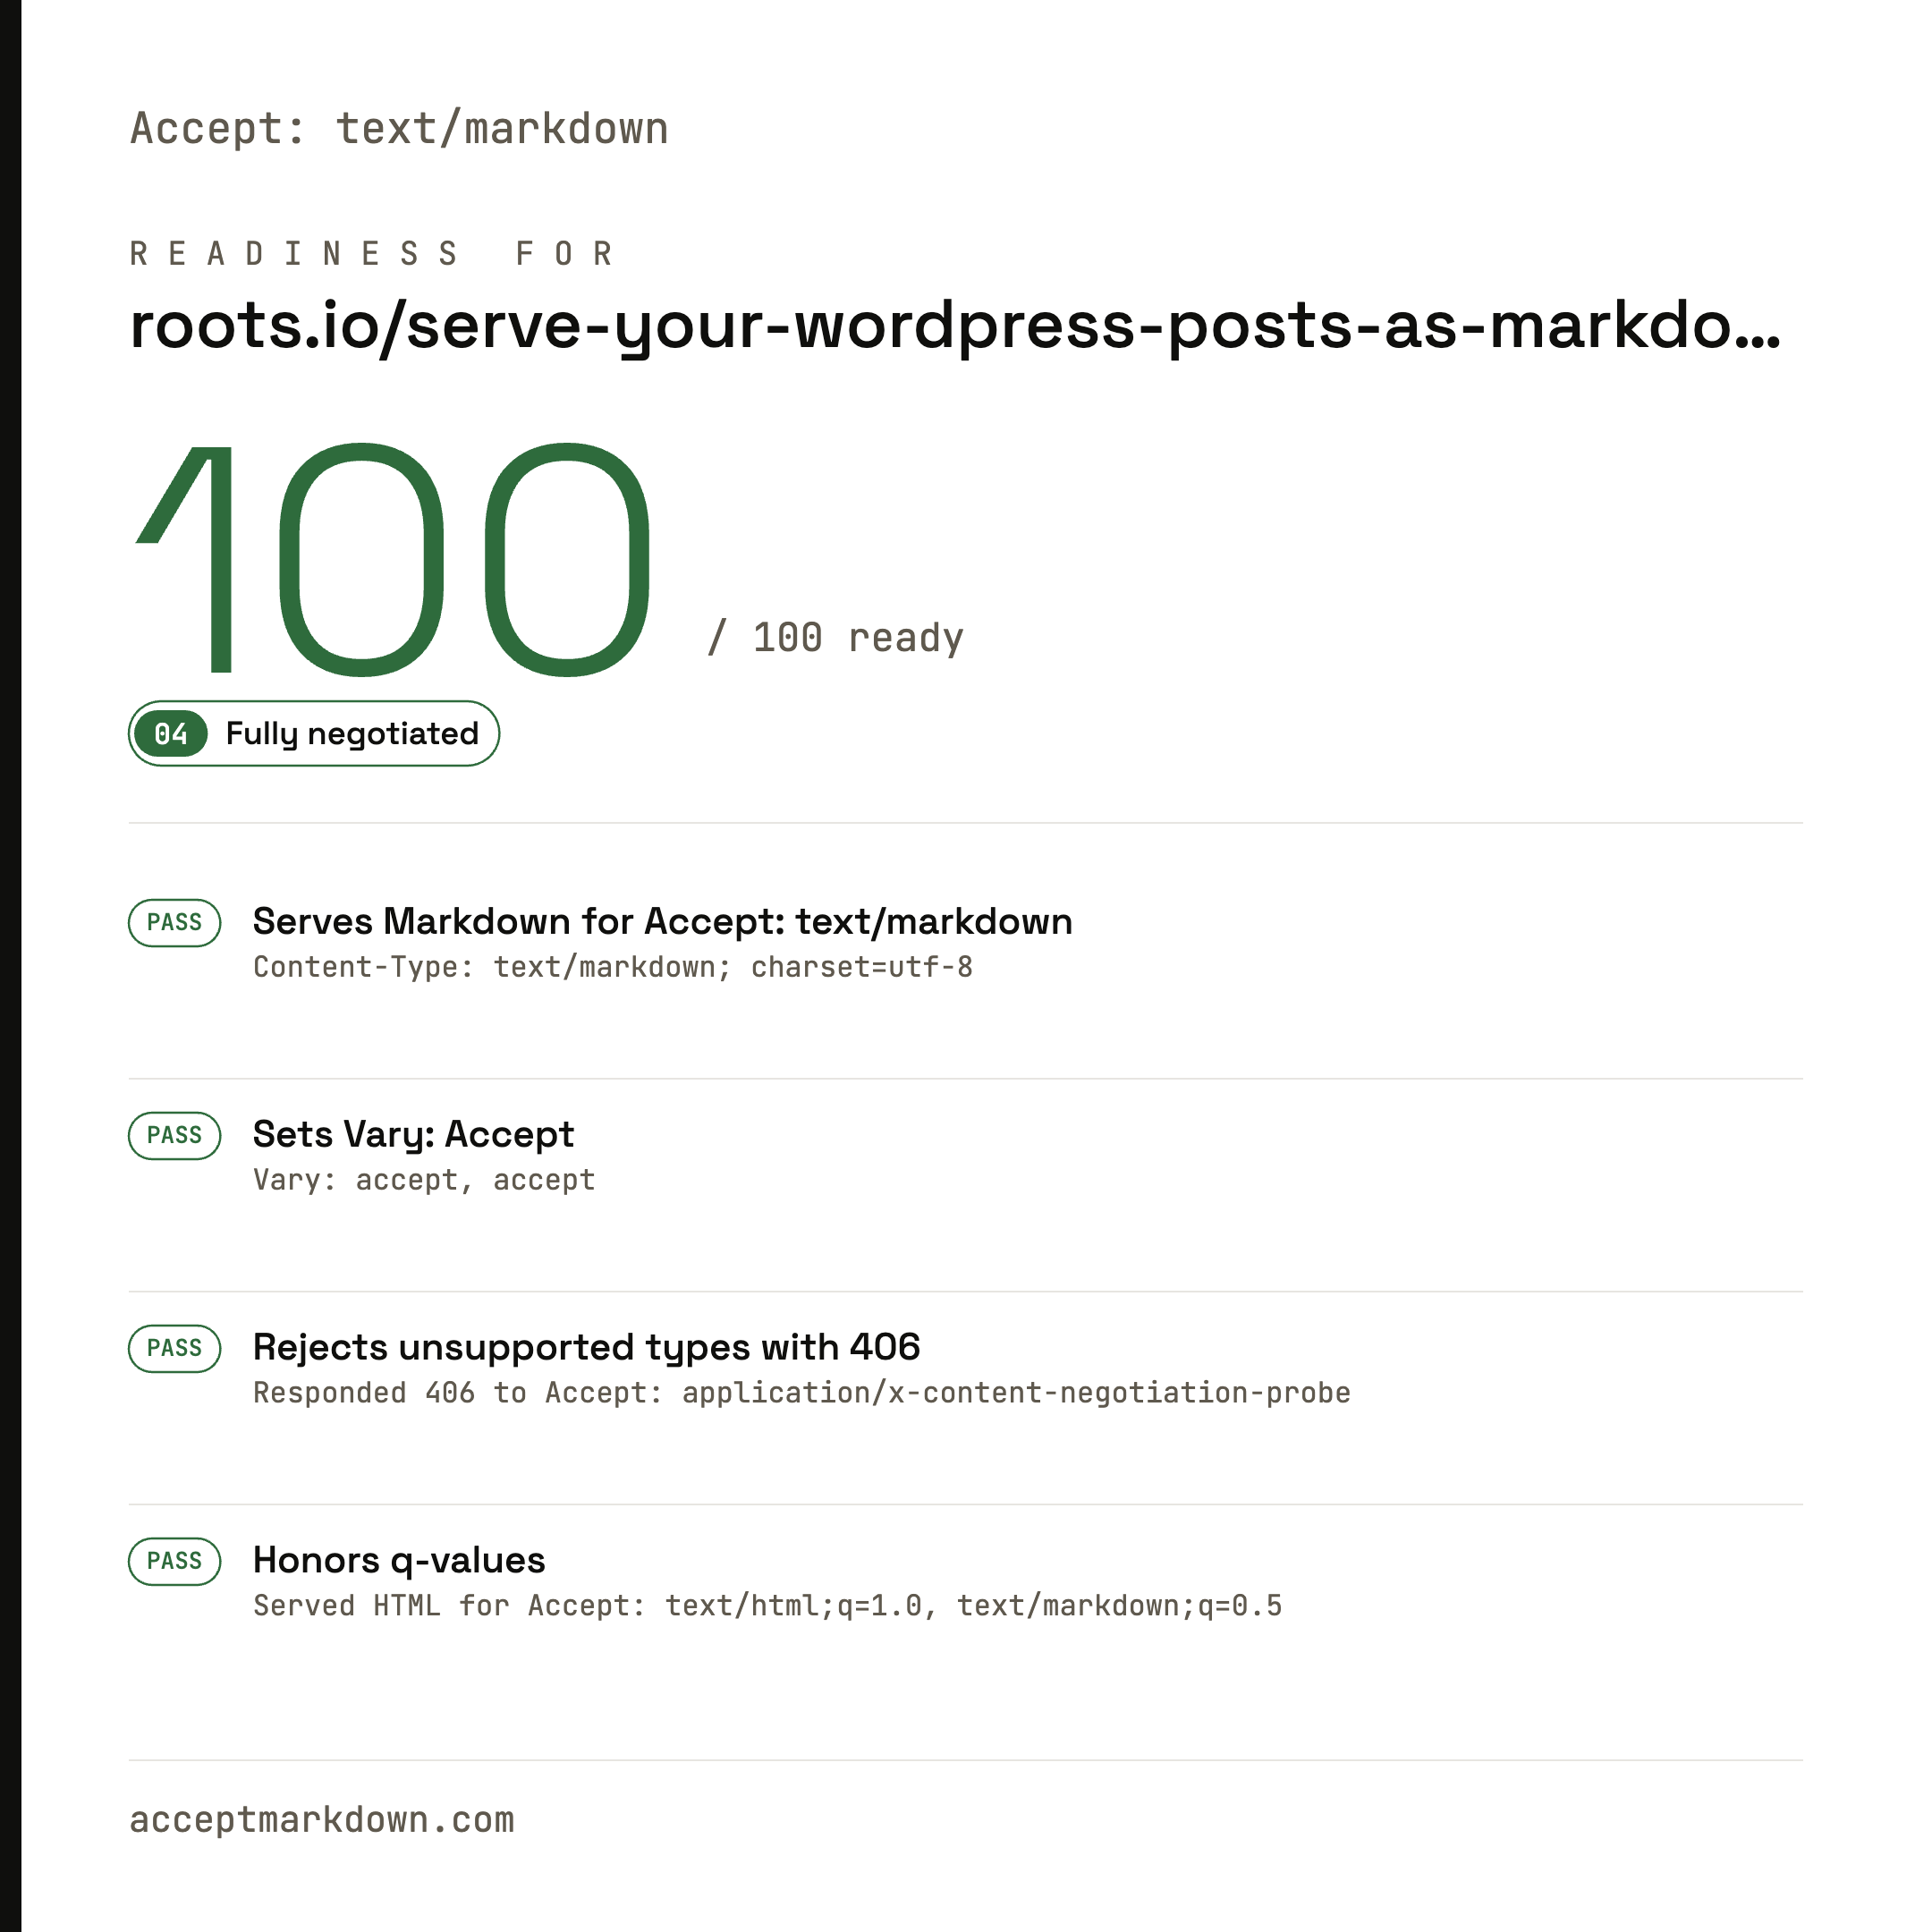
A WordPress plugin that serves post content as Markdown via Accept headers and .md URLs
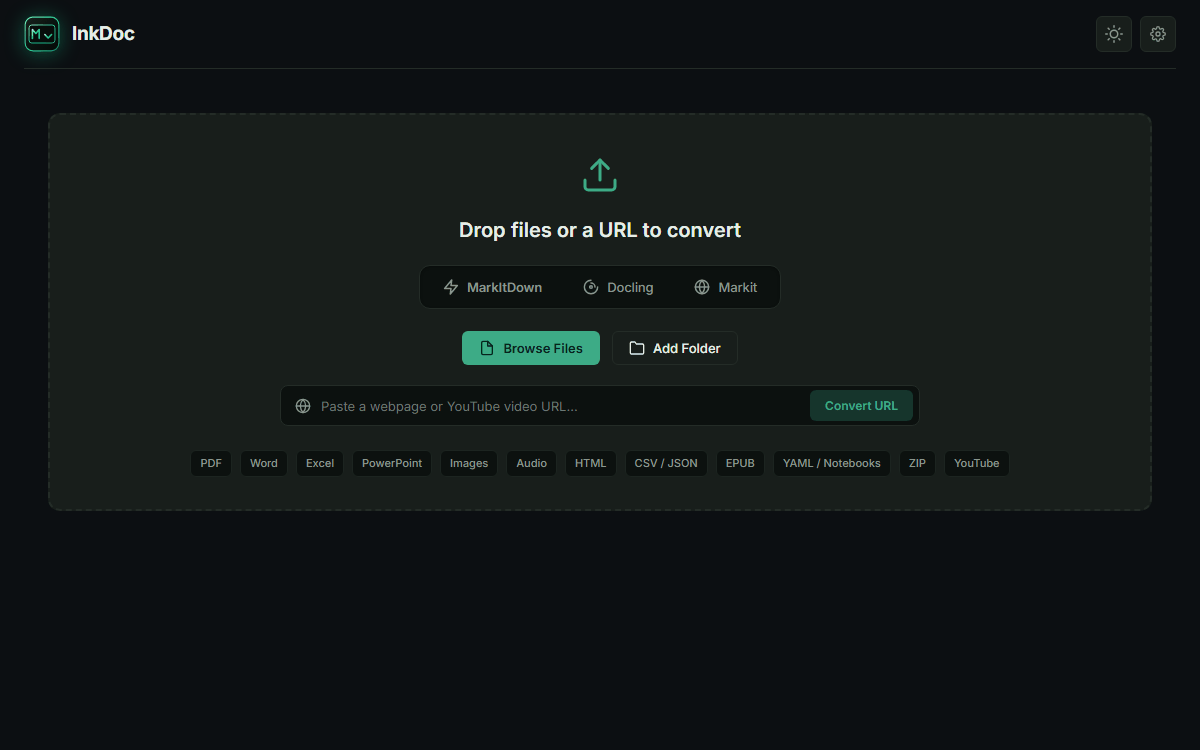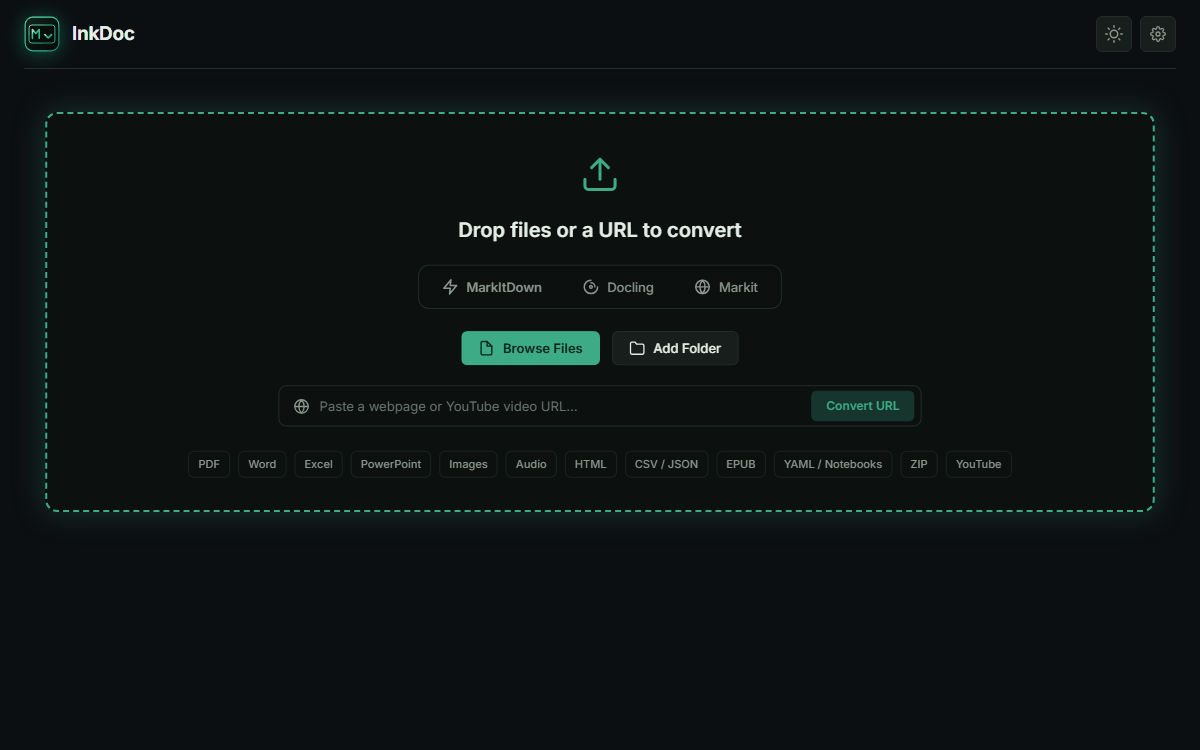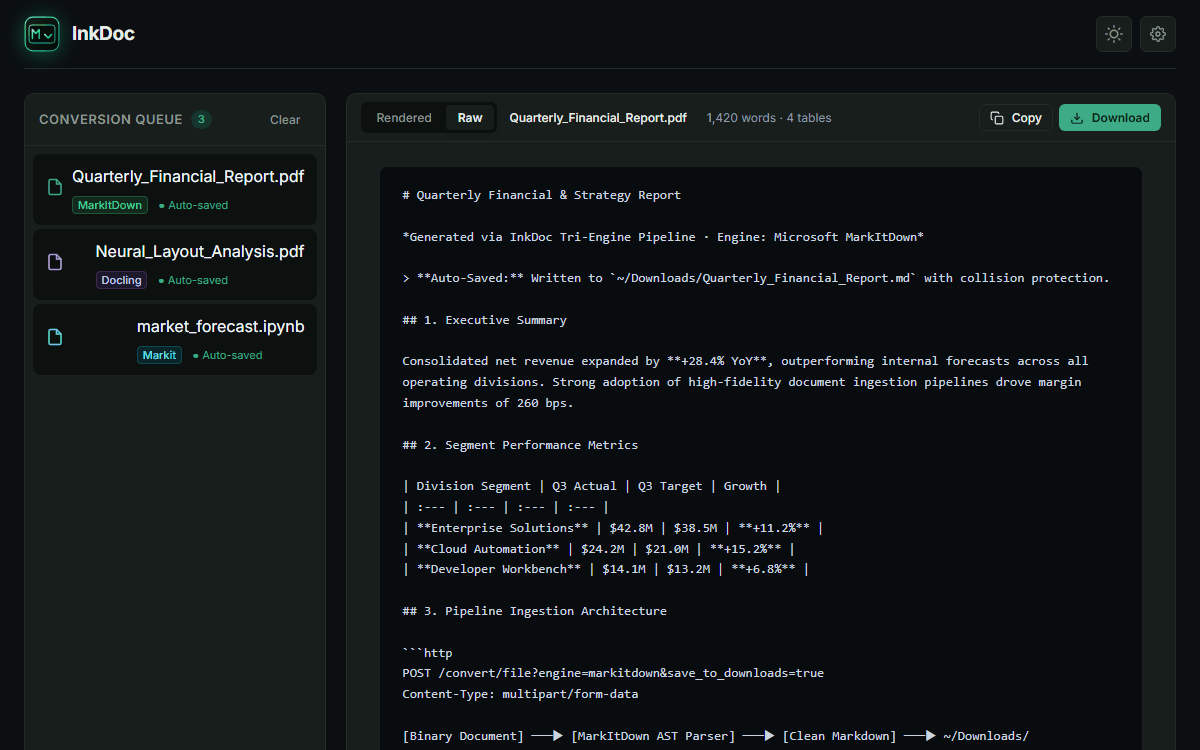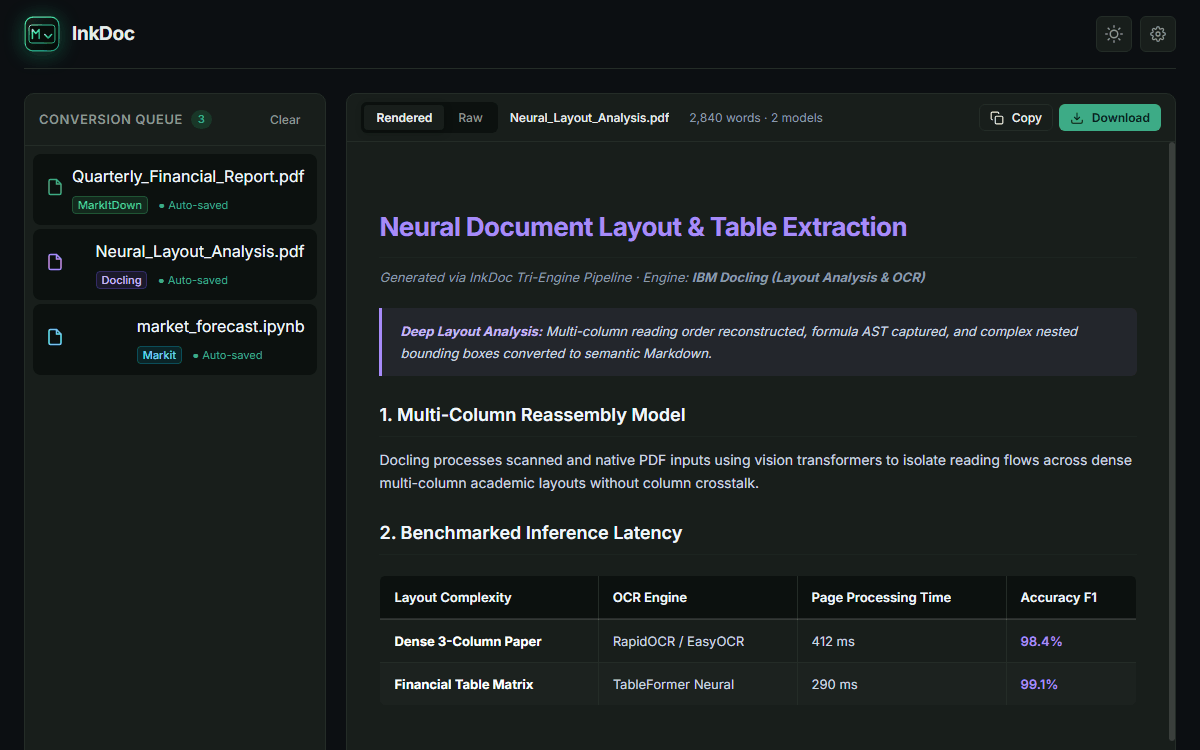
Turn any document into clean, AI-ready Markdown — locally on your machine. Desktop app for Windows, macOS & Linux powered by MarkItDown, Docling, GLM-OCR and Markit.
Convert PDF, Word, PowerPoint, HTML, email & 40+ formats to clean Markdown — and back. Built for LLMs, RAG & Python pipelines, with a built-in MCP server.
Save web pages as Markdown files with preserved formatting. Perfect for documentation, articles, and note-taking.
飞书导出工具的是 小遥搜索飞书导出工具 — 飞书文档,一键导出 Markdown。Xiaoyao Feishu Export — Batch Export Feishu Docs to Markdown.
Local-first MCP server and CLI in Rust: any page as LLM-ready Markdown, whole-site crawls, keyless search, and local captcha solving. No cloud, no API keys.
Self-hostable NGINX module that serves Markdown to AI agents via HTTP content negotiation (Accept: text/markdown), powered by a Rust converter.
Portable web-research and browser-automation SKILLs for Claude Code, Codex, and OpenCode — Playwright, Chrome DevTools, nodriver, and HTML-to-Markdown.
Turn a supported list of filetypes (e.g. .docx) into a markdown structured text file. Also optionally defangs indicators and extract texts from images. Built for threat intel use-cases.
A fast, parallelized CLI tool that scrapes web pages and converts them to markdown with an interactive TUI browser.
Context.dev plugin for Cursor: live web search, scraping and structured extraction over MCP.
Context.dev CLI: scrape, crawl, search and screenshot the web from your terminal. Returns LLM-ready markdown or JSON.
Convert any document format into LLM-ready data format (markdown) with advanced intelligent document processing capabilities powered by pre-trained models.