doris
Apache Doris is a real-time analytics and hybrid search database for AI agents.
- 16k
- Java
- Apache-2.0
- 6 h ago
Apache Doris is a real-time analytics and hybrid search database for AI agents.
Official repository of Trino, the distributed SQL query engine for big data, formerly known as PrestoSQL (https://trino.io)
The world's fastest open query engine for sub-second analytics both on and off the data lakehouse. With the flexibility to support nearly any scenario, StarRocks provides best-in-class performance for multi-dimensional analytics, real-time analytics, and ad-hoc queries. A Linux Foundation project.
High-performance data engine for AI and multimodal workloads. Process images, audio, video, and structured data at any scale
The fastest unified streaming SQL Engine in a single C++ binary. ⚡ Millisecond latency. 100+ GB/s throughput. Continuously compute stateful context from streams, logs, metrics, events, and CDC.
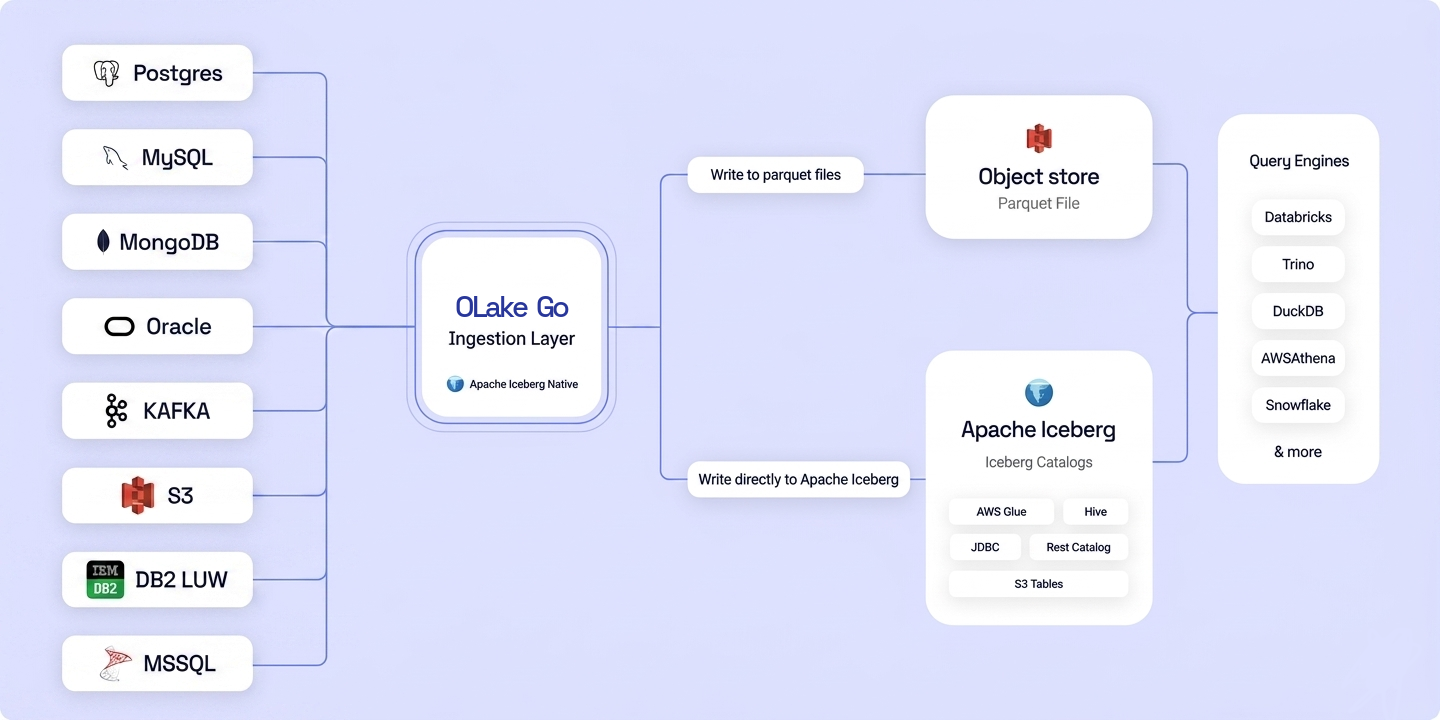
OLake Go: open-source replication from databases, Kafka and S3 to Apache Iceberg and Parquet. Sources: Postgres, MySQL, MongoDB, Oracle, MSSQL, DB2, Kafka, S3. Formerly datazip-inc/olake. Table maintenance lives in datazip-inc/olake-fusion.
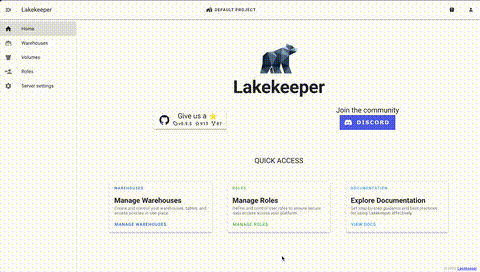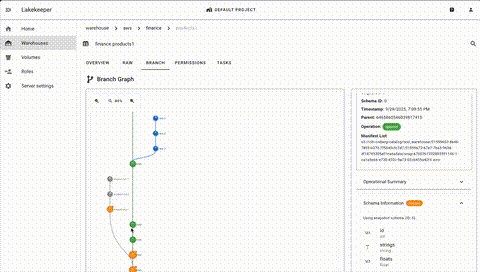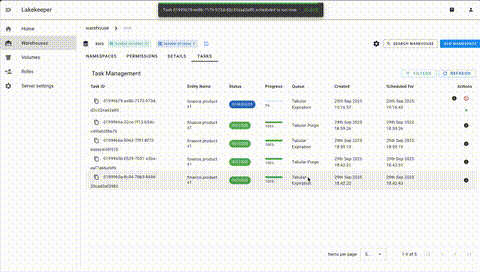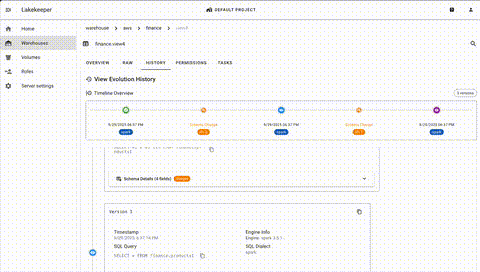
Apache Iceberg REST Catalog in Rust — access control, credential vending and audit for every engine and AI agent. Apache 2.0.
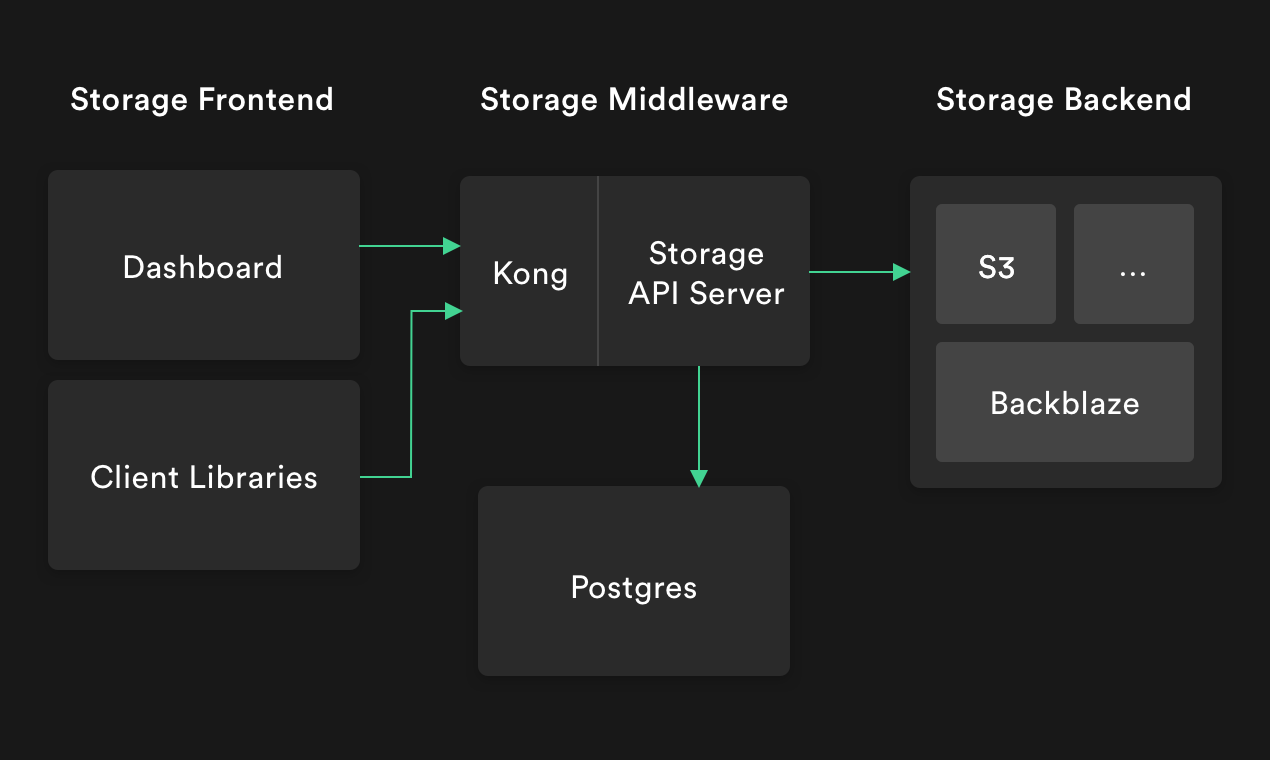
S3 compatible object storage service that stores metadata in Postgres
Firebolt Core is a free, self-hosted edition of Firebolt's distributed query engine (https://www.firebolt.io/); it provides high-performance data warehousing capabilities that can be deployed anywhere from a single laptop to enterprise datacenters.
Real-time Data Warehouse with Apache Flink & Apache Kafka & Apache Hudi
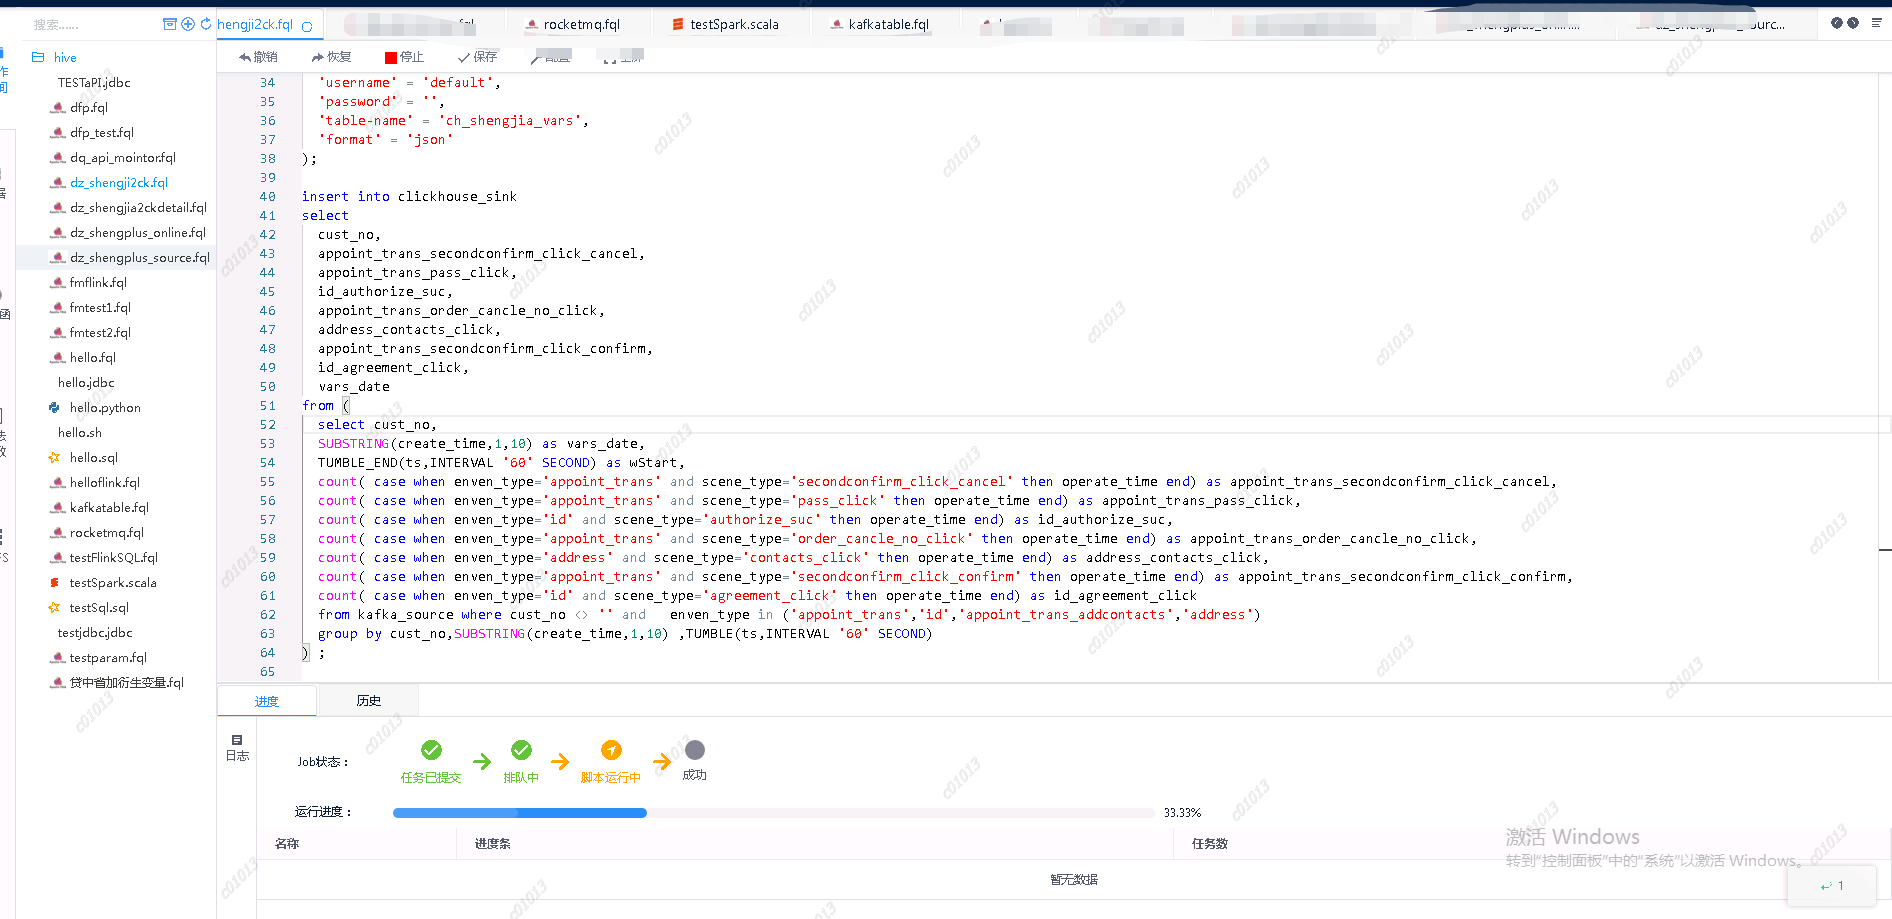
Streaming application development and management system, based on Linkis and DSS, planning to provide the workflow-like graphical drag-and-drop development capability.
Stream PostgreSQL changes into standard Apache Iceberg tables, built in Rust.
BETA RELEASE - NOT FOR PRODUCTION: Transparent data tiering and partition lifecycle management for PostgreSQL. A single table spans recent rows in PostgreSQL partitions and older rows in Apache Iceberg on S3-compatible, Azure, or GCS storage; the cold tier is readable and writable through the same SQL, no app changes.
Feature demos, integration guides & hands-on labs/projects using Kpow, Flex, Kafka, Flink, Iceberg & more
100+ data engineering projects from scratch — streaming, CDC, table formats, query engines, consensus, governance. 2,500+ tests, mypy strict.
Interactive Apache Iceberg debugger for exploring production tables and tracing metadata evolution through AI and real time graph visualization.
K2I - Kafka to Iceberg streaming ingestion engine. A Rust CLI tool inspired by Moonlink architecture that consumes from Kafka, buffers with Apache Arrow for sub-second query freshness, and writes to Apache Iceberg tables.
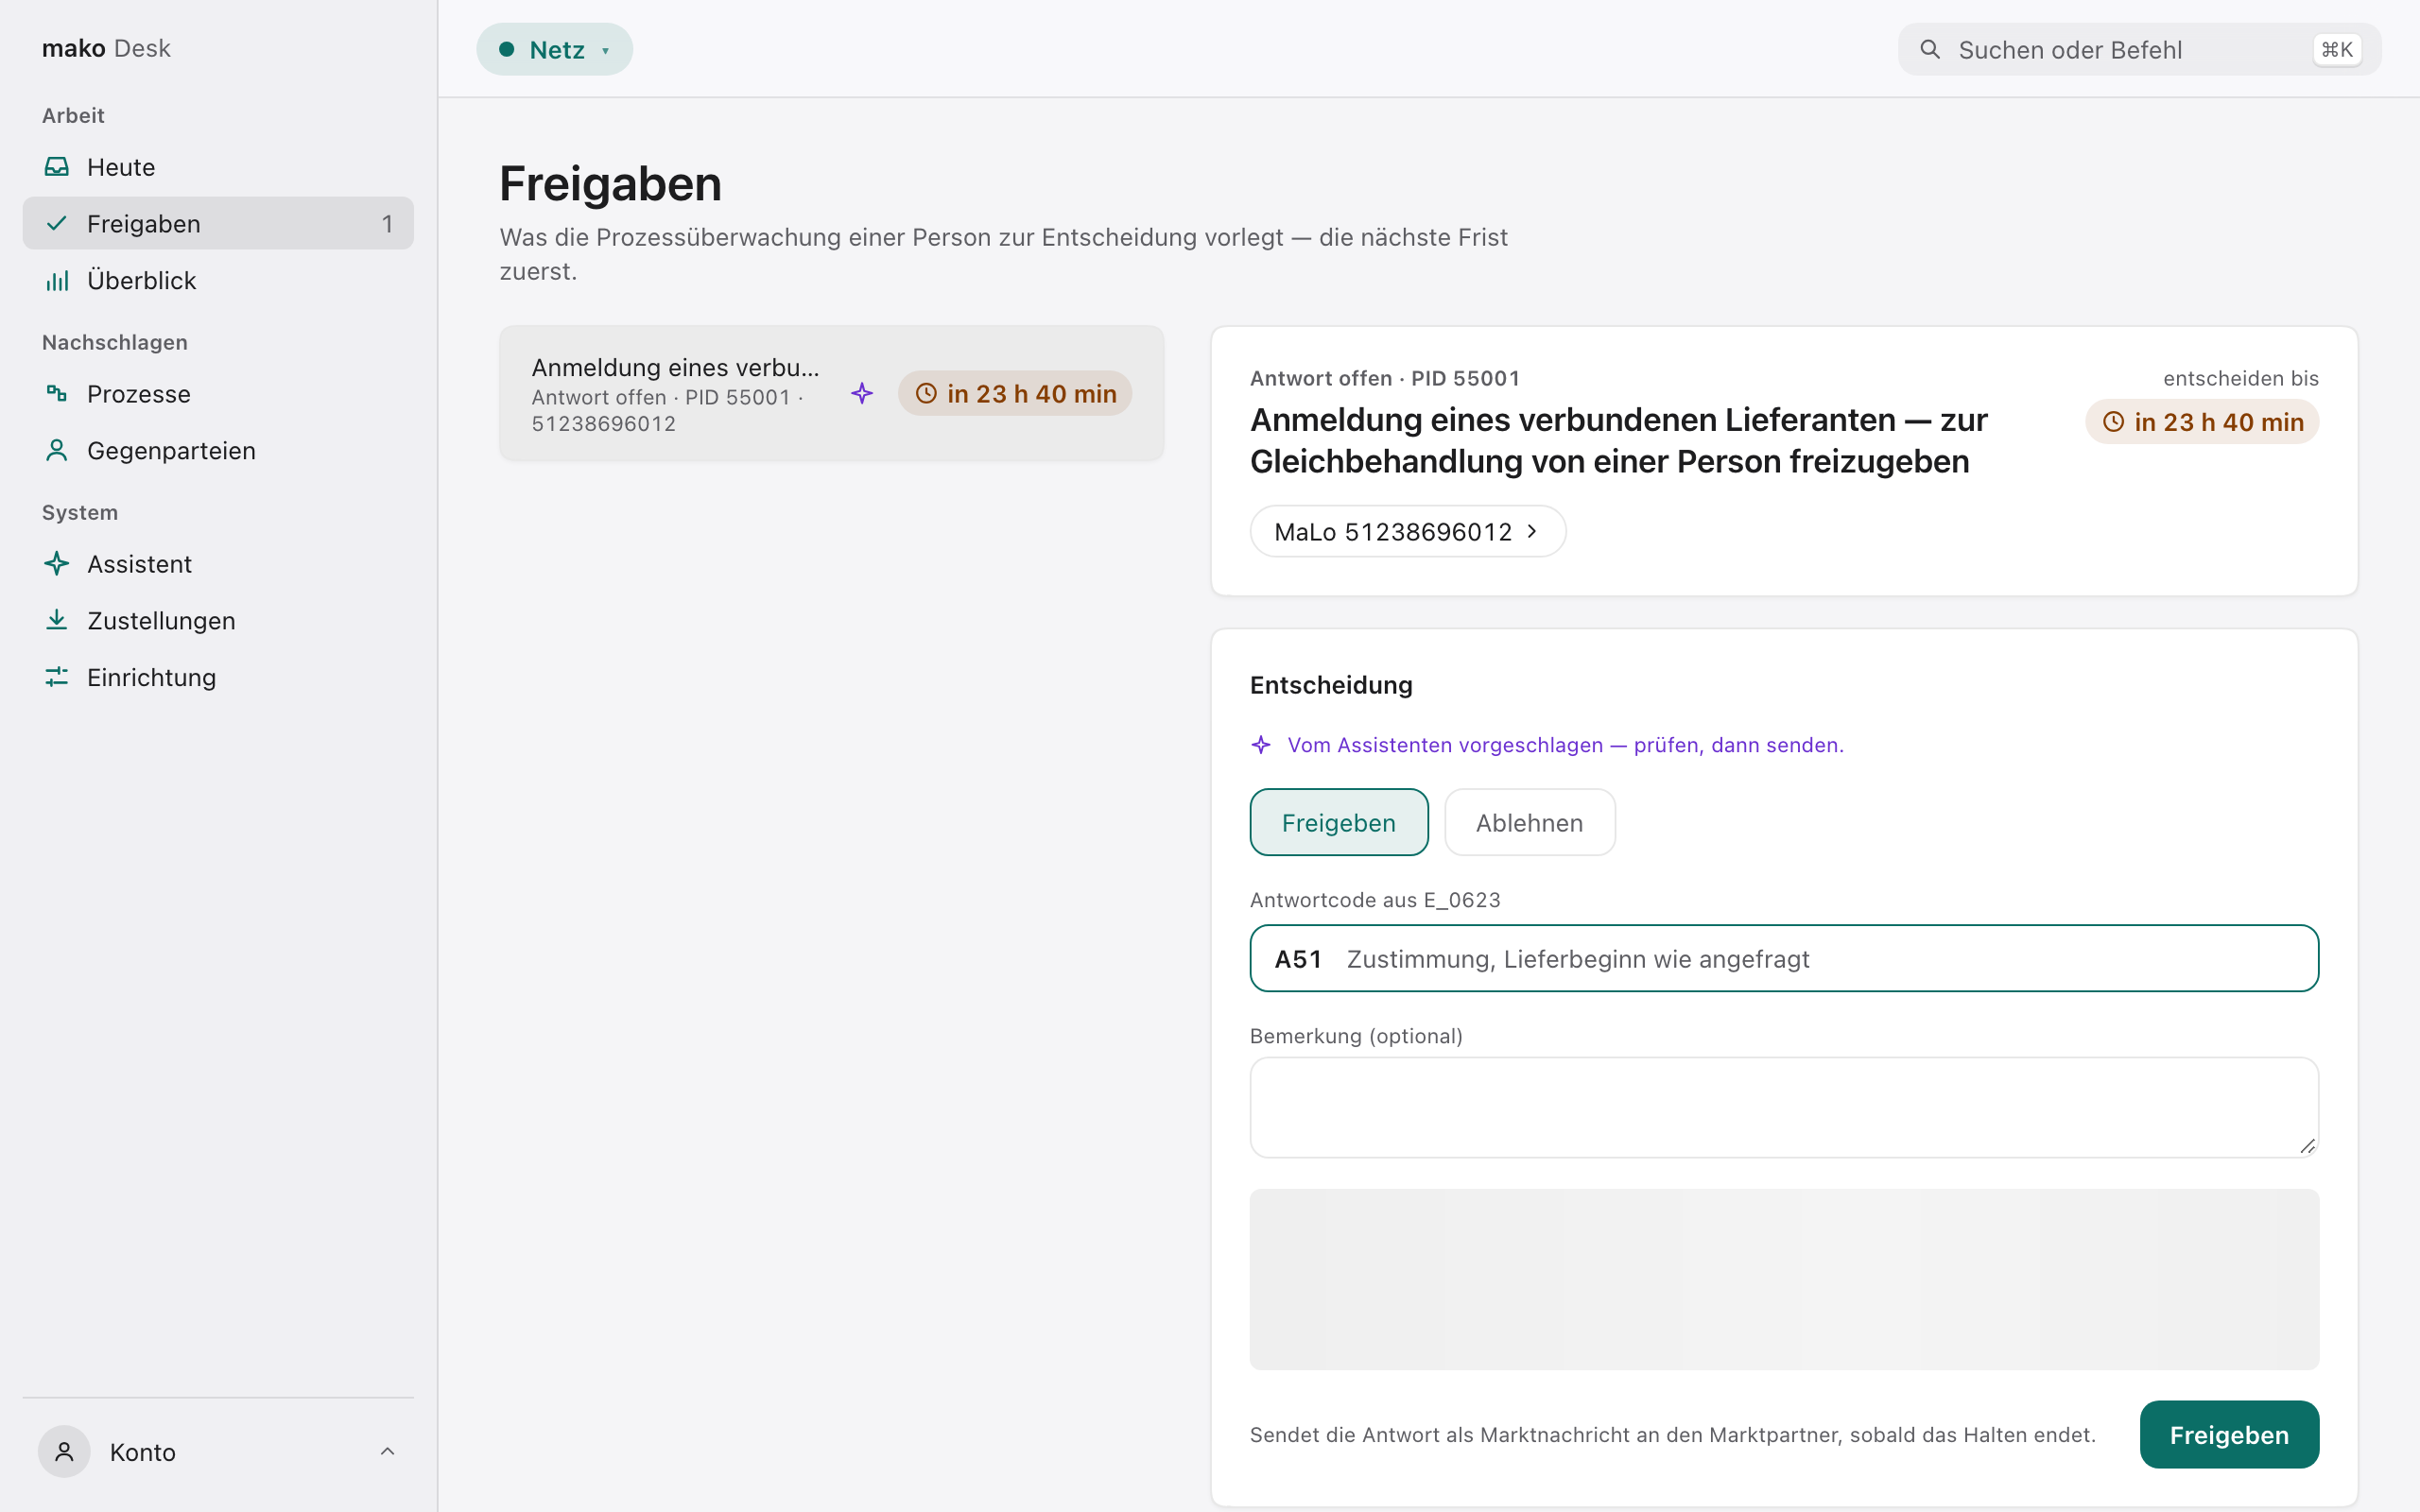
⚡ mako is an open-source, AI-first operating platform for the German energy market, in Rust.
A production-grade, cross-platform, single-binary Apache Iceberg REST Catalog server written in Rust.
Open-source data lakehouse on your laptop: Iceberg 1.12 with the Lakekeeper REST catalog, RustFS (or SILO), DuckDB, Polars, PyIceberg, Spark 4.1 and Trino. Retail medallion and renewal-features pipelines.
Terraform and OpenTofu provider for Lakekeeper, the Apache Iceberg REST Catalog
cancerOnIce (Catchment Lake): population cancer data as Apache Iceberg tables keyed on geography and time, every source release kept queryable; served behind icegate
A curated list of awesome Databricks resources, including tutorials, notebooks, libraries, and tools.
Distributed SQL lakehouse engine in Rust: DataFusion + Iceberg + pgwire, with Iceberg caching, federation, materialized views and CDC