Viewers
OHIF zero-footprint DICOM viewer and oncology specific Lesion Tracker, plus shared extension packages
- 4.4k
- TypeScript
- MIT
- 3 h ago
OHIF zero-footprint DICOM viewer and oncology specific Lesion Tracker, plus shared extension packages
Local AI photo scoring, culling, and gallery — score, organise, and explore your library with face recognition and semantic search. No cloud, no subscriptions.
This repository explores the variety of techniques commonly used to analyze and interpret images. It also describes challenging real-world applications where vision is being successfully used, both for specialized applications such as medical imaging, and for fun, consumer-level tasks such as image editing and stitching, which students can apply to their own personal photos and videos.
HTML PPT Generator: Audience-Tailored Slides, Speaker, and Visual Verification
GARI (Genetic Algorithm for Reproducing Images) reproduces a single image using Genetic Algorithm (GA) by evolving pixel values.
The vision plugin for OpenCode that truly understands images. Inspect, read, and reason about any screenshot or picture with deeper understanding than any other plugin — fully local, private, and free.
C++ library and command-line software for processing and analysis of terabyte-scale volume images locally or on a computing cluster.
Fundamentals of Digital Image Processing: A Practical Approach with Examples in Matlab - Solomon / Breckon, 2010
An end-to-end processing pipeline that transforms multi-channel whole-slide images into single-cell data.
🍊 :rice_scene: Orange3 add-on for dealing with image related tasks
AI-powered deep research tool leveraging web scraping for cost-effective, comprehensive analysis. Open-source and API-cost free!
🗺️ Geo Explorer is an open-source, AI-powered geolocation engine that reimagines how we interact with maps and places. Unlike traditional "black box" systems, Geo Explorer uses a transparent, reasoning-based approach—leveraging Google’s Gemini model with real-time grounding in Google Search and Maps—to analyze images, understand natural language.
This repository contains a curated collection of notebooks for implementing state-of-the-art multimodal Vision-Language Models (VLMs).
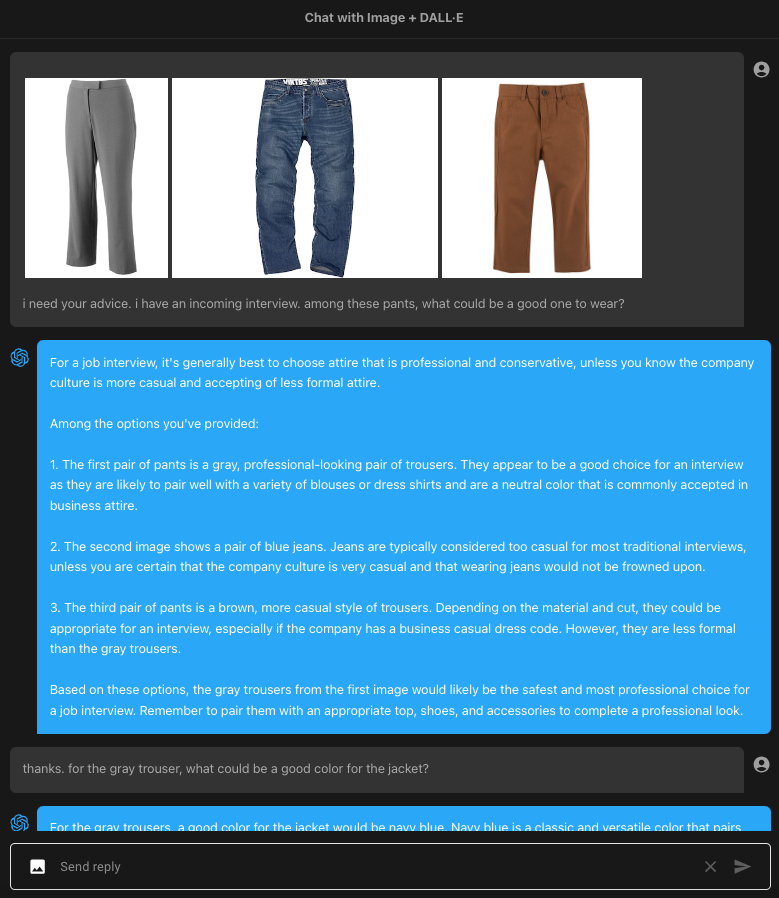
This sample project integrates OpenAI's GPT-4 Vision, with advanced image recognition capabilities, and DALL·E 3, the state-of-the-art image generation model, with the Chat completions API. This powerful combination allows for simultaneous image creation and analysis.
ESP32 Camera extension to allow the camera to detect movement using image centre of mass shift
MobileNetV2-UNet semantic segmentation for Starbucks logo detection - 50ms inference with PyTorch Lightning, binary mask output for mobile deployment
Capability-aware vision + paste extension for the pi coding agent. Delegates image analysis only when the active model is text-only; passes through natively for multimodal models (zero delegation).
A structured, hands-on learning path for mastering Computer Vision with Python and OpenCV, covering image processing, filtering, thresholding, contours, feature detection, object detection, video processing, tracking, deep learning, OCR, segmentation, and AI-powered computer vision applications.