ArchiveBox
🗃 Open source self-hosted web archiving. Takes URLs/browser history/bookmarks/Pocket/Pinboard/etc., saves HTML, JS, PDFs, media, and more...
- 29k
- Python
- MIT
- 5 h ago
🗃 Open source self-hosted web archiving. Takes URLs/browser history/bookmarks/Pocket/Pinboard/etc., saves HTML, JS, PDFs, media, and more...
🌐 Guide and tools to run a full offline mirror of Wikipedia.org with three different approaches: Nginx caching proxy, Kiwix + ZIM dump, and MediaWiki/XOWA + XML dump
🖥️ Official ArchiveBox browser extension: automatically/manually preserve your browsing history using ArchiveBox.
😇 A Docker Compose bundle to run on servers with spare CPU, RAM, disk, and bandwidth to help the world. Includes Tor, ArchiveWarrior, BOINC, and more...
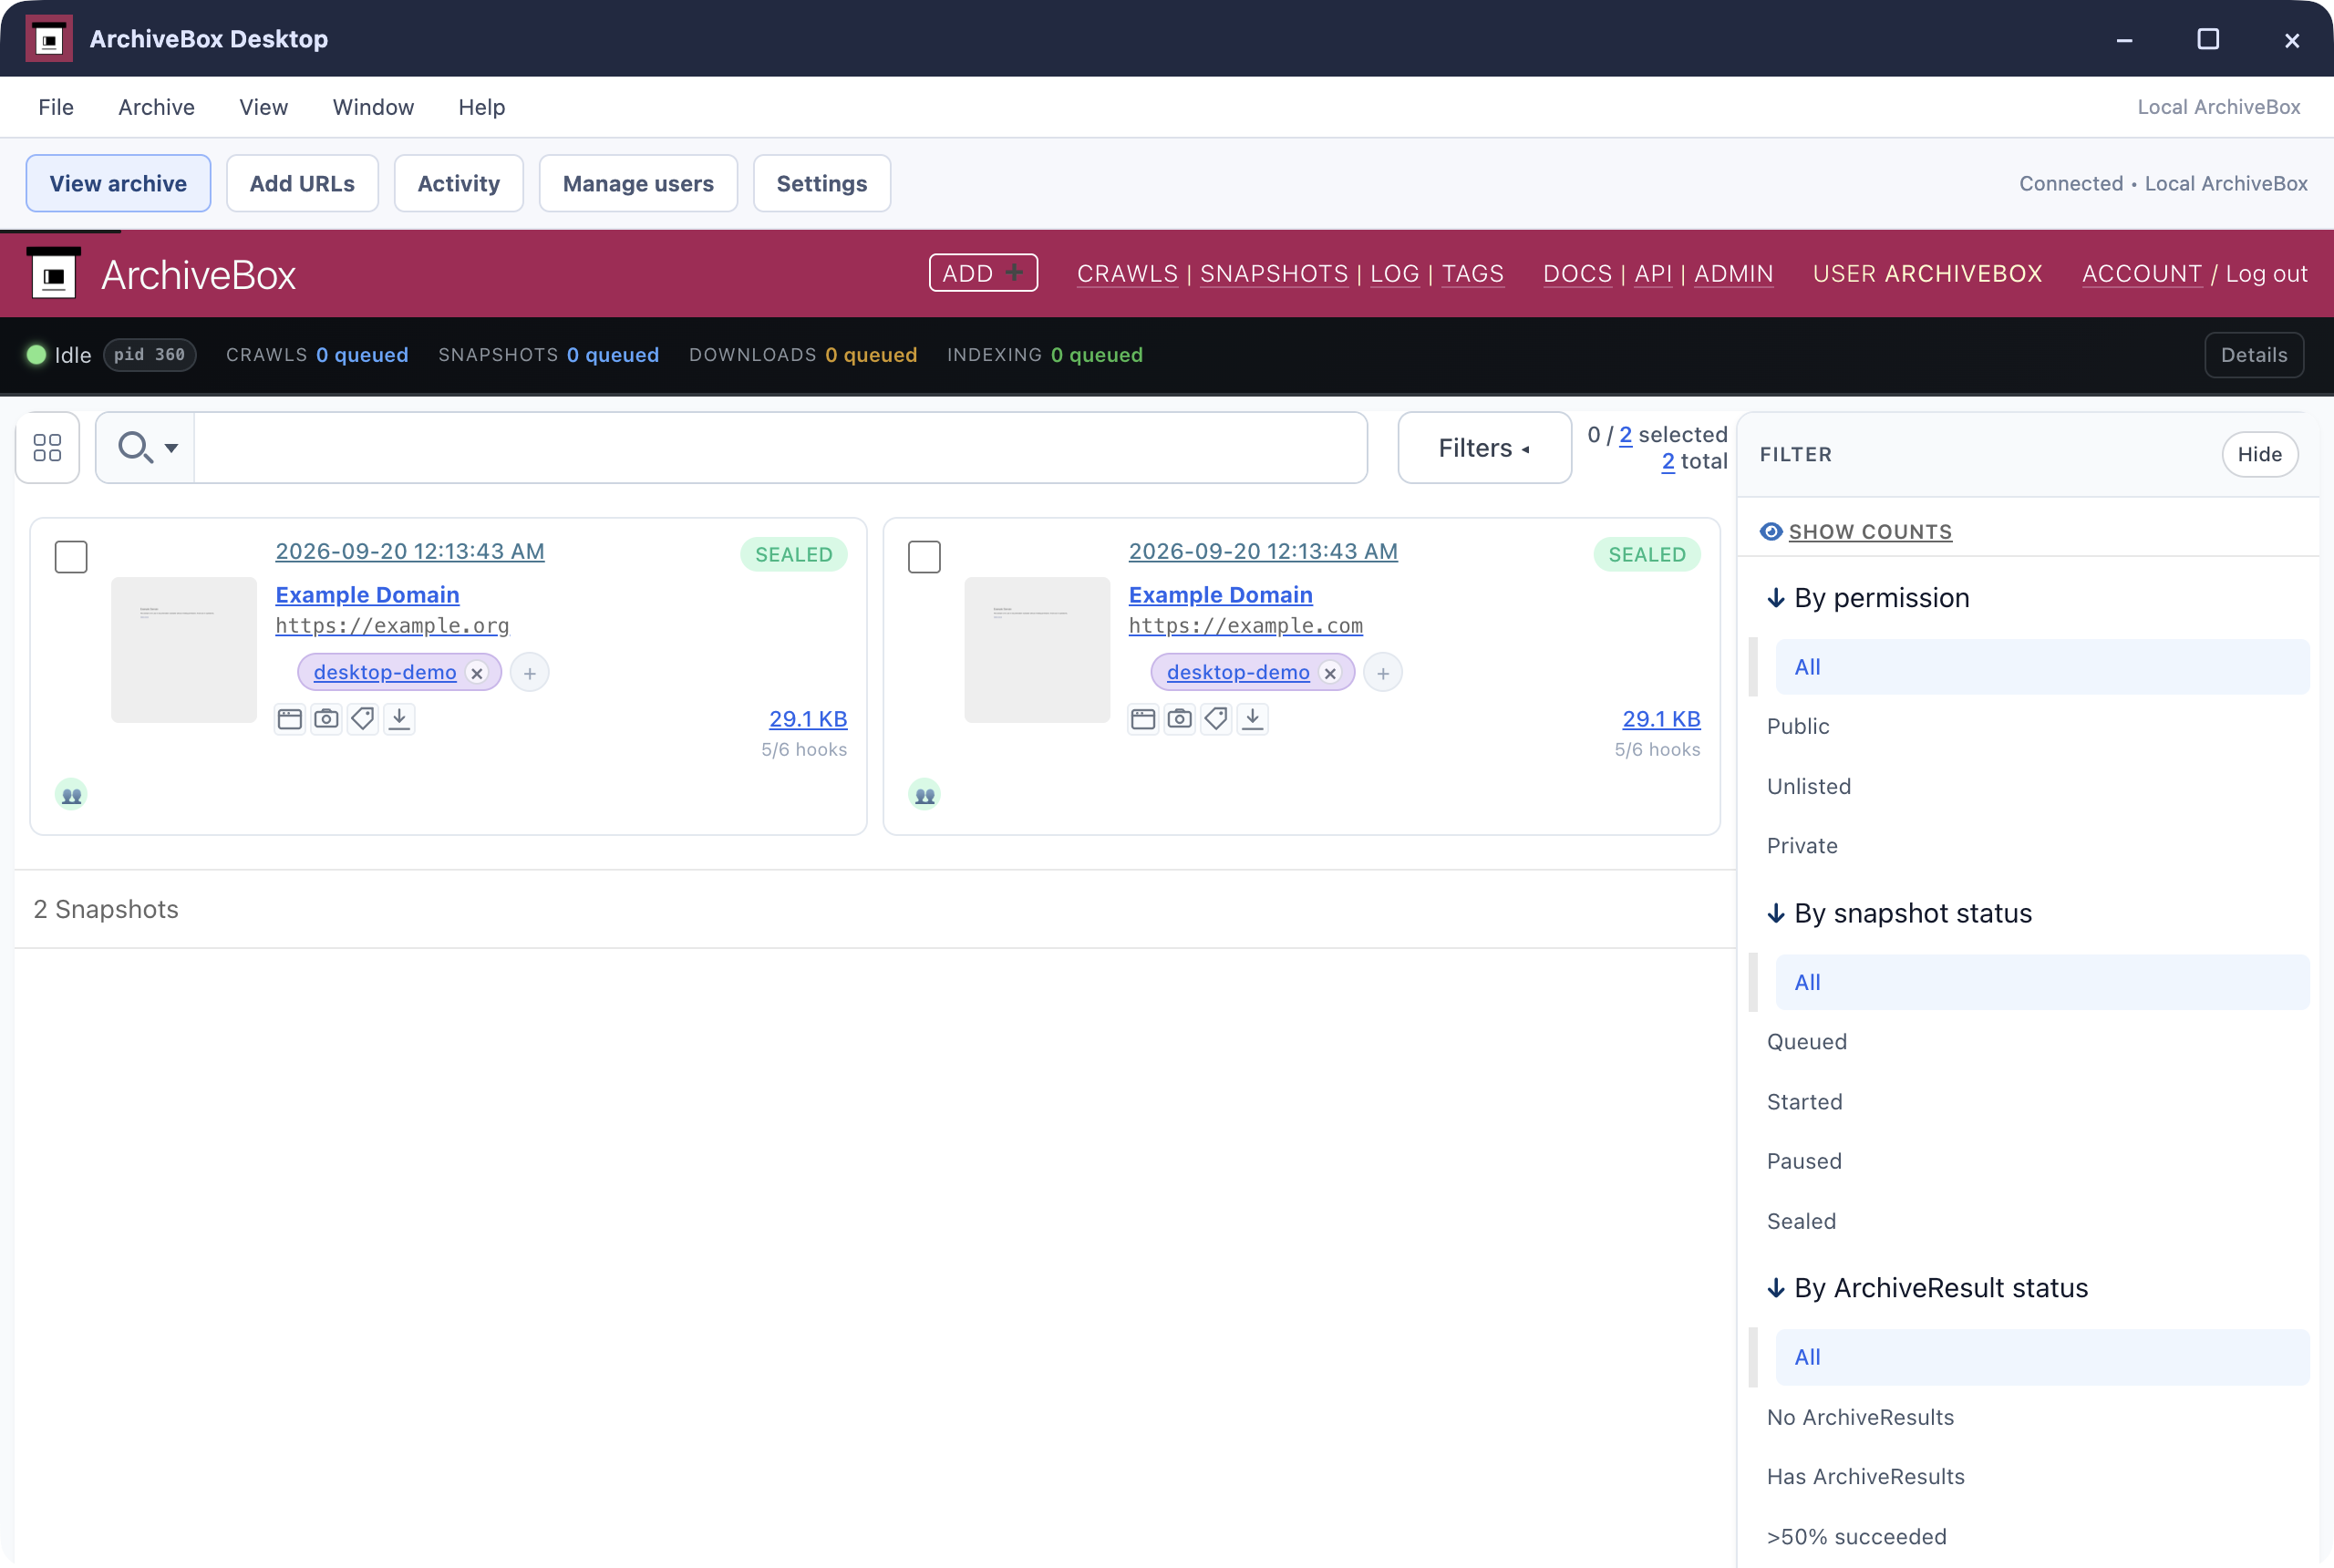
⚛️ Windows & Linux ArchiveBox Desktop App (powered by Electron + Docker Desktop).
⬇️ A simple all-in-one CLI tool to download EVERYTHING from a URL (like youtube-dl/yt-dlp, forum-dl, gallery-dl, simpler ArchiveBox). 🎭 Uses headless Chrome to get HTML, JS, CSS, images/video/audio/subtitles, PDFs, screenshots, article text, git repos, and more...
🎭 An introduction to the Internet Archiving ecosystem, tooling, and some of the ethical dilemmas that the community faces.
Javascript/Node wrapper around Mozilla's Readability library so that ArchiveBox can call it as a oneshot CLI command to extract each page's article text.
Official ArchiveBox MITM proxy: saves URLs of all requests passing through to an ArchiveBox server for archival.
🍺 Homebrew formula for installing the ArchiveBox self-hosted internet archiving solution on macOS.
DigestBox takes any webpage URL (news article, video link, comment thread, etc.) and gives you just the raw content. It's powered by ArchiveBox.io under the hood.
🤝 A proof of concept to find the intersection of bytes between two files on different nodes, without ever revealing the cleartext to the other node. Designed for anonymizing HTML archives that may contain PII.
🧩 Plugins and extractors that ArchiveBox + abx-dl use: chrome, ytdlp, wget, singlefile, readability, forum-dl, gallery-dl, papers-dl, and more...
</> JS Port of ArchiveBox so that it can run fully in-browser, using modern WACZ + CDX capture based on webrecorder + WASM to run Python plugins in-browser using pyiodide. Lets us run the full ArchiveBox plugin suite directly inside the ArchiveBox Browser Extension without a separate remote server.
🍥 ArchiveBox apt/deb package for installing on Ubuntu/Debian-based Linux systems.
Source for the Github Wiki / ReadTheDocs documentation for AchiveBox, the self-hosted internet archiving solution.