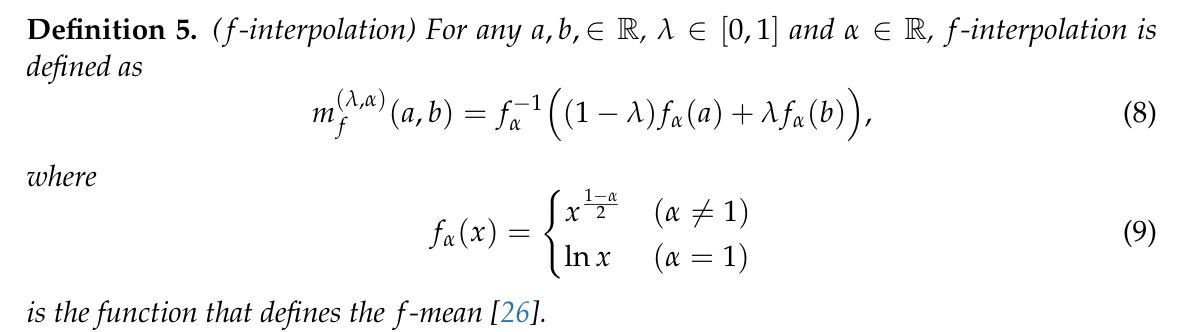semantic-soft-bootstrapping
A self-distillation based training method for long context reasoning in a single LLM without reinforcement learning
- 11
- Python
- MIT
- 10 mo ago
A self-distillation based training method for long context reasoning in a single LLM without reinforcement learning
Relative entropy, mutual information, KL divergence of 2 given Images 🖼
Bakes a system prompt into a LoRA adapter, so a chat model behaves as if prompted without the prompt in its context. It trains on the KL divergence to the prompted model, after Prompt Baking (arXiv 2409.13697). PyTorch, Transformers and PEFT, Qwen3.5 by default, and it fits an 8 GB GPU.
KL-divergence scoring of quantized MLX and GGUF checkpoints against a full-precision teacher, with a disk cache of teacher logits
Zero-dependency Edge Vision INT4/INT8 Post-Training Quantization (PTQ) engine with Kullback-Leibler (KL) divergence entropy calibration, analytical Conv2D+BatchNorm folding, QDQ synthesis, and SQNR posture auditor.
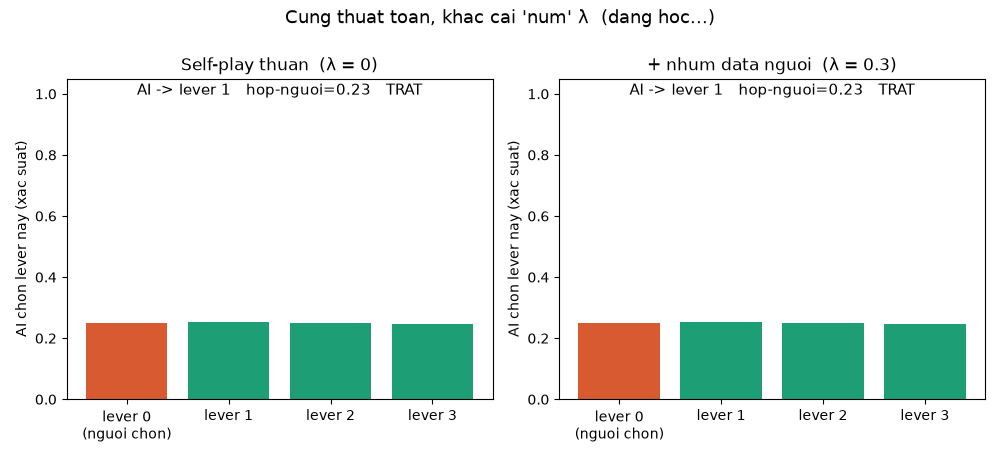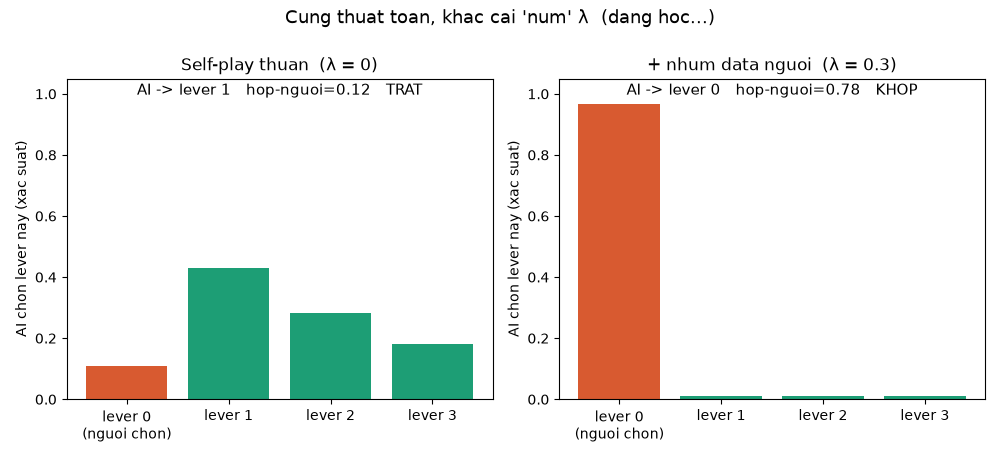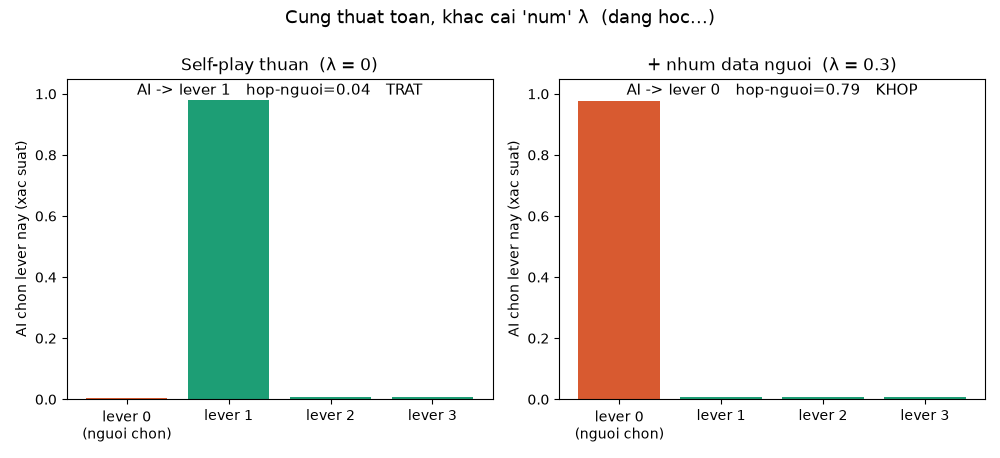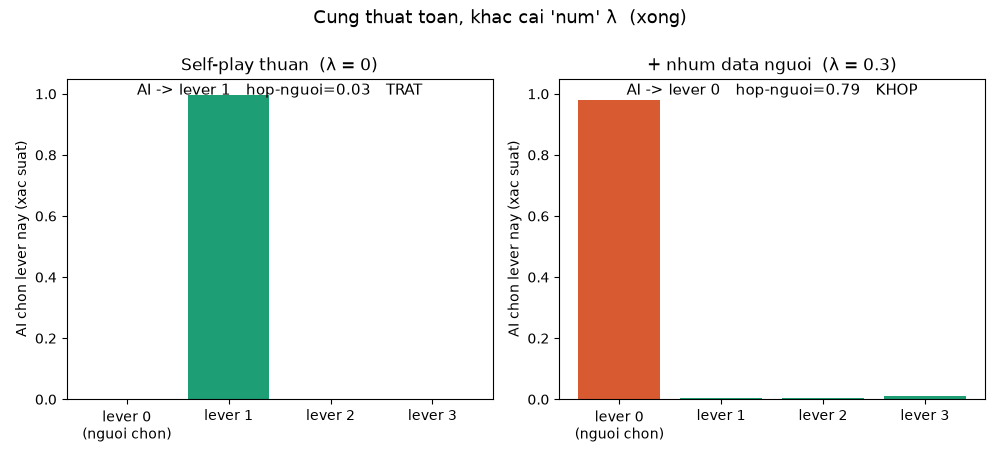
Hands-on, runnable demos of SPICED (self-play + a pinch of human data, arxiv 2606.19370) at tiny scale on a Mac M5: demo-regularized self-play, the RLHF KL knob, and LoRA on a real LLM.
Can a dense LLM be made sparse for faster local inference? Converting Qwen3.5-9B FFNs into Mixture-of-Experts, with Triton kernels on AMD RDNA4 (ROCm), benchmarked by KL divergence against llama.cpp GGUF quantization and MTP speculative decoding.
KL-divergence + blind task eval of GLM-4.7-Flash and its REAP-pruned variant vs gpt-oss-20b on llama.cpp
Variational autoencoders using Kera's modular design