kserve
Standardized Distributed Generative and Predictive AI Inference Platform for Scalable, Multi-Framework Deployment on Kubernetes
- 6.3k
- Go
- Apache-2.0
- 13 h ago
Standardized Distributed Generative and Predictive AI Inference Platform for Scalable, Multi-Framework Deployment on Kubernetes
cube studio开源云原生一站式机器学习/深度学习/大模型AI平台,mlops算法链路全流程,算力租赁平台,notebook在线开发,拖拉拽任务流pipeline编排,多机多卡分布式训练,超参搜索,推理服务VGPU虚拟化,边缘计算,标注平台自动化标注,deepseek等大模型sft微调/奖励模型/强化学习训练,vllm/ollama/mindie大模型多机推理,私有知识库,AI模型市场,支持国产cpu/gpu/npu 昇腾生态,支持RDMA,支持pytorch/tf/mxnet/deepspeed/paddle/colossalai/horovod/ray/volcano等分布式
A guideline for building practical production-level deep learning systems to be deployed in real world applications.
WARNING: Katib project is DEPRECATED, users should migrate to OptimizationJob and Kubeflow Trainer
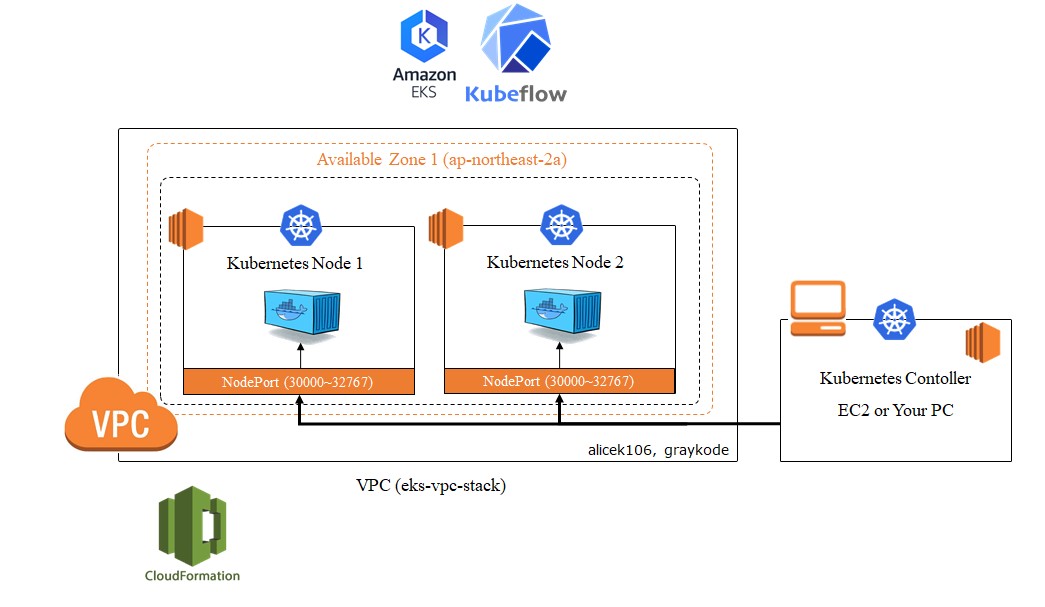
DoEKS is a tool to build, deploy and scale Data Platforms on Amazon EKS
Kubernetes Operator for MPI-based applications (distributed training, HPC, etc.)
Kubernetes Guide. Learn all about Kubernetes monitoring, networking, and containers. Whether you're running Kubernetes Locally or in the Cloud ( Azure, AWS, and GCP).
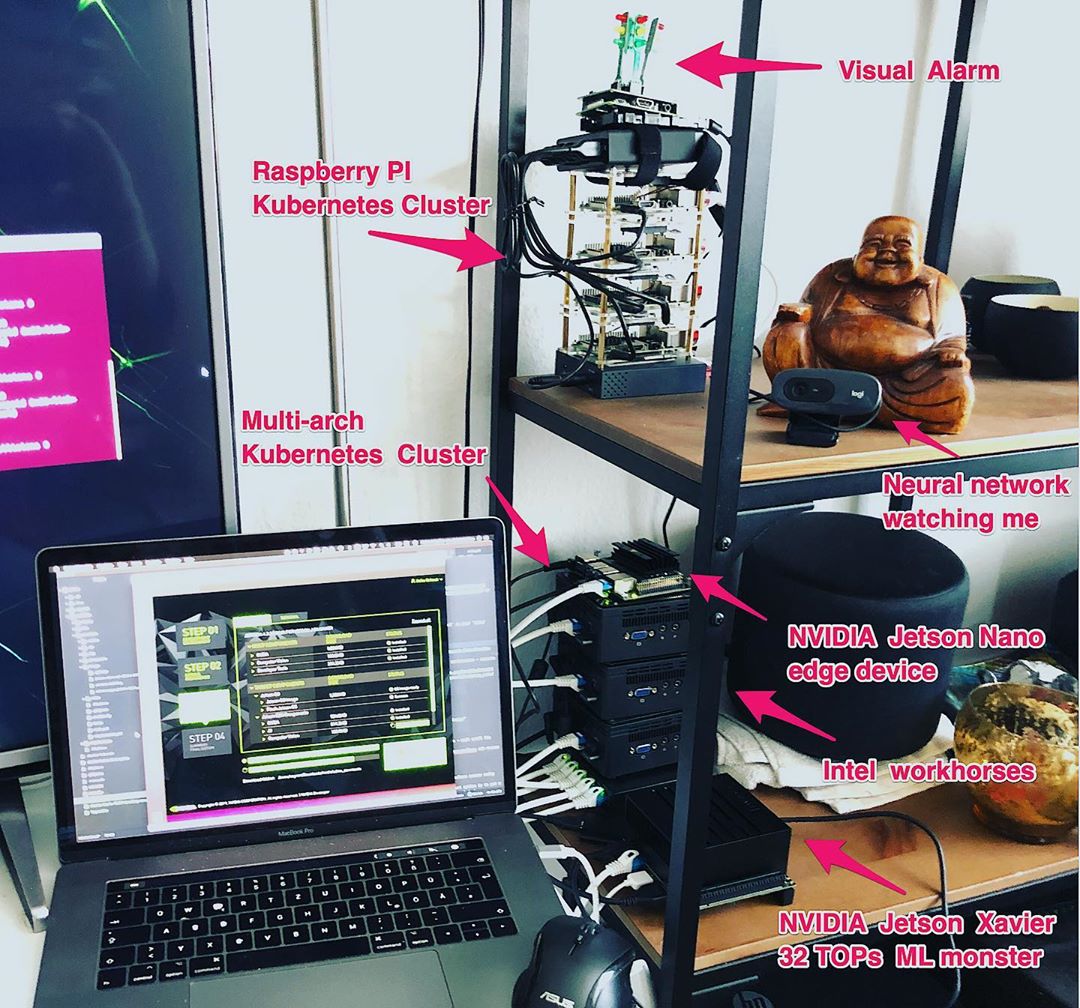
Helmut Hoffer von Ankershoffen experimenting with arm64 based NVIDIA Jetson (Nano and AGX Xavier) edge devices running Kubernetes (K8s) for machine learning (ML) including Jupyter Notebooks, TensorFlow Training and TensorFlow Serving using CUDA for smart IoT.
Information about the Kubeflow community including proposals and governance information.
Transform your pythonic research to an artifact that engineers can deploy easily.
Hands-on MLOps projects to explore and learn the practical aspects of machine learning engineering for production.
Coursera Machine Learning Engineering for Production Specialization Course
Template for multi-modal machine learning in healthcare using Kedro. Combine reports, tabular data and images using various fusion methods.
Production-grade MLOps: Model deployment, monitoring, feature stores, and ML pipelines for real-world AI systems.
This repository bootstraps a fully functional Kubernetes cluster from scratch on a single VPS using QEMU/KVM virtual machines. Every component is installed manually: no kubeadm, no managed control plane, no cloud provider.
Deep-dive MLOps curriculum — 12 self-contained modules across orchestration, streaming, ML platforms, LLM apps, IaC, and observability, with projects and interview prep.
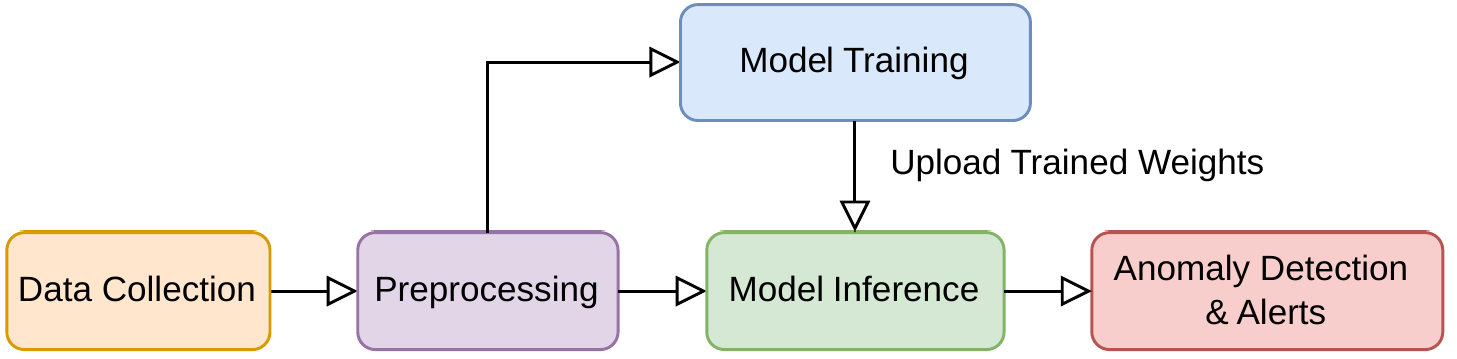
Deep-learning thermal anomaly detection for HPC datacenters: autoencoder and LSTM-AE models on Marconi-100 supercomputer telemetry (ExaMon), with a Kubernetes/Kubeflow MLOps pipeline for real-time monitoring, alerting, and predictive maintenance.
A CLI to deploy and run ML workflows using Kubeflow. Strictly WIP - Not suitable for use as of now.
GRaph Anomaly Anticipation Framework for Exascale HPC — GNN-based node anomaly prediction on CINECA Marconi100, with offline GNN training and online Kubernetes/Kubeflow MLOps deployment (published in Future Generation Computer Systems).