vmlx
vMLX - Use MLX models easily - JANGQ (GGUF for MLX) - Not dependant on mlx_vlm
- 923
- Python
- Apache-2.0
- 2 wk ago
vMLX - Use MLX models easily - JANGQ (GGUF for MLX) - Not dependant on mlx_vlm
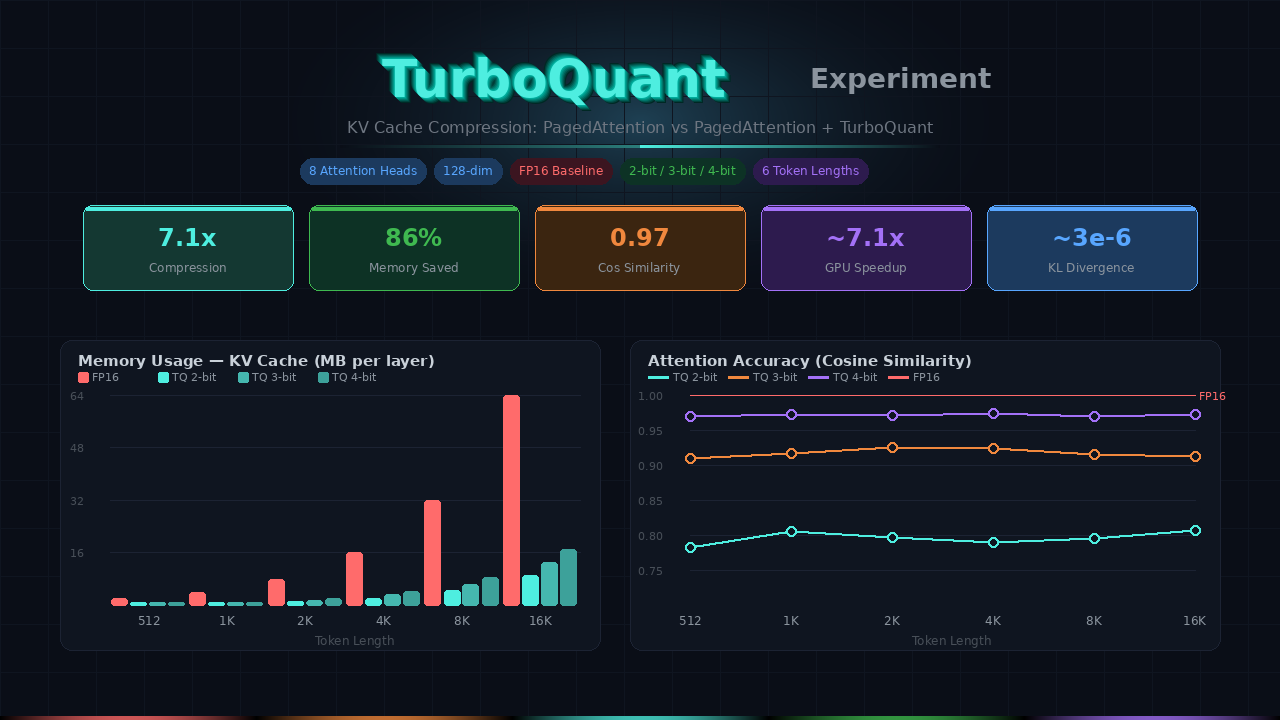
KV Cache with PagedAttention vs PagedAttention + TurboQuant - experiments across token sizes comparing memory, latency, and accuracy.