MMStar
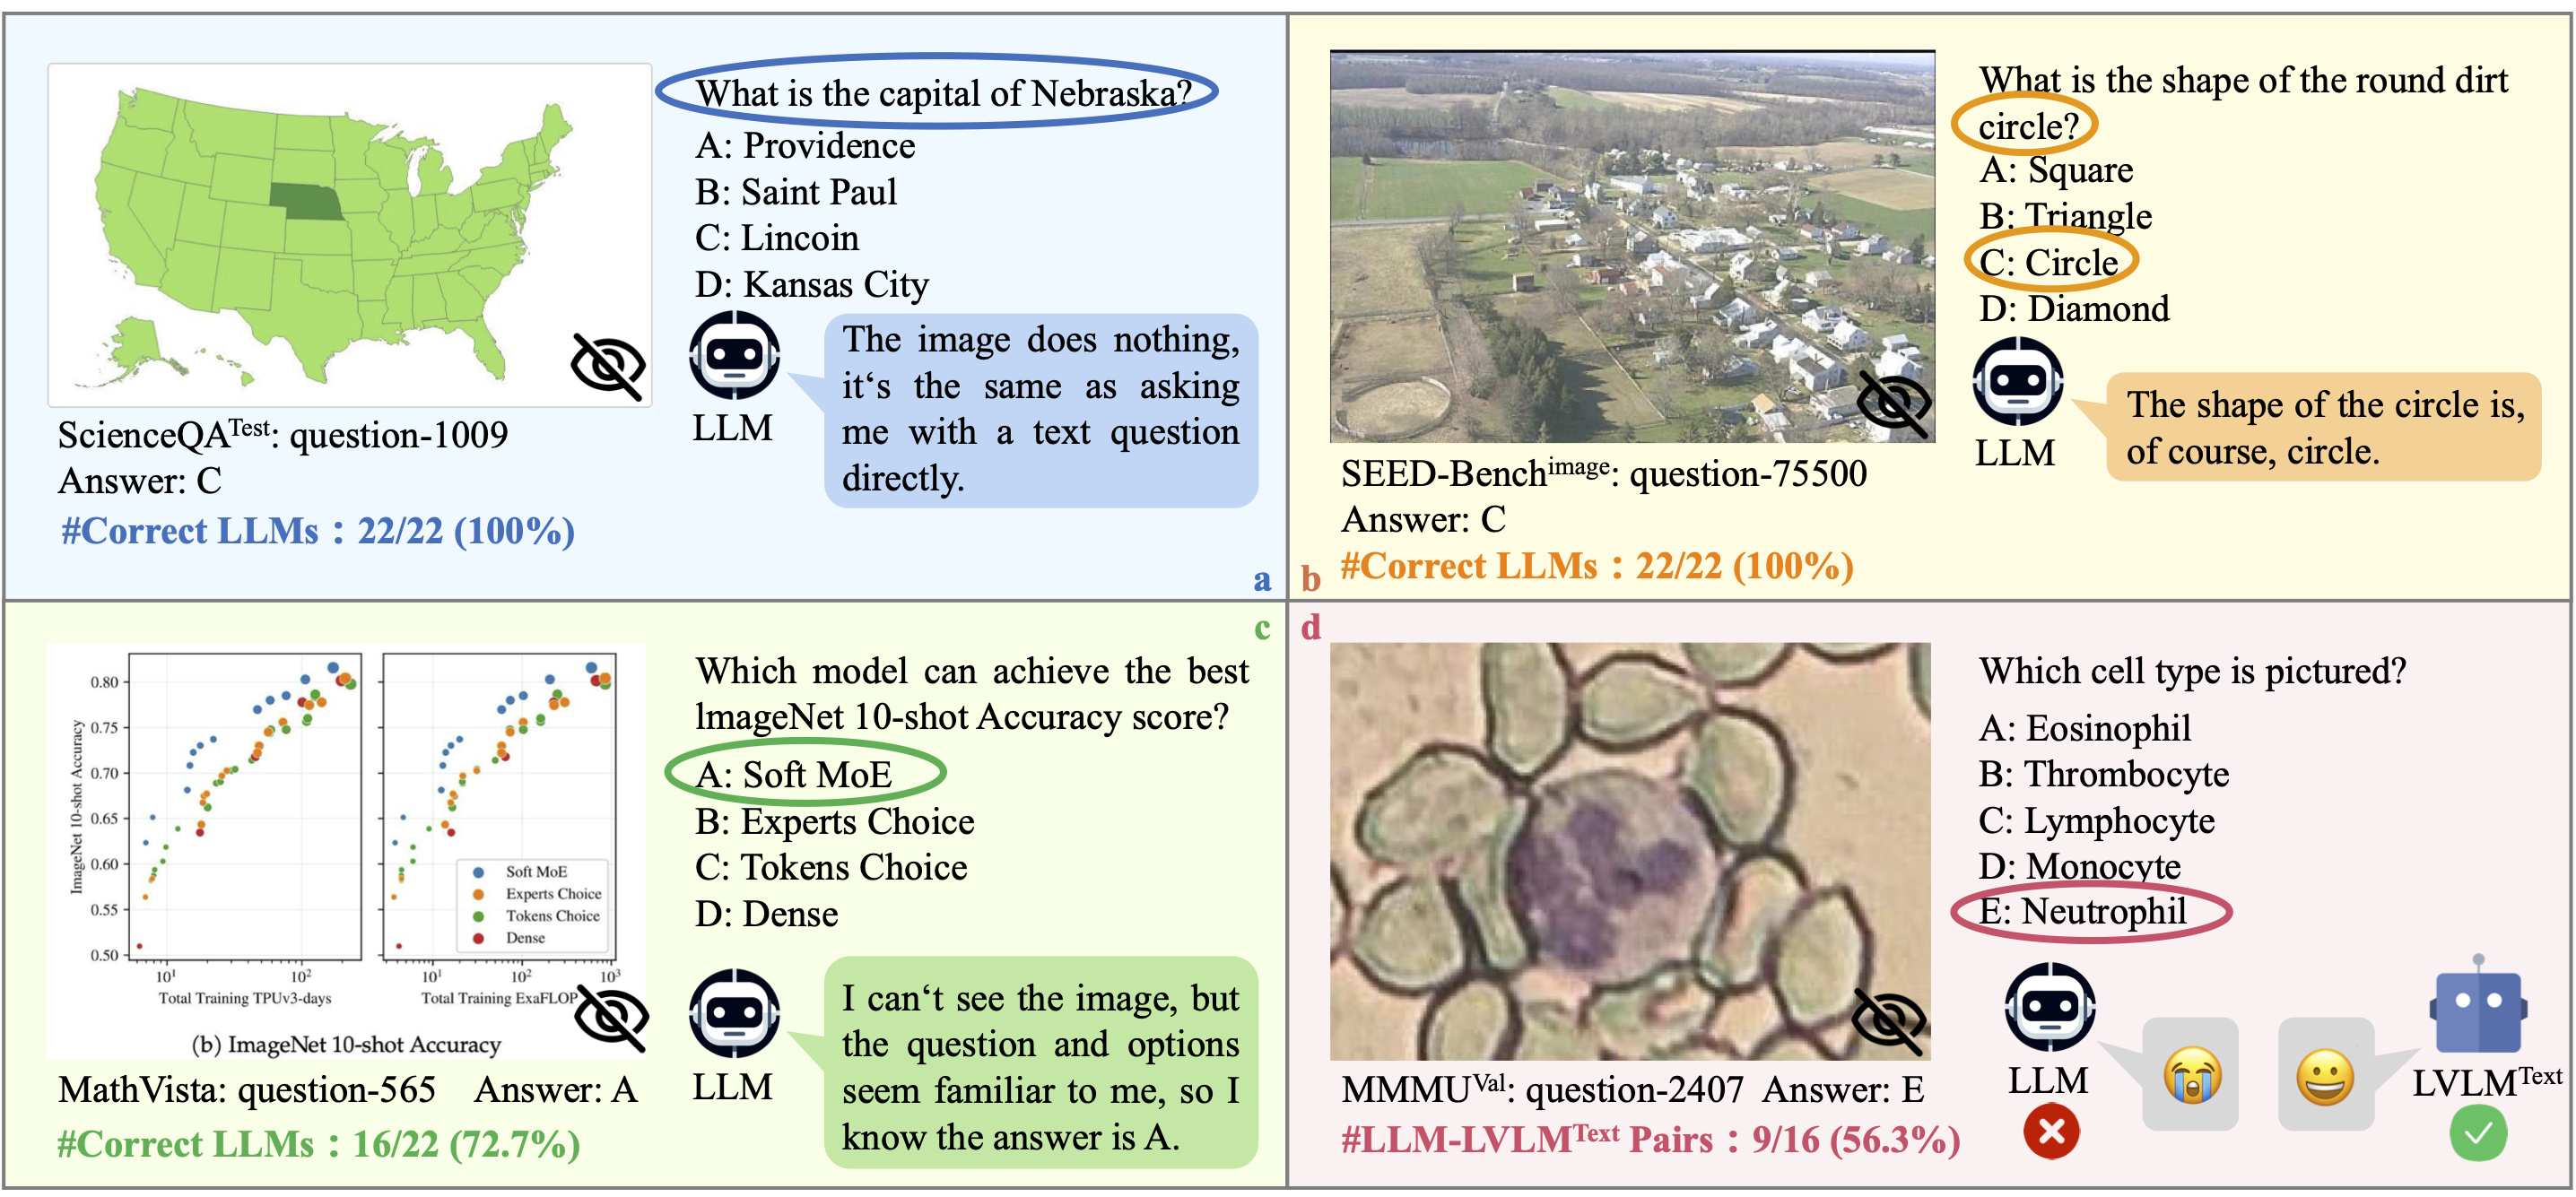
[NeurIPS 2024] This repo contains evaluation code for the paper "Are We on the Right Way for Evaluating Large Vision-Language Models"
- 218
- Python
- 2 y ago
[NeurIPS 2024] This repo contains evaluation code for the paper "Are We on the Right Way for Evaluating Large Vision-Language Models"
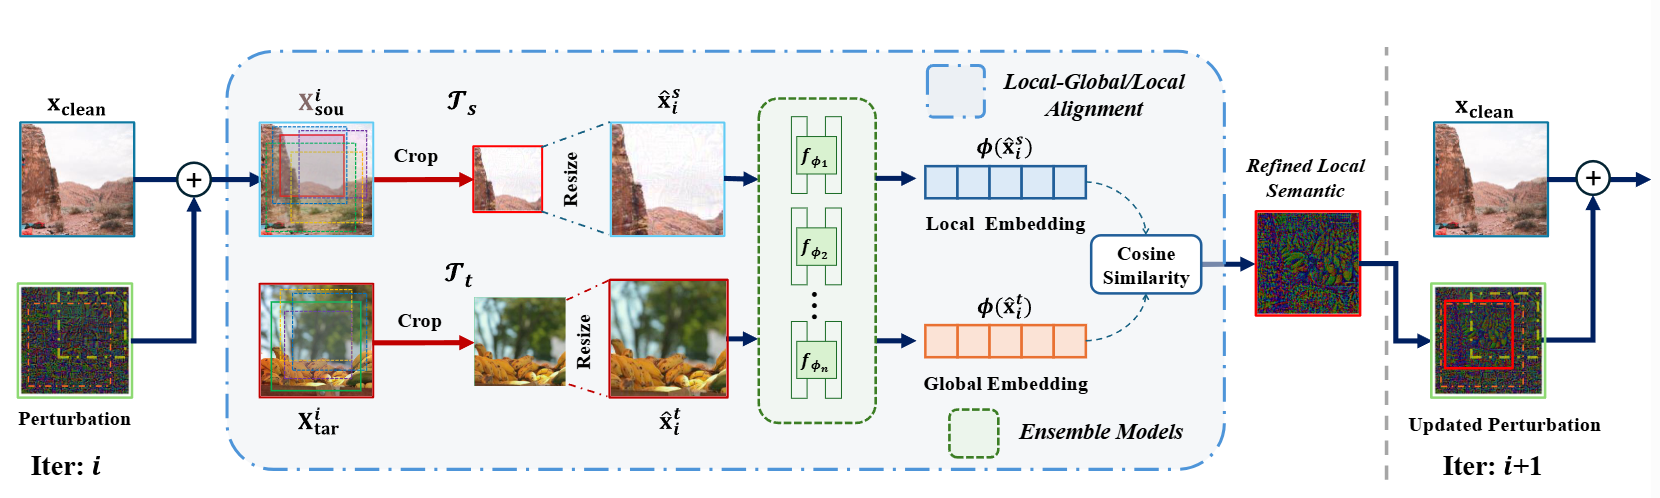
[NeurIPS25 & ICML25 Workshop on Reliable and Responsible Foundation Models] A Simple Baseline Achieving Over 90% Success Rate Against the Strong Black-box Models of GPT-4.5/4o/o1. Paper at: https://arxiv.org/abs/2503.10635
[ICLR'25] Dysca: A Dynamic and Scalable Benchmark for Evaluating Perception Ability of LVLMs
A powerful Streamlit application that allows users to analyze and interact with YouTube video content through natural language questions.