oneDNN
Open-source library of optimized deep learning operations (matmul, convolution, attention) for CPUs (x64, AArch64, RISC-V) and Intel GPUs. Used by PyTorch, TensorFlow, OpenVINO, and ONNX Runtime.
- 4.1k
- C++
- Apache-2.0
- 8 h ago
Open-source library of optimized deep learning operations (matmul, convolution, attention) for CPUs (x64, AArch64, RISC-V) and Intel GPUs. Used by PyTorch, TensorFlow, OpenVINO, and ONNX Runtime.
Distributed Communication-Optimal Matrix-Matrix Multiplication Algorithm
Matrix multiplication on GPUs for matrices stored on a CPU. Similar to cublasXt, but ported to both NVIDIA and AMD GPUs.
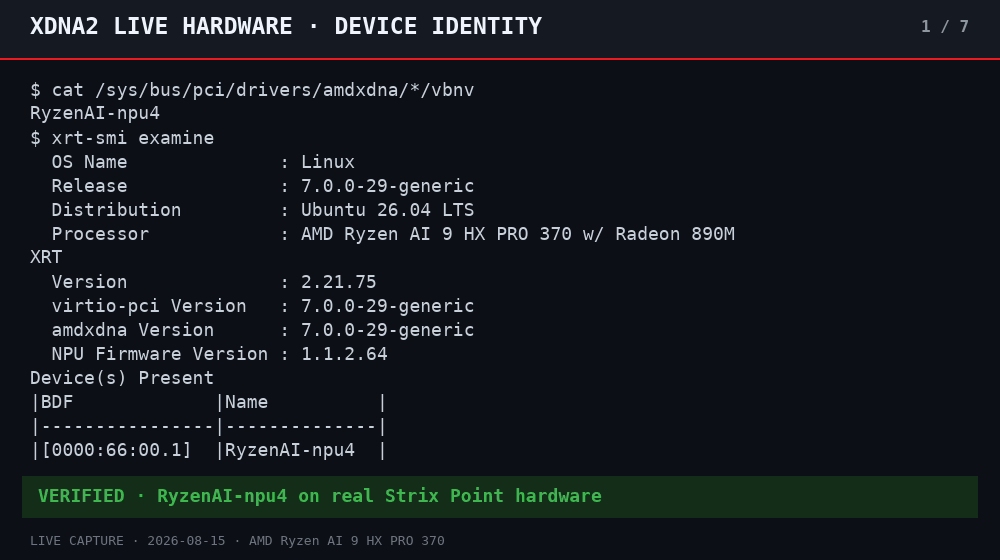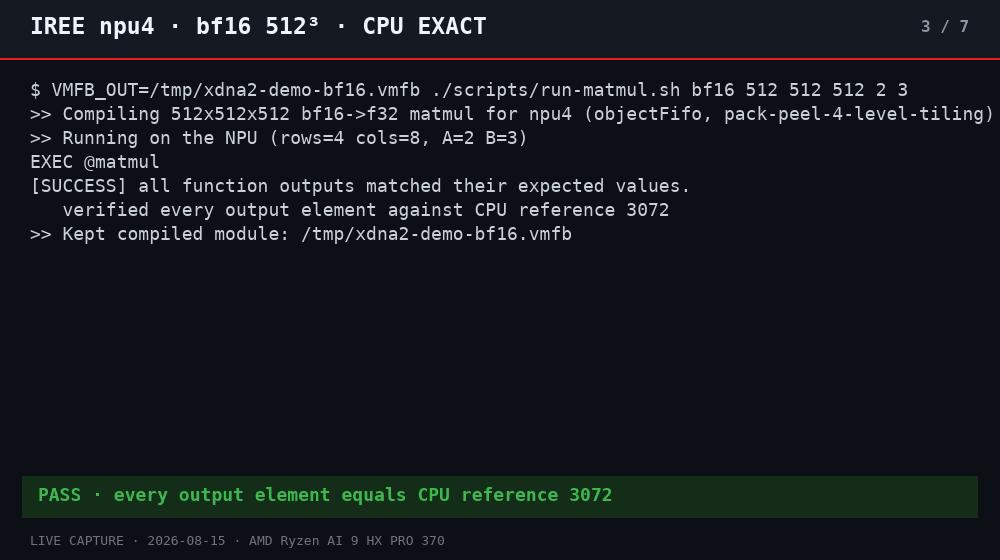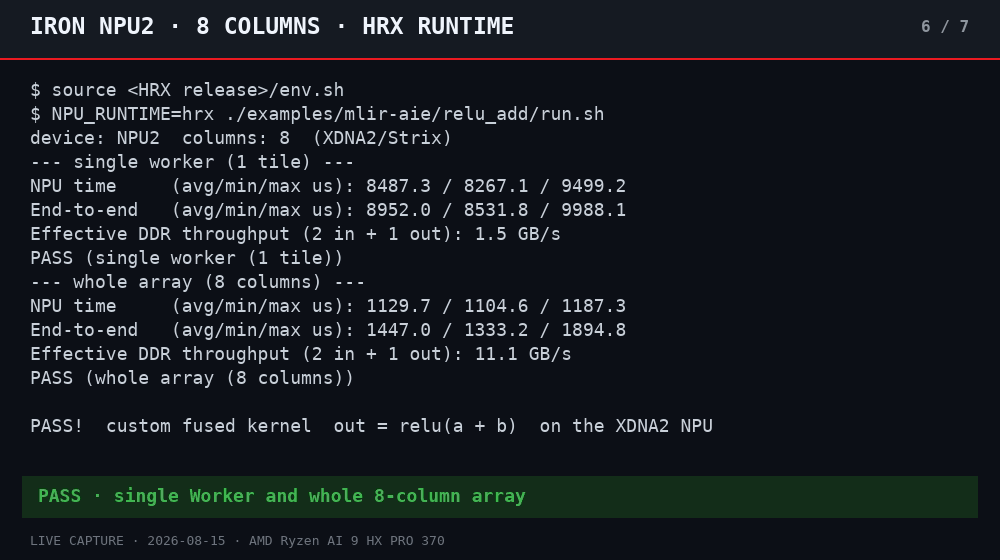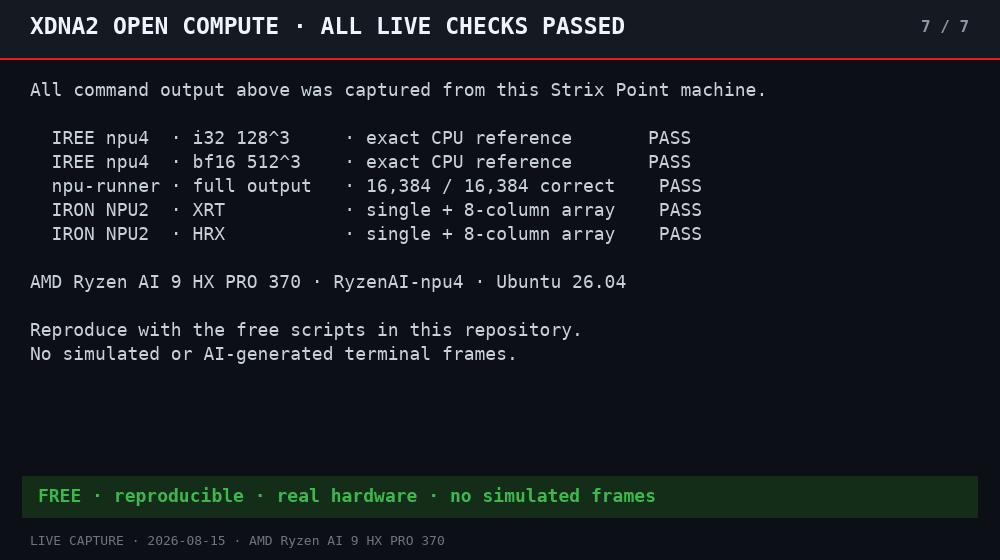
Open, reproducible AMD XDNA1 + Strix Point XDNA2 compute on Linux: pinned builds, CPU-reference checks, persistent C/Python runners, and an LLM roadmap.
Optimised matrix multiplication kernels for acceleration on the Tenstorrent Tensix architecture
PTX matrix multiplication library for NVIDIA GPUs, exposing a single C `matmul` function that runs FP16 tensor-core GEMM through the NVIDIA Driver API without CUDA C, nvcc, or cuBLAS.