deepvoice3_pytorch
PyTorch implementation of convolutional neural networks-based text-to-speech synthesis models
- 2k
- Python
- 3 y ago
PyTorch implementation of convolutional neural networks-based text-to-speech synthesis models
Vui Nano — a small, context-aware text-to-speech model trained on real conversations. 219M active params (305M total), Apache 2.0, voice cloning, streaming, runs on CPU (dependency-free C build). Ships with a full real-time voice assistant: WebRTC, ASR, local LLM, OpenAI Realtime API compatible.
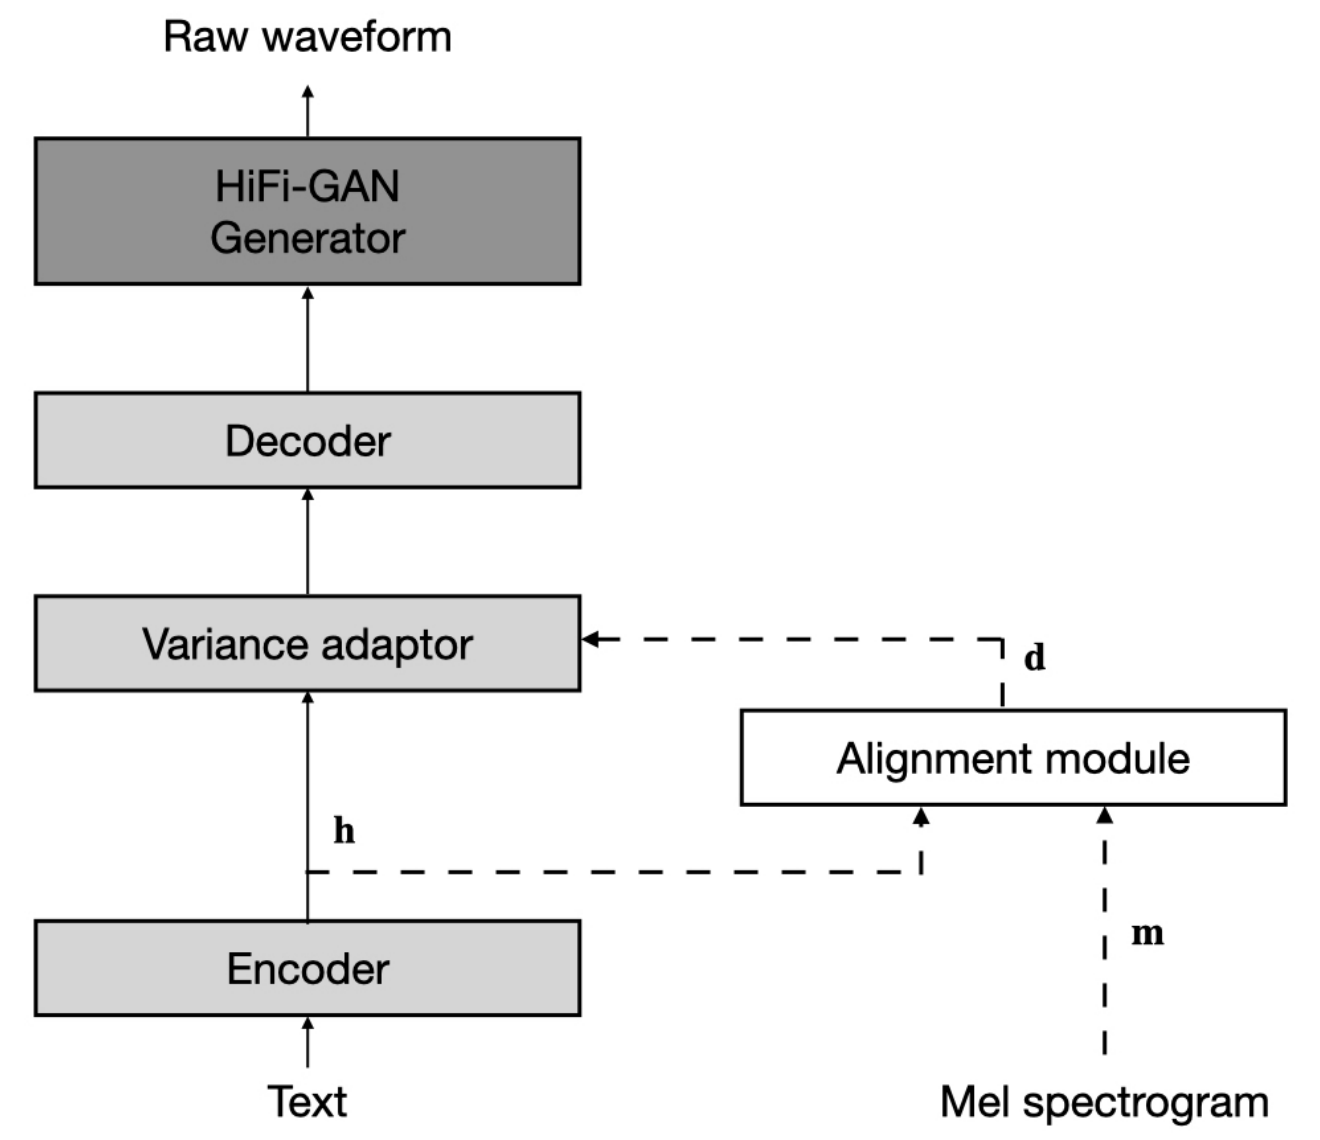
A Non-Autoregressive Transformer based Text-to-Speech, supporting a family of SOTA transformers with supervised and unsupervised duration modelings. This project grows with the research community, aiming to achieve the ultimate TTS
A Non-Autoregressive End-to-End Text-to-Speech (text-to-wav), supporting a family of SOTA unsupervised duration modelings. This project grows with the research community, aiming to achieve the ultimate E2E-TTS
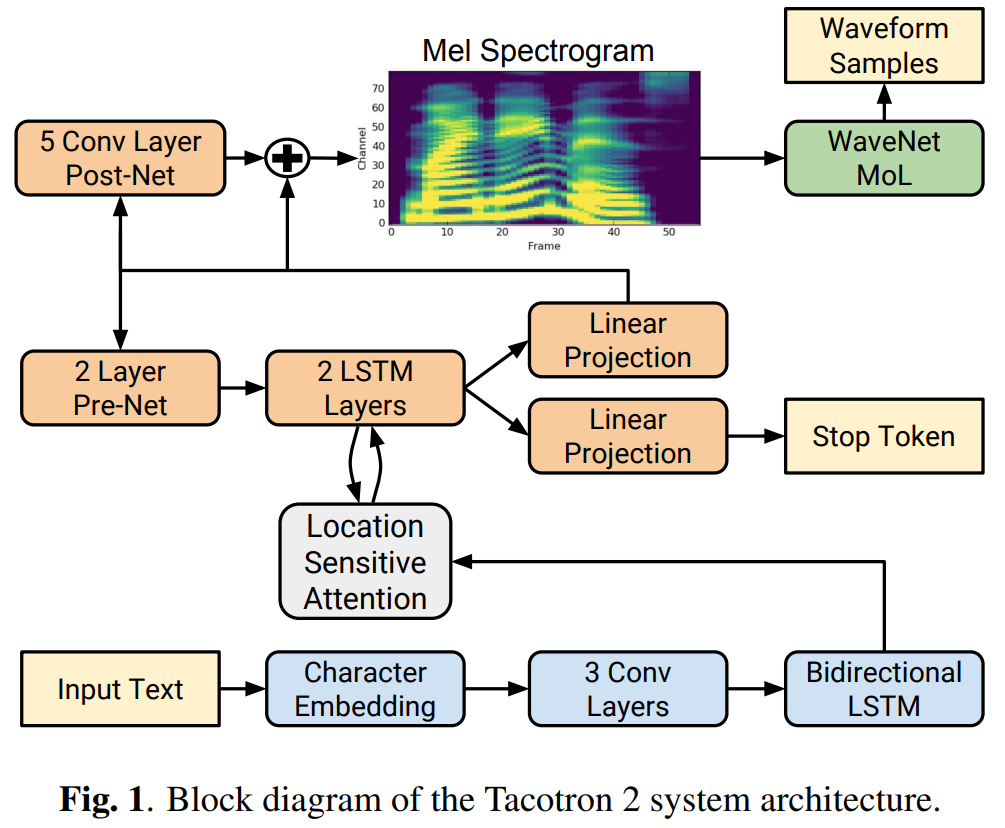
PyTorch Implementation of Google's Natural TTS Synthesis by Conditioning WaveNet on Mel Spectrogram Predictions. This implementation supports both single-, multi-speaker TTS and several techniques to enforce the robustness and efficiency of the model.