nvme

Open repos and models their makers tagged nvme, most starred first. The same for everyone.

AI on my own machineRepo

janas

37 tok/s from Qwen3-Next-80B (48 GB) on a 32 GB laptop, 24 without drafts vs 2.8 for llama.cpp; reading 62 vs 16 tok/s. Faster than llama.cpp on all 13 models compared in Q4_K_M. LLMs bigger than your RAM, pure C, CPU or GPU.

  • 734
  • C
  • GPL-3.0
  • 1 d ago
prabanta-devTake it
AI on my own machineRepo

modelfs

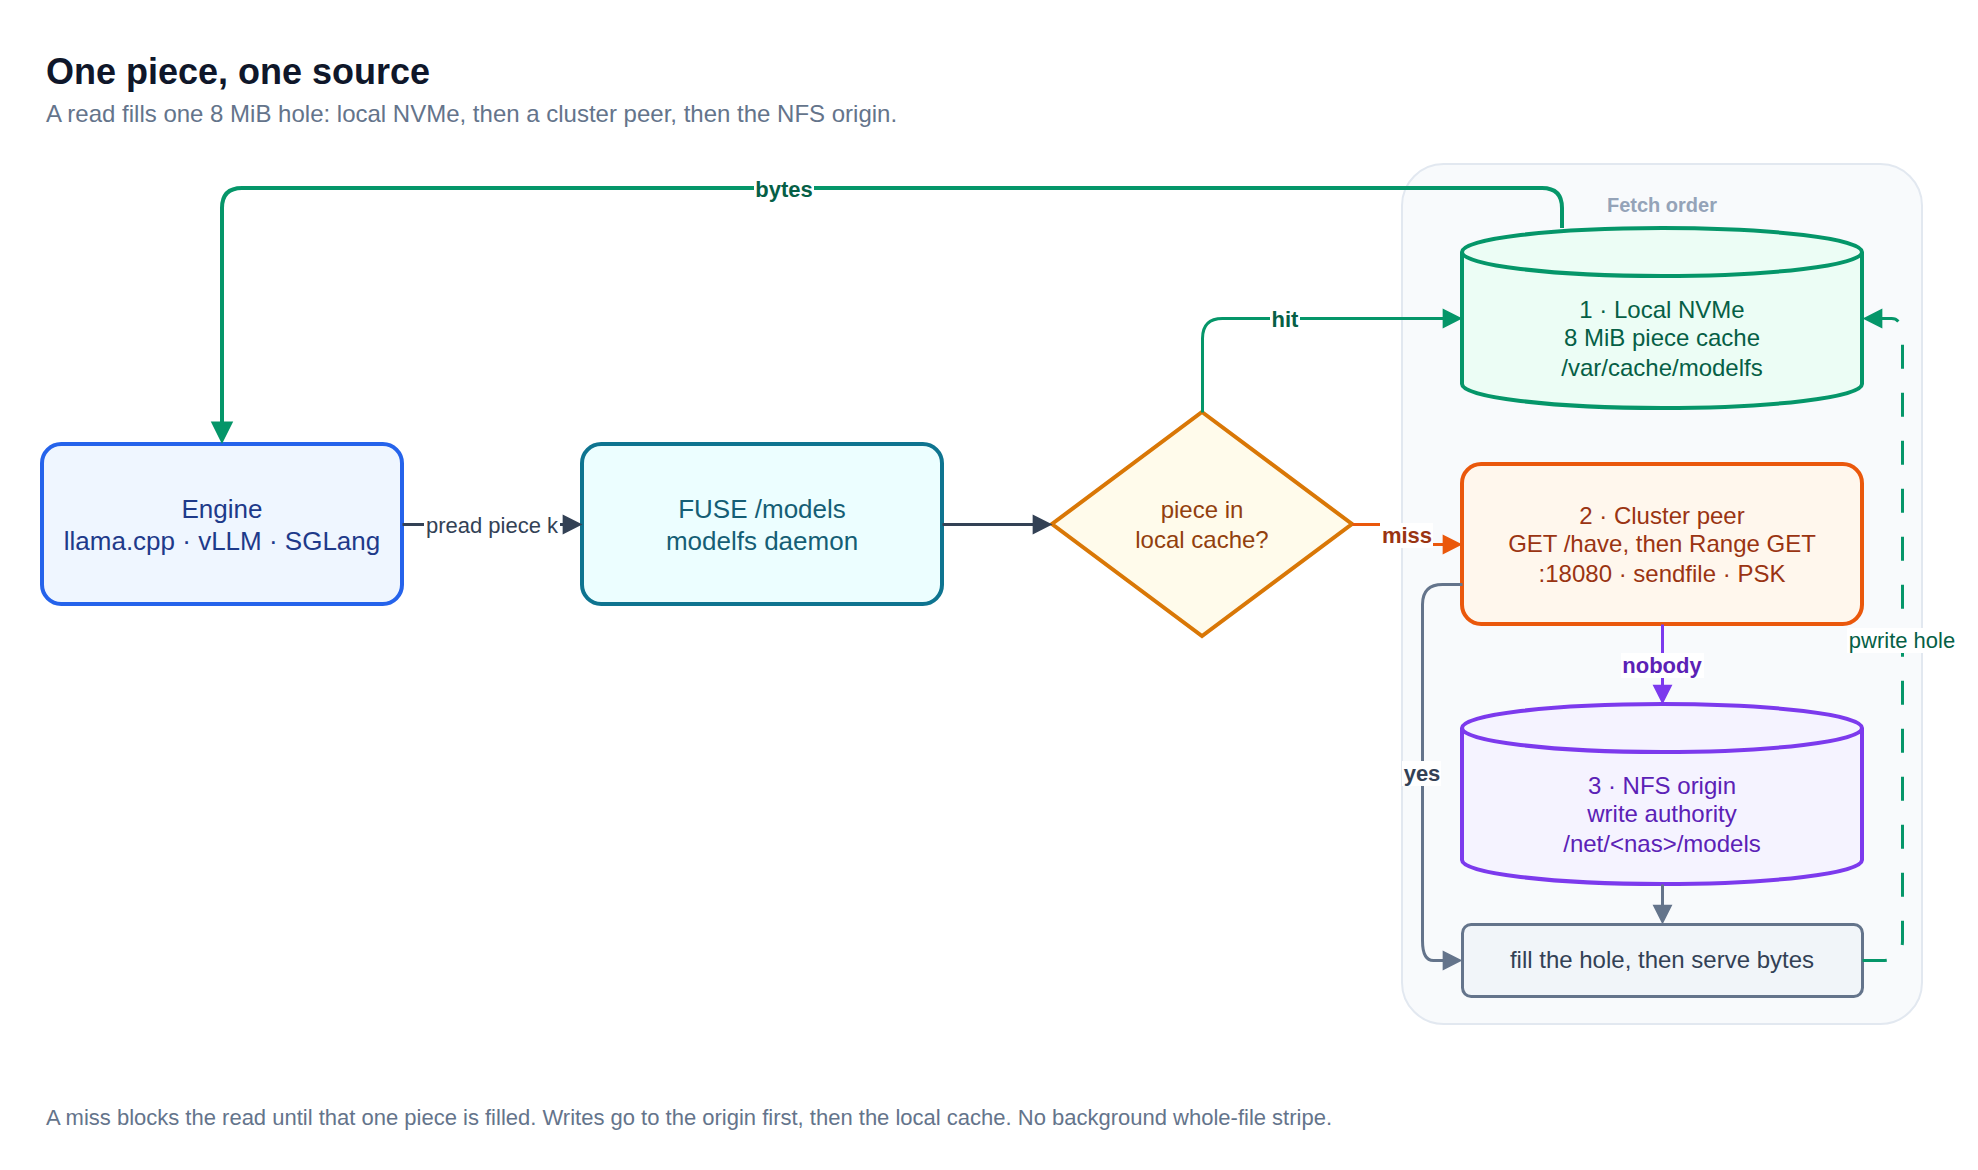
POSIX /models mount for LLM weights: one Zig FUSE binary per node, local NVMe piece cache, peer-to-peer transfers via sendfile

  • 1
  • Zig
  • GPL-3.0
  • 2 d ago
maci0Take it
Search GitHub and Hugging Face for nvme

Get , open it once and sign in. Then come back here and press the button again.