inferssd
Run models larger than your RAM or VRAM by streaming MoE experts from SSD. Built on llama.cpp.
- 1.3k
- C++
- Apache-2.0
- 3 h ago
Run models larger than your RAM or VRAM by streaming MoE experts from SSD. Built on llama.cpp.
Xolotl: run DeepSeek-V4.1-Flash, all 552B, as a local coding agent on one gaming PC (RTX 4090 + 110 GB RAM): ~33 tok/s agent, ~41 fast, 512K context. Plus Inkling-2-Mini (Thinking Machines, own engine + MTP drafter), GLM-5.3-Flash, Qwen3.8, LFM3-Omni. MoE experts tiered across VRAM, RAM and NVMe (Xolotl Direct). OpenAI + Anthropic API.
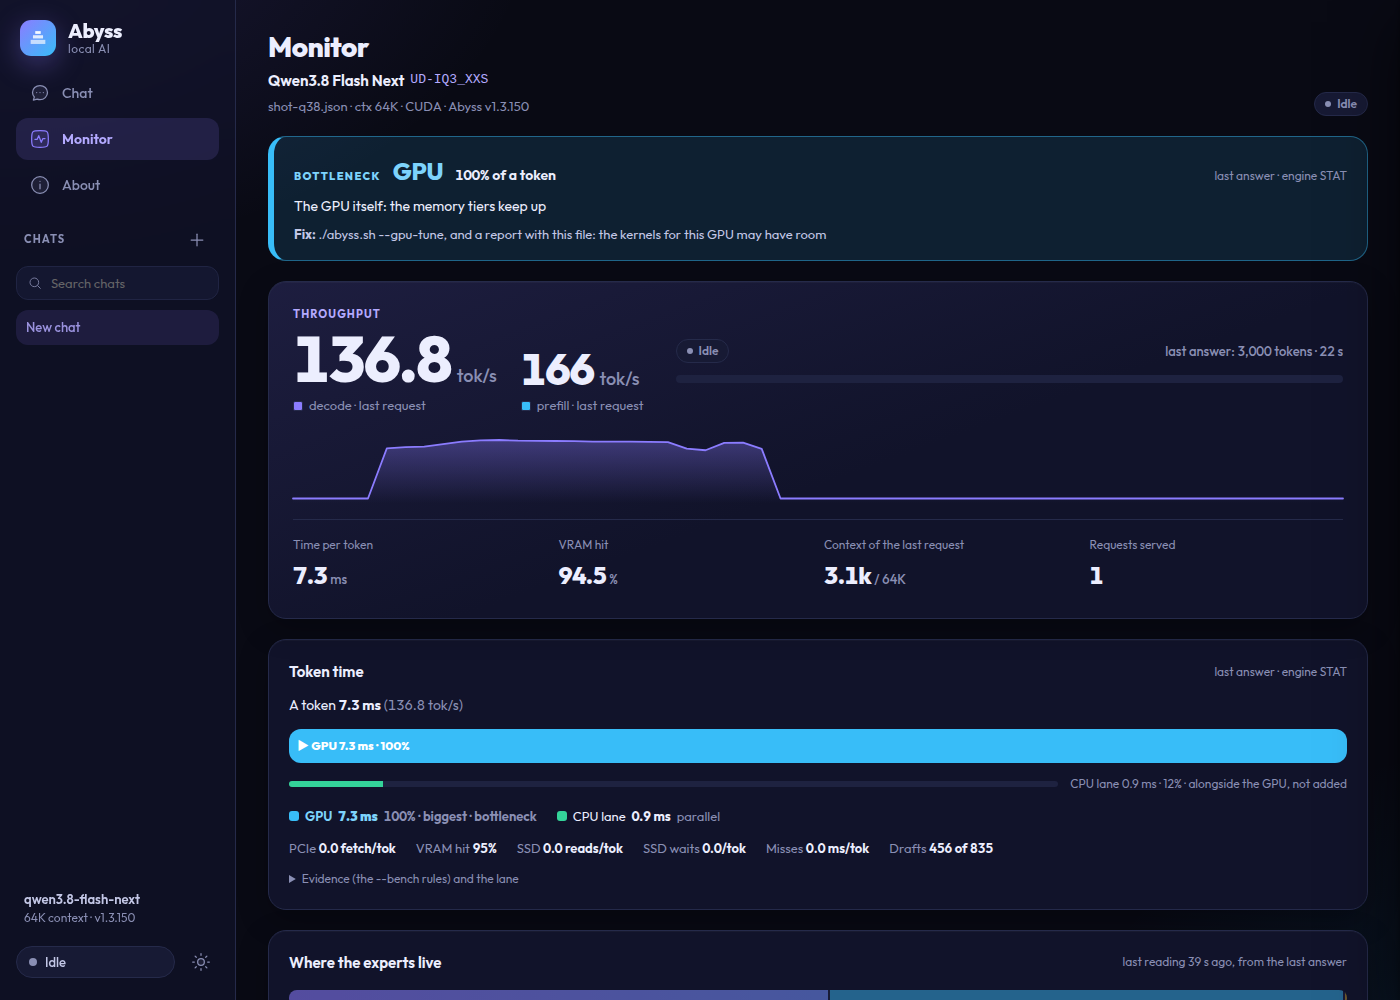
Run 50-280 GB MoE LLMs (DeepSeek V4/V4.1 Flash, GLM-5.3-Flash, Qwen3.8-Flash-Next, Ornith) on one consumer GPU: experts spread over VRAM, RAM and NVMe SSD. Browser chat + OpenAI/Anthropic APIs. CUDA, ROCm, DGX Spark.
ZO2 (Zeroth-Order Offloading): Full Parameter Fine-Tuning 175B LLMs with 18GB GPU Memory [COLM2025]
Run GLM-5.3-Flash, DeepSeek-V4.1-Flash and MiniMax-M3.1-Flash locally on your own NVIDIA GPU with fast, private chat and OpenAI/Anthropic-compatible API.
Java implementation of Home Edge project with sub set of features for Android support
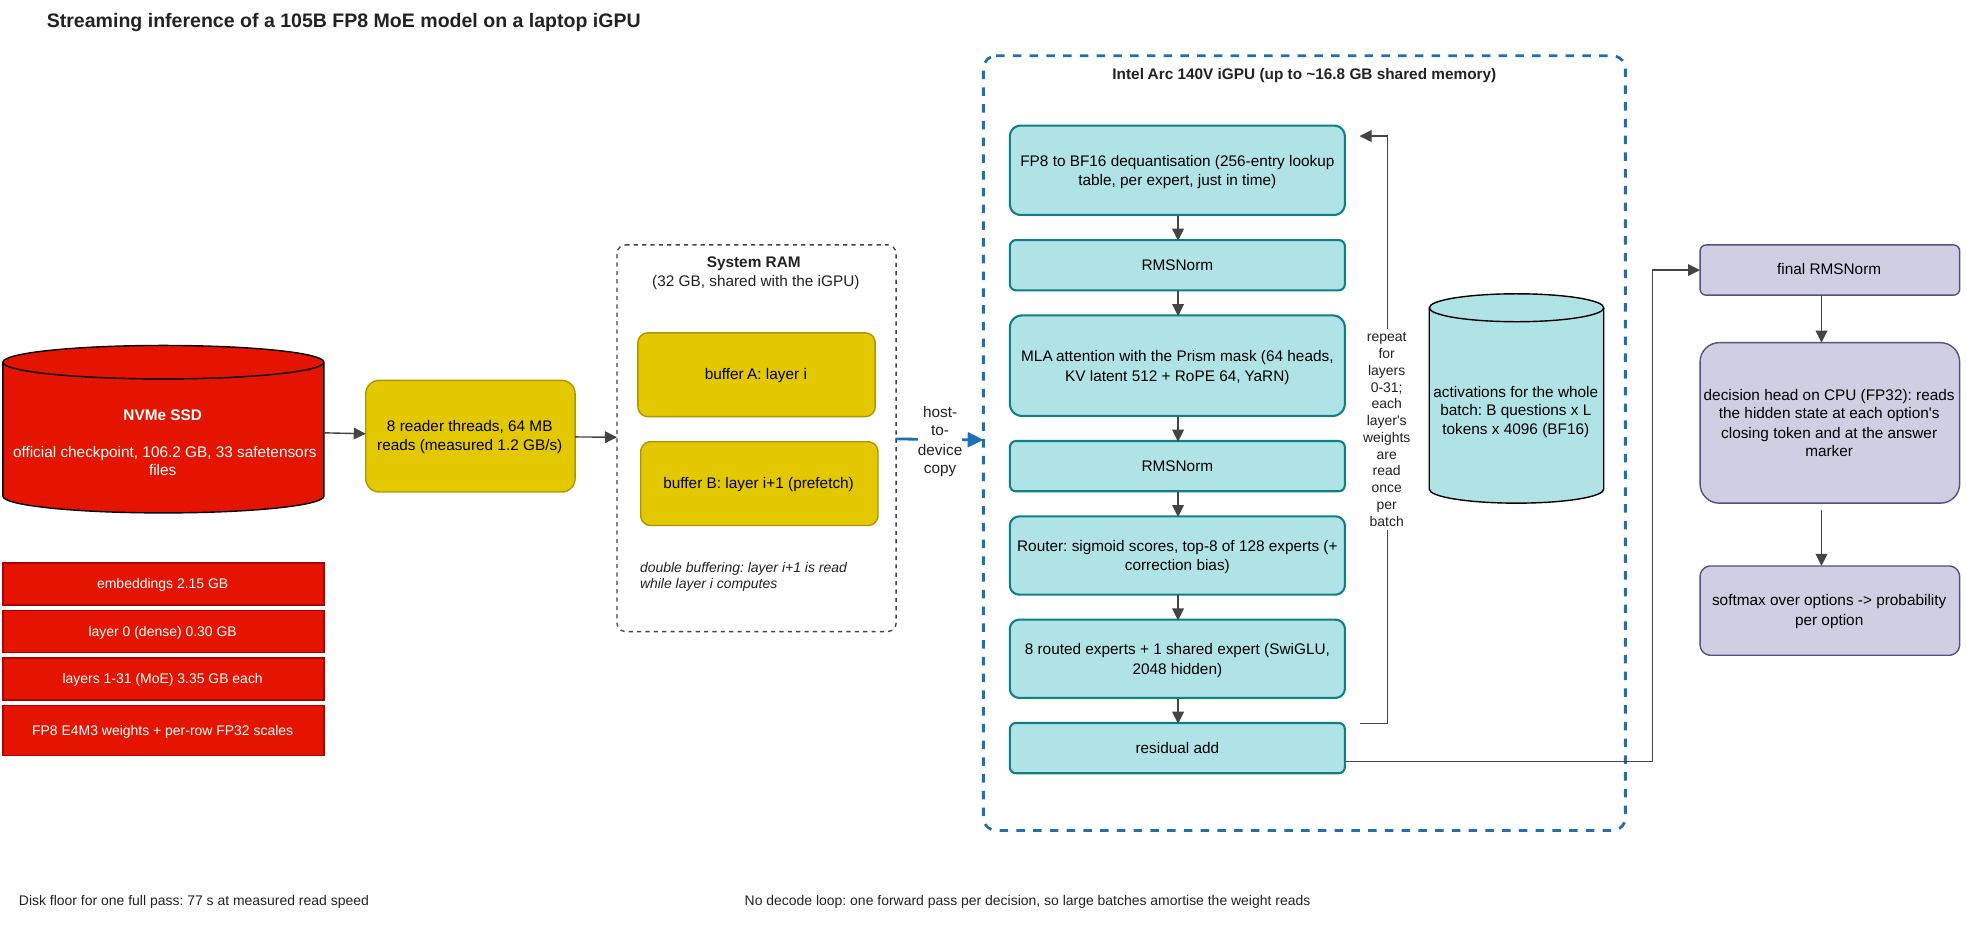
Run Sarvam's 105B FP8 MoE decision model (Prism) on a laptop iGPU by streaming layers from SSD, plus an expert-pruning study. Pure PyTorch.
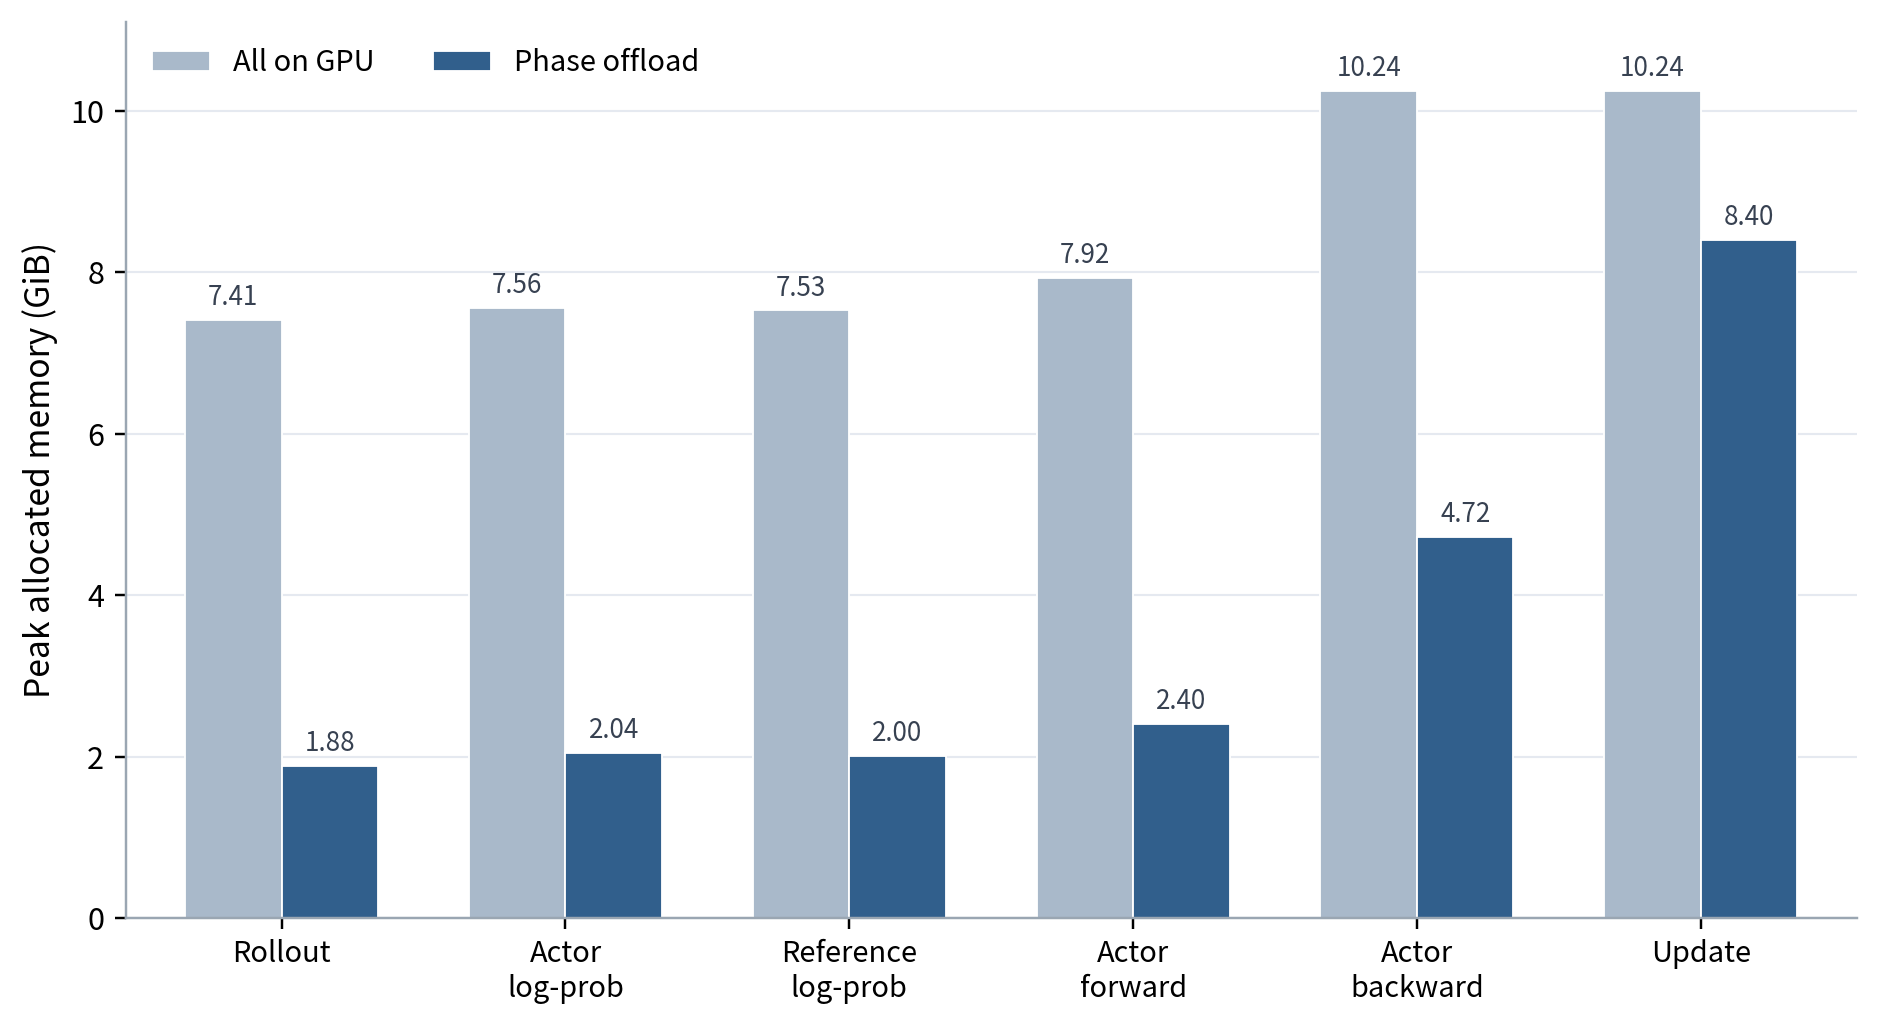
Memory-efficient full-parameter GRPO on a single GPU with phase-aware offloading, CPU AdamW, and async gradient streaming.
Running large language models on a single M1/M2 GPU for throughput-oriented scenarios.
A simple system to offload coding tasks to local llm through agentic first ide