shimmy
⚡ Pure-Rust WebGPU inference engine — OpenAI-API compatible, GGUF native, runs on any GPU. No Python. No llama.cpp. Single binary.
- 6k
- Rust
- Apache-2.0
- 8 d ago
⚡ Pure-Rust WebGPU inference engine — OpenAI-API compatible, GGUF native, runs on any GPU. No Python. No llama.cpp. Single binary.
GraphRAG-rs is a high-performance, state-of-the-art Rust implementation of GraphRAG (Graph-based Retrieval Augmented Generation) that builds knowledge graphs from documents and enables natural language querying with configurable entity extraction and local LLM integration
A Ruby gem for interacting with Ollama's API that allows you to run open source AI LLMs (Large Language Models) locally.
Connect MATLAB to LLM APIs, including OpenAI® Chat Completions, Azure® OpenAI Services, and Ollama™
Self-hosted alternative to OpenAI's Responses API compatible with Agents SDK and works with all model providers (Claude/R1/Qwen/Ollama etc)
SmarterRouter: An intelligent LLM gateway and VRAM-aware router for Ollama, llama.cpp, and OpenAI. Features semantic caching, model profiling, and automatic failover for local AI labs.
Extend the Ollama API with dynamic AI tool integration from multiple MCP (Model Context Protocol) servers. Fully compatible, transparent, and developer-friendly, ideal for building powerful local LLM applications, AI agents, and custom chatbots
Ollama负载均衡服务器 | 一款高性能、易配置的开源负载均衡服务器,优化Ollama负载。它能够帮助您提高应用程序的可用性和响应速度,同时确保系统资源的有效利用。
Ollama-compatible LLM server. Beats vllm by 40% on single stream decode, and by 20% on multi stream decode, and beats ollama by much 2-4x. Made possible with custom CUDA kernels, MTP, speculation and its own 3-bit builds. Uncensors models in one command. Windows and Linux, NVIDIA. Optimized to not eat up ram.
Ollama with Let's Encrypt Using Docker Compose
Python command-line tool for interacting with AI models through the OpenRouter API/Cloudflare AI Gateway, or local self-hosted Ollama. Optionally support Microsoft LLMLingua prompt token compression
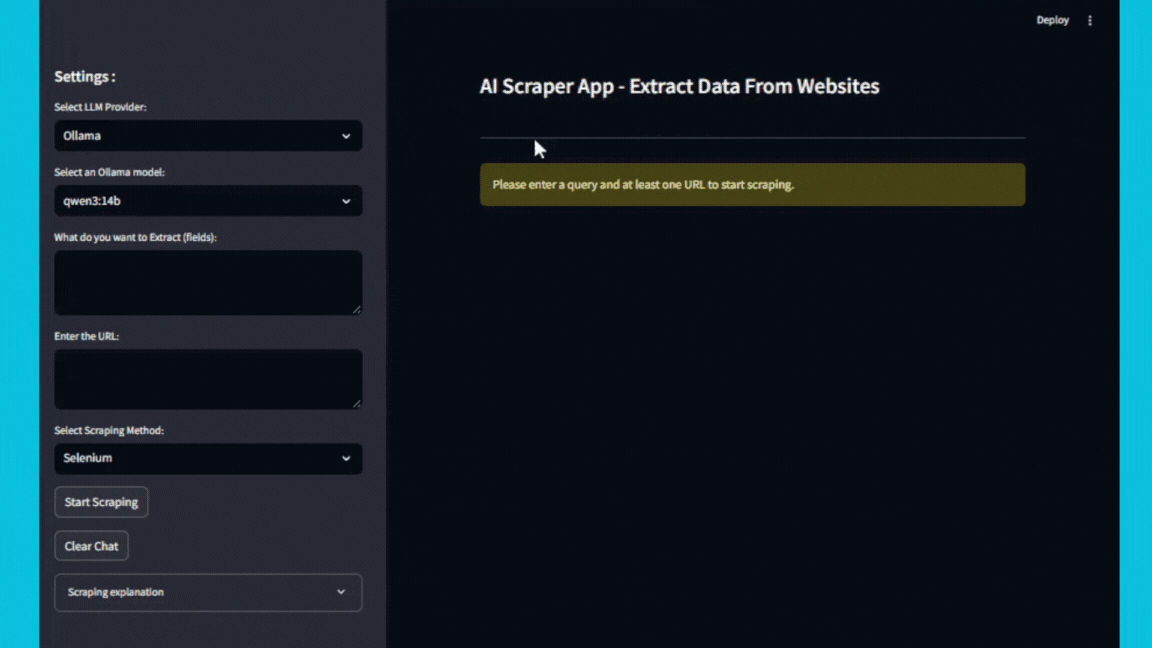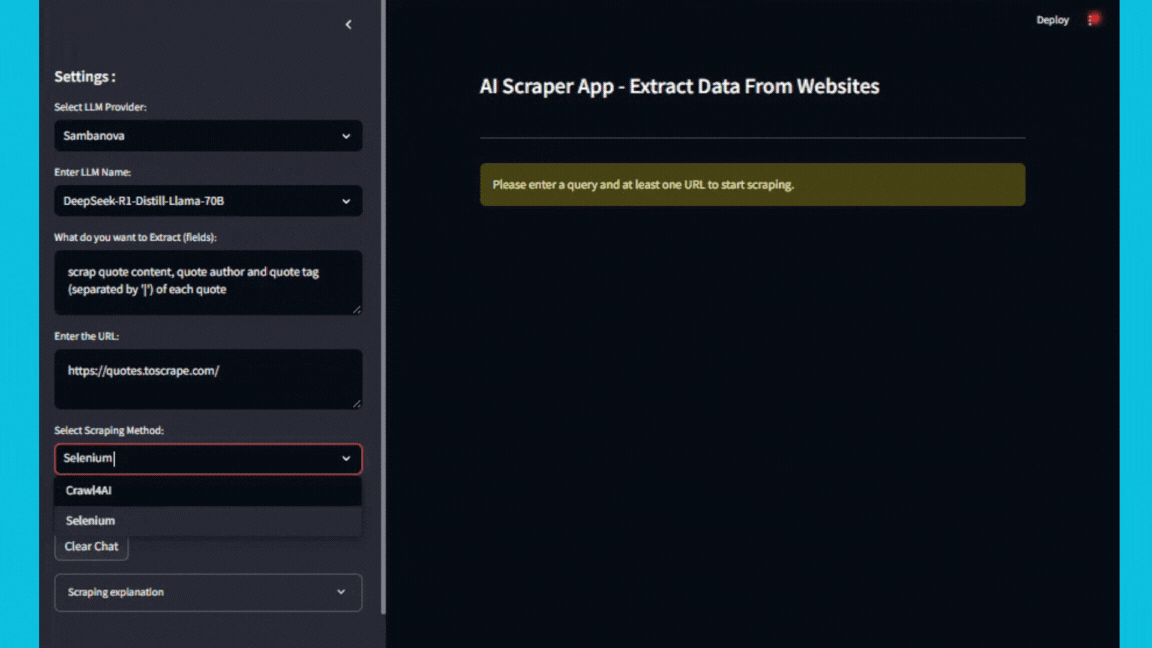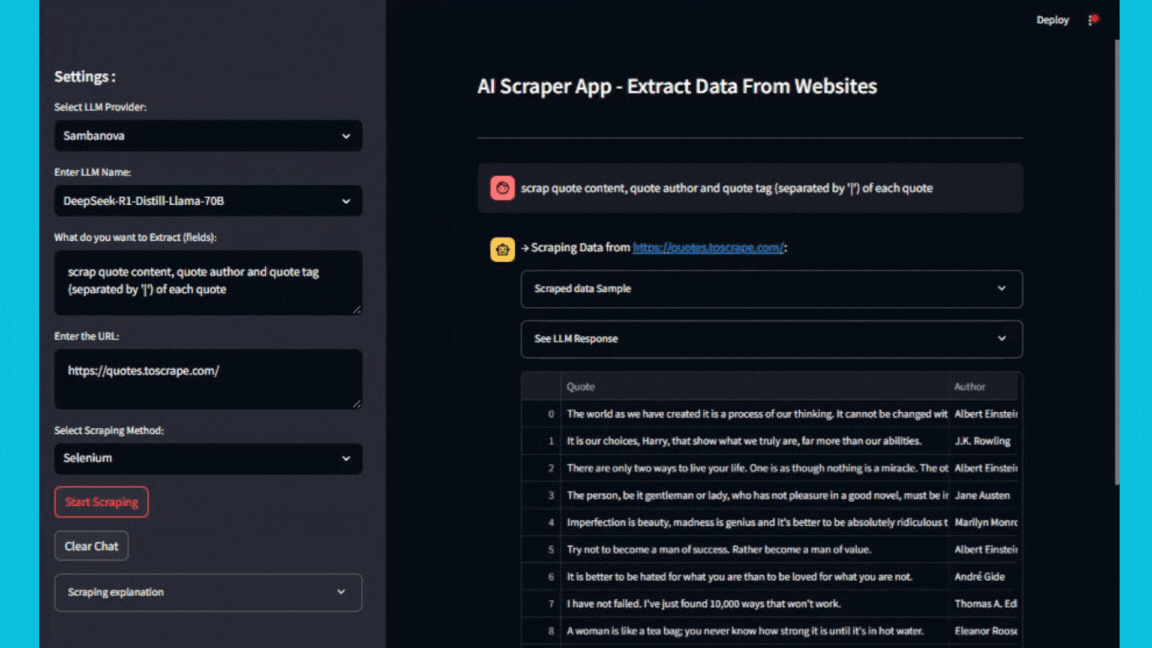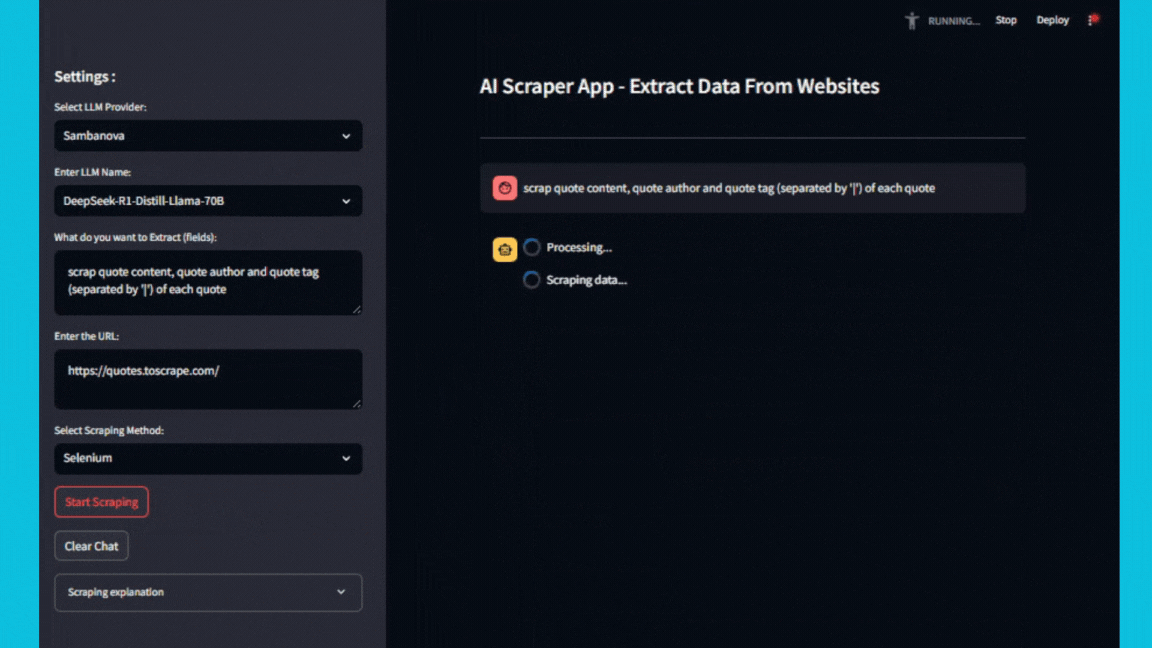
AI Scraper : scrap and extract data from website in any format (CSV, JSON, HTML...) using Selenium or Crawl4ai, and using Ollama or Sambanova API, and using Streamlit for UI as chatbot
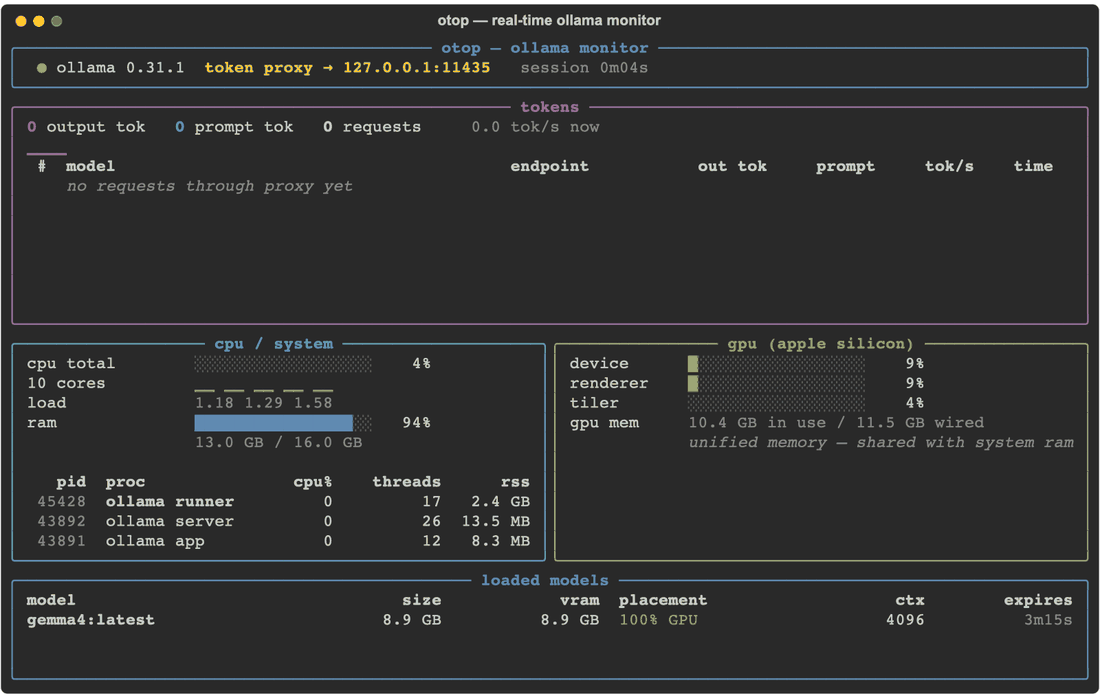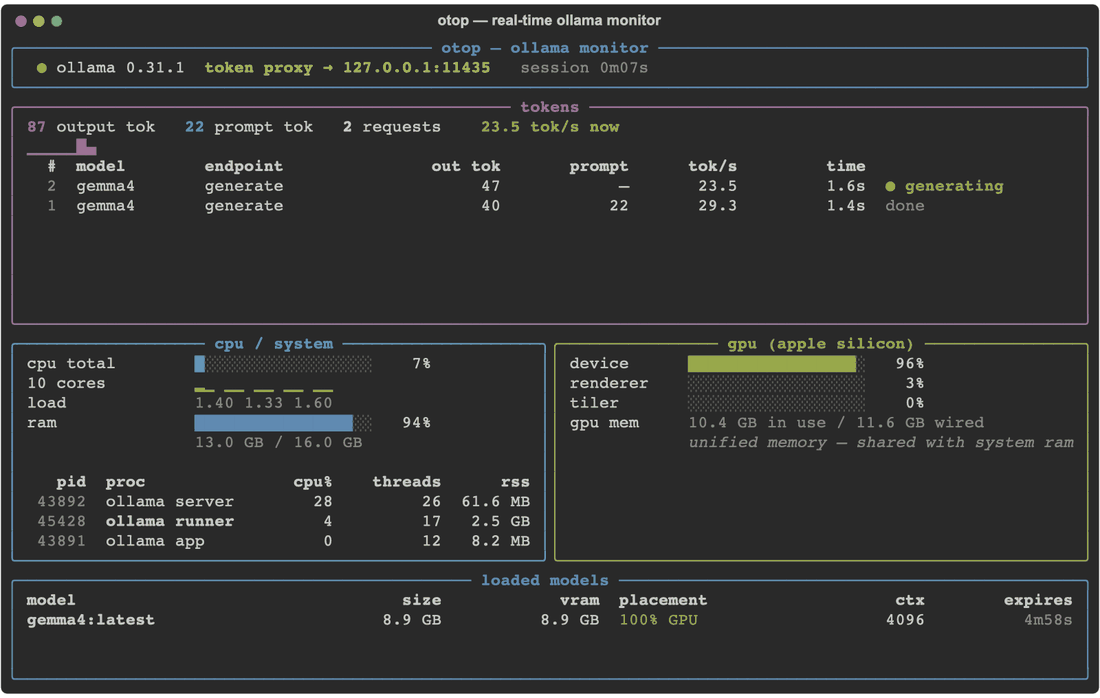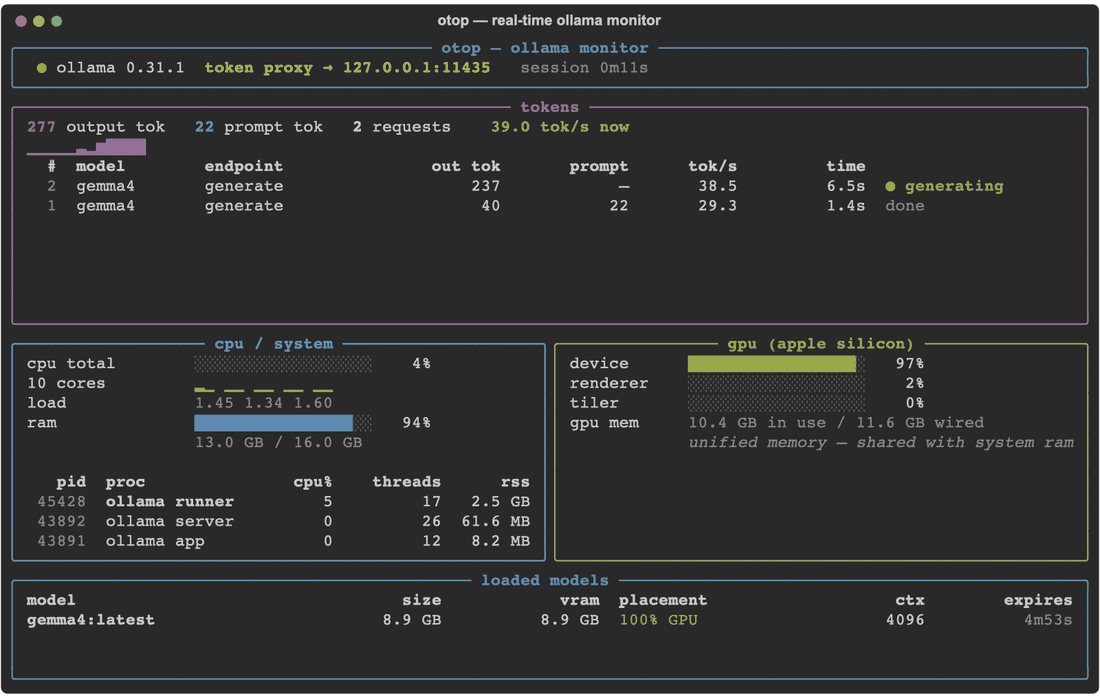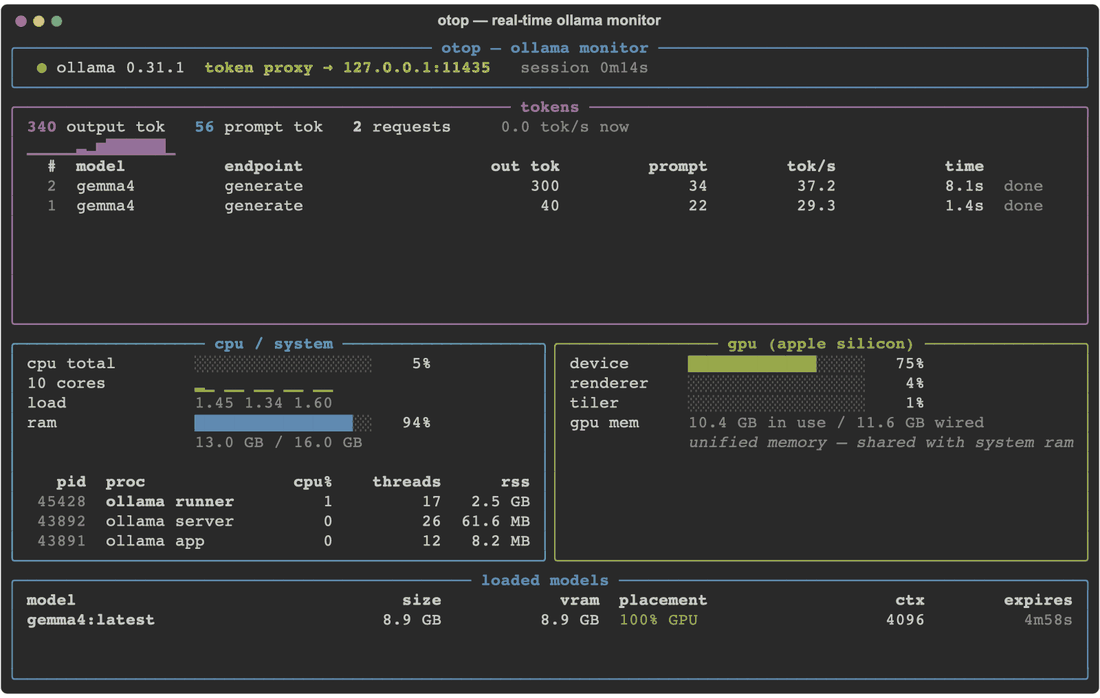
Real-time terminal dashboard for Ollama — live output token counting (tokens/sec), CPU & thread usage, Apple Silicon GPU utilization, VRAM and loaded models. htop for your local LLM.
A Bash Library for Ollama. Run LLM prompts straight from your shell, and more
Lightweight OpenAI/OLLaMA/GenAI compatible caller, originally designed for DeepInfra.
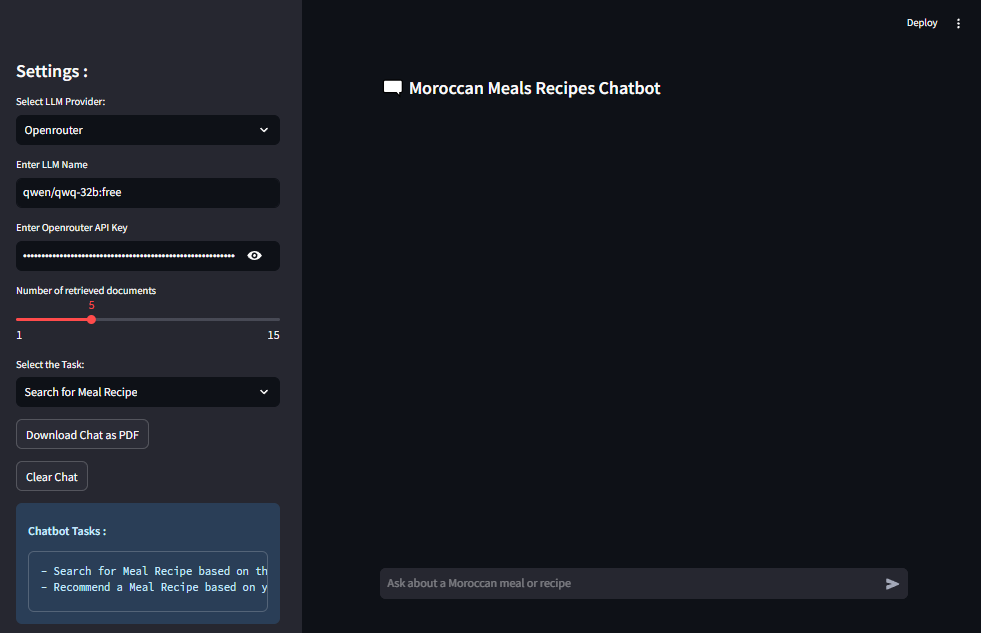
Moroccan Meal Recipes Chatbot Using Rag technique, with Ollama, Openrouter API, Faiss DB and Streamlit
Companion Toolkit for "Local AI Engineering with Ollama"
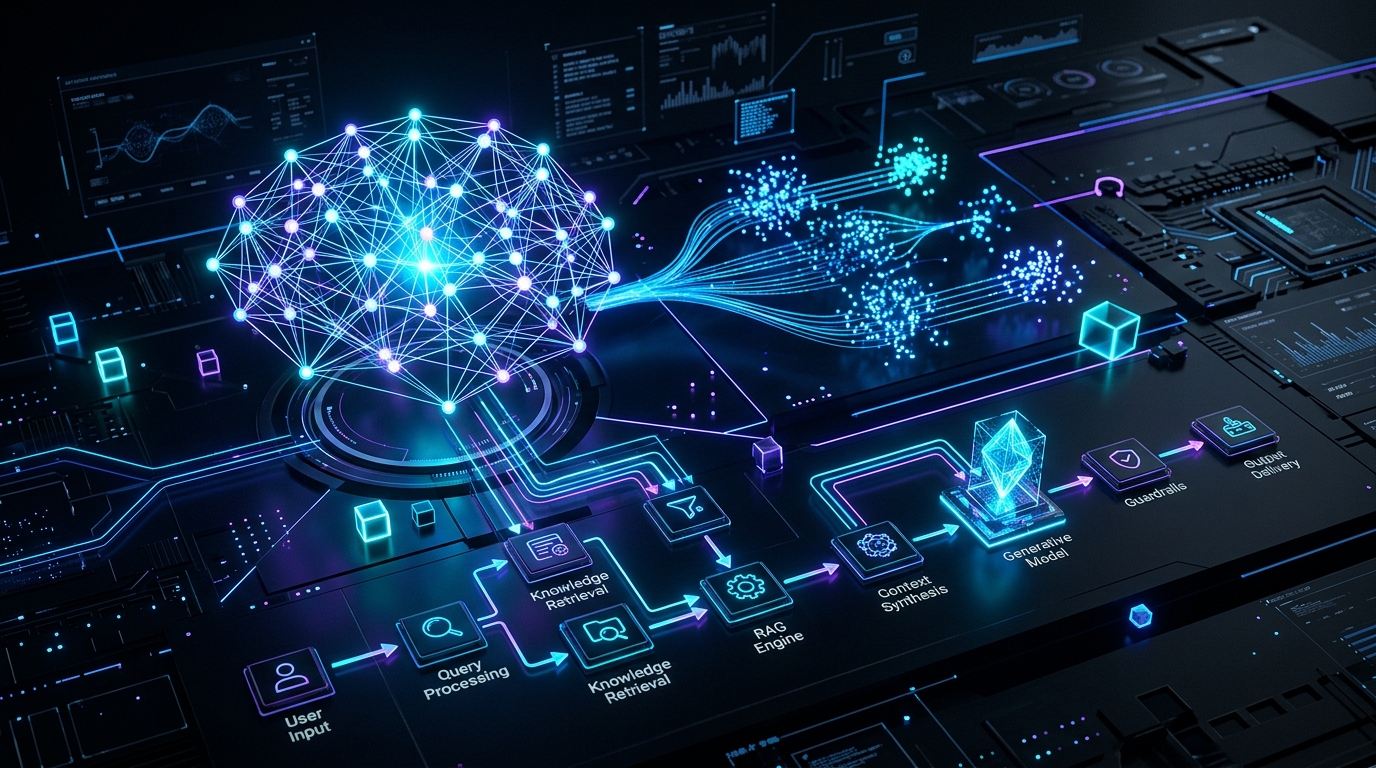
Advanced RAG: Build & Deploy Production GenAI Apps bridges the gap between proof-of-concept prototypes and enterprise-ready, scalable AI solutions. This repository provides end-to-end architectures, hybrid retrieval algorithms, multi-agent conversational patterns