foundry-local
- 2.7k
- C++
- 5 d ago
TinyML & Edge AI: On-device inference, model quantization, embedded ML, ultra-low-power AI for microcontrollers and IoT devices.
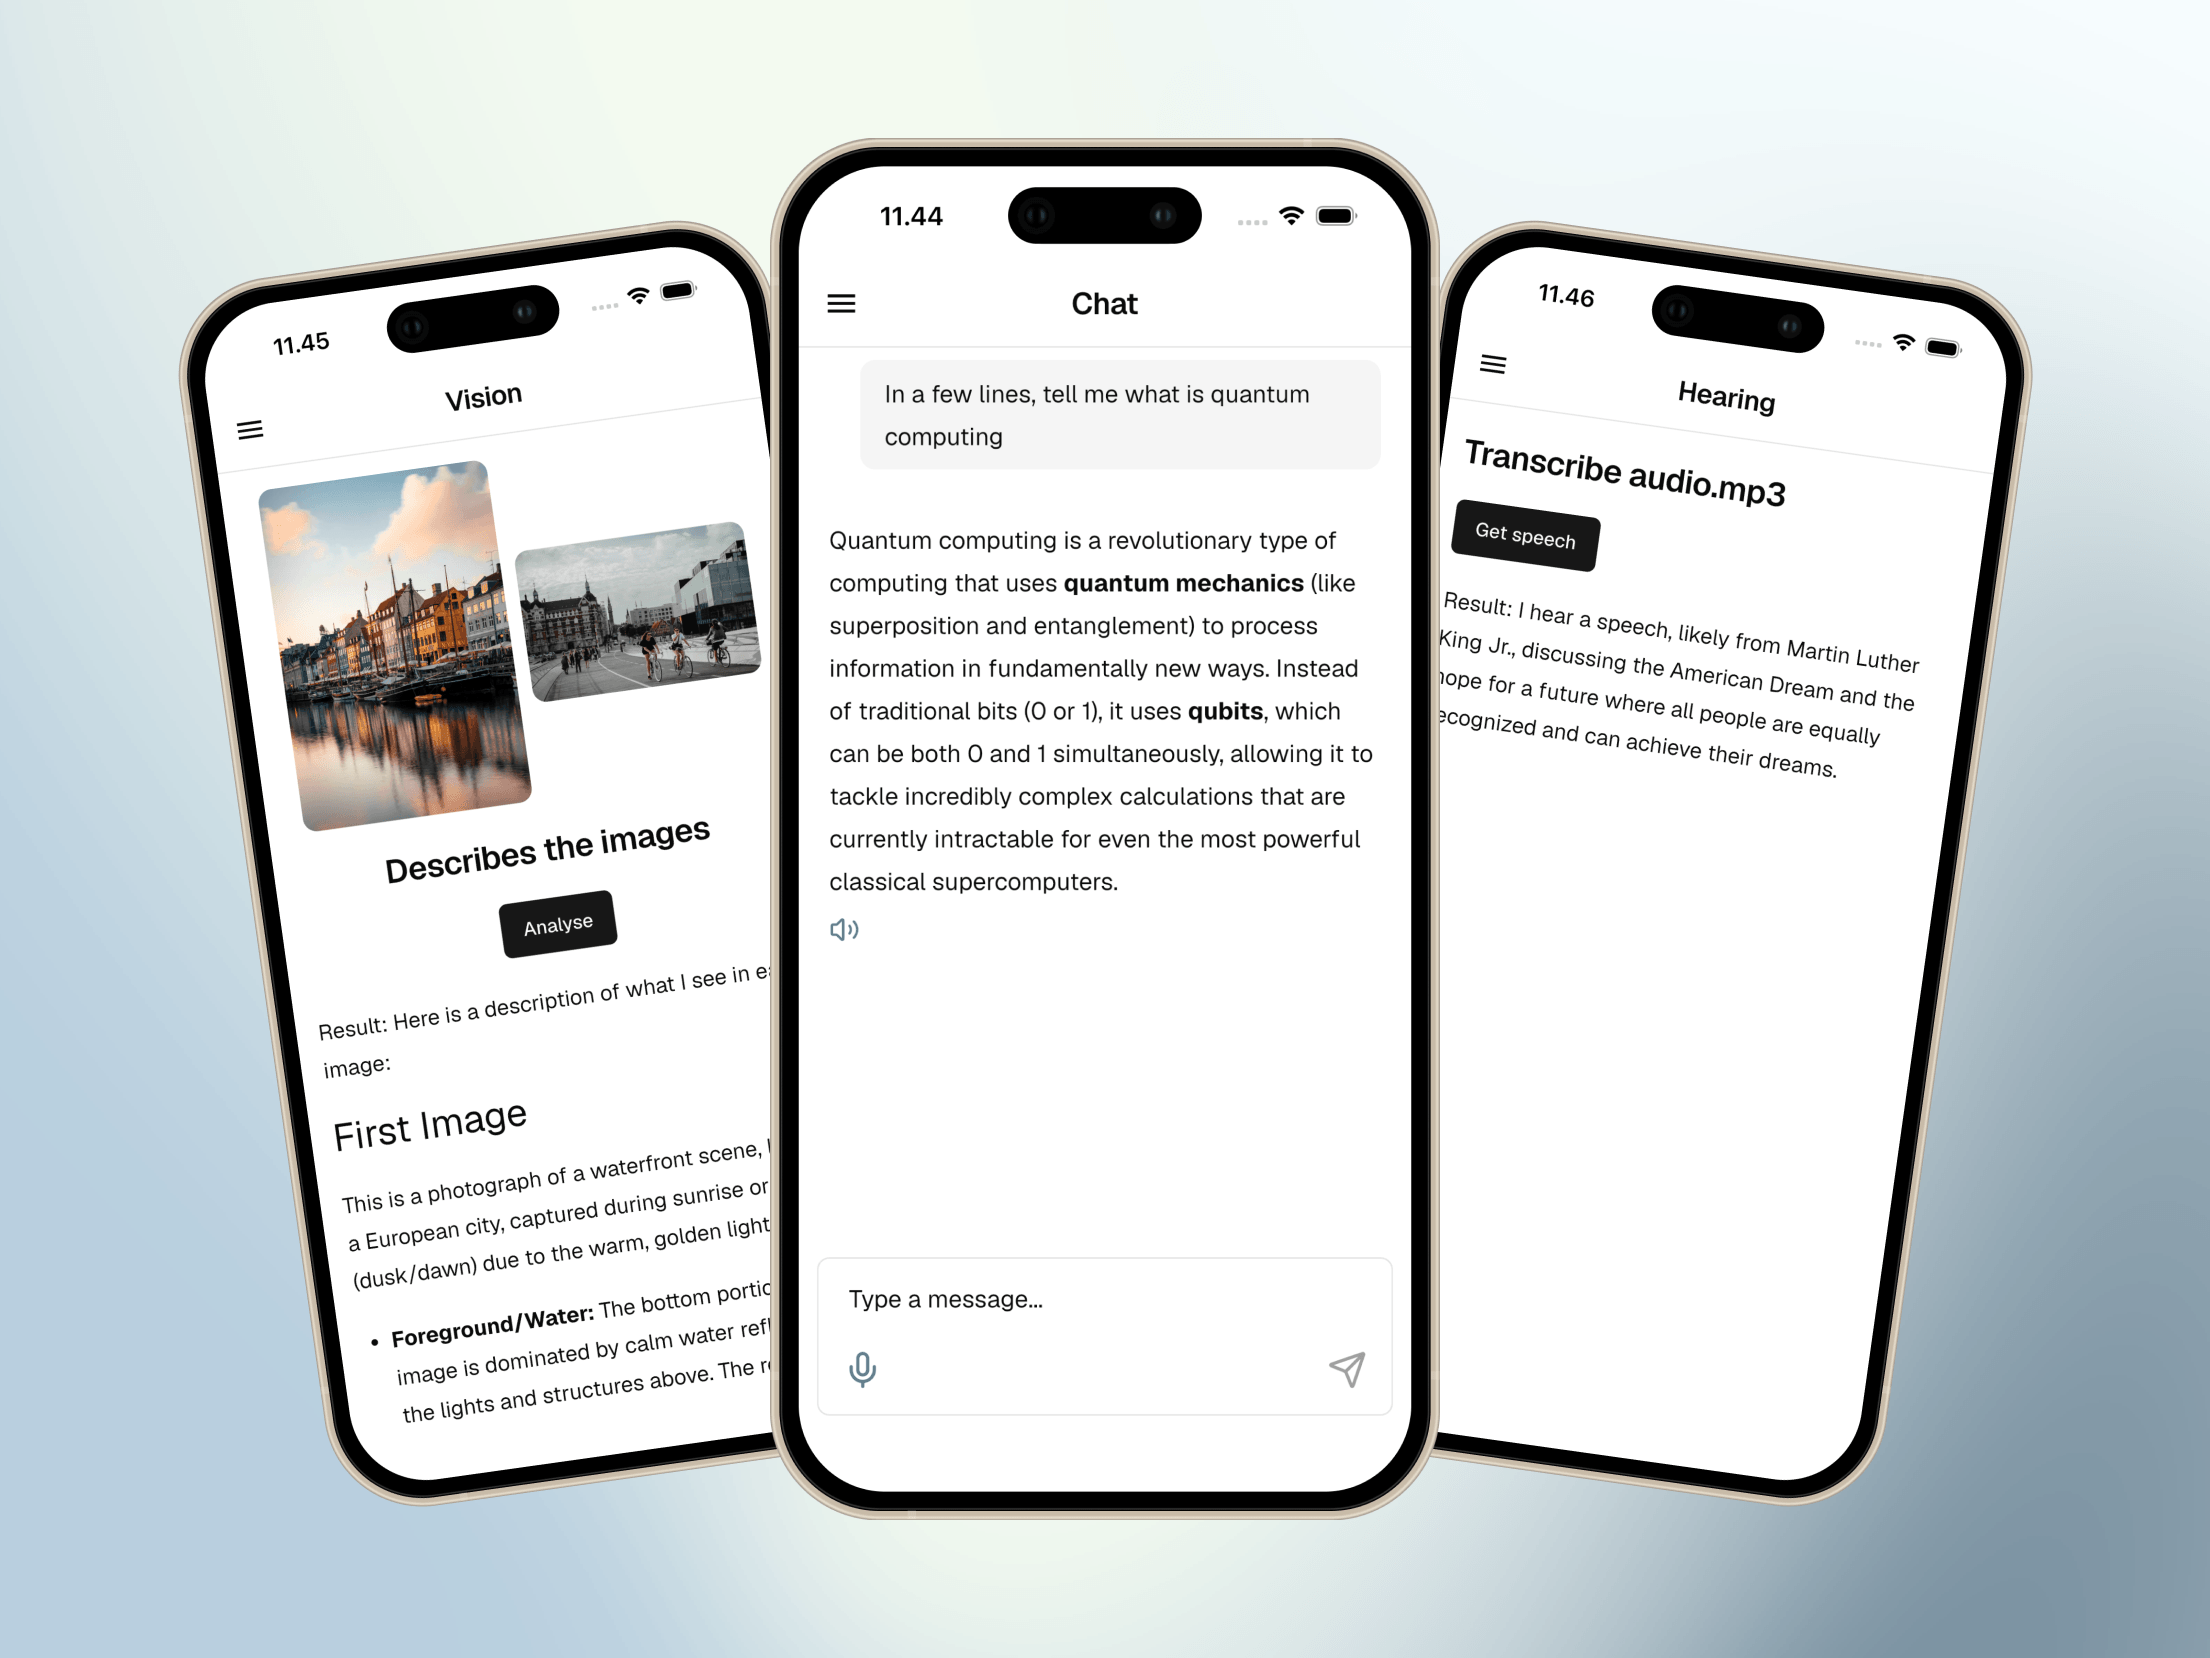
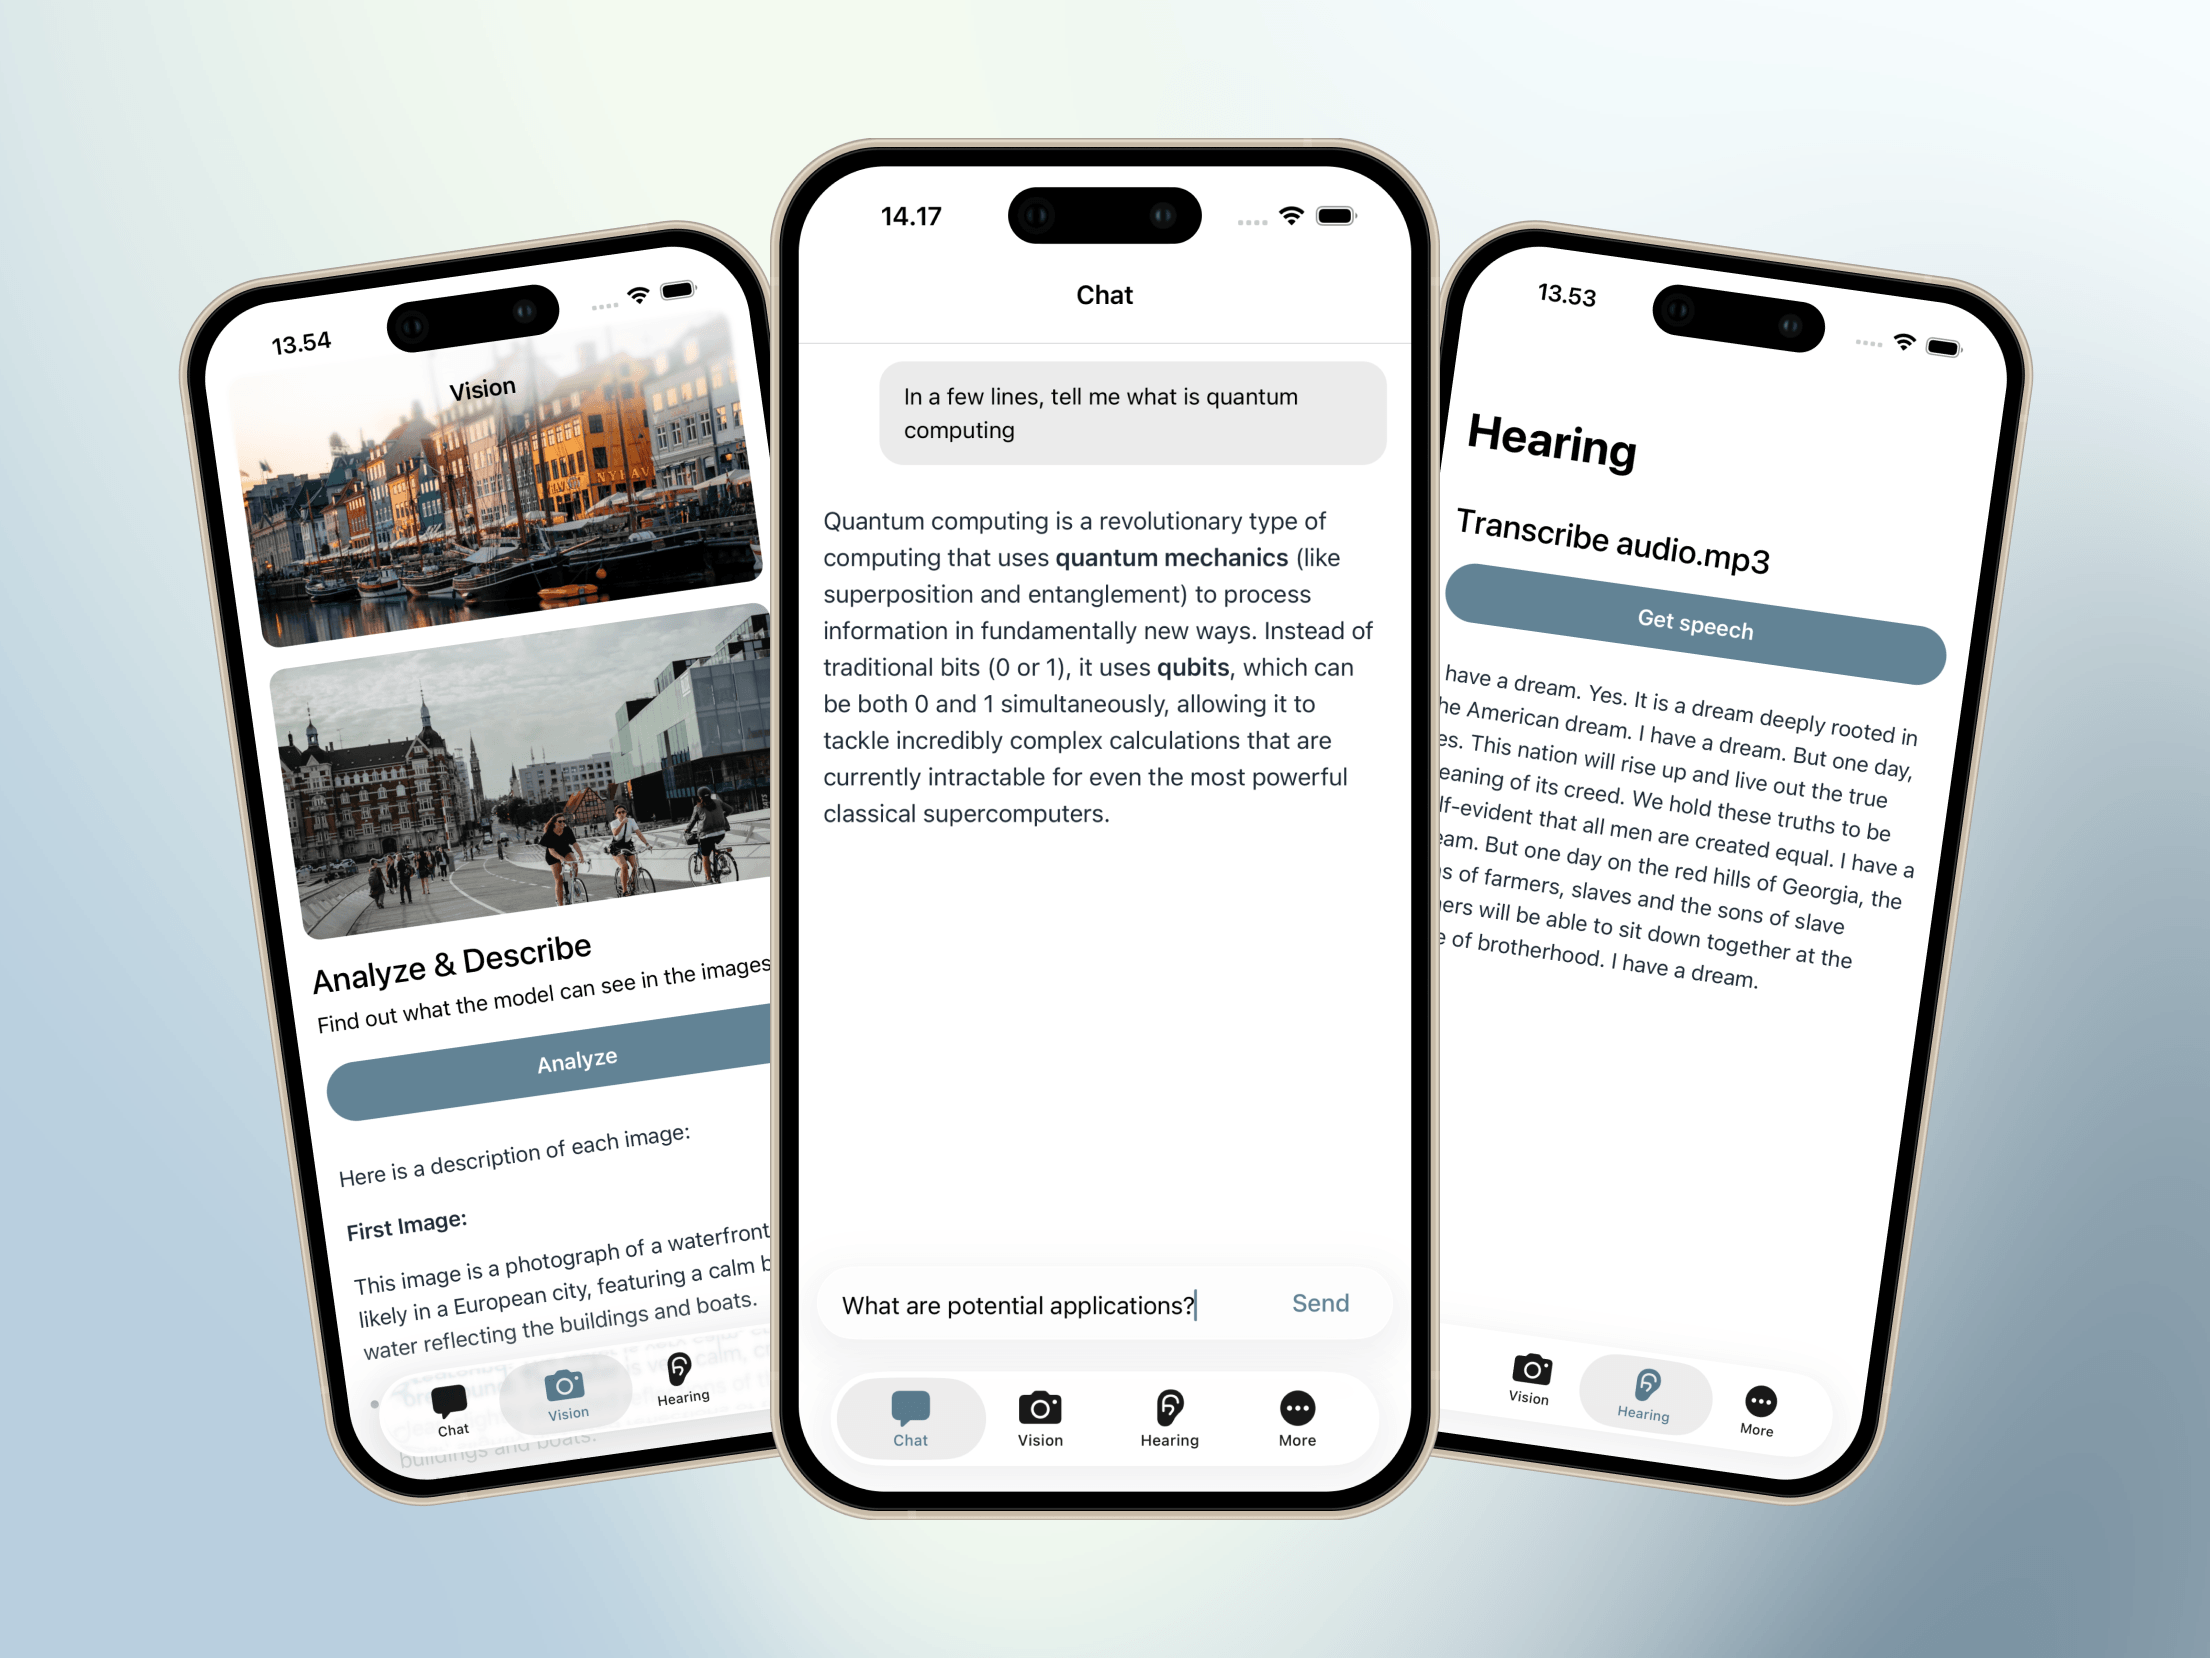
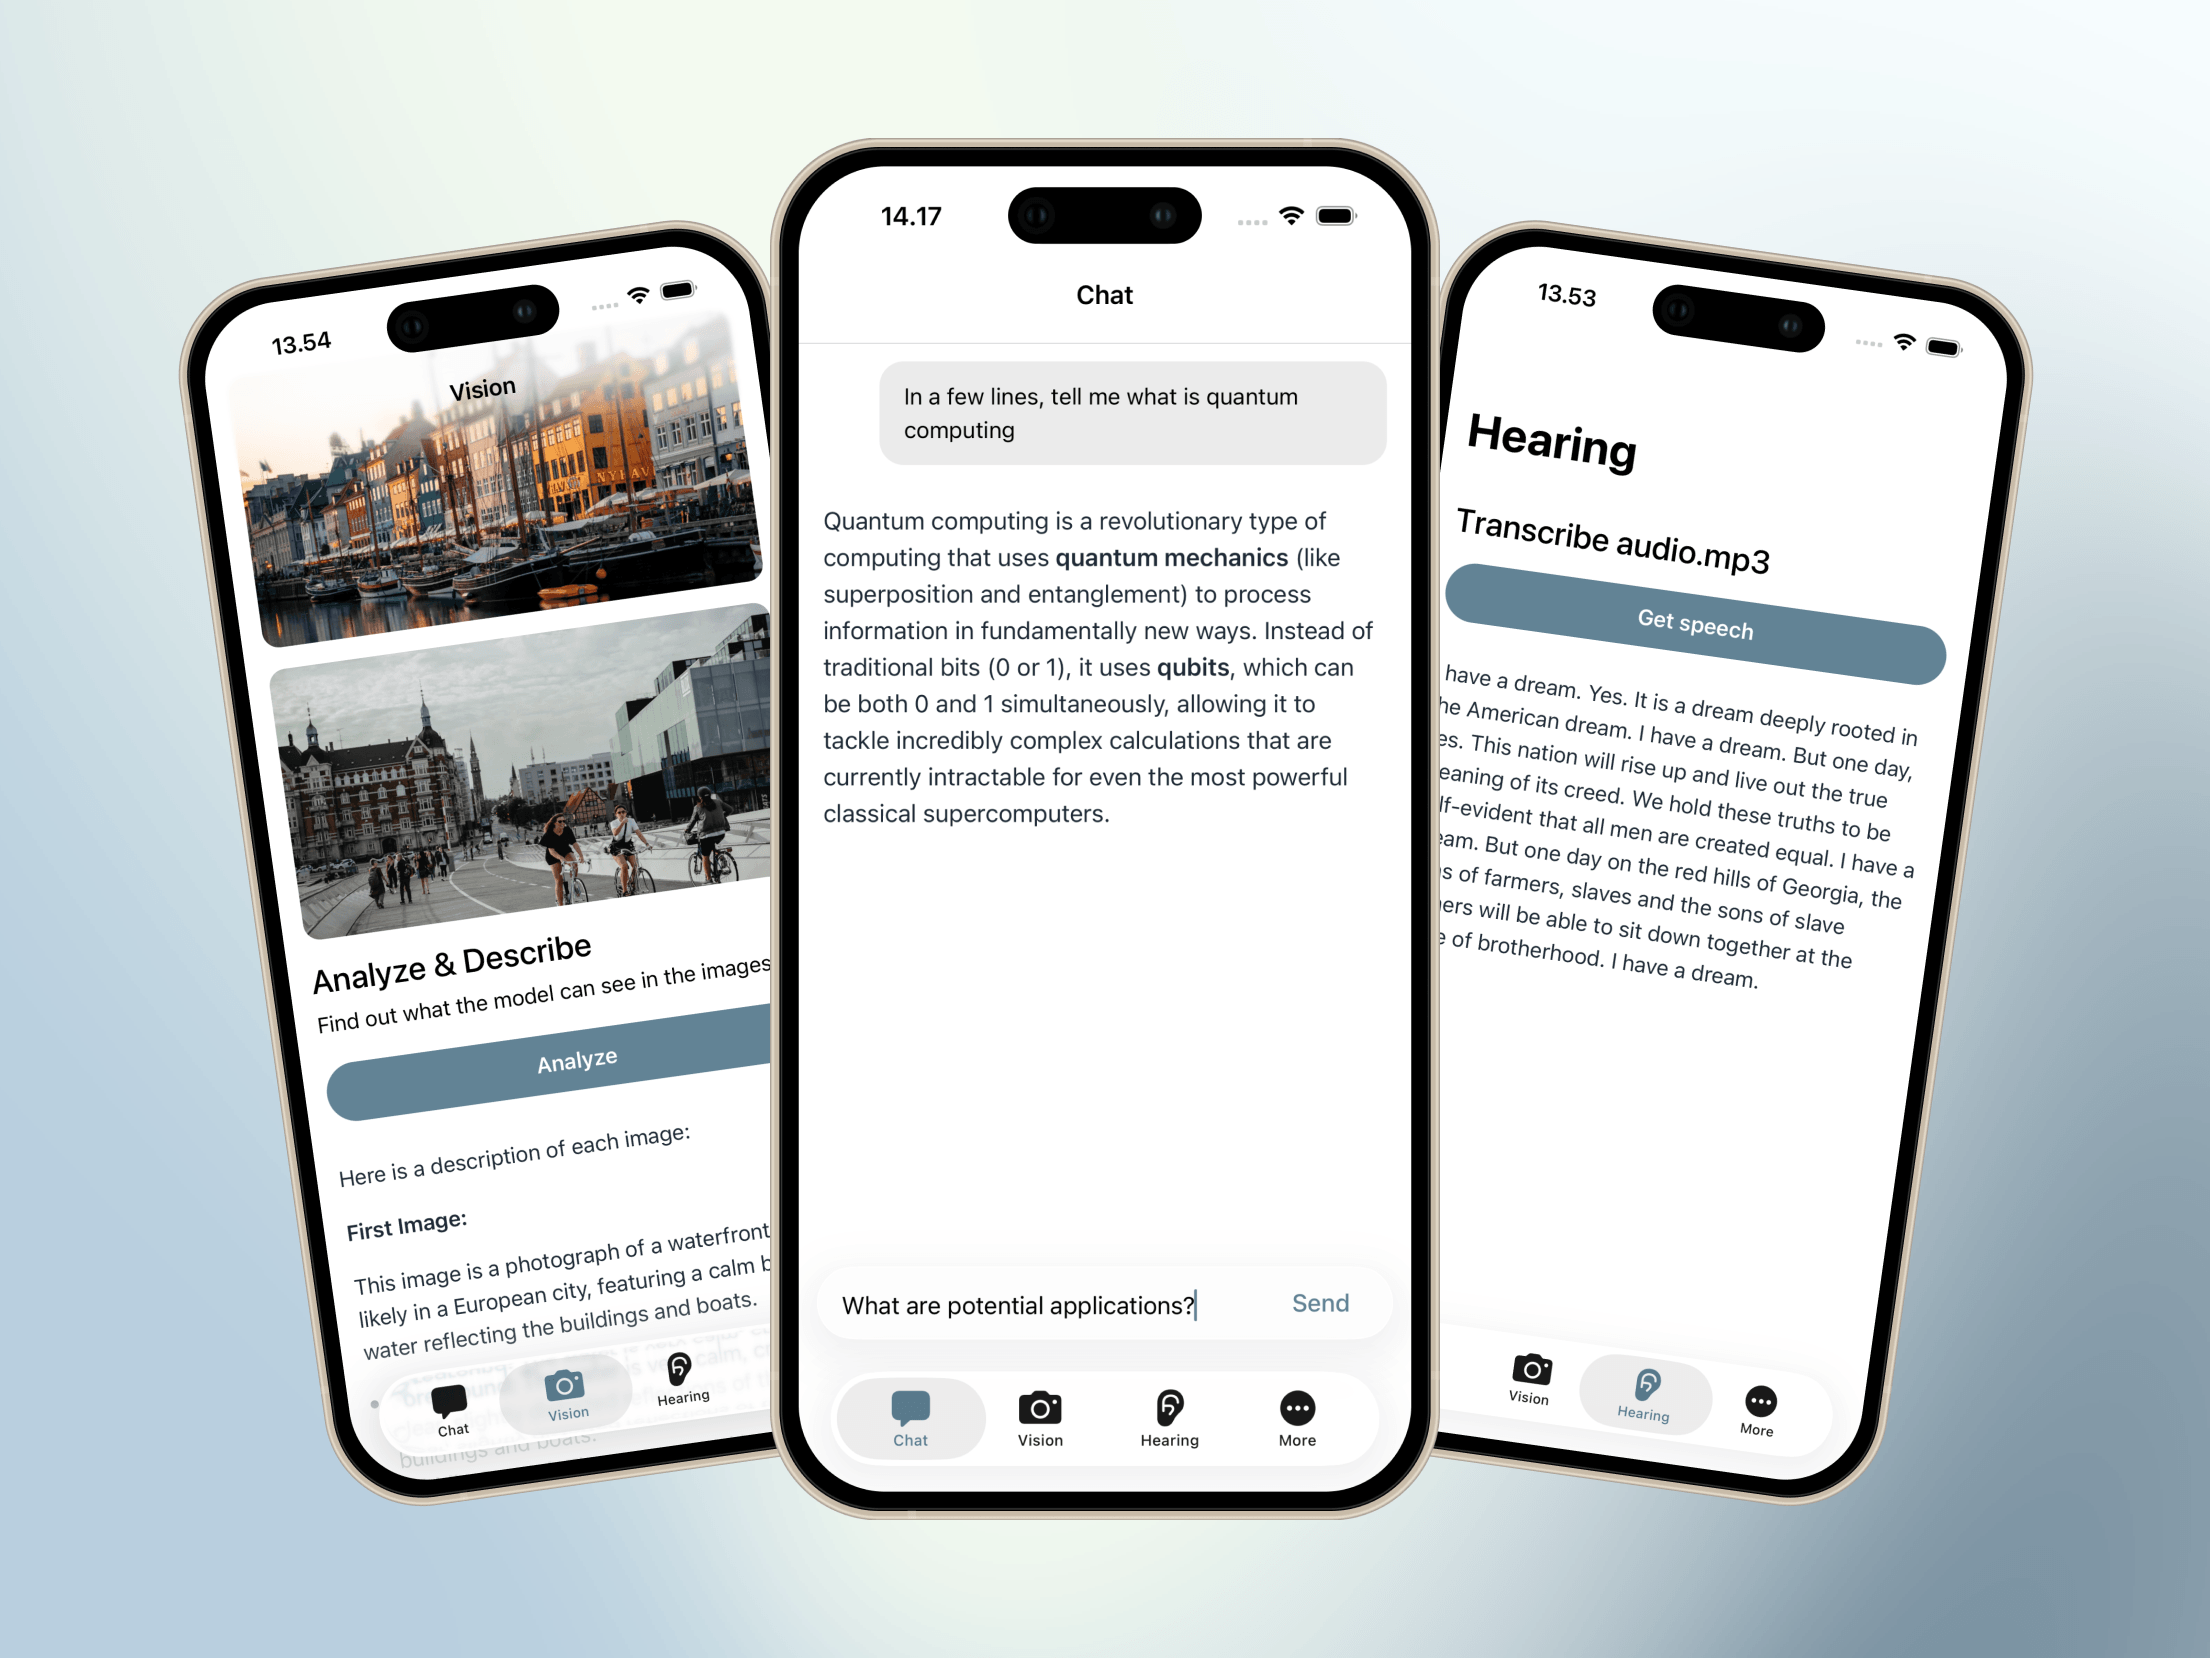
Flutter starter example app to get started with NobodyWho, a library designed to run LLMs locally and efficiently on any device.
⚡️ The fastest way to run local LLMs on Apple Silicon — sub-second model loads, beats Ollama on throughput, tail latency, and full-response time. OpenAI/Ollama-compatible. No cloud, no API keys.
React Native starter example app to get started with NobodyWho, a library designed to run LLMs locally and efficiently on any device.
Mobile AI: iOS CoreML, Android TFLite, on-device inference, ONNX, TensorRT, and ML deployment for smartphones.
Custom llama.cpp fork with character intelligence engine: control vectors, attention bias, head rescaling, attention temperature, fast weight memory
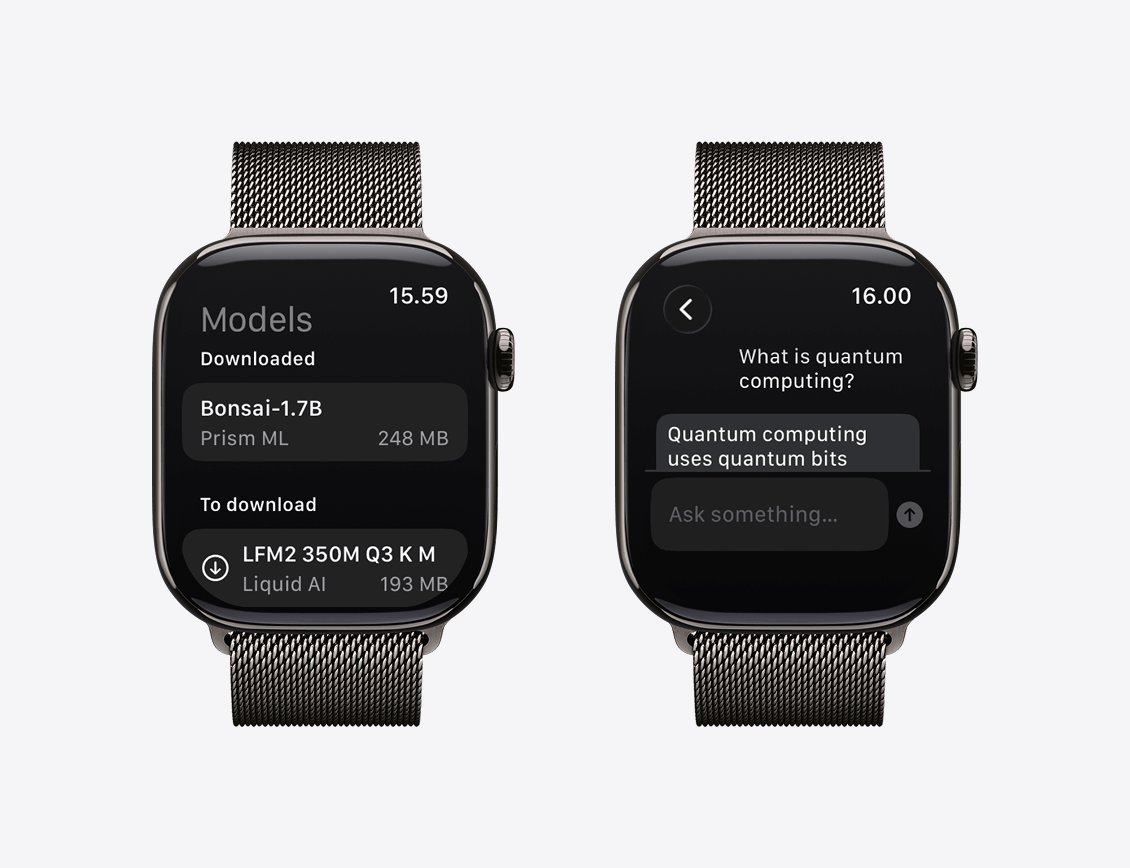
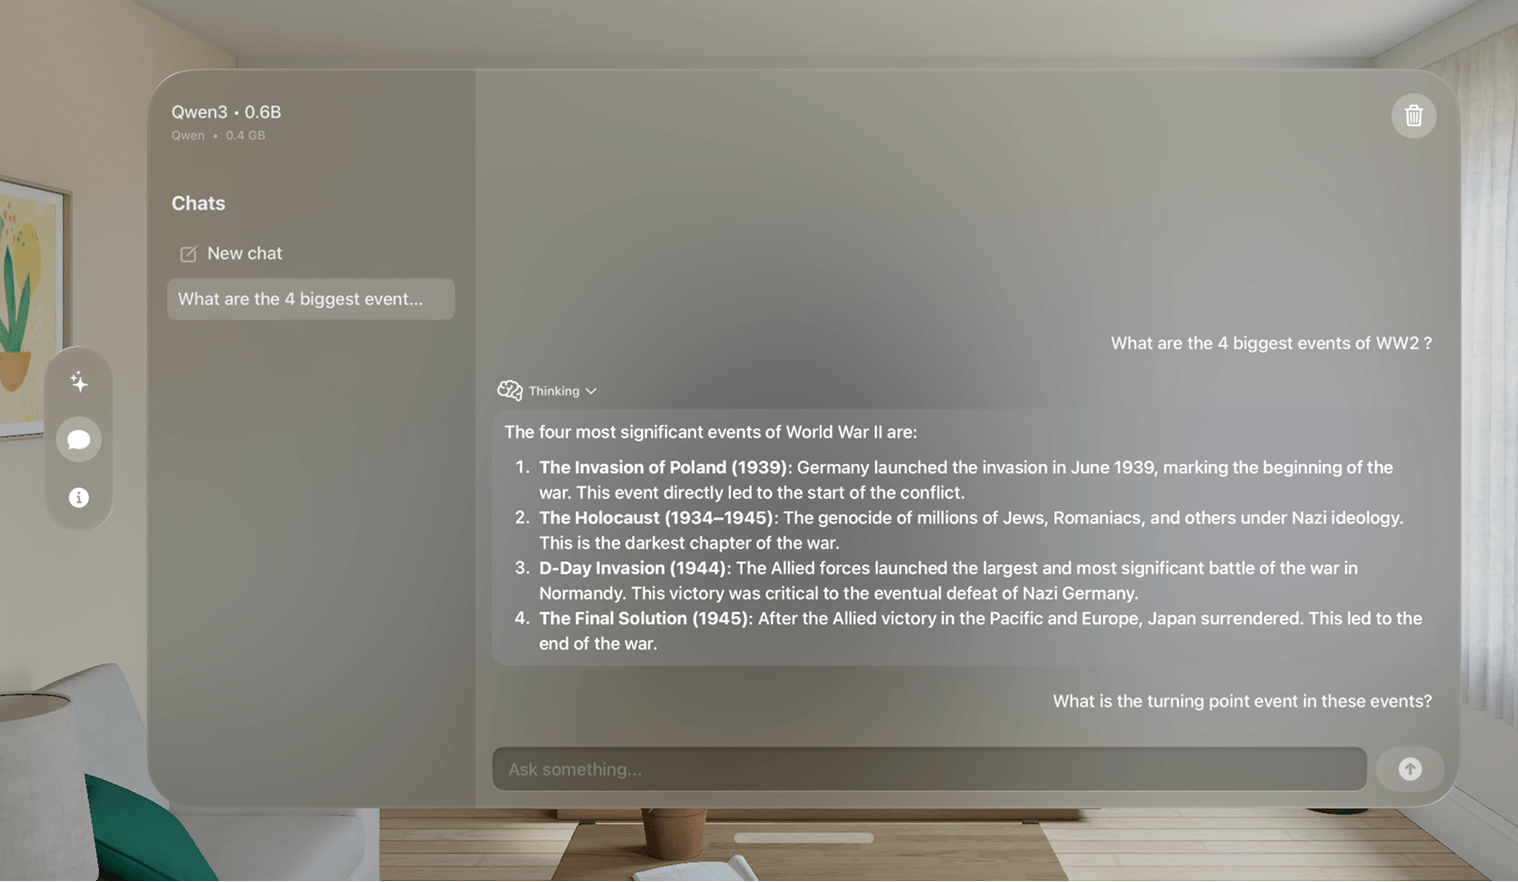
On-device AI inference for Swift apps. Run LLMs locally on iOS, macOS, visionOS and watchOS.
Production Android AI with ExecuTorch 1.0 - Deploy PyTorch models to mobile with NPU acceleration and 50KB footprint
Real-time SAM2 segmentation on edge devices - 40x faster C++ inference with ONNX Runtime for iOS/Android deployment
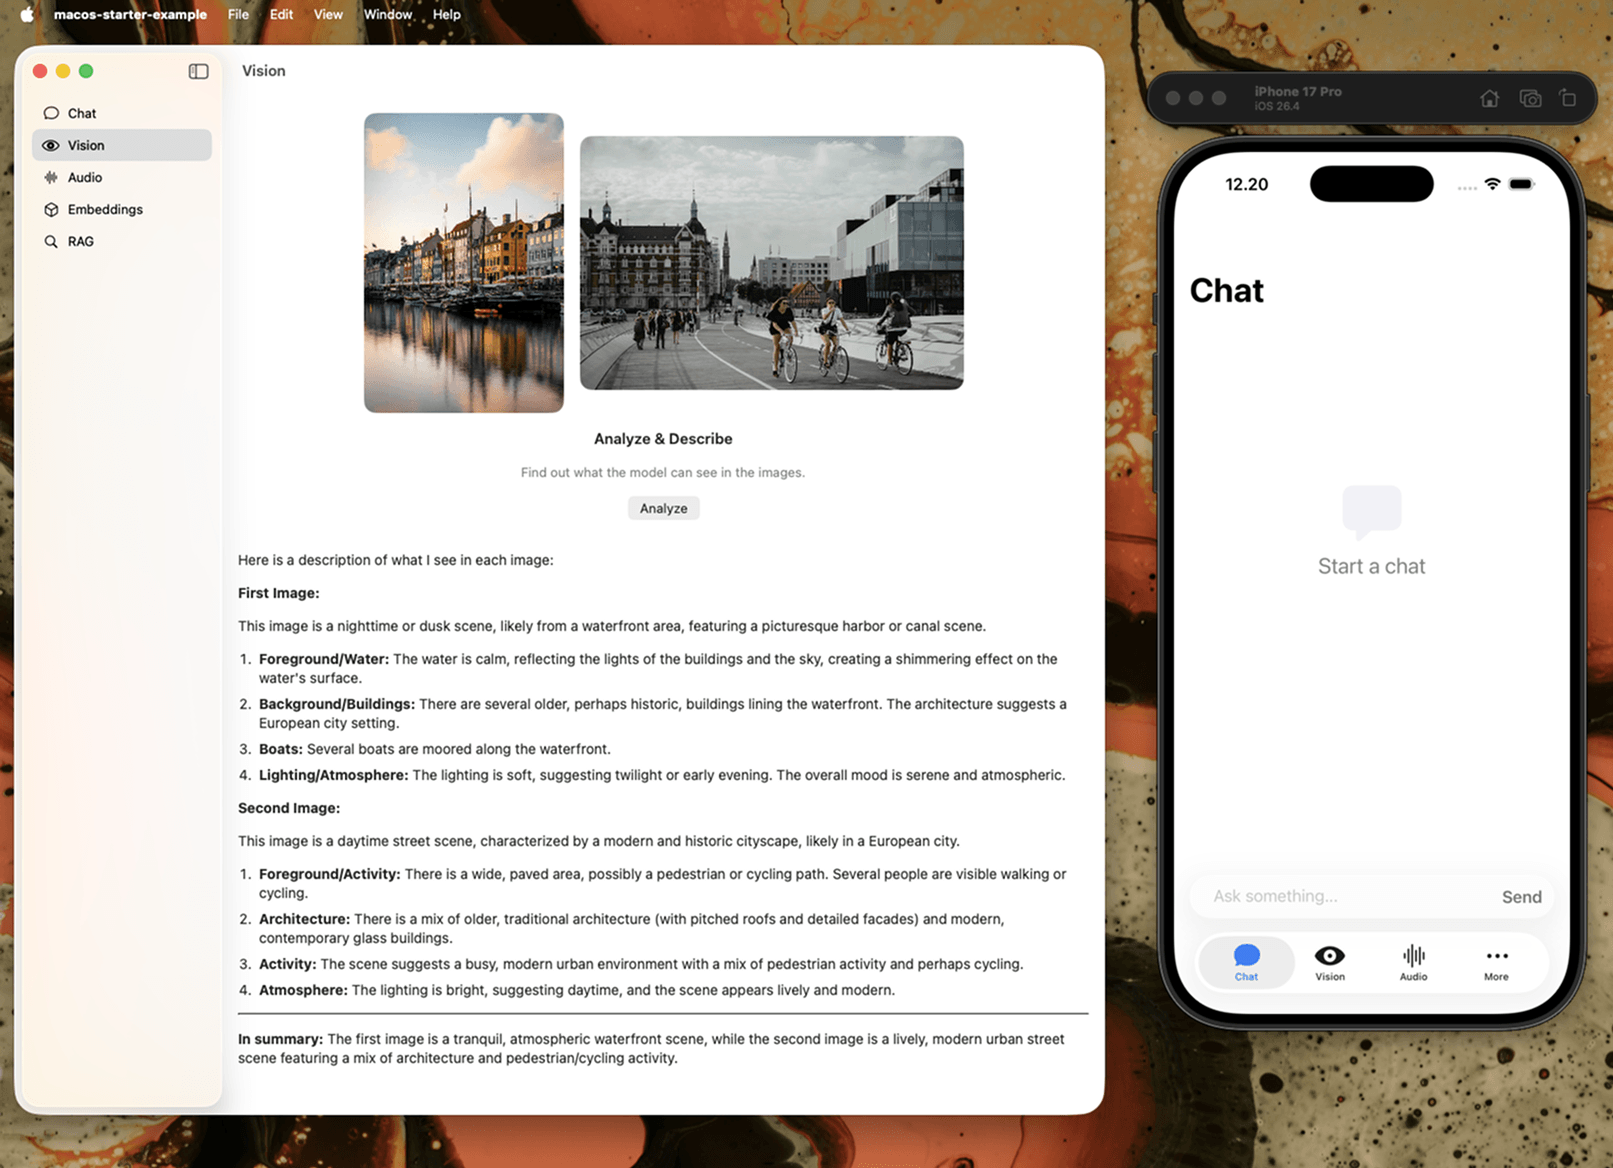
iOS & macOS starter example apps to get started with NobodyWho, a library designed to run LLMs locally and efficiently on any device.
Expo starter example app to get started with NobodyWho, a library designed to run LLMs locally and efficiently on any device.
Electron starter example app to get started with NobodyWho, a library designed to run LLMs locally and efficiently on any device.