cost-xray
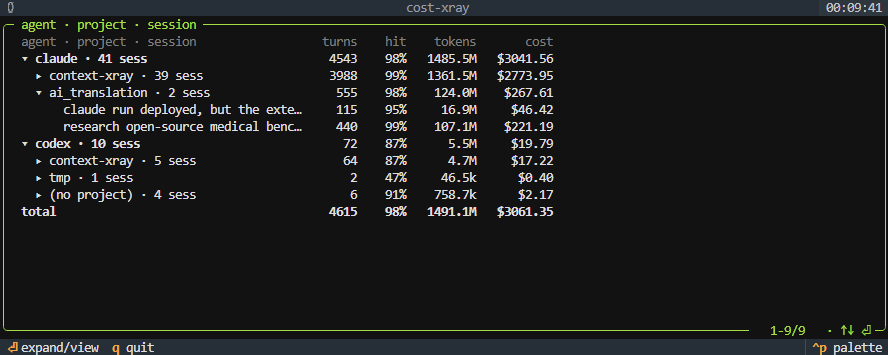
See what Claude Code and Codex actually send to the API — and what each part costs.
- 5.8k
- Python
- MIT
- 11 d ago
See what Claude Code and Codex actually send to the API — and what each part costs.
Keep long, image-heavy Codex and Claude Code chats fast: earlier images become ID placeholders the model fetches back on demand, even after compaction. Local, cache-friendly, MIT.
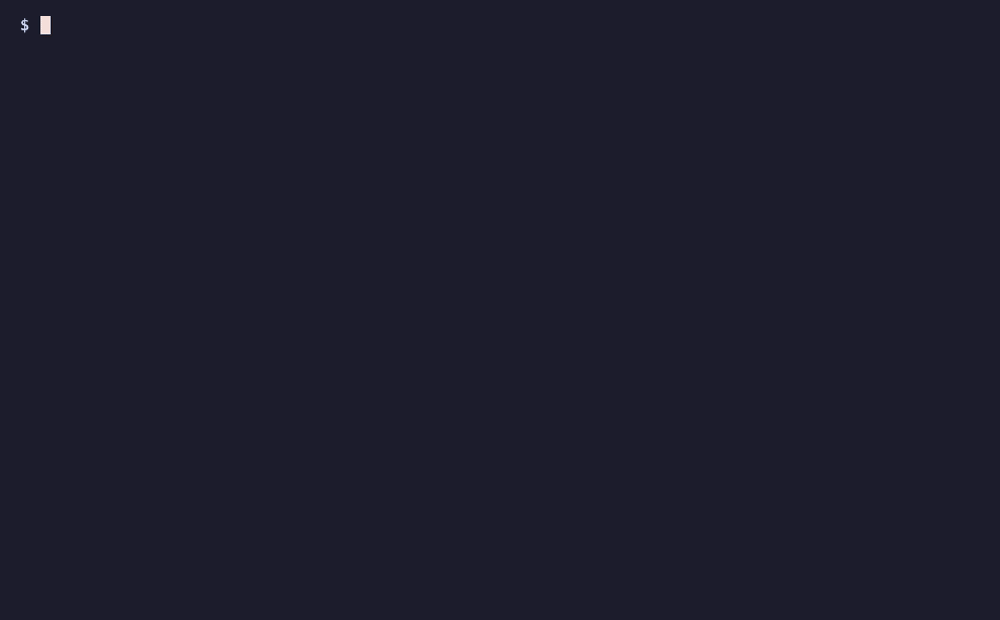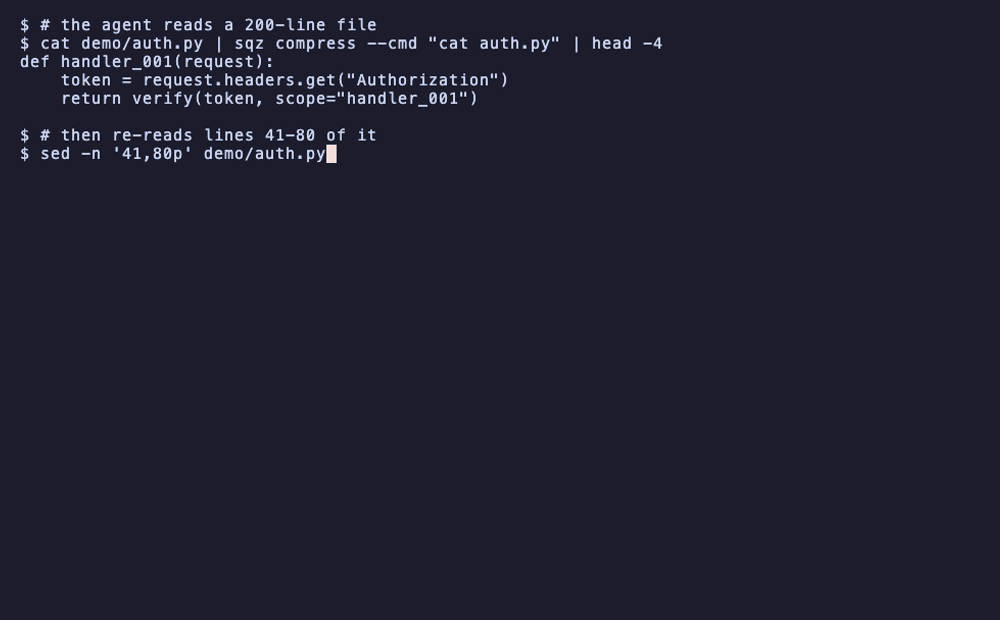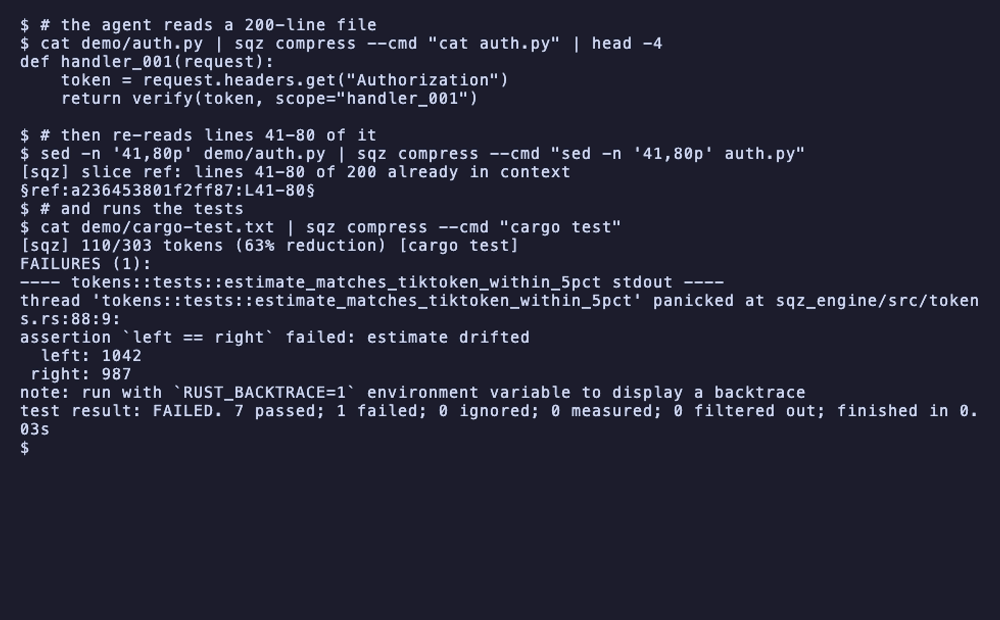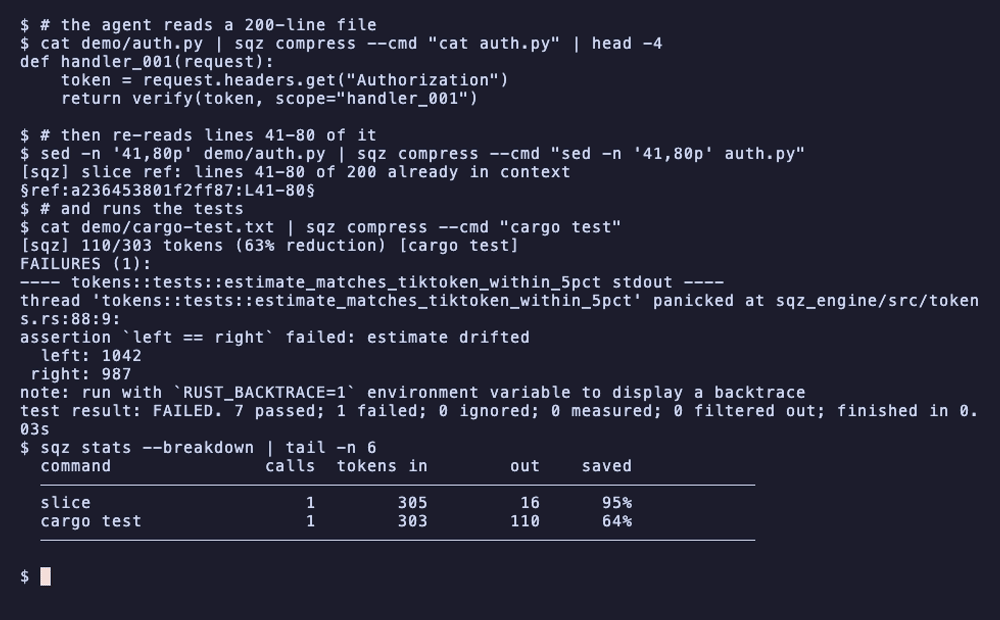
Context compression for AI coding agents: compresses tool output before it enters the model, dedups repeats to 13-token refs. Claude Code, Cursor, Codex, Kiro, Zed, any MCP client. Rust, zero LLM calls.
91.5% fewer tokens on tool output on Headroom's own benchmark, where Headroom removes 61.4%. Separately, the same SWE-bench tasks resolved at 0.71x the cost of plain Claude Code. Plus memory across sessions and subscription quota pacing. Claude Code, Codex, Copilot, Gemini and 12 more. Local, MIT.
Streamline your workflow with Lynkr, a CLI tool that acts as an HTTP proxy for efficient code interactions using Claude Code CLI.
Companionship, chat, coding, and work share one memory and context framework — the kind of AI you see in science fiction: it keeps you company, and it gets things done with you.(这是一个基于上下文和注意力机制做的一个多元化的agent项目)
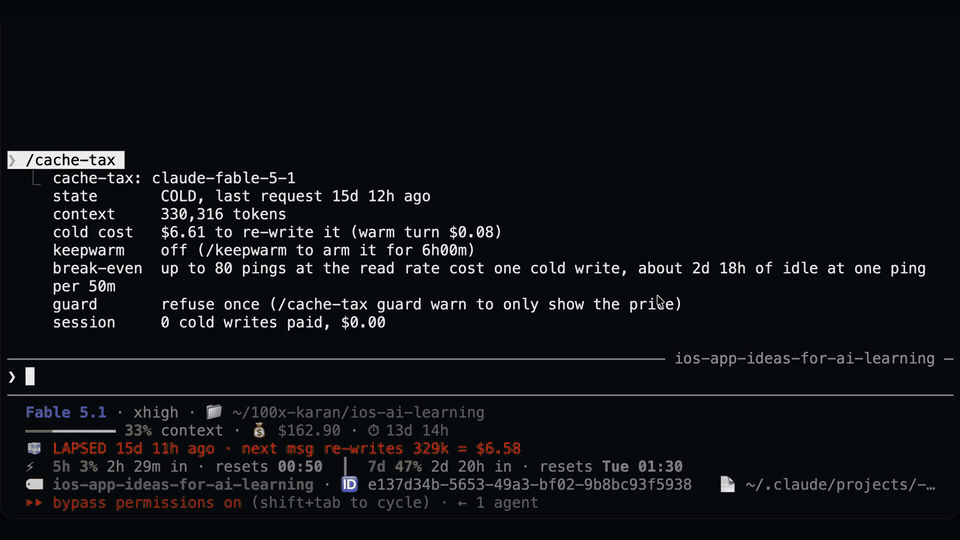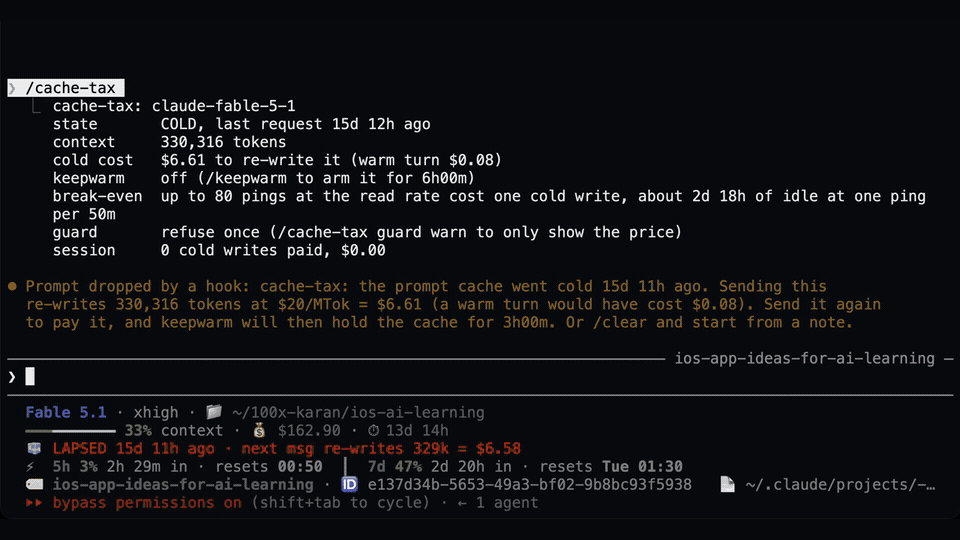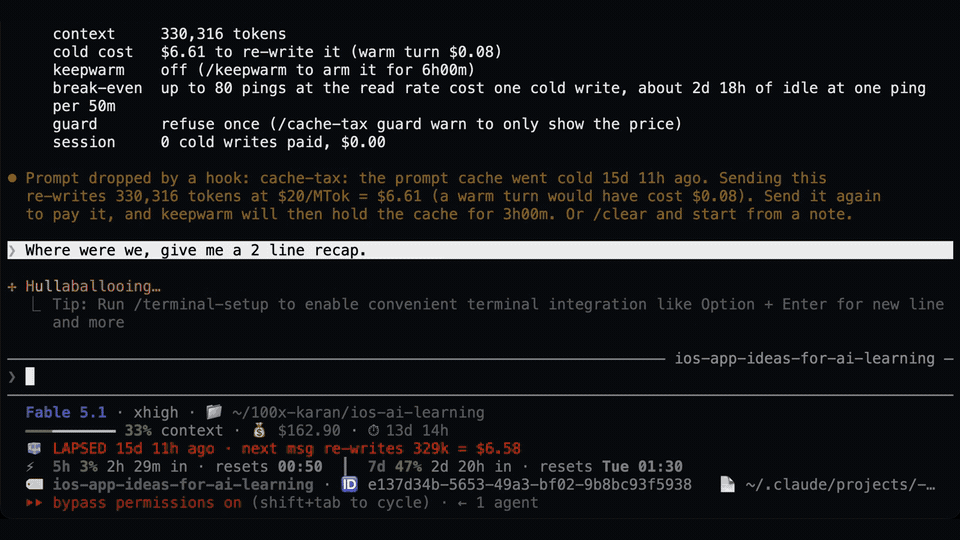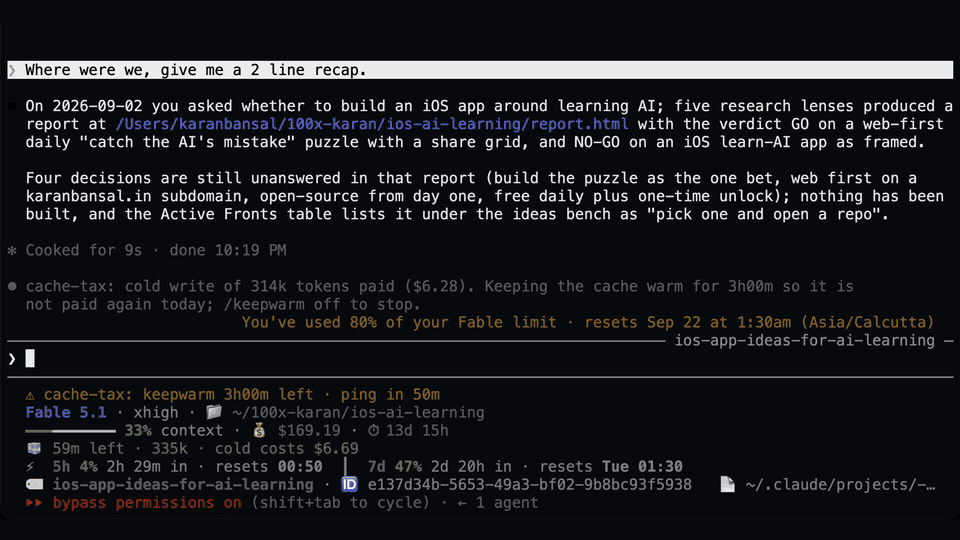
Keep Claude Code’s prompt cache warm during breaks and show the estimated cost before a cold send.
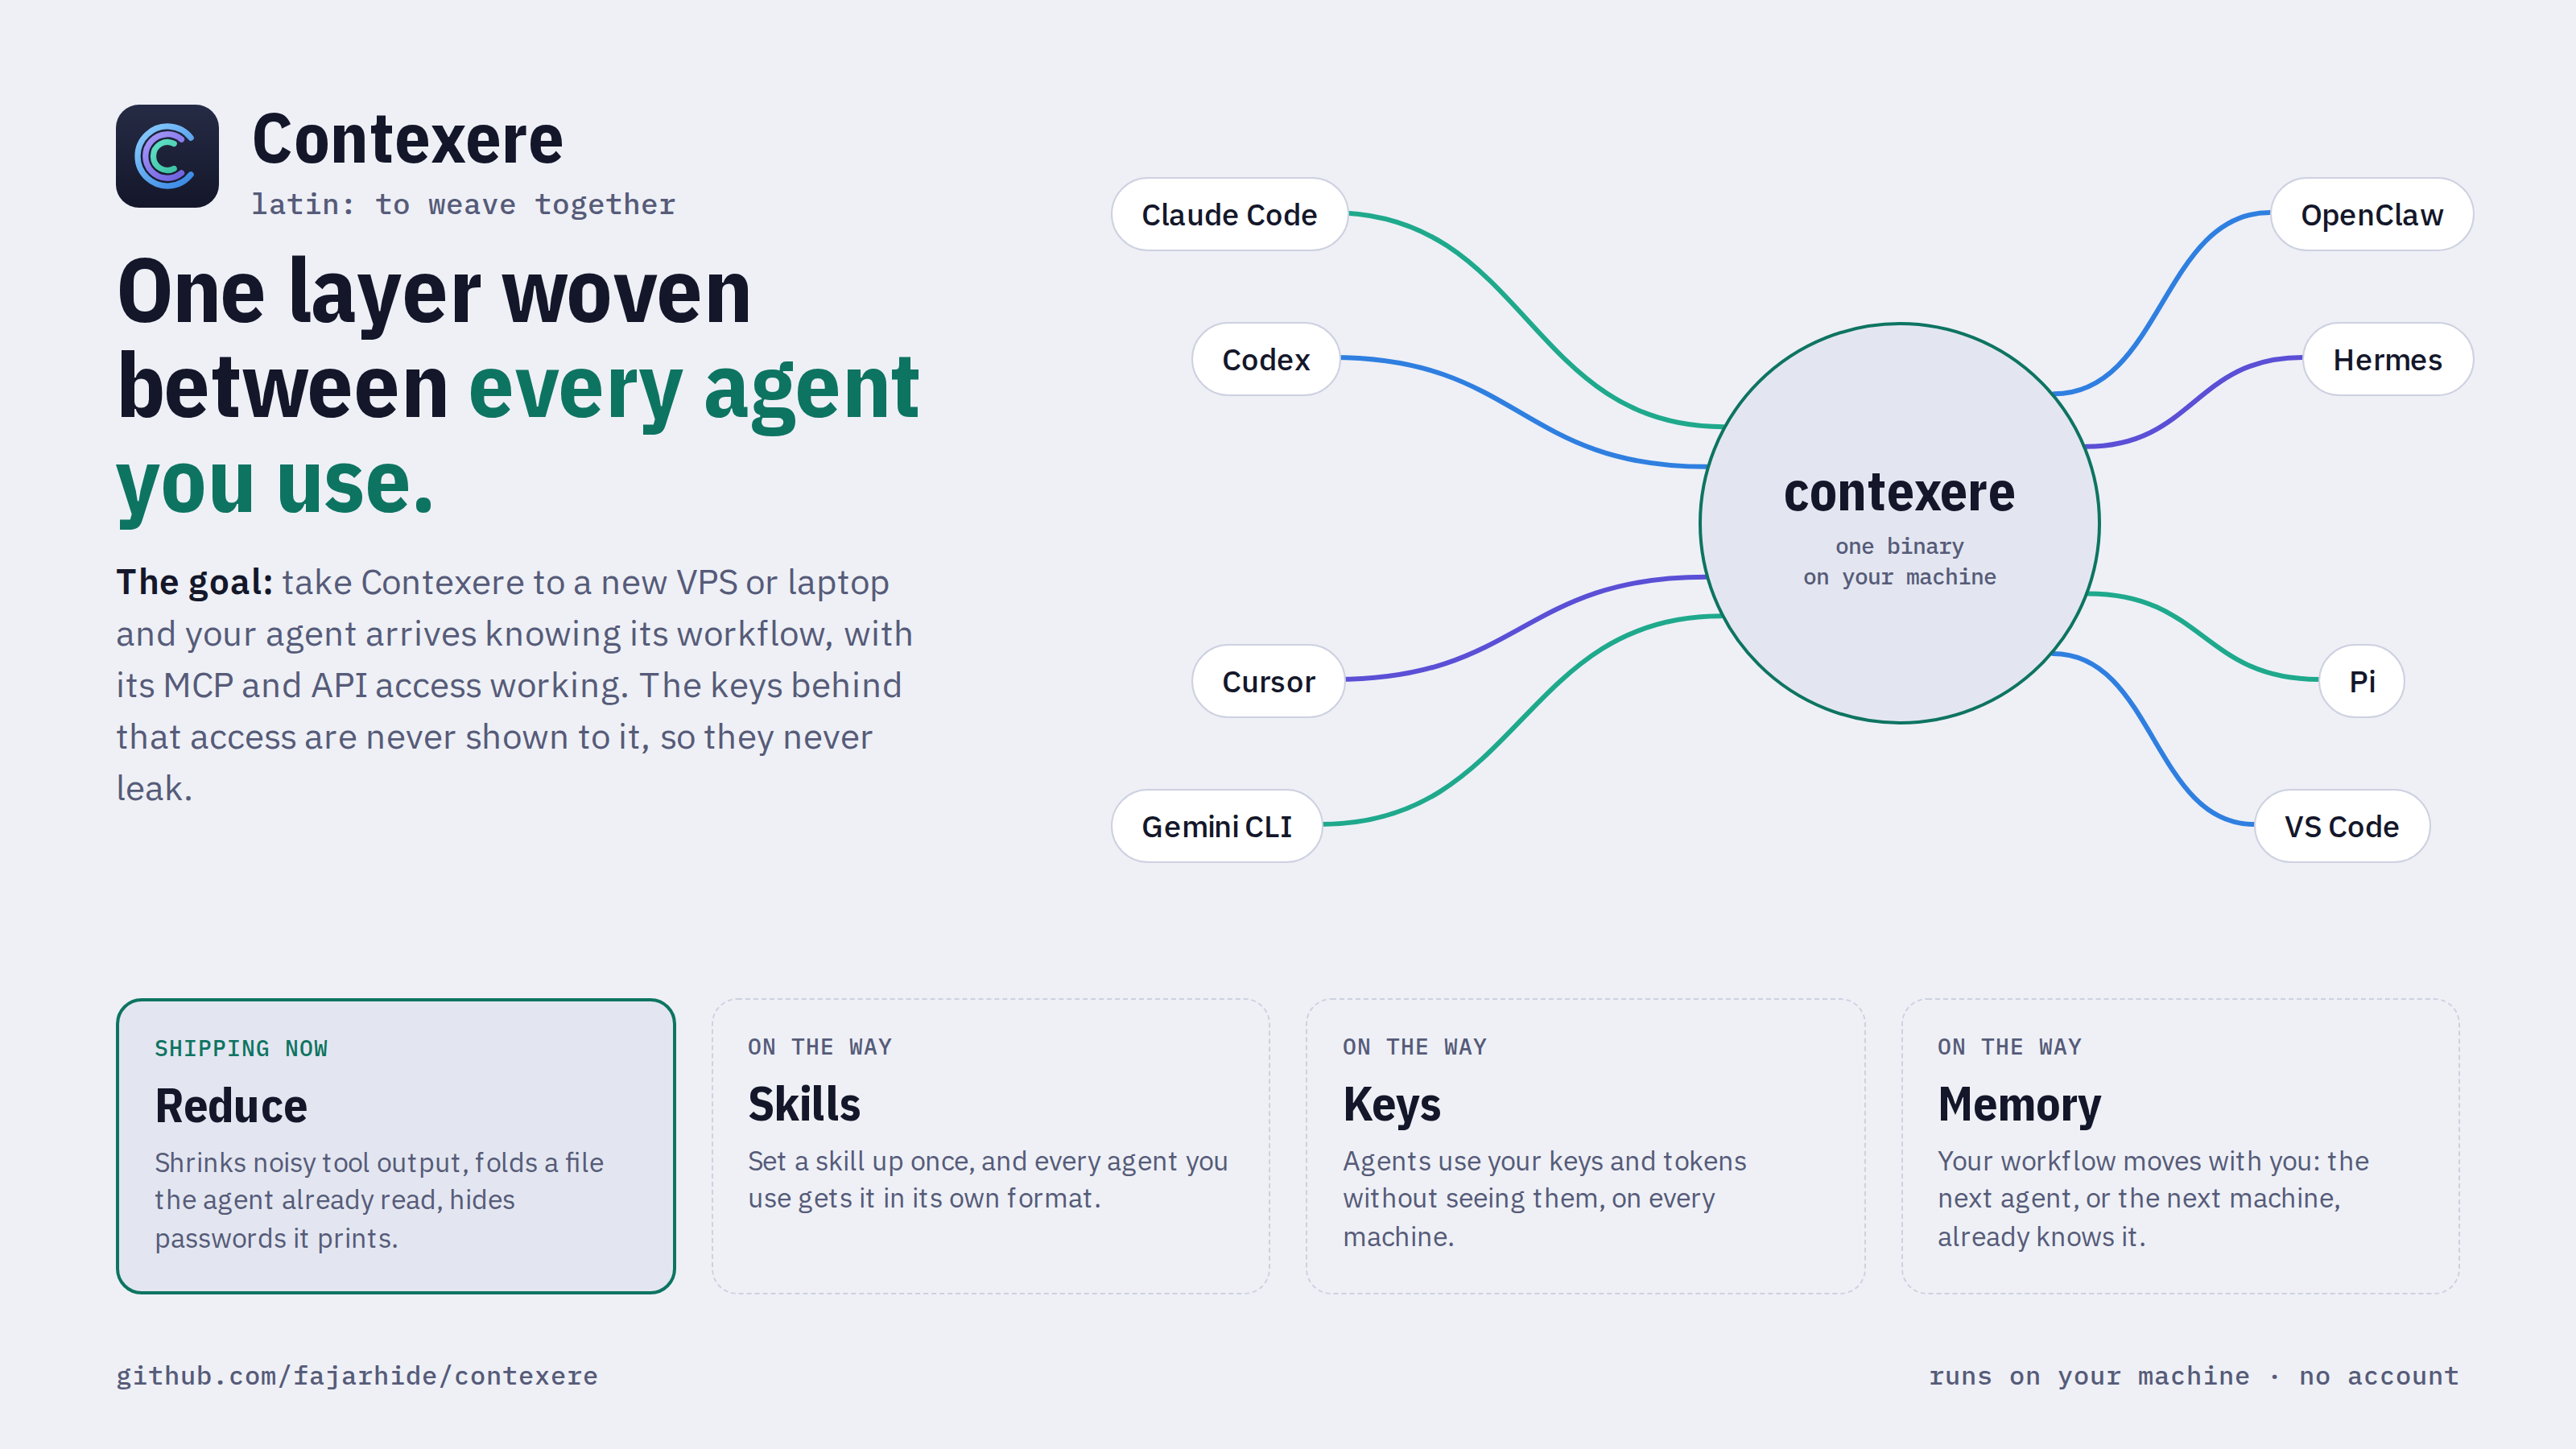
The one place for the skills, keys and memory of every agent you use. Formerly OMNI.
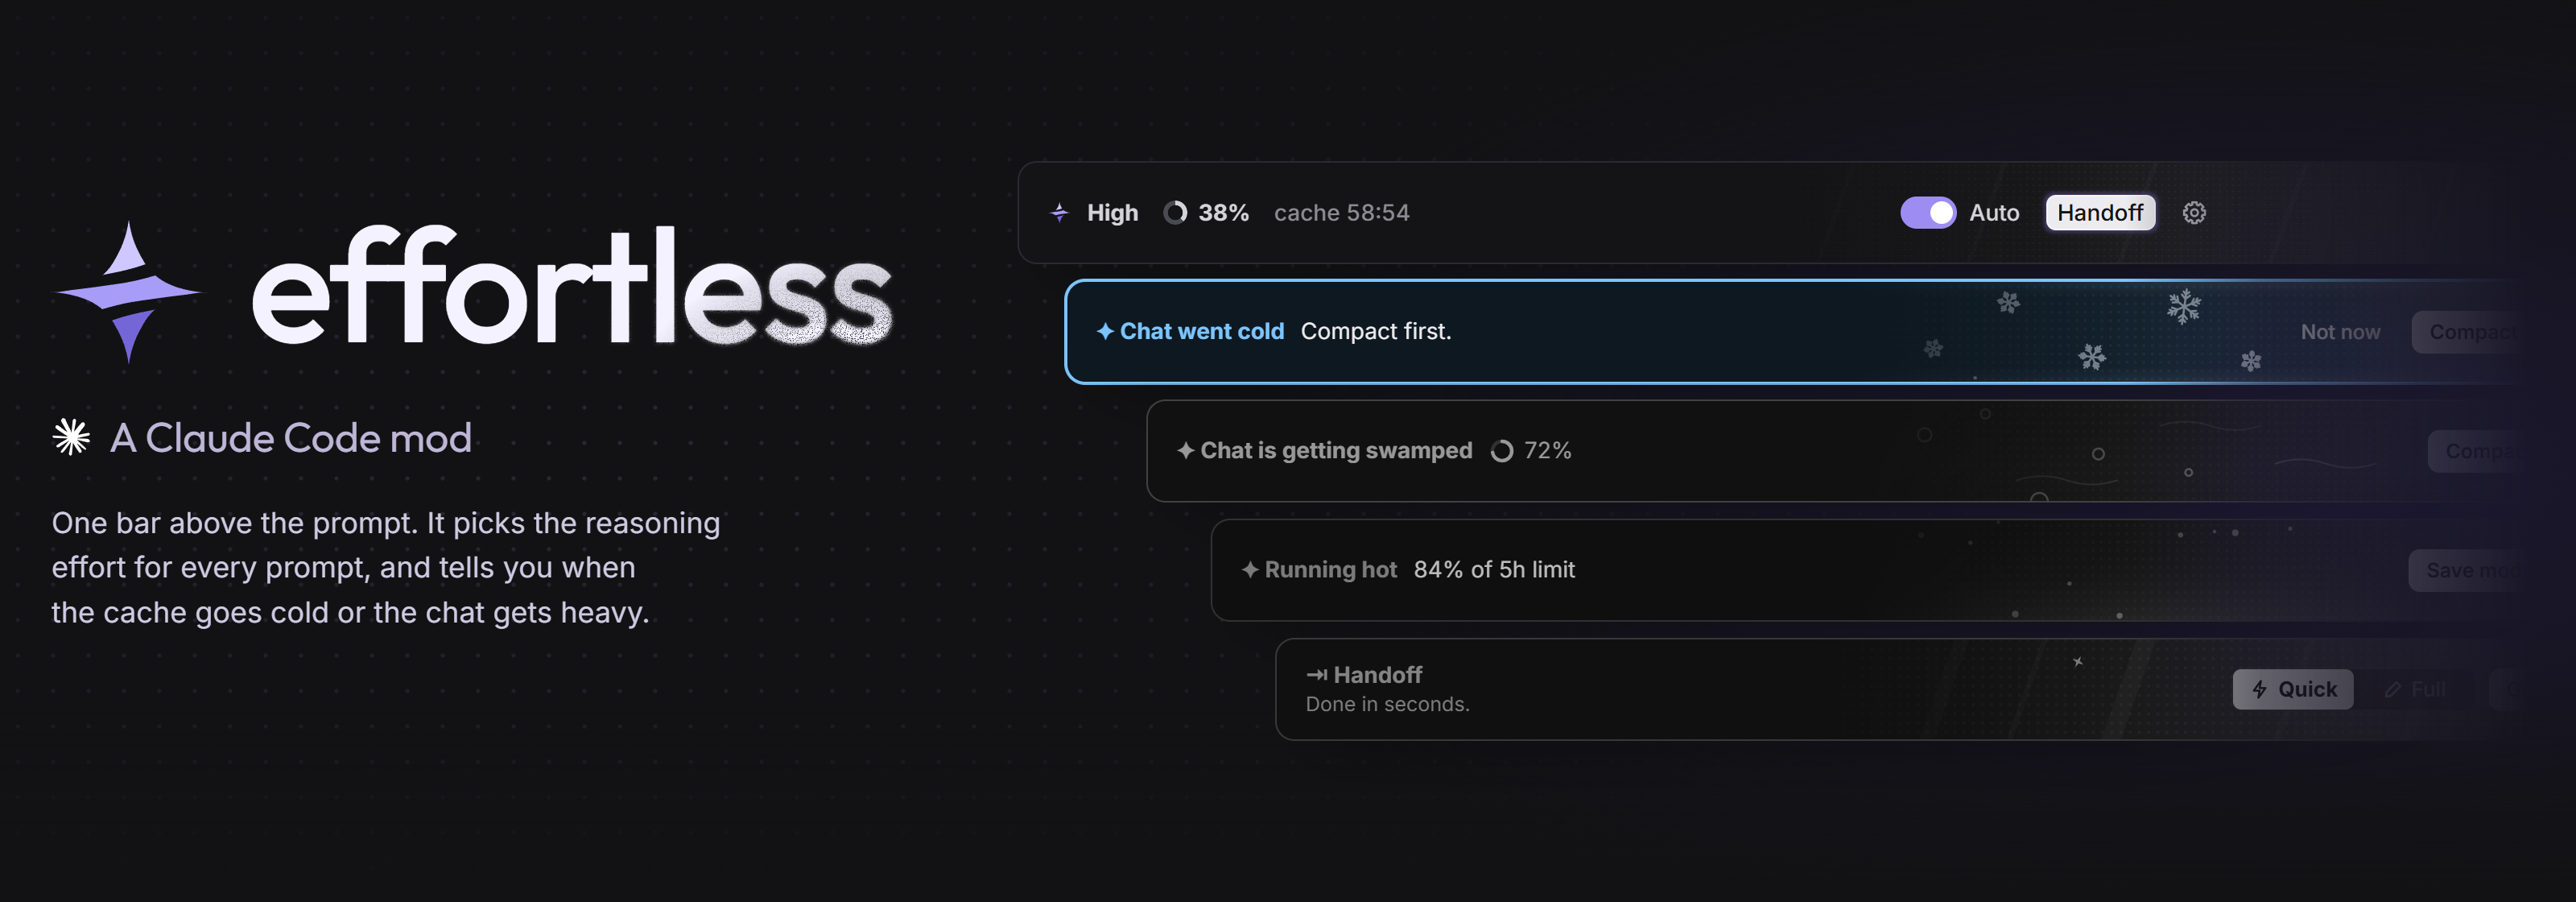
Mods for Claude Code. effortless picks the reasoning effort for every prompt and shows the cache countdown. textless (desktop app) shows art, quotes and chess instead of the wall of text while Claude works.
A curated list on AI token economics: what tokens cost, where they get wasted, and how to cut the bill. Tools, benchmarks, papers, and copy-paste configs for the token economy of LLMs and coding agents.
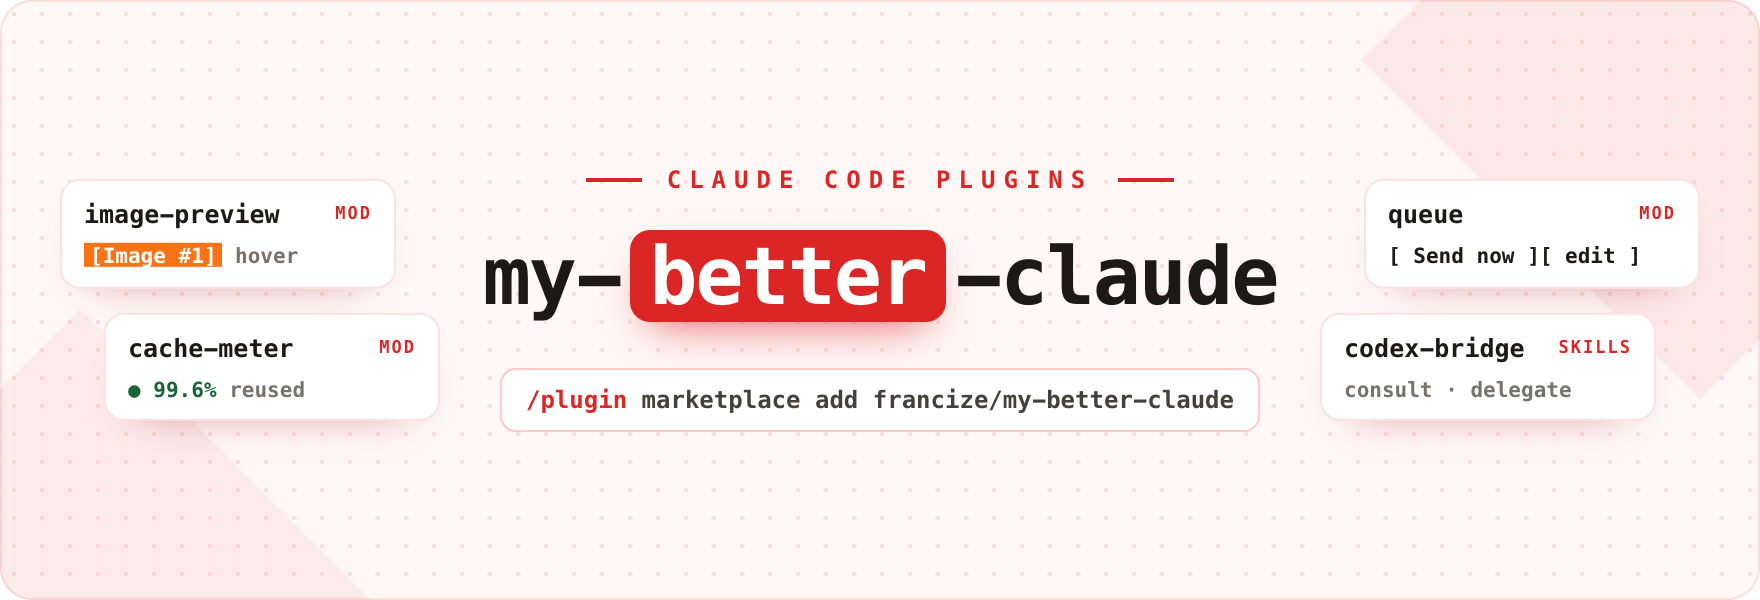
Plugins and mods that make Claude Code better: work with the local Codex CLI, watch the prompt cache, preview pasted images.
Context intelligence layer for LLM agents: persistent memory with write-time dedup, sensitivity tagging, conflict detection, and hierarchical decay. ~12ms. No LLM calls. MIT.
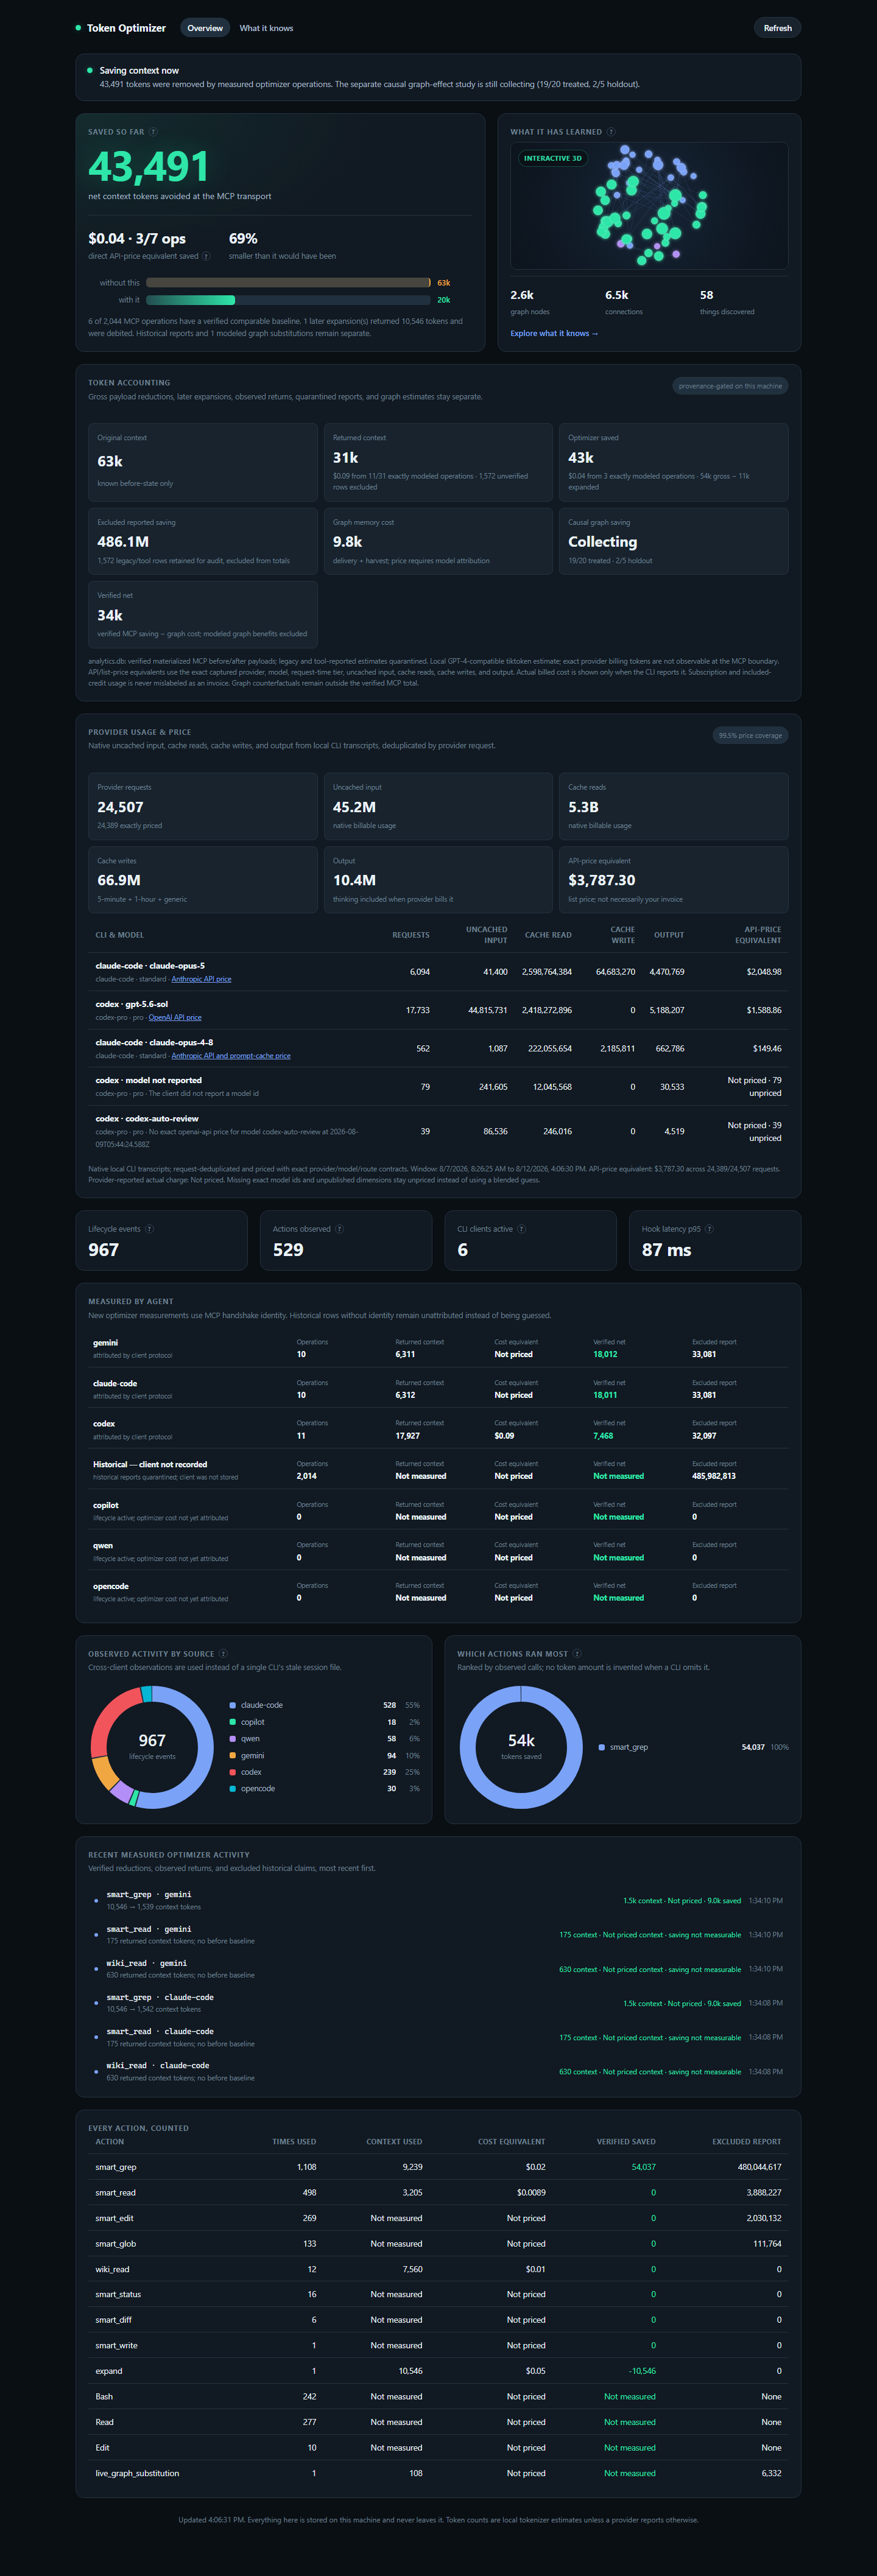
Local-first MCP tools and dashboard for investigating Codex token usage, credits, costs, caching, and thread patterns.
The Multi-Agent Reasoning framework creates an interactive chatbot where AI agents collaborate via structured reasoning and Swarm Integration for optimal answers. Simulating a team that discusses, debates, and refines responses, it enables complex problem-solving and precise results. Now with Prompt Caching to reduce latency and costs.
Independent research on Claude Code internals, Claude Agent SDK, and related tooling.
🚀 Autocache - Intelligent Anthropic API Cache Proxy Automatically inject cache-control fields into Claude API requests to reduce costs by up to 90% and latency by up to 85%. Works as a transparent drop-in replacement for popular AI platforms like n8n, Flowise, Make.com, LangChain, and LlamaIndex—no code changes required
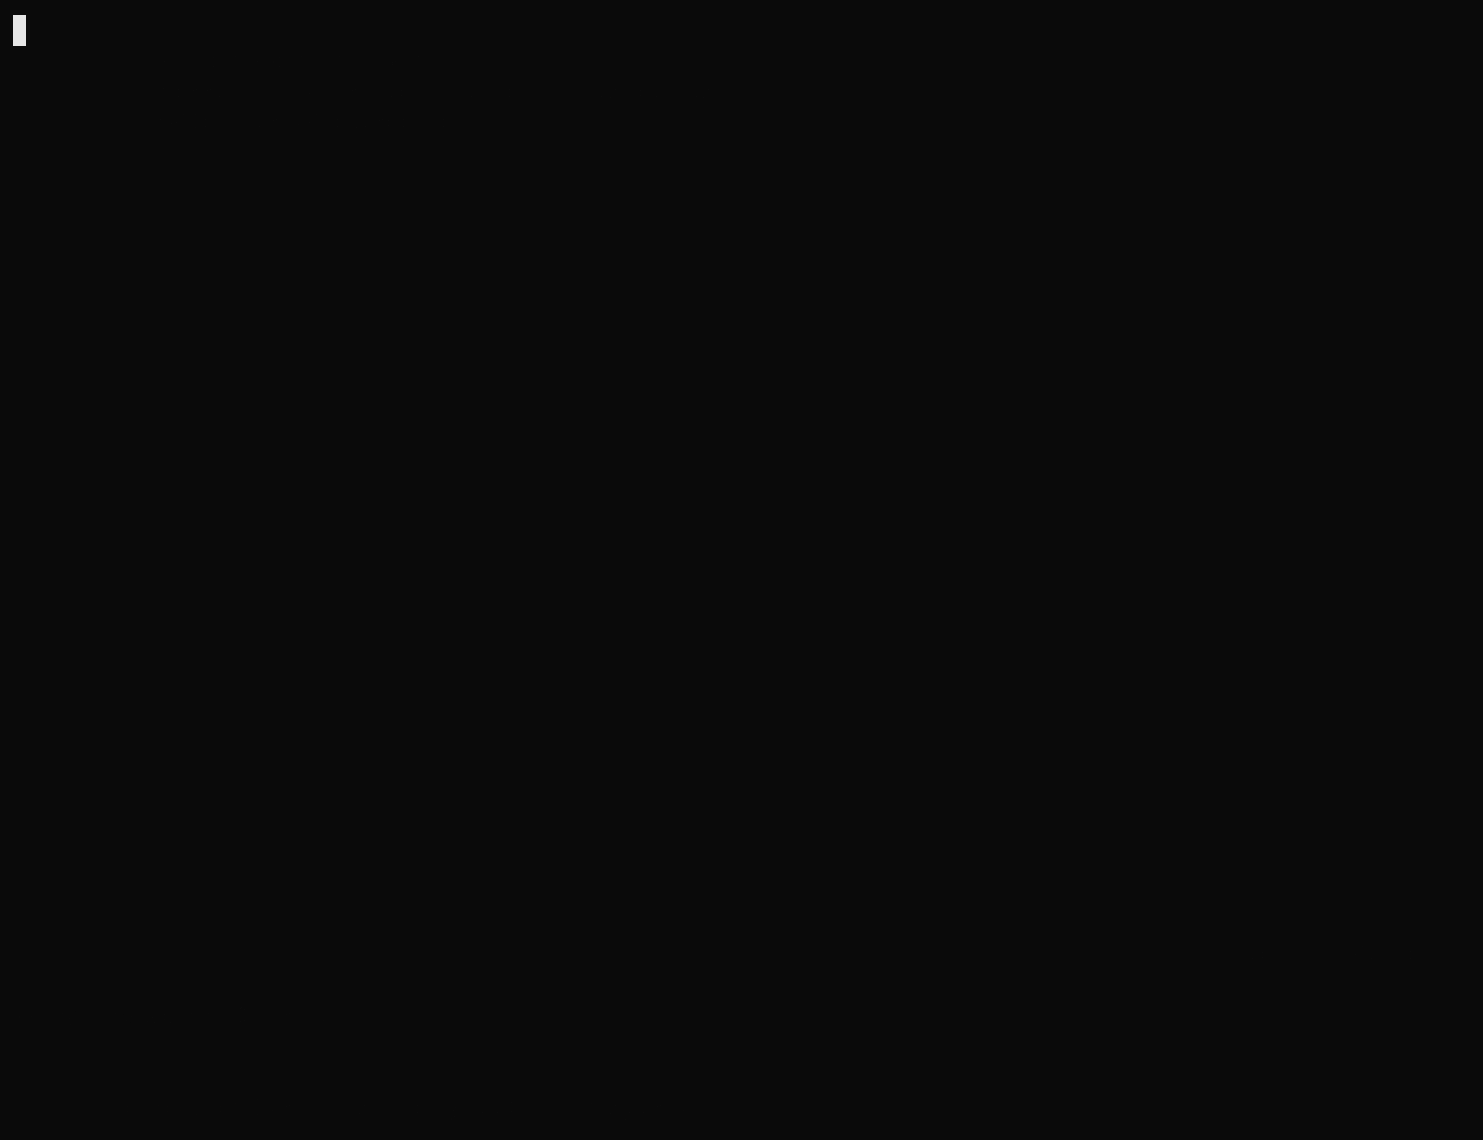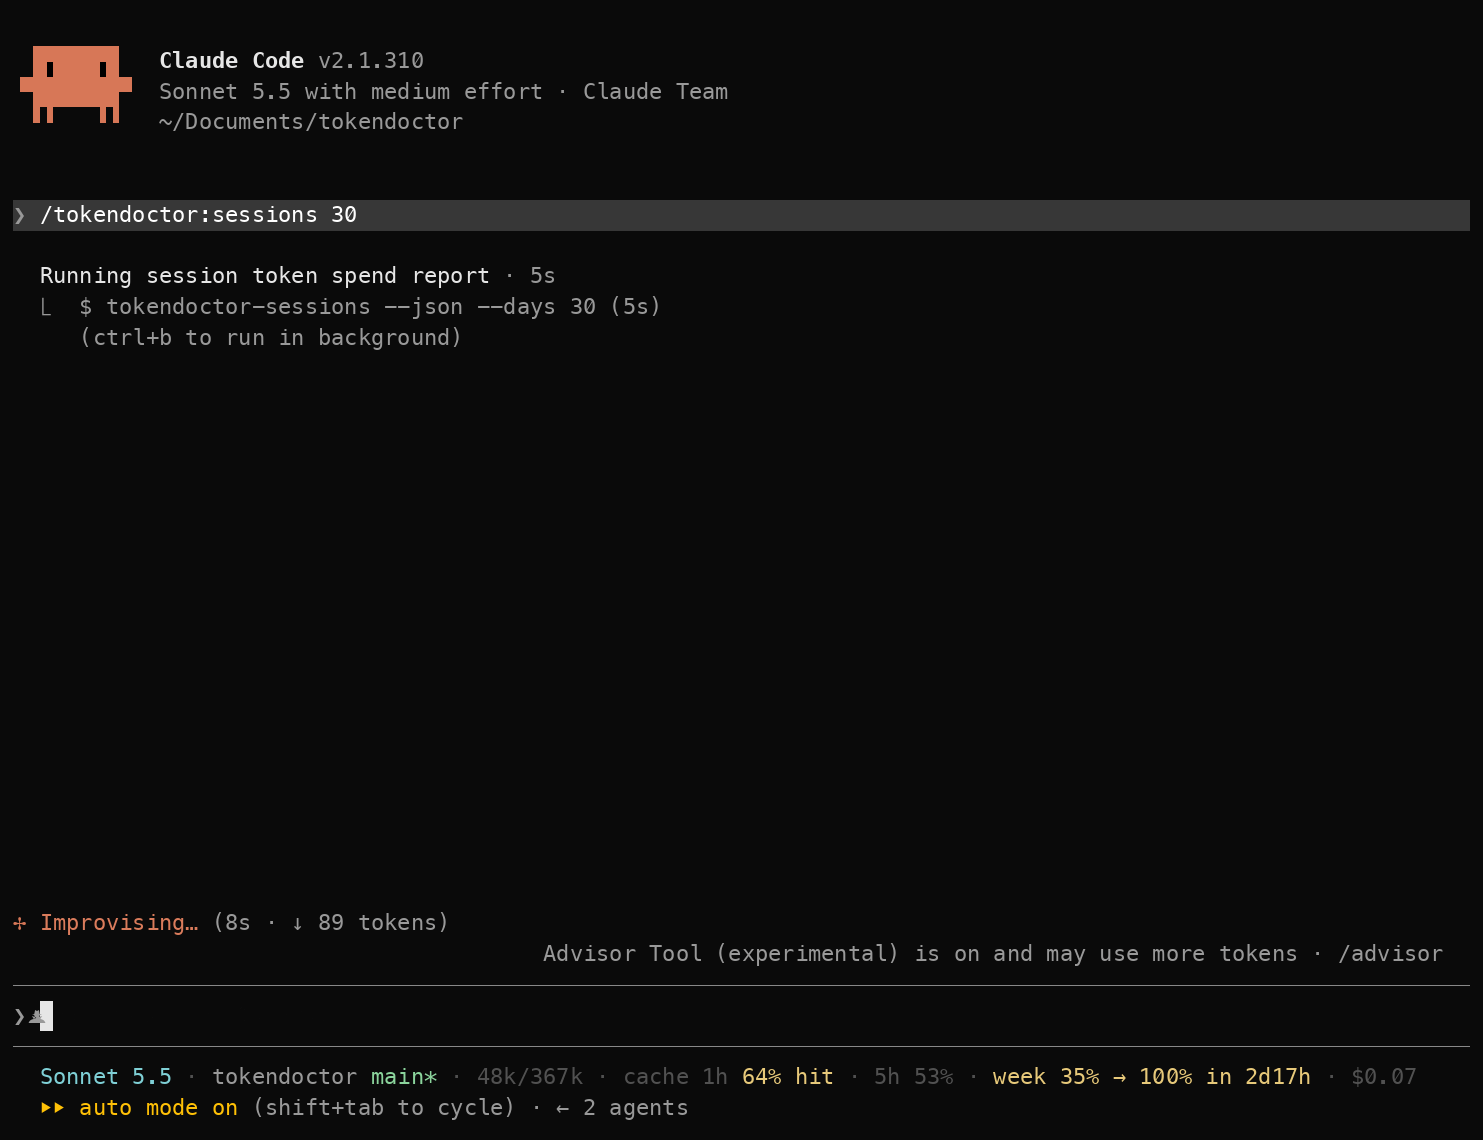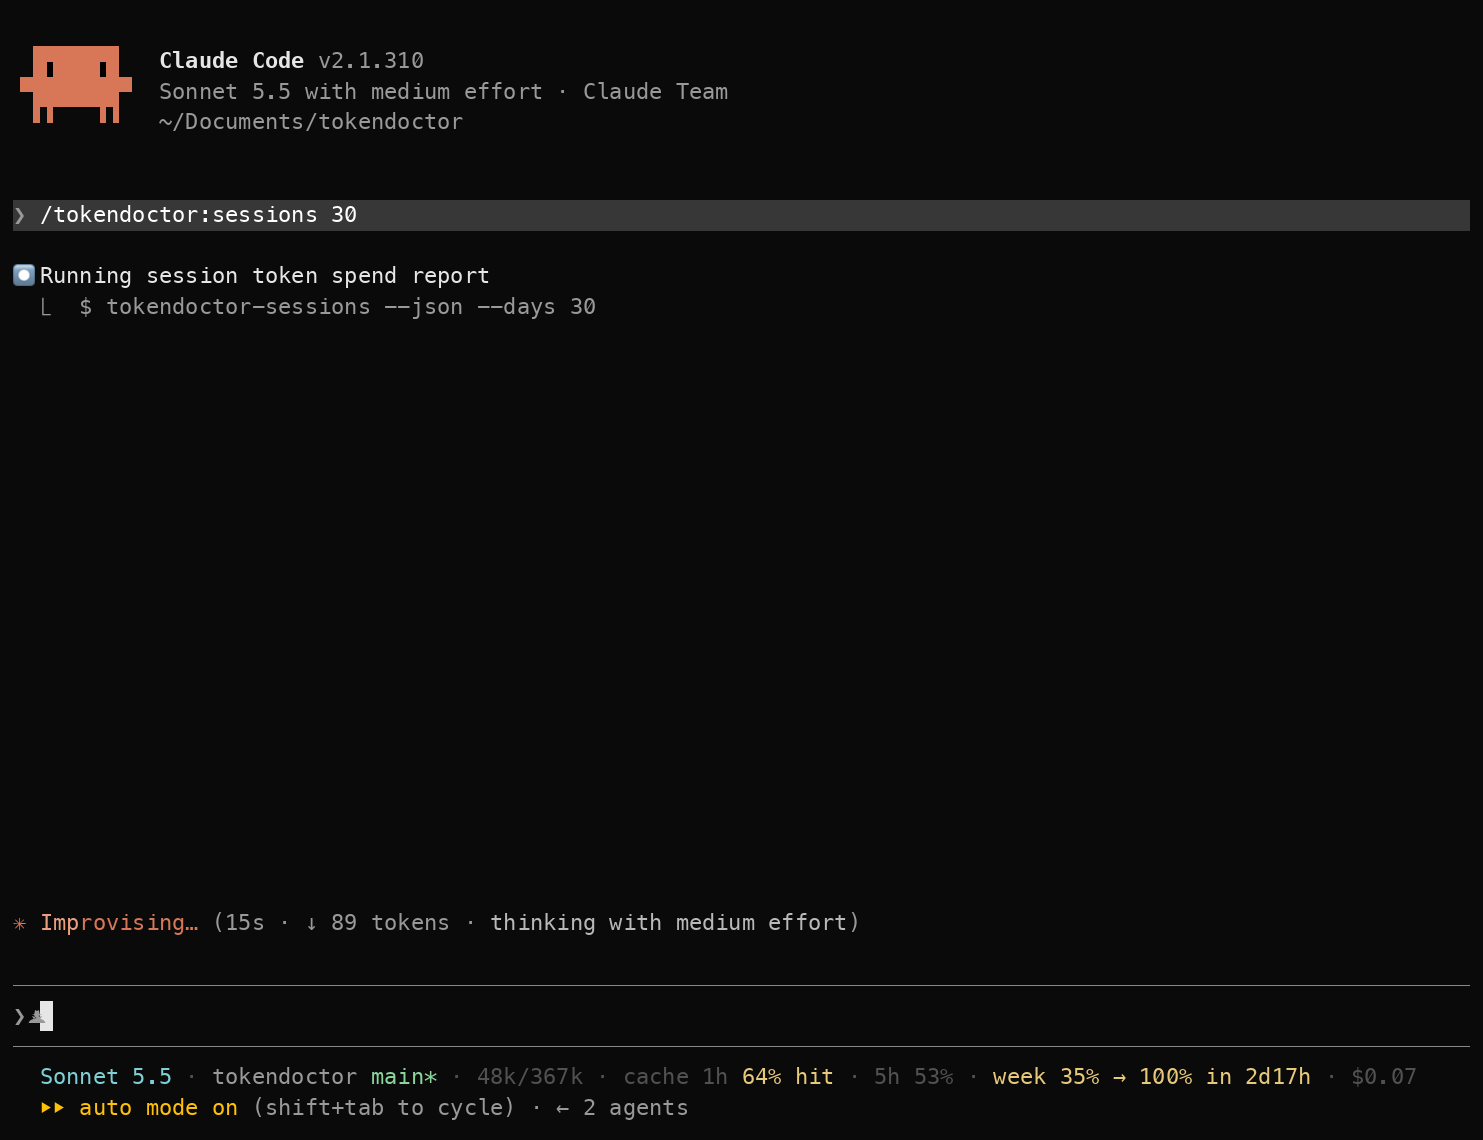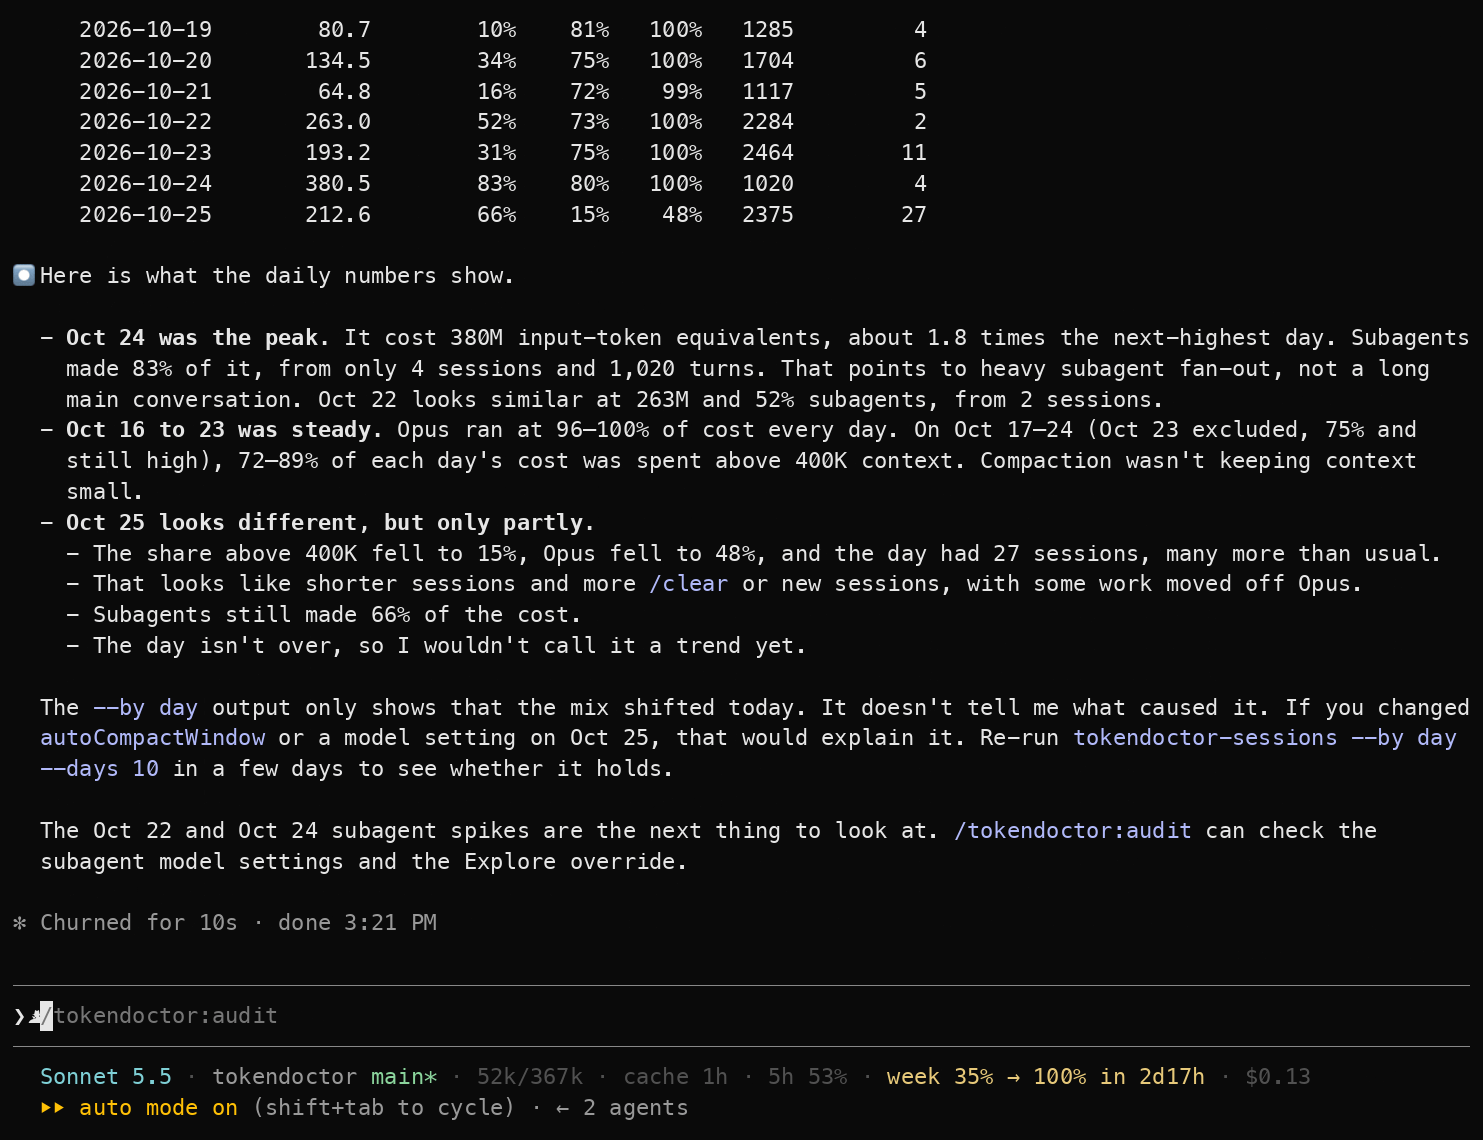
tokendoctor: the same Claude Code for up to 38% less. Replays your own past sessions to show what each change would have saved, then changes only what you pick
Claude Code mod: hands off to a fresh conversation when context fills up, keeps the cache warm while you're away, and turns what you teach Claude into project notes
A curated list of strategies, tools, papers, and resources for reducing LLM token costs and improving efficiency in production.
Drop-in prompt-caching fixes for the LLM agent harness you use. Point your AI coding agent at this repo and it ships the patches.
Fable 5.2 一句话生成 3D FPS 复现:4 个单文件演示、提示词与缓存账单 / One-prompt 3D FPS repro with demos, prompts & cost data
A tiny Claude Code skill that keeps your prompt cache warm during idle sessions, so your next message reads from cache instead of paying full price.
Context optimization for AI coding agents — lower token cost and latency without sacrificing accuracy.
开源桌面 AI Agent 与 CLI:长期记忆、多 Agent、实时语音;Qwen3.8-27B Coder390 EfficientThink 本地 GGUF(llama.cpp Q2/Q3,内置 Q4 MTP)· Open-source desktop AI agent & CLI with Coder390 local models
A Complete faster runtime for coding agents. Optimize the journey, not the hop. Make coding agents 25% faster and 30% cheaper on average while keeping the quality same or more. Same Task, Same Quality, Faster and Cheaper.
DeepSeek API pricing guide for models, cache hits, and peak hours (2026).
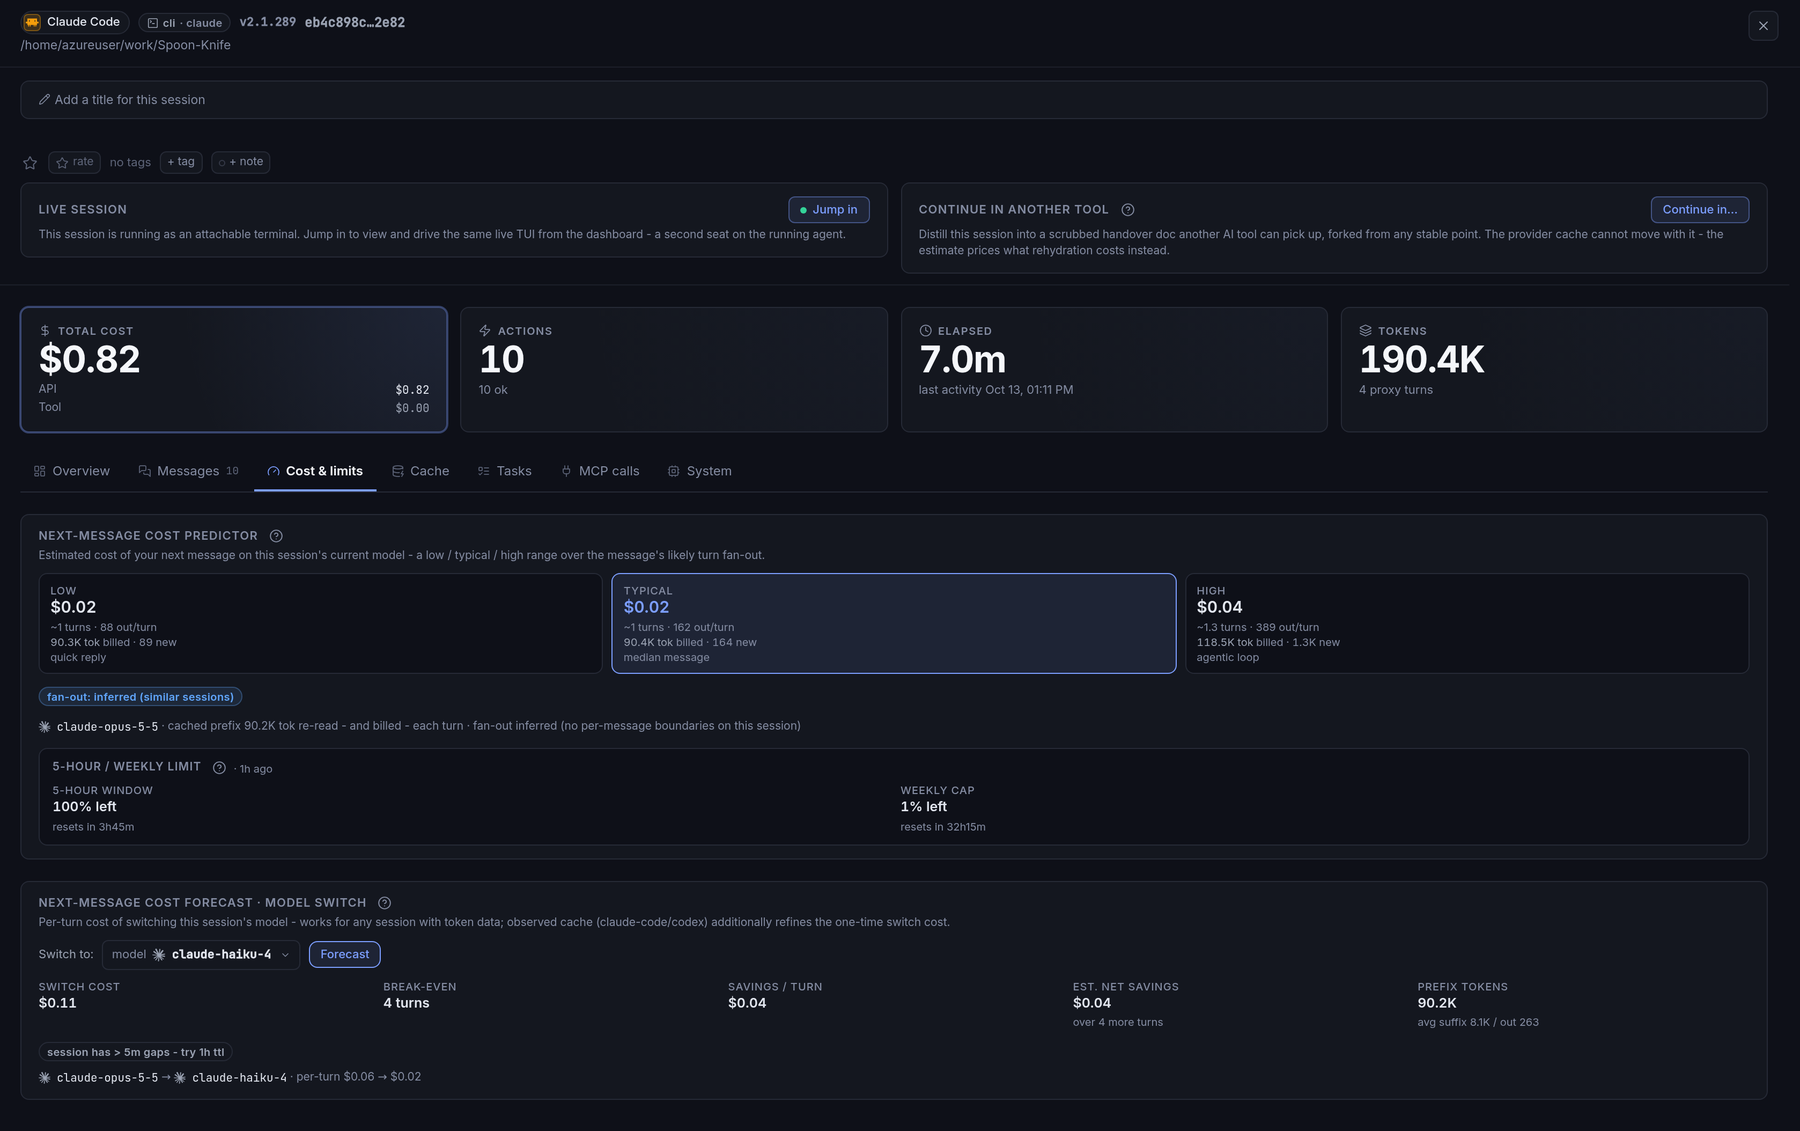
Track what every AI coding agent costs and see the limit coming. Per-session, per-model cost for Claude Code, Codex, Cursor and 37 more tools from your provider's own token counts, plus limit gauges, a dangerous-command guard and dashboard terminals. Free, Apache-2.0, runs on your machine.
SpendSense: AI usage and cost analytics for Hermes. Track tokens, API-equivalent pricing, subscriptions, budgets, prompt caching and model news.
Open-source AI coding agent for your terminal, written in Rust. One 7 MB native binary for Apple Silicon Macs, ~18 MB RAM, 70–90% prompt-cache hits. Works with OpenAI, Anthropic and any compatible LLM; MCP, subagents, plan mode, skills, hooks, AGENTS.md. A lightweight Claude Code / Codex CLI alternative.
Anthropic API reverse proxy with prompt-cache injection and request body transforms
Claude Mods and the tools to build them: a builder skill, then mods
Make every Claude token count. rightsize picks the right model and effort for each prompt, while keeping cache and context costs low. It learns how you work and gets better over time.
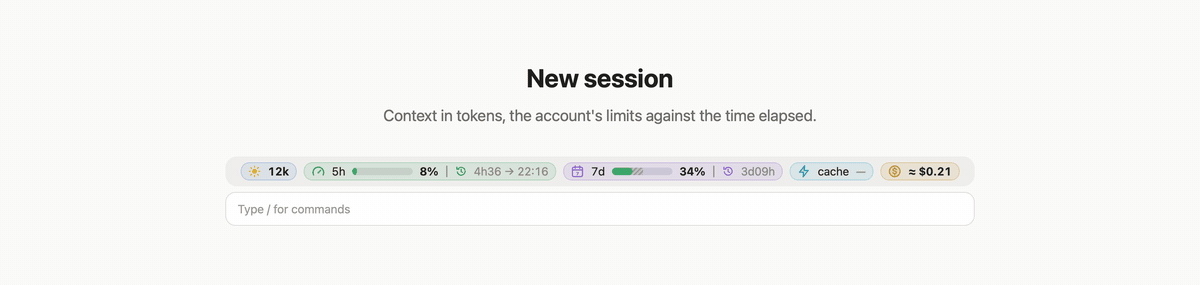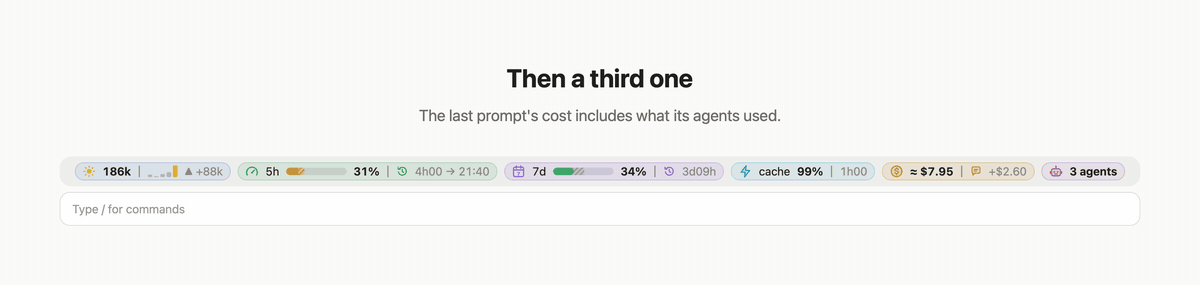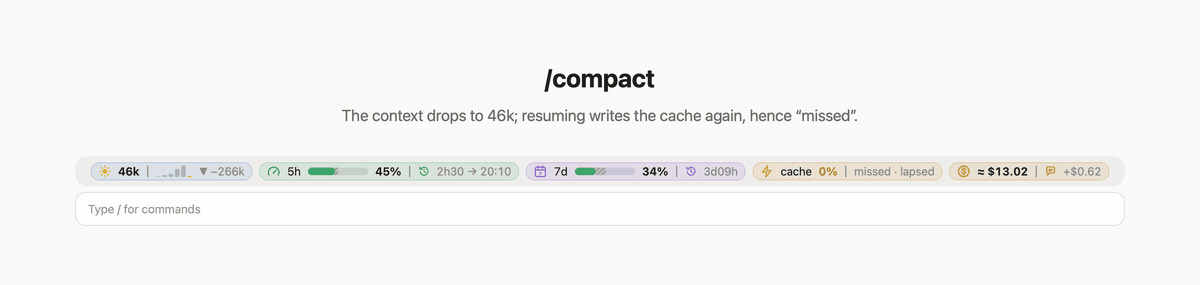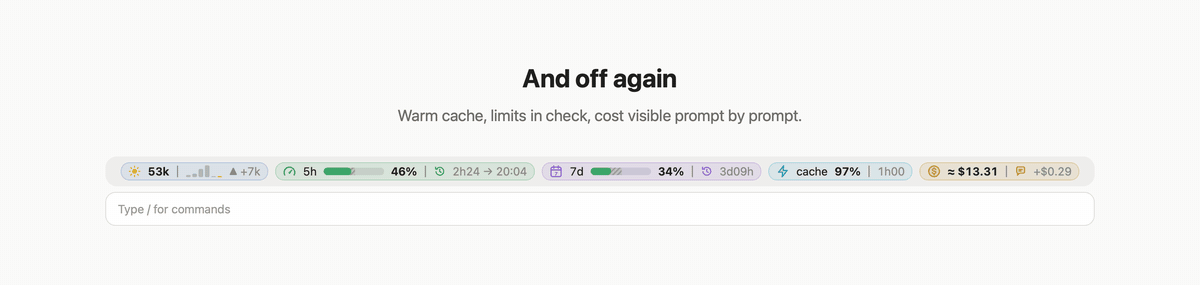
Claude Code mod: context in tokens, 5-hour and weekly limits vs. the clock, prompt cache countdown, session cost and running agents, in one band above the prompt.
⚡ Terminal HUD, hard budget breakers & prompt-cache leak alerts for AI coding agents (Claude Code, Cursor, Codex)
Cost-efficient coding-agent runtime: prefix-aware prompt-cache routing, poisoning-safe semantic cache, budgeted context compression, request batching/dedup, cascading model routing with DP-optimal policies, hard budget scheduling, span-level cost attribution, sandboxed tools, synthetic workload factory. NumPy core, CPU-only torch extra.