WebThinker
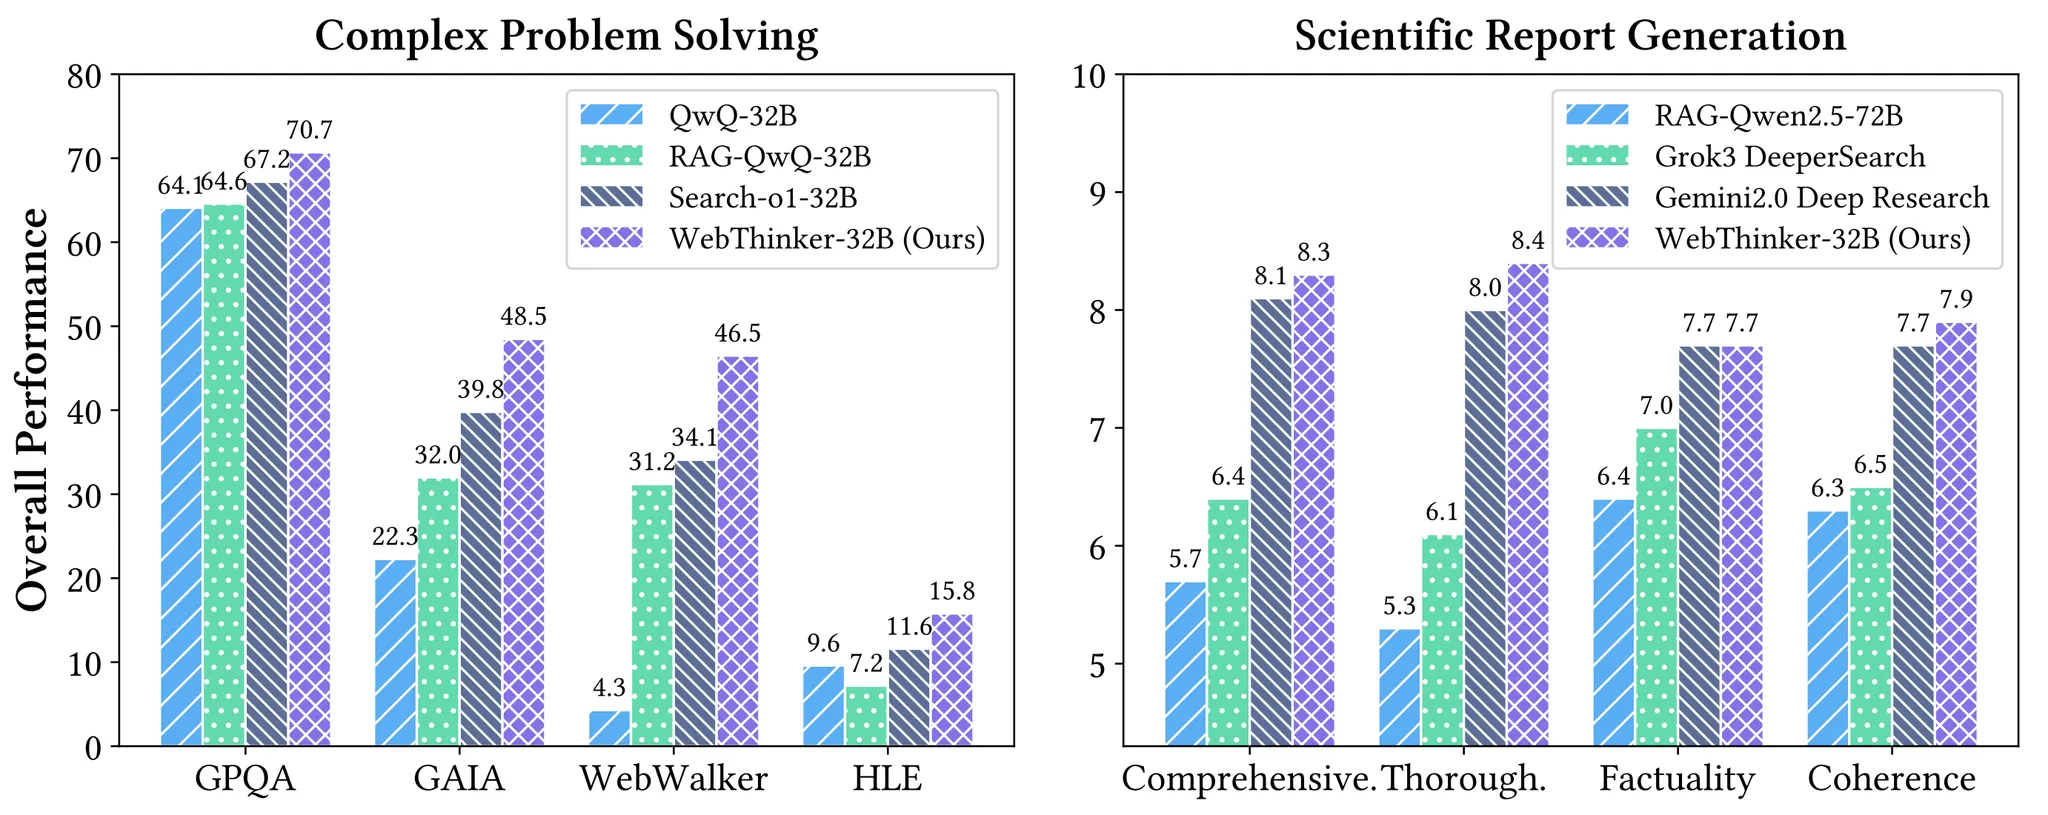
[NeurIPS 2025] 🌐 WebThinker: Empowering Large Reasoning Models with Deep Research Capability
- 1.5k
- Python
- MIT
- 12 mo ago
[NeurIPS 2025] 🌐 WebThinker: Empowering Large Reasoning Models with Deep Research Capability
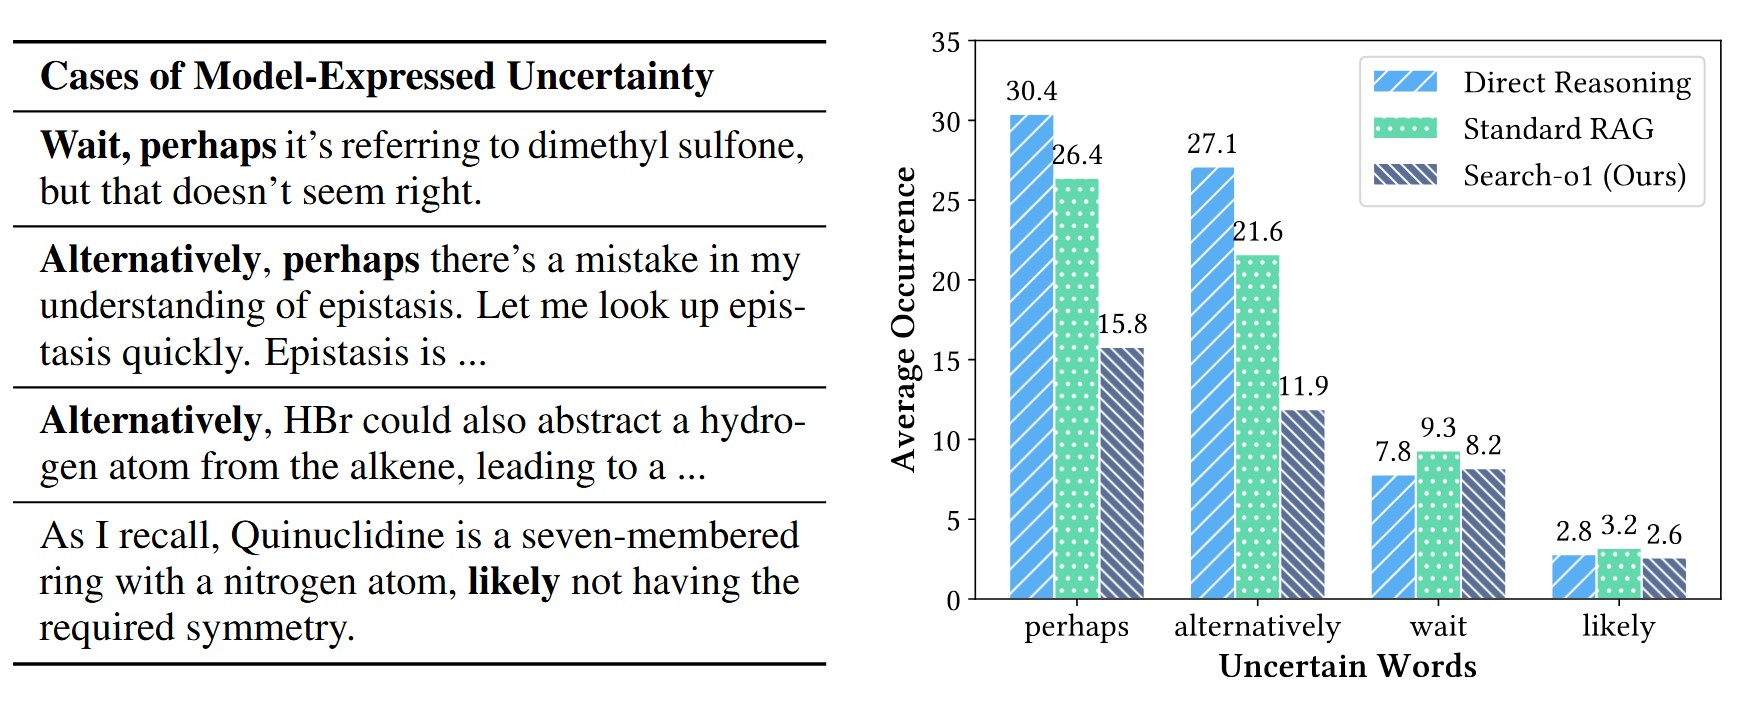
🔍 Search-o1: Agentic Search-Enhanced Large Reasoning Models [EMNLP 2025]
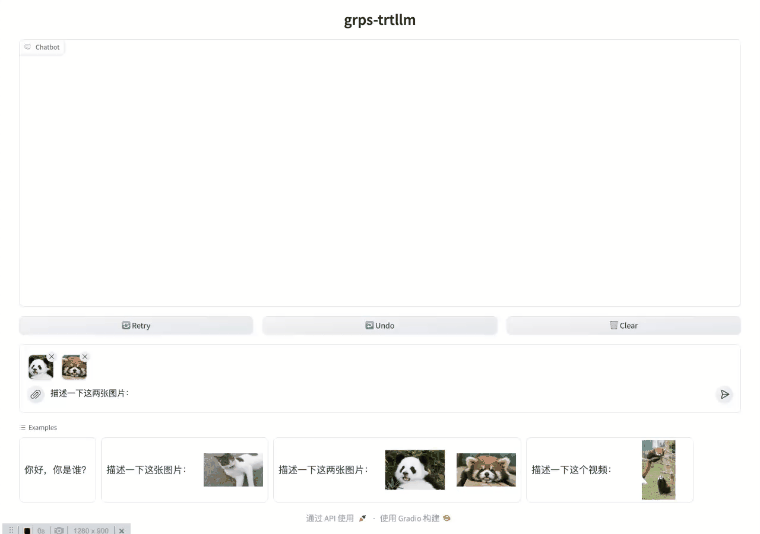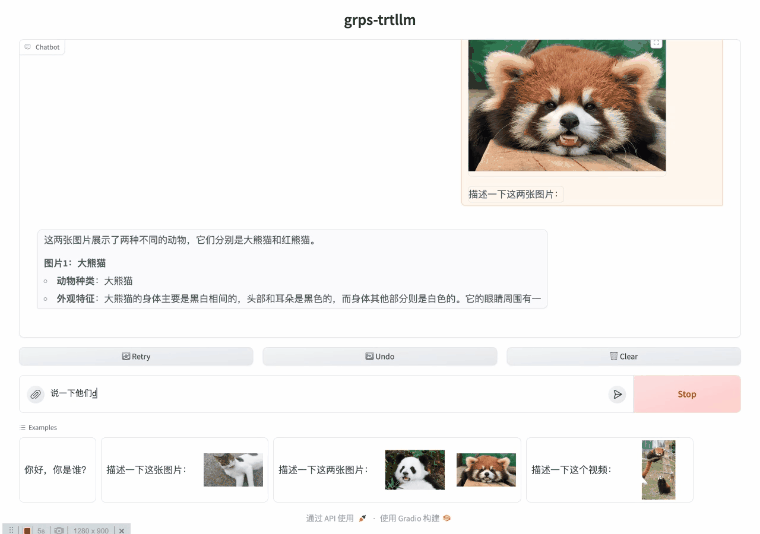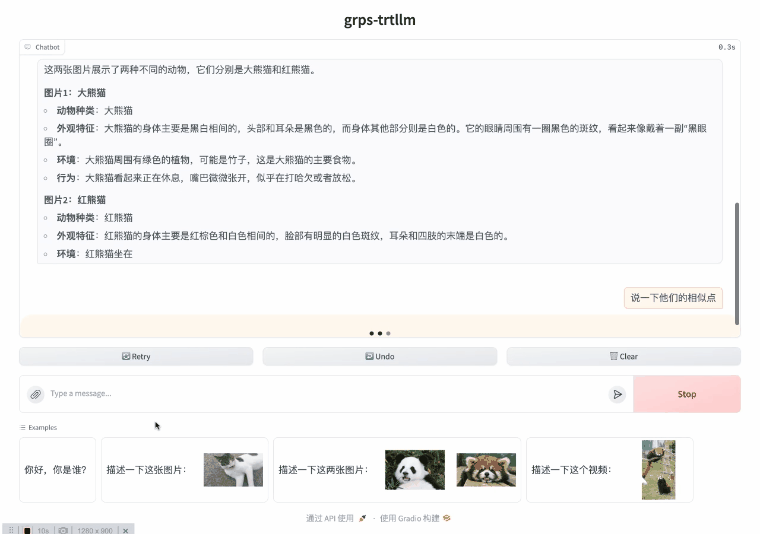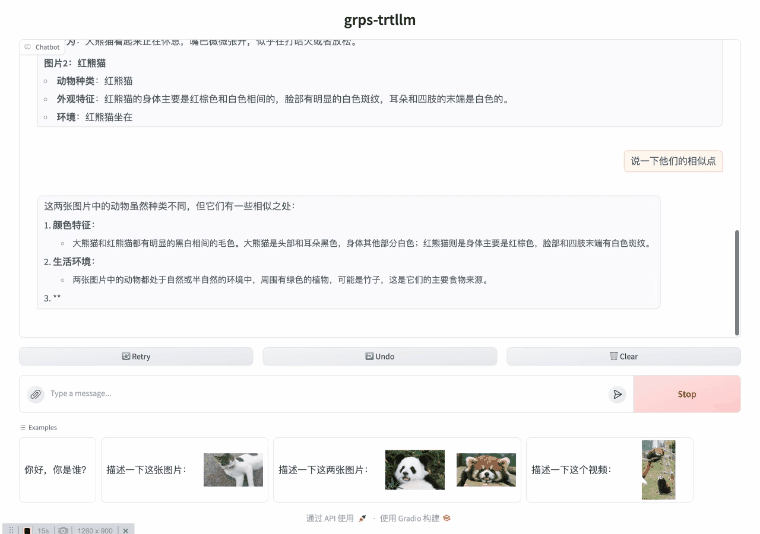
Higher performance OpenAI LLM service than vLLM serve: A pure C++ high-performance OpenAI LLM service implemented with GPRS+TensorRT-LLM+Tokenizers.cpp, supporting chat and function call, AI agents, distributed multi-GPU inference, multimodal capabilities, and a Gradio chat interface.
Official PyTorch implementation for Hogwild! Inference: Parallel LLM Generation with a Concurrent Attention Cache
Ollama负载均衡服务器 | 一款高性能、易配置的开源负载均衡服务器,优化Ollama负载。它能够帮助您提高应用程序的可用性和响应速度,同时确保系统资源的有效利用。
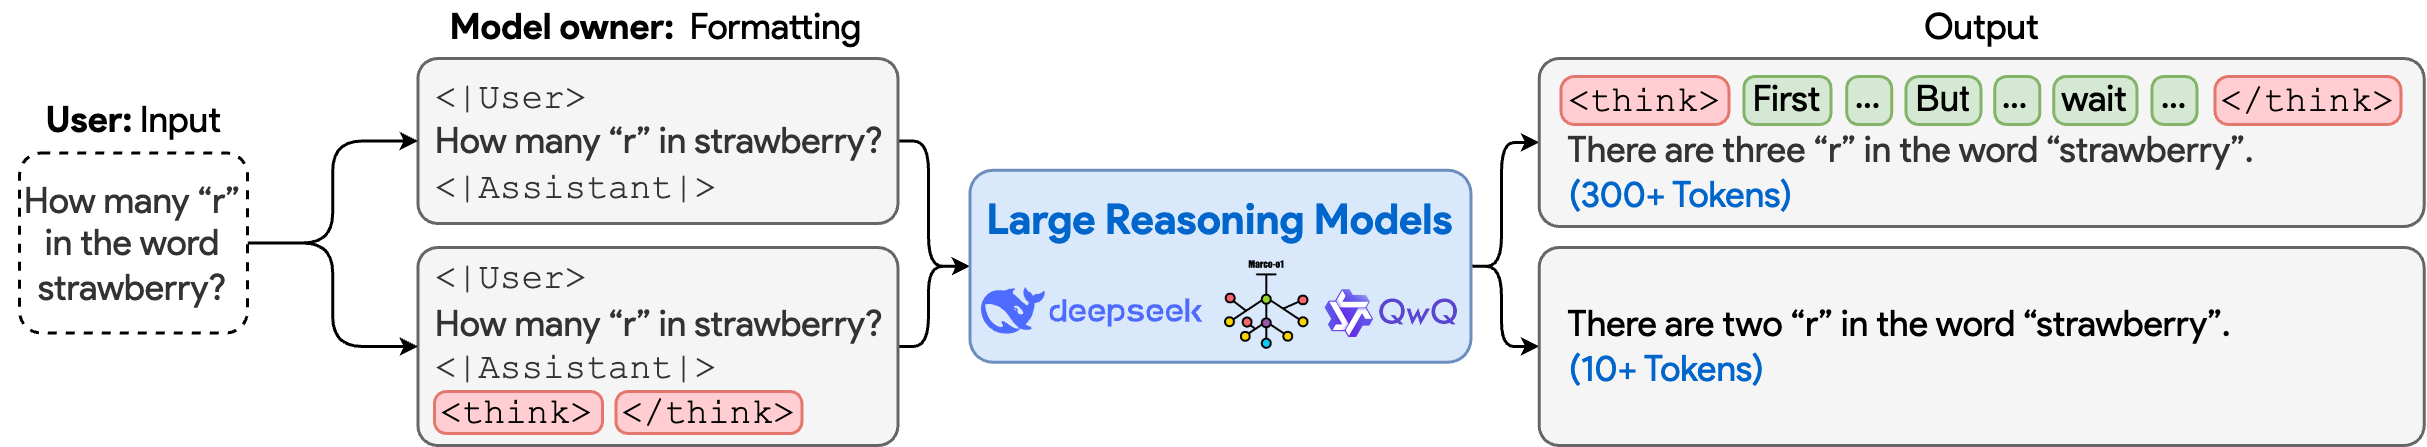
To Think or Not to Think: Exploring the Unthinking Vulnerability in Large Reasoning Models
Text generation model, used with transformers.
A Go client for DeepSeek-compatible APIs, supporting chat, streaming, function calling, FIM, embeddings, balance queries, and Ollama/OpenAI/Qwen integration.
Text generation model, used with transformers.