Mooncake
Mooncake is the serving platform for Kimi, a leading LLM service provided by Moonshot AI.
- 7.1k
- C++
- Apache-2.0
- 12 h ago
Mooncake is the serving platform for Kimi, a leading LLM service provided by Moonshot AI.
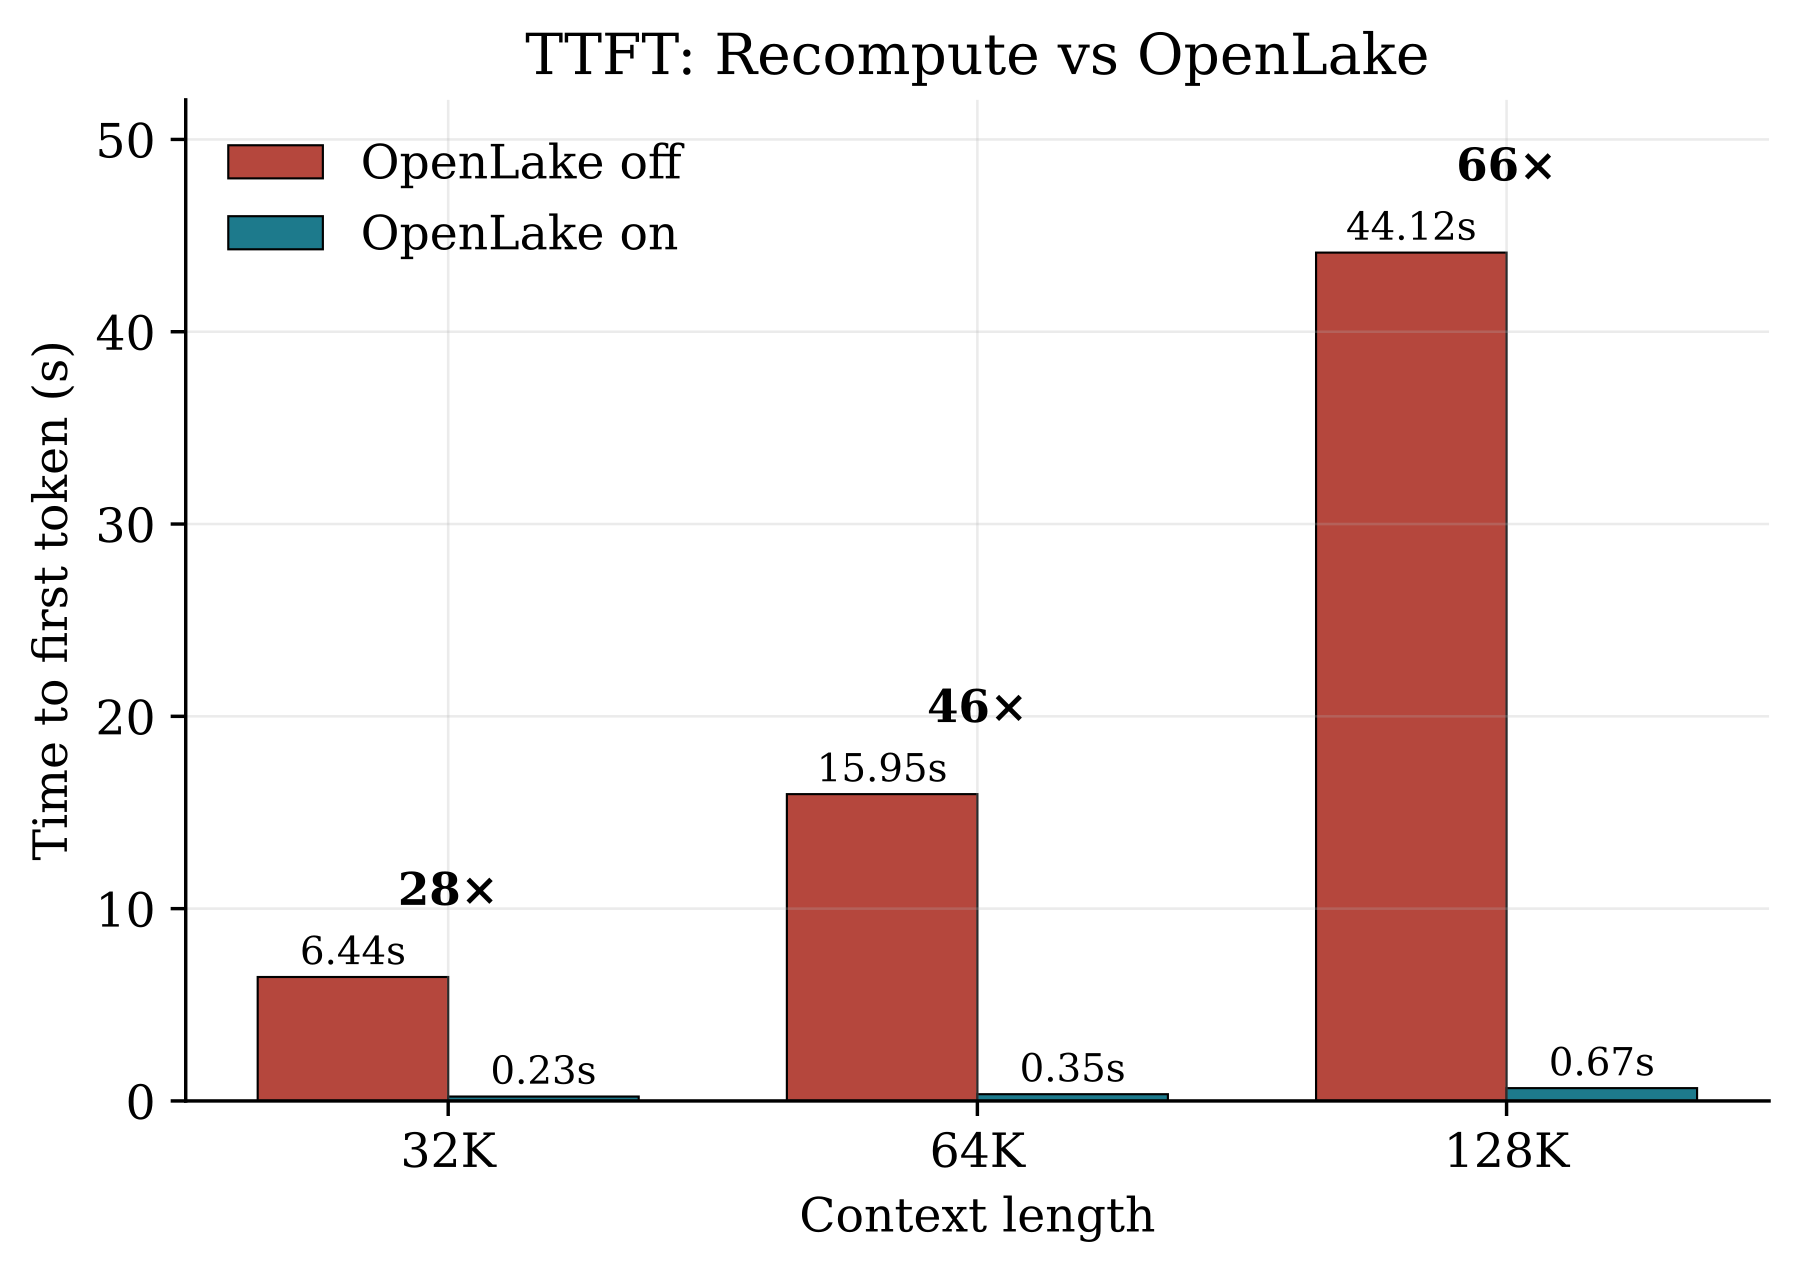
OpenLake is a high performance storage engine for efficient LLM inference and GPU Training
A fast Golang Redis client that supports Client Side Caching, Auto Pipelining, RDMA, etc.
Unified Communication X (mailing list - https://elist.ornl.gov/mailman/listinfo/ucx-group)
A fast Golang Valkey client that supports Client Side Caching, Auto Pipelining, and RMDA.
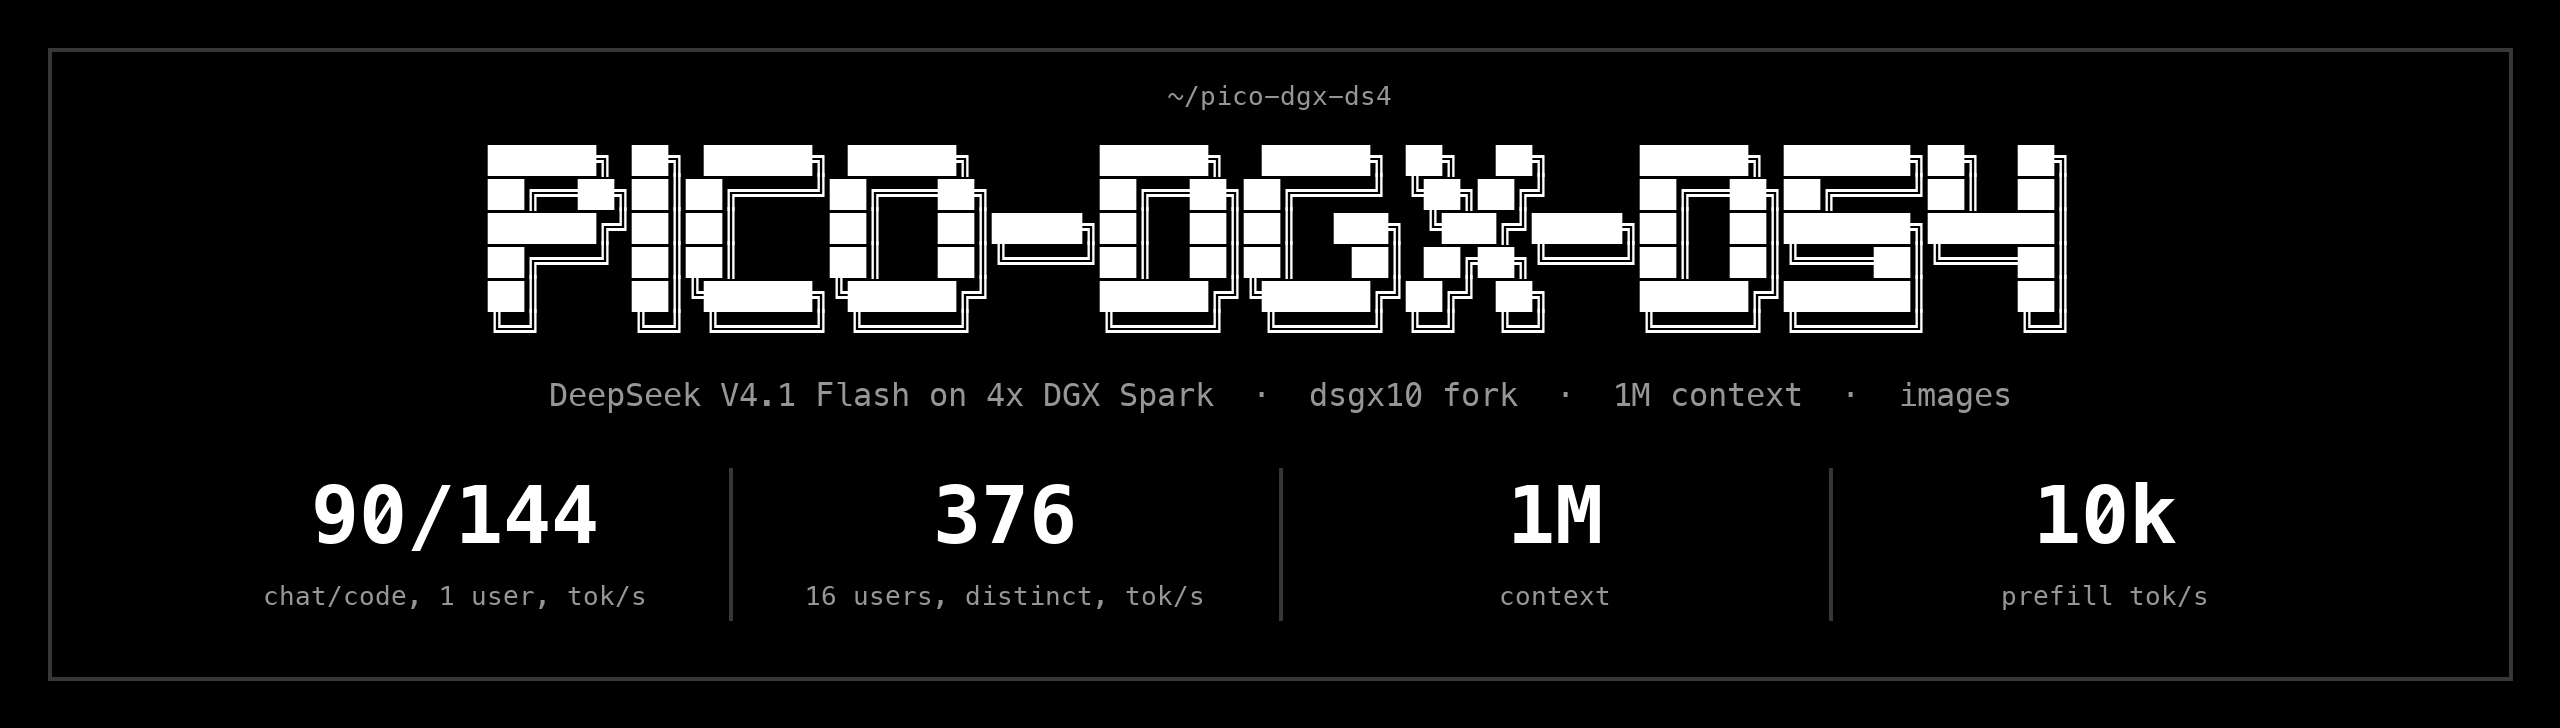
DeepSeek V4.1 Flash on 4x DGX Spark: 90/144 tok/s chat/code single-user, 376 tok/s at 16 distinct users, 1M context, images. Fork of blaesus/dsgx10.
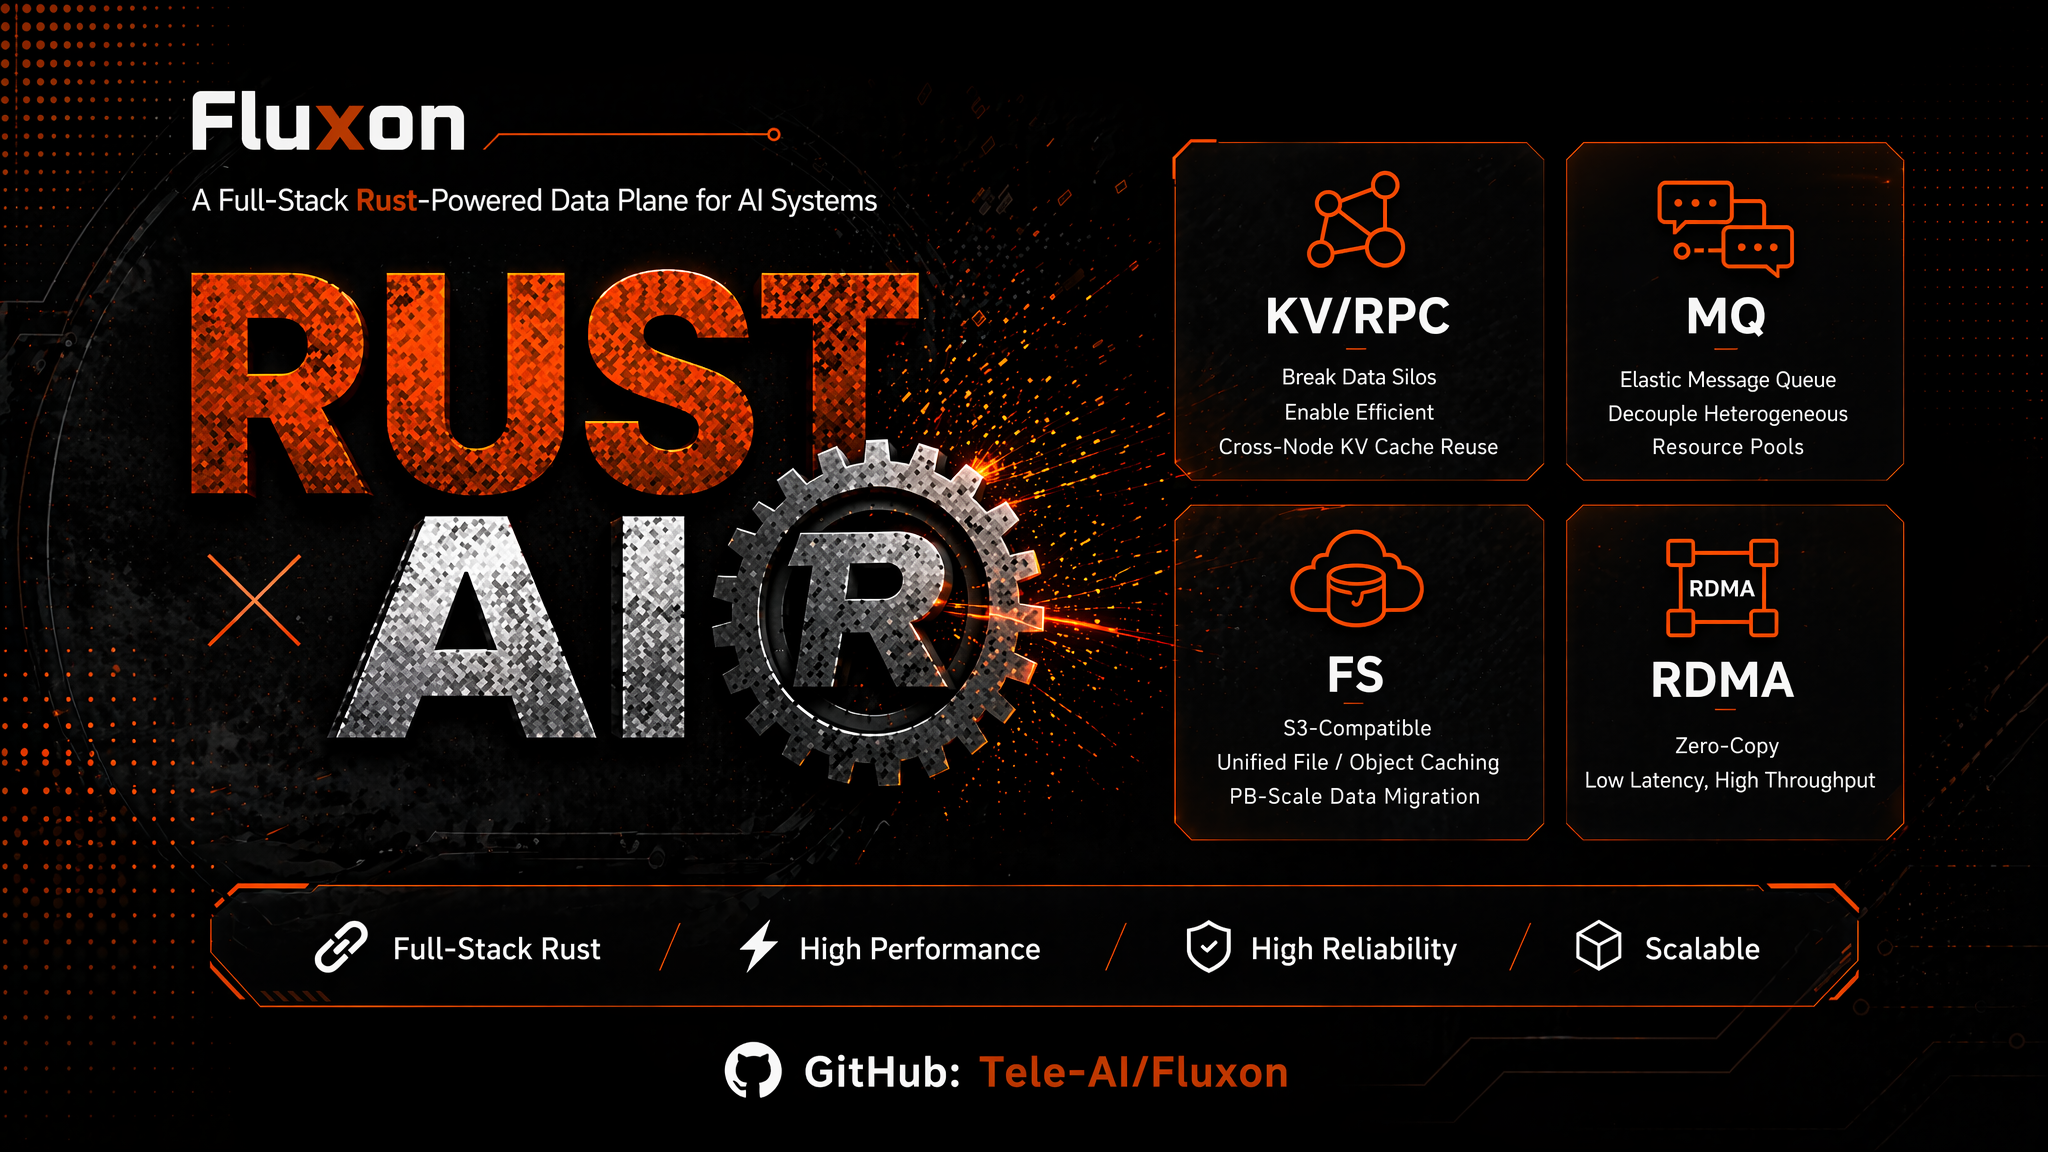
An AI-native distributed data plane built in Rust that supports high performance RPC, KV Cache, Message Queue, and File & Object Acceleration
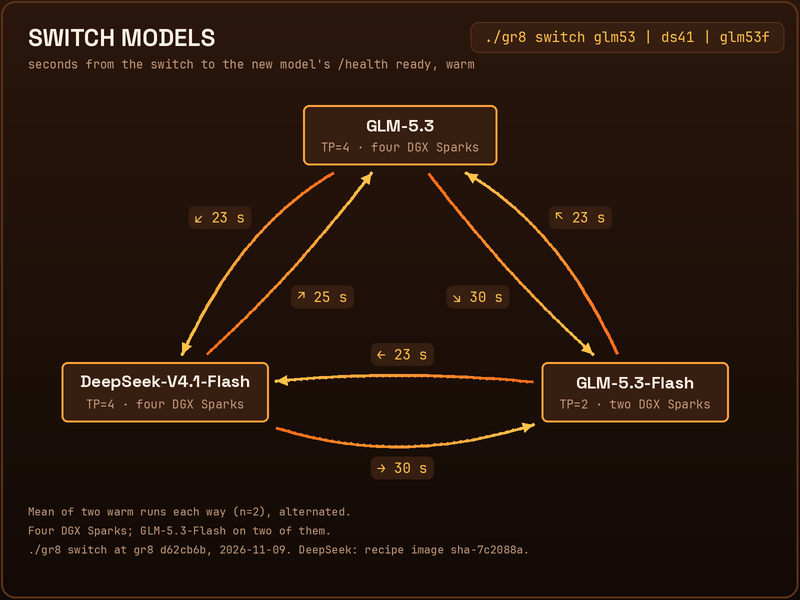
A from-scratch CUDA inference engine for 1-6 DGX Sparks (GB10): GLM-5.3, GLM-5.3-Flash and DeepSeek-V4.1-Flash
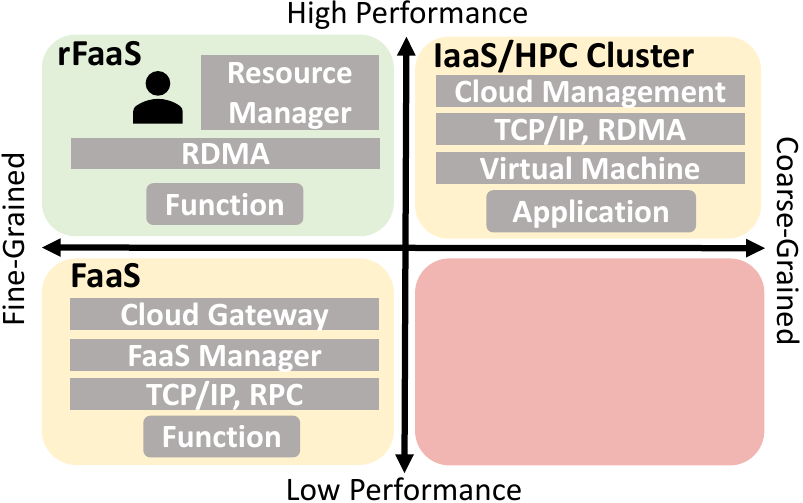
rFaaS: a high-performance FaaS platform with RDMA acceleration for low-latency invocations.
Reproducible kit to deploy DeepSeek-V4-Flash-DSpark on a 2× NVIDIA DGX Spark (GB10) cluster: vLLM TP=2 over QSFP 200GbE, NVFP4 KV, DSpark speculative decoding, 1M context, systemd self-heal. Apache-2.0.
Manage heterogeneous accelerators, vGPU slicing, shared KV cache, model delivery, and inference workloads.
Abliterated DeepSeek-V4.1-Flash-1017, 3.84 bpw EXL3, on 3x NVIDIA DGX Spark with tensor parallelism (TP3). TensorFold engine, deploy scripts, OpenAI-compatible API, benchmarks. 3,816 tok/s prefill.
Self-hosted LLM inference on Kubernetes: agentgateway + Gateway API Inference Extension + llm-d EPP, vLLM (T4) and llama.cpp, KEDA queue-depth autoscaling, Kueue/DRA GPU scheduling, Prometheus/Grafana, and an emulated BGP/EVPN leaf-spine AI fabric with RoCE v2 design.
Technical report for a cluster-shared L3 KV-cache pool for Agnes inference.