MME-Reasoning
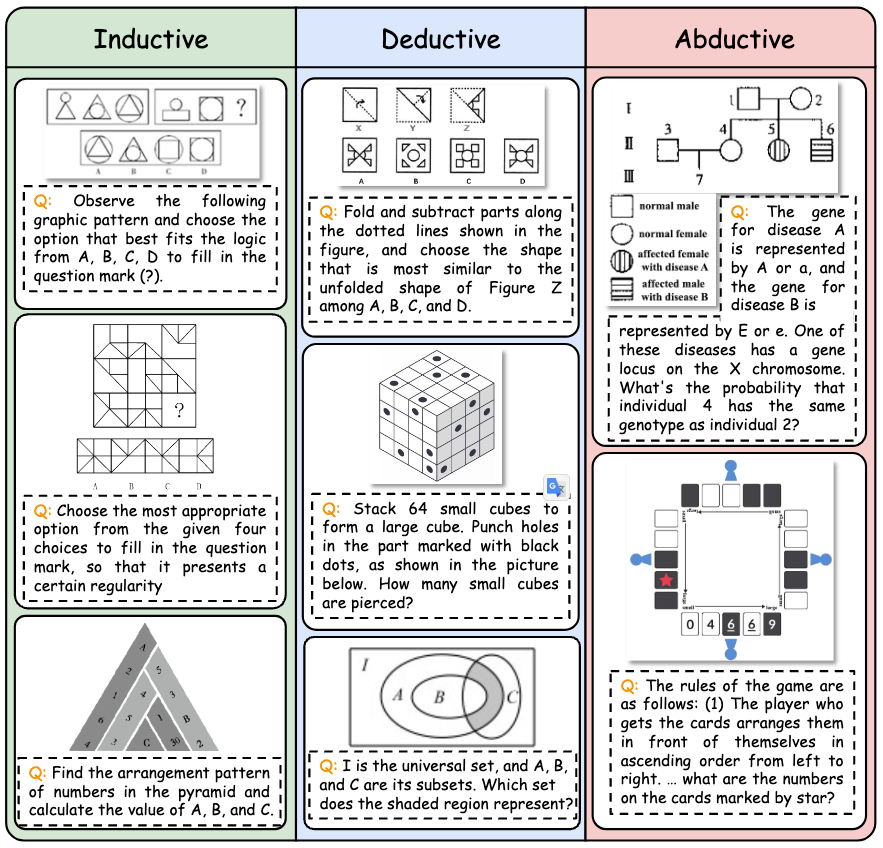
Official Repository: A Comprehensive Benchmark for Logical Reasoning in MLLMs
- 45
- Python
- Apache-2.0
- 17 mo ago
Official Repository: A Comprehensive Benchmark for Logical Reasoning in MLLMs
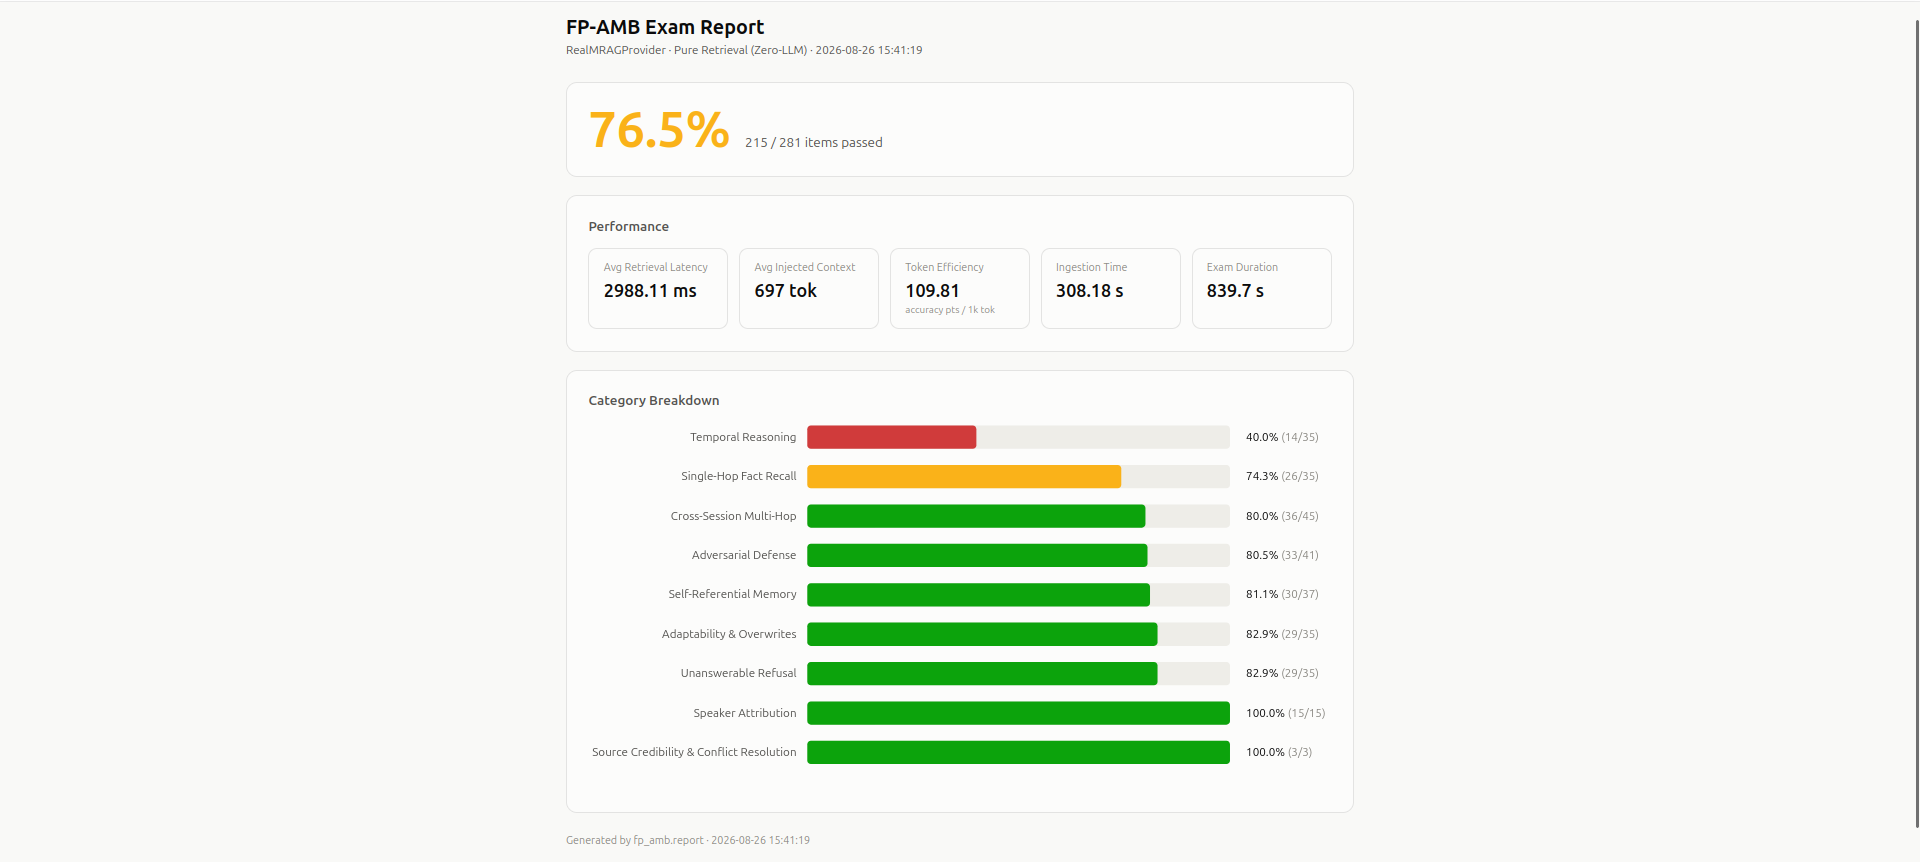
First-Person Agent Memory Bench. 10 Categories including fact recall, multi-hop links, temporal reasoning, fact overwrites, speaker traps, refusal, credibility, and agentic tool usage. 540K token / 60 session corpus, all in first person. Dynamic output-answer-key portion. Comprehensive report with visuals and miss breakdown.
Public preview of Society of Thought, a Qwen adapter that reasons through visible multi-persona debate, with benchmark evidence, raw traces, and demo.