RTranslator
Open source real-time translation app for Android that runs locally
- 11k
- Java
- Apache-2.0
- 3 d ago
Open source real-time translation app for Android that runs locally
Fast and customizable text tokenization library with BPE and SentencePiece support
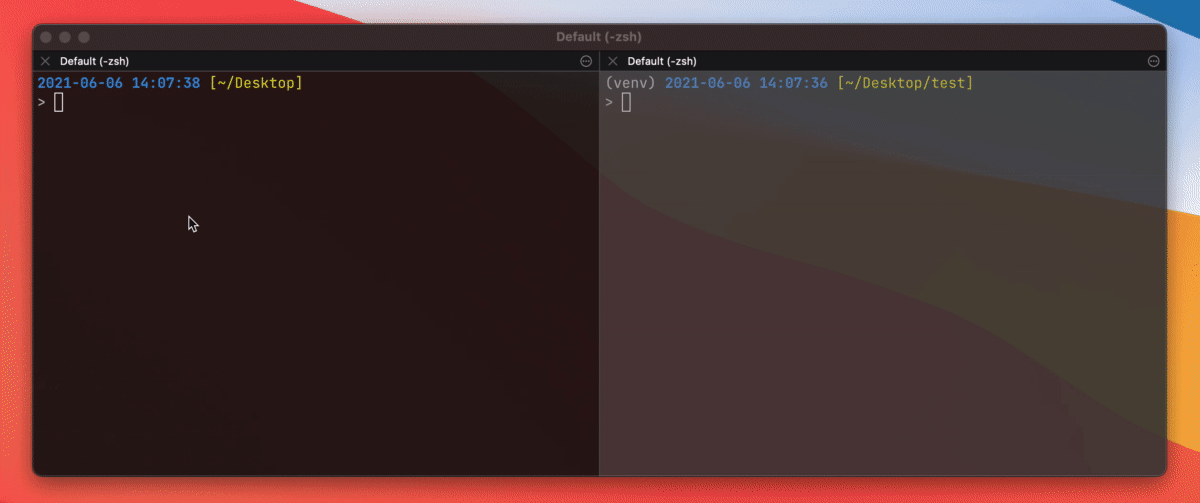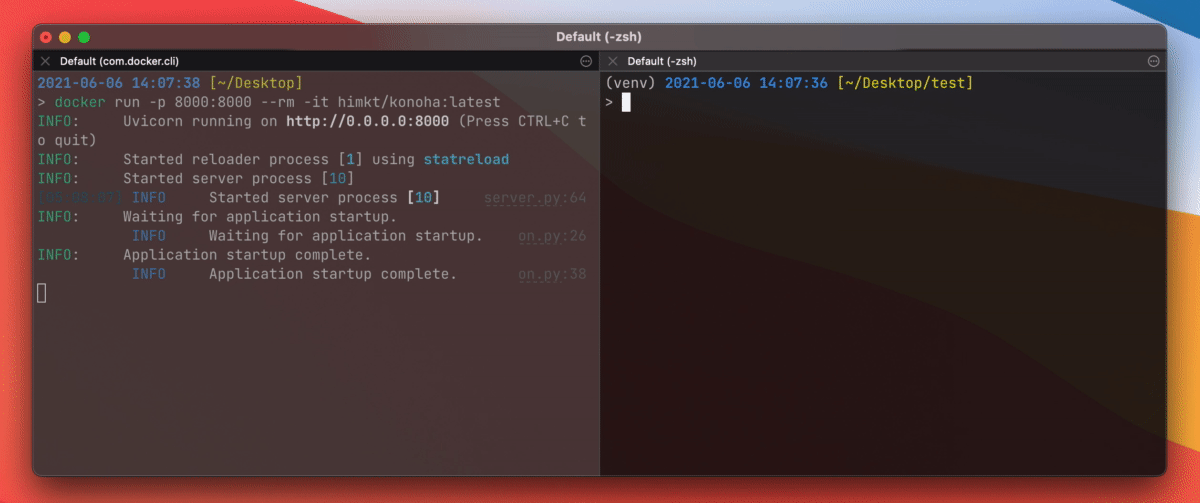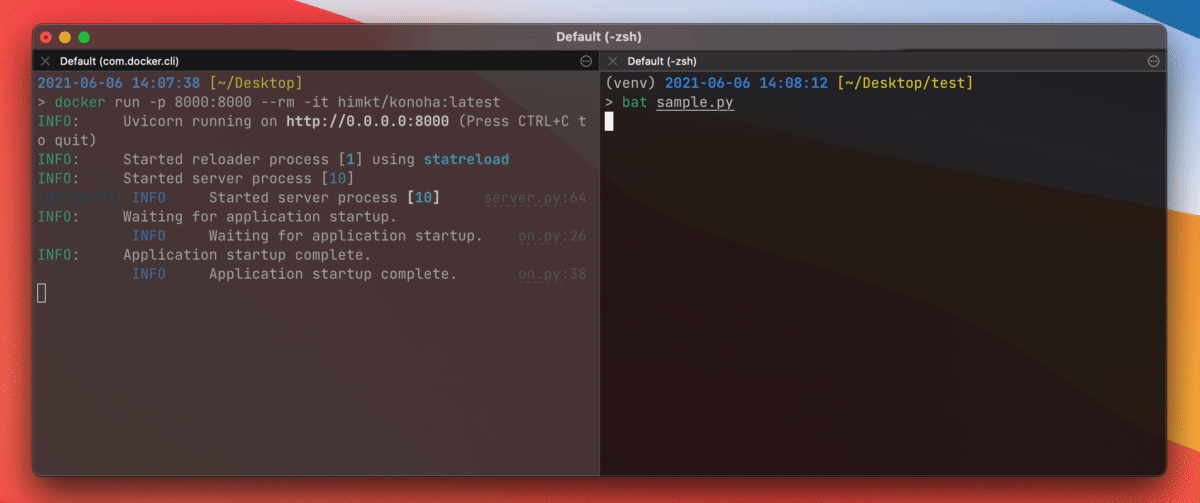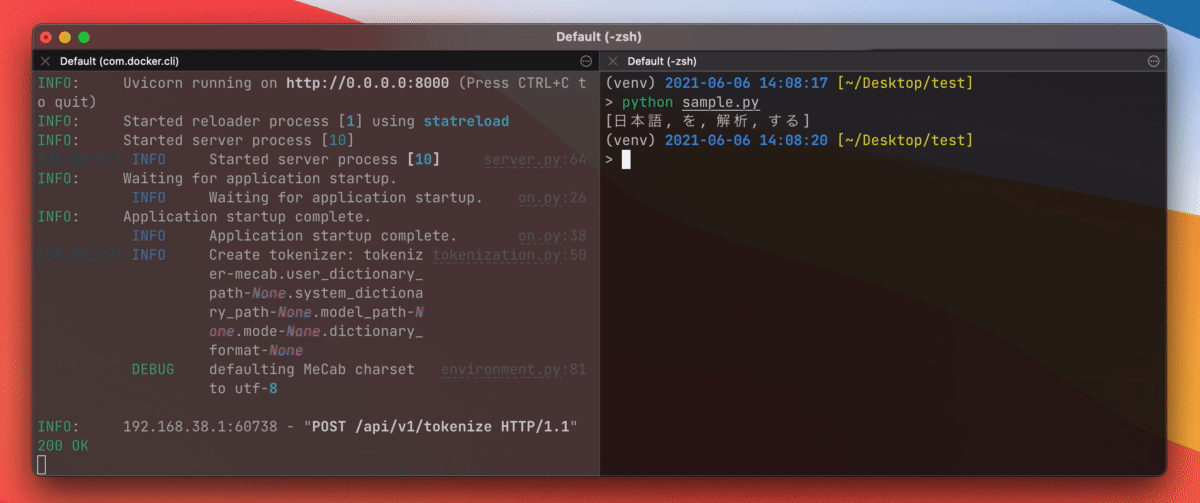
🌿 An easy-to-use Japanese Text Processing tool, which makes it possible to switch tokenizers with small changes of code.
Pure Rust GGUF tokenizer: 100% llama.cpp parity, zero C/C++ FFI, zero unsafe, WASM-ready. Free forever.
FLUX-REALISM is an experimental, advanced image generation application designed to provide highly realistic image synthesis workflows. Powered by the state-of-the-art FLUX architecture, the suite offers a dual-model workspace featuring FLUX.1-Krea-dev and a specialized FLUX.1-dev.
A Gradio-based demo application for comparing state-of-the-art OCR models: DeepSeek-OCR, Dots.OCR, HunyuanOCR, and Nanonets-OCR2-3B.
Flux.2-Klein-KV-Edit-Consistency-Ultra-Fast is a high-performance image editing and generation workspace based on the black-forest-labs/FLUX.2-klein-9b-kv base model and the dx8152/Flux2-Klein-9B-Consistency LoRA adapter.
To investigate various DNN text classifiers including MLP, CNN, RNN, BERT approaches.
A Gradio-based demonstration for the Tongyi-MAI/Z-Image-Turbo diffusion pipeline, enhanced with a curated collection of LoRAs (Low-Rank Adaptations) for style transfer and creative image generation. Users can select from pre-listed LoRAs or add custom ones from Hugging Face repositories.
A Gradio-based demonstration application for the Tencent HunyuanOCR model, focused on optical character recognition (OCR) tasks such as text detection, extraction, and coordinate formatting from images. Users can upload images, customize prompts (e.g., for Chinese/English text).
Kontext-Photo-Mate-v2 is an advanced image manipulation application built on top of the FLUX.1 Kontext AI model, featuring multiple LoRA adapters for fine-grained perspective and object editing.
A 66M parameter decoder-only transformer language model implemented from scratch in PyTorch. Features a custom SentencePiece tokenizer, RoPE positional embeddings, SwiGLU feed-forward network, per-layer KV cache for efficient autoregressive inference, and a Svelte-based streaming chat interface.
Train a Llama-style Hindi LLM from scratch on a single 6 GB GPU: SentencePiece tokenizer, packed data pipeline, plain PyTorch training. Extensible to 10+ Indian languages.
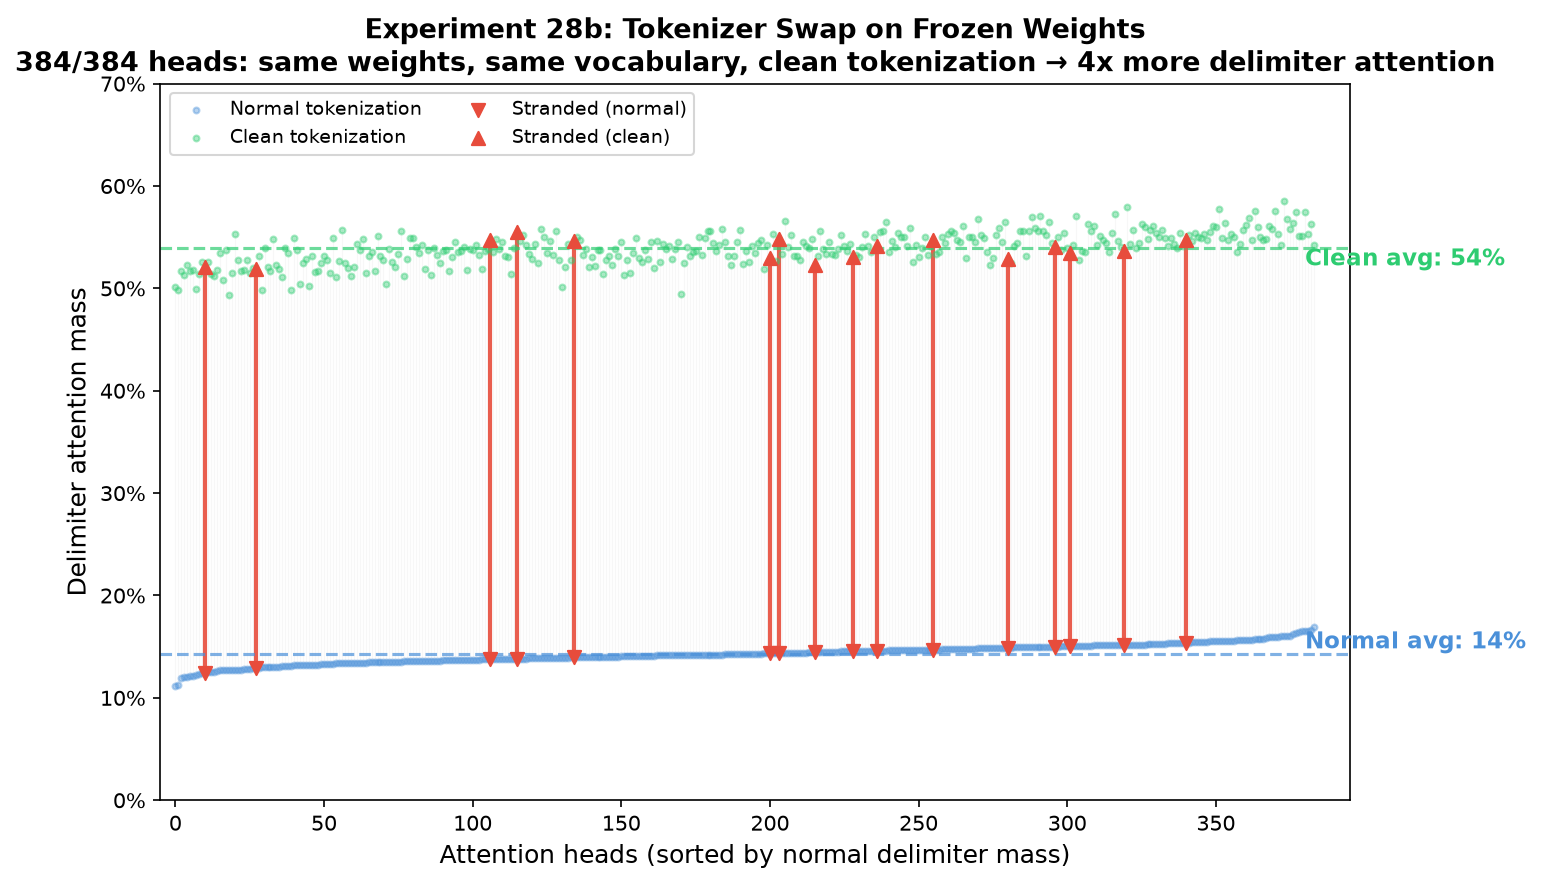
Merge Barriers in BPE Tokenization: How Tokenizer Design Causally Determines Attention Head Specialization. Paper, 23 eval scripts, 86 result files, tokenizer definitions, 4 model checkpoints.