pdf-craft
PDF craft can convert PDF files into various other formats. This project will focus on processing PDF files of scanned books.
- 6.8k
- Python
- MIT
- 16 h ago
PDF craft can convert PDF files into various other formats. This project will focus on processing PDF files of scanned books.
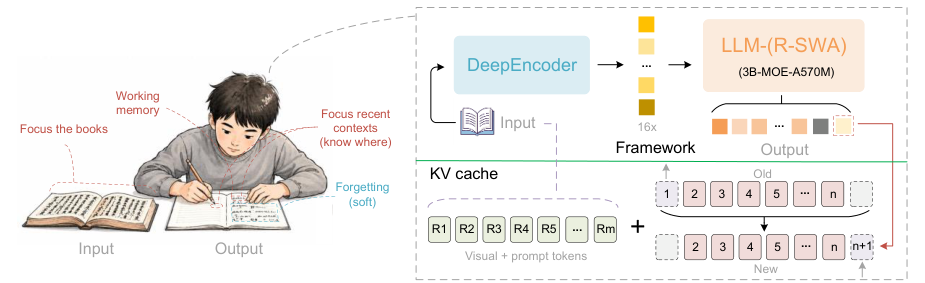
Pure-Rust, CPU-only OCR engine for Baidu Unlimited-OCR (a DeepSeek-OCR-derived 3B MoE VLM). Five-model zoo, custom int8 kernels, no ML framework, no Python, no GPU.
Run Baidu Unlimited-OCR on AMD GPUs at 56 tok/s with zero accuracy loss — one command. Only 16GB VRAM required.
DeepSeek-OCR-2-Unlimited-OCR is an advanced, experimental visual document processing and open-ended text localization dashboard. This application establishes a unified interface that allows users to swap between two premier vision-language document models: deepseek-ai/DeepSeek-OCR-2 and baidu/Unlimited-OCR.
A Gradio-based demo application for comparing state-of-the-art OCR models: DeepSeek-OCR, Dots.OCR, HunyuanOCR, and Nanonets-OCR2-3B.
Baidu's New AI Beats Google at 300-Page OCR on 2GB GPU! (Unlimited OCR 2 Review) - 3.34B MoE ultra-long document parsing pipeline
Free, open-source Google Colab notebook that converts PDF & image files (JPG, PNG, BMP, TIFF, WEBP) into clean Markdown using Baidu's Unlimited-OCR (MIT license, 93%+ OmniDocBench). No API key, no cost — runs on free Colab GPU. PDF to Markdown, OCR, document parsing, image to text converter.
DeepSeek-OCR-experimental is an advanced, multi-purpose visual document intelligence and object localization sandbox. Powered by the unredacted prithivMLmods/DeepSeek-OCR-Latest-BF16.I64-v2.0 architecture, this suite is designed to deliver highly accurate, structure-aware image text extractions.
Local-GPU OCR benchmark on smartphone photos of an English vocabulary book: PaddleOCR / PaddleOCR-VL-1.6 / DeepSeek-OCR v1 & v2 / baidu Unlimited-OCR